OpenAILanguage modelActive

GPT-6 Luna

GPT-6 Luna is in the upper middle: Rank 35 of 92 in the overall index. Through the API it is cheap.

IntelligenceRank 35 of 92

96.3Overall indexhigher is better

SpeedRank 40 of 100

101Tokens per secondhigher is better

PriceRank 8 of 95

Input $0.10 · Output $0.50

$0.20per 1M tokenslower is better

ContextRank 2 of 102

1.05Mtokens at once≈ 1,580 A4 pages

PopularityRank 30 of 785

60out of 100+8 vs. last month

based on search, usage and attention

Summary

It is cheap: $0.20 per 1M tokens (input and output blended); a typical model costs $1.55. At 101 tokens per second it writes faster than a typical model (87).

GPT-6 Luna improves multi-step work compared with GPT-5.6 Luna. In OpenAI’s AutomationBench comparison at high reasoning effort, it scores 5.4 percentage points higher at a 58% lower cost per task. The evaluation covers workflows across business applications.

Luna remains the smallest and lowest-cost GPT-6 tier. GPT-6.1 Sol covers the more capable Sol line.

GPT-6 Luna benchmarks

Overall index (Gradually Meta-Score v4)

20 of 92 models

4 models in this view are measured at a lower reasoning effort than max in the overall index. Dashed column: lower reasoning effort than the top.

GPT-6 Luna by reasoning effort

Points on the overall index scale. The value at max is GPT-6 Luna's overall index; the other efforts derive from the same Artificial Analysis test series. Missing efforts are never estimated.

406080100120nonelowmediumhighxhighmaxDeepSeek-V4.1-Flash · none: 84.7DeepSeek-V4.1-Flash · max: 99.7GLM-5.3 · low: 89.4GLM-5.3 · max: 100.7GPT-6 Luna · none: 59.4GPT-6 Luna · low: 65.2GPT-6 Luna · medium: 82.4GPT-6 Luna · high: 87.1GPT-6 Luna · xhigh: 90.6GPT-6 Luna · max: 96.3
GPT-6 Lunanone 59.4 · low 65.2 · medium 82.4 · high 87.1 · xhigh 90.6 · max 96.3DeepSeek-V4.1-Flashnone 84.7 · max 99.7GLM-5.3low 89.4 · max 100.7Filled dot: effort of the overall index. Shading: 95% range.

Source: Meta-Score v4; tiers: Artificial Analysis

Speed

20 of 100 models

Mercury 2.5576tokens/s · Configuration Reasoning enabled; effort unspecified · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
Gemini 3.1 Flash-Lite336tokens/s · Configuration High effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
Gemini 3.5 Flash-Lite299tokens/s · Configuration High effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
Nemotron 3.5 Lightning245tokens/s · Configuration Reasoning enabled; effort unspecified · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
Claude Haiku 5.5236tokens/s · Configuration Max effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
o3-mini230tokens/s · Configuration High effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
Ling 3.0 Flash199tokens/s · Configuration Reasoning enabled; effort unspecified · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
DeepSeek-V3 0324195tokens/s · Configuration Non-reasoning · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
GPT-5.4 mini191tokens/s · Configuration Xhigh effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
Gemini 3 Flash Preview191tokens/s · Configuration Non-reasoning · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
Gemini 3.5 Flash184tokens/s · Configuration High effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
Gemini 3.6 Flash182tokens/s · Configuration High effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
Command A Plus177tokens/s · Configuration Reasoning enabled; effort unspecified · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
DeepSeek-V4.1-Flash176tokens/s · Configuration Max effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
DeepSeek V4.1 Flash 1017172tokens/s · Configuration Max effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
Qwen 3.7 Max165tokens/s · Configuration Reasoning enabled; effort unspecified · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
GPT-5.4 nano153tokens/s · Configuration Xhigh effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
GPT OSS 20B152tokens/s · Configuration High effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
GPT OSS 120B151tokens/s · Configuration High effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
GPT-6 Luna101tokens/s · Configuration Max effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06

Output tokens per second, measured by Artificial Analysis

Intelligence vs. price

most attractive area: stronger and cheaper than half of the models shownbest intelligence for the price

80100120$0.10$0.50$2$10$20Gemini 3.6 Flash: 96.7, $1.50Step 5 Preview: 97.3, $1.43MiMo V2.6 Flash: 98.3, $0.18Claude Opus 4.8: 99.0, $10DeepSeek-V4.1-Flash: 99.7, $0.26Qwen 3.8 Max 0902: 100.3, $2.48GLM-5.3: 100.7, $2.15GPT-5.6 Terra: 100.7, $4.50MiMo V2.6 Pro: 100.9, $0.54GPT-5.5: 100.9, $11.25Kimi K3: 101.2, $6Grok 4.6: 102.4, $3Grok 4.7: 103.4, $3Claude Haiku 5.5: 103.4, $0.20GPT-6.1 Terra: 105.3, $2Gemini 3.8 Flash: 106.5, $1.50DeepSeek V4.1 Flash 1017: 106.6, $0.26Muse Spark 1.3: 107.4, $2GPT-5.6 Sol: 108.7, $8GPT-6 Sol: 110.5, $4Claude Fable 5: 112.5, $20Kimi K3.1 Pro: 112.9, $4Muse Wonder: 113.4, $8Claude Opus 5: 117.2, $10GPT-6.1 Sol: 119.2, $4GPT-6 Astra: 121.3, $20Gemini 4 Argon: 122.3, $4Claude Sonnet 5.5: 122.8, $4Claude Fable 5.1: 123.8, $20Claude Opus 5.5: 126.1, $8GPT-6 Luna: 96.3, $0.20GPT-6 LunaClaude Opus 5.5Claude Fable 5.1Claude Sonnet 5.5Gemini 4 ArgonGPT-6 AstraGPT-6.1 SolClaude Opus 5Muse WonderKimi K3.1 ProClaude Fable 5GPT-6 SolGPT-5.6 SolMuse Spark 1.3DeepSeek V4.1 Flash 1017Gemini 3.8 FlashGPT-6.1 TerraClaude Haiku 5.5Grok 4.7Grok 4.6Kimi K3GPT-5.5MiMo V2.6 ProGPT-5.6 TerraGLM-5.3Qwen 3.8 Max 0902DeepSeek-V4.1-FlashClaude Opus 4.8MiMo V2.6 FlashStep 5 PreviewGemini 3.6 FlashPrice per 1M tokens, blended (log scale)Overall index

GPT-6 Luna by task area

Points, 100 = reference group average · higher is better

MathematicsRank 9 of 47105.5
AgentsRank 32 of 9899.5
FinanceRank 38 of 10498.3
ReasoningRank 32 of 7297.8
CodingRank 35 of 10997.5
HealthRank 28 of 7295.2
GeneralRank 31 of 6594.4
MultimodalRank 20 of 4792.0
LegalRank 41 of 7290.7
KnowledgeRank 19 of 3289.2

Text Arena

How people rate the answers in blind comparisons, Elo points with style control · higher is better

20 of 40 models

as of October 30, 2026 · Source: LMArena

WebDev Arena

How people rate generated websites and web apps in blind comparisons, Elo points · higher is better

20 of 43 models

as of October 30, 2026 · Source: LMArena

Terminal-Bench 4.0

Share of tasks the model solves as an agent in the terminal, in percent · higher is better

20 of 38 models

as of November 7, 2026 · Source: Vals AI

Vibe Code Bench

Share of apps the model builds correctly from a description, in percent · higher is better

20 of 51 models

as of November 7, 2026 · Source: Vals AI

Show all 1,076 published benchmark results

Page 1 of 89

Published benchmarks

General tasks

BioMysteryBench

Sub-taskGPT-6 Luna (This model)GPT-6.1 SolGPT-6 AstraGPT-6 SolGPT-5.6 SolGPT-5.6 Luna
Hard17.65%39.22% (best value in this row)37.26%35.29%29.41%27.45%
Human-solvable71.69%89.04% (best value in this row)89.04% (best value in this row)84.02%80.82%69.41%
Overall61.48%79.63% (best value in this row)79.26%74.82%71.11%61.48%

higher is betterAs of November 7, 2026Source: Vals AIbars scaled within each row, not across rows

Methodology and context
Metric
accuracy

Finance

ClaimBench

Sub-taskGPT-6 Luna (This model)GPT-6.1 Sol
Direct support100% (best value in this row)100% (best value in this row)
Missing evidence100% (best value in this row)100% (best value in this row)
Non-supporting citation100% (best value in this row)100% (best value in this row)
Numeric discrepancy100% (best value in this row)100% (best value in this row)
Overall99.18%100% (best value in this row)
Subtle contradiction95.92%100% (best value in this row)

higher is betterAs of November 7, 2026Source: Vals AIbars scaled within each row, not across rows

Methodology and context
Metric
accuracy

Recorded measurement details

BioMysteryBench: Hard (Show measurement, test conditions, and source)
Source value
17.647
Score
17.647
Metric
accuracy
Unit
%
Benchmark version
1
Category
general
Task
human_difficult
Task label
Hard
Direction
Higher is better
Comparison cohort
vals-biomysterybench:1:human_difficult
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-07
Methodology
Source model ID: openai/gpt-6-luna. Source model name: GPT-6 Luna. Provider reported by source: OpenAI. Evaluator: Vals AI. Dataset type: public. Leaderboard date: 2026-11-05. Harness: Terminus 2. Reasoning effort: max. Maximum output tokens: 128000. Latency in seconds: 566.382. Standard error: 3.396. Cost per task in USD: 0.058804. Source ID: vals-ai. Evidence capture ID: vals-biomysterybench-2026-11-07-c2992129e13e. Source payload hash: c2992129e13e1455796b51fe354f18fa049ad9dcfe02fd66196230a60aeea9df. Parser version: vals-astro-v4. Imported at: 2026-11-07
Comparison methodology
Harness: Terminus 2. Reasoning effort: max. Maximum output tokens: 128000
Source Vals AI
BioMysteryBench: Human-solvable (Show measurement, test conditions, and source)
Source value
71.689
Score
71.689
Metric
accuracy
Unit
%
Benchmark version
1
Category
general
Task
human_solvable
Task label
Human-solvable
Direction
Higher is better
Comparison cohort
vals-biomysterybench:1:human_solvable
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-07
Methodology
Source model ID: openai/gpt-6-luna. Source model name: GPT-6 Luna. Provider reported by source: OpenAI. Evaluator: Vals AI. Dataset type: public. Leaderboard date: 2026-11-05. Harness: Terminus 2. Reasoning effort: max. Maximum output tokens: 128000. Latency in seconds: 513.89. Standard error: 2.416. Cost per task in USD: 0.051939. Source ID: vals-ai. Evidence capture ID: vals-biomysterybench-2026-11-07-c2992129e13e. Source payload hash: c2992129e13e1455796b51fe354f18fa049ad9dcfe02fd66196230a60aeea9df. Parser version: vals-astro-v4. Imported at: 2026-11-07
Comparison methodology
Harness: Terminus 2. Reasoning effort: max. Maximum output tokens: 128000
Source Vals AI
BioMysteryBench: Overall (Show measurement, test conditions, and source)
Source value
61.481
Score
61.481
Metric
accuracy
Unit
%
Benchmark version
1
Category
general
Task
overall
Task label
Overall
Direction
Higher is better
Comparison cohort
vals-biomysterybench:1:overall
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-07
Methodology
Source model ID: openai/gpt-6-luna. Source model name: GPT-6 Luna. Provider reported by source: OpenAI. Evaluator: Vals AI. Dataset type: public. Leaderboard date: 2026-11-05. Harness: Terminus 2. Reasoning effort: max. Maximum output tokens: 128000. Latency in seconds: 523.805. Standard error: 2.593. Cost per task in USD: 0.053236. Source ID: vals-ai. Evidence capture ID: vals-biomysterybench-2026-11-07-c2992129e13e. Source payload hash: c2992129e13e1455796b51fe354f18fa049ad9dcfe02fd66196230a60aeea9df. Parser version: vals-astro-v4. Imported at: 2026-11-07
Comparison methodology
Harness: Terminus 2. Reasoning effort: max. Maximum output tokens: 128000
Source Vals AI
ClaimBench: Direct support (Show measurement, test conditions, and source)
Source value
100
Score
100
Metric
accuracy
Unit
%
Benchmark version
1
Category
finance
Task
direct_support
Task label
Direct support
Direction
Higher is better
Comparison cohort
vals-claimbench:1:direct_support
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-07
Methodology
Source model ID: openai/gpt-6-luna. Source model name: GPT-6 Luna. Provider reported by source: OpenAI. Evaluator: Vals AI. Dataset type: public. Leaderboard date: 2026-10-23. Reasoning effort: max. Maximum output tokens: 128000. Latency in seconds: 6.911378. Standard error: 0. Cost per task in USD: 0.00132. Source ID: vals-ai. Evidence capture ID: vals-claimbench-2026-11-07-6aa89f0db85e. Source payload hash: 6aa89f0db85e2bdc765ff8d942de0d491dd37f2f2e635bb4a95b0f92746fc6d3. Parser version: vals-astro-v4. Imported at: 2026-11-07
Comparison methodology
Reasoning effort: max. Maximum output tokens: 128000
Source Vals AI
ClaimBench: Missing evidence (Show measurement, test conditions, and source)
Source value
100
Score
100
Metric
accuracy
Unit
%
Benchmark version
1
Category
finance
Task
missing_evidence
Task label
Missing evidence
Direction
Higher is better
Comparison cohort
vals-claimbench:1:missing_evidence
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-07
Methodology
Source model ID: openai/gpt-6-luna. Source model name: GPT-6 Luna. Provider reported by source: OpenAI. Evaluator: Vals AI. Dataset type: public. Leaderboard date: 2026-10-23. Reasoning effort: max. Maximum output tokens: 128000. Latency in seconds: 7.086452. Standard error: 0. Cost per task in USD: 0.001385. Source ID: vals-ai. Evidence capture ID: vals-claimbench-2026-11-07-6aa89f0db85e. Source payload hash: 6aa89f0db85e2bdc765ff8d942de0d491dd37f2f2e635bb4a95b0f92746fc6d3. Parser version: vals-astro-v4. Imported at: 2026-11-07
Comparison methodology
Reasoning effort: max. Maximum output tokens: 128000
Source Vals AI
ClaimBench: Non-supporting citation (Show measurement, test conditions, and source)
Source value
100
Score
100
Metric
accuracy
Unit
%
Benchmark version
1
Category
finance
Task
non_supporting_citation
Task label
Non-supporting citation
Direction
Higher is better
Comparison cohort
vals-claimbench:1:non_supporting_citation
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-07
Methodology
Source model ID: openai/gpt-6-luna. Source model name: GPT-6 Luna. Provider reported by source: OpenAI. Evaluator: Vals AI. Dataset type: public. Leaderboard date: 2026-10-23. Reasoning effort: max. Maximum output tokens: 128000. Latency in seconds: 7.176003. Standard error: 0. Cost per task in USD: 0.001385. Source ID: vals-ai. Evidence capture ID: vals-claimbench-2026-11-07-6aa89f0db85e. Source payload hash: 6aa89f0db85e2bdc765ff8d942de0d491dd37f2f2e635bb4a95b0f92746fc6d3. Parser version: vals-astro-v4. Imported at: 2026-11-07
Comparison methodology
Reasoning effort: max. Maximum output tokens: 128000
Source Vals AI
ClaimBench: Numeric discrepancy (Show measurement, test conditions, and source)
Source value
100
Score
100
Metric
accuracy
Unit
%
Benchmark version
1
Category
finance
Task
numeric_discrepancy
Task label
Numeric discrepancy
Direction
Higher is better
Comparison cohort
vals-claimbench:1:numeric_discrepancy
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-07
Methodology
Source model ID: openai/gpt-6-luna. Source model name: GPT-6 Luna. Provider reported by source: OpenAI. Evaluator: Vals AI. Dataset type: public. Leaderboard date: 2026-10-23. Reasoning effort: max. Maximum output tokens: 128000. Latency in seconds: 7.372316. Standard error: 0. Cost per task in USD: 0.001414. Source ID: vals-ai. Evidence capture ID: vals-claimbench-2026-11-07-6aa89f0db85e. Source payload hash: 6aa89f0db85e2bdc765ff8d942de0d491dd37f2f2e635bb4a95b0f92746fc6d3. Parser version: vals-astro-v4. Imported at: 2026-11-07
Comparison methodology
Reasoning effort: max. Maximum output tokens: 128000
Source Vals AI
ClaimBench: Overall (Show measurement, test conditions, and source)
Source value
99.184
Score
99.184
Metric
accuracy
Unit
%
Benchmark version
1
Category
finance
Task
overall
Task label
Overall
Direction
Higher is better
Comparison cohort
vals-claimbench:1:overall
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-07
Methodology
Source model ID: openai/gpt-6-luna. Source model name: GPT-6 Luna. Provider reported by source: OpenAI. Evaluator: Vals AI. Dataset type: public. Leaderboard date: 2026-10-23. Reasoning effort: max. Maximum output tokens: 128000. Latency in seconds: 7.283. Standard error: 0.203. Cost per task in USD: 0.001372. Source ID: vals-ai. Evidence capture ID: vals-claimbench-2026-11-07-6aa89f0db85e. Source payload hash: 6aa89f0db85e2bdc765ff8d942de0d491dd37f2f2e635bb4a95b0f92746fc6d3. Parser version: vals-astro-v4. Imported at: 2026-11-07
Comparison methodology
Reasoning effort: max. Maximum output tokens: 128000
Source Vals AI
ClaimBench: Subtle contradiction (Show measurement, test conditions, and source)
Source value
95.918
Score
95.918
Metric
accuracy
Unit
%
Benchmark version
1
Category
finance
Task
subtle_contradiction
Task label
Subtle contradiction
Direction
Higher is better
Comparison cohort
vals-claimbench:1:subtle_contradiction
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-07
Methodology
Source model ID: openai/gpt-6-luna. Source model name: GPT-6 Luna. Provider reported by source: OpenAI. Evaluator: Vals AI. Dataset type: public. Leaderboard date: 2026-10-23. Reasoning effort: max. Maximum output tokens: 128000. Latency in seconds: 7.866128. Standard error: 1.001. Cost per task in USD: 0.001357. Source ID: vals-ai. Evidence capture ID: vals-claimbench-2026-11-07-6aa89f0db85e. Source payload hash: 6aa89f0db85e2bdc765ff8d942de0d491dd37f2f2e635bb4a95b0f92746fc6d3. Parser version: vals-astro-v4. Imported at: 2026-11-07
Comparison methodology
Reasoning effort: max. Maximum output tokens: 128000
Source Vals AI

Page 1 of 89

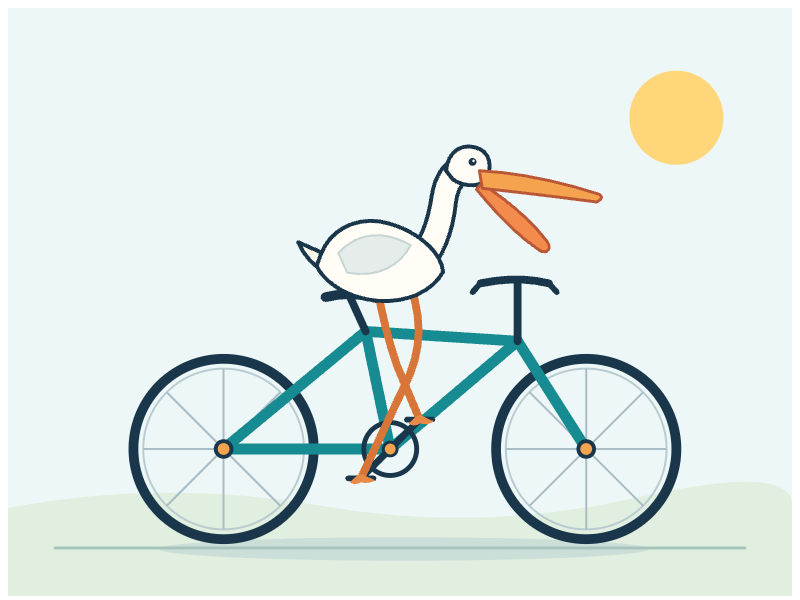
See for yourself: one prompt, one attempt

We show the latest attempt without fixes; it does not count toward the overall index.

GPT-6 Luna: Pelican on a bicycle
A community classic for free-form SVG drawing.

Pelican on a bicycle

Prompt

Generate an SVG of a pelican riding a bicycle

Oct 1, 2026 · 47 s · $0.0022

Test details
Run date
Oct 1, 2026
API provider
openrouter
Requested API model
openai/gpt-6-luna
Reasoning setting
high
Token limit including reasoning
8,192 tokens
Output tokens
4,493 tokens
Cost of the attempt
$0.0022
Response time
46.7 s
API model reported in response
openai/gpt-6-luna
Pinned endpoint
OpenAI | openai/gpt-6-luna-20260922
Temperature
Provider default
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating

Visually reviewed. This individual test does not establish overall model quality.

Task origin: Simon Willison
SVG short test

SVG short test

One SVG task with the same fixed settings for every model, without hidden thinking.

GPT-6 Luna

Unavailable in this round

Popularity compared

How often the model is searched for, used and mentioned, compared with every model of its category.

Popularity index

The 100 most popular models of this category, 0 to 100, higher is more popular

20 of 100 models

As of November 2026 · Source: gradually.ai popularity index

Over time

Weekly values from October 18, 2026 to November 7, 2026

GPT-6 LunaGemini 3.8 Flash 61Muse Spark 1.3 61Claude Sonnet 5.5 60GPT-5.4 mini 59

Method changes in the timeline, a jump at these points is no market event:

  1. 1November 1, 2026: Value only with search or usage data, 30-day attention

What is gaining popularity right now, across models, vendors, harnesses and AI subscriptions, is collected in All AI trends.

GPT-6 Luna compared

Compare with another model

The most popular comparisons

  1. 1GPT-6 Luna vs. GPT-5.6 Terra
  2. 2Claude Haiku 5.5 vs. GPT-6 Luna
  3. 3GPT-6 Luna vs. Gemini 3.8 Flash
  4. 4GPT-6 Luna vs. DeepSeek-V4.1-Flash
  5. 5GPT-6 Luna vs. GPT-5.4 mini
  6. 6GPT-6 Astra vs. GPT-6 Luna
  7. 7GPT-6 Luna vs. GLM-5.3-Flash
  8. 8GPT-6.1 Sol vs. GPT-6 Luna
  9. 9GPT-6 Luna vs. DeepSeek-V4-Pro
Show all 56 comparisons
  1. 10Claude Sonnet 5 vs. GPT-6 Luna
  2. 11GPT-6 Luna vs. Gemini 3.5 Flash-Lite
  3. 12Claude Haiku 4.5 vs. GPT-6 Luna
  4. 13Claude Sonnet 4.6 vs. GPT-6 Luna
  5. 14GPT-6 Luna vs. GPT-5.4
  6. 15GPT-6 Luna vs. Gemini 3.1 Pro Preview
  7. 16Claude Sonnet 5.5 vs. GPT-6 Luna
  8. 17GPT-6 Luna vs. DeepSeek V4.1 Flash 1017
  9. 18Claude Opus 4.8 vs. GPT-6 Luna
  10. 19GPT-6 Luna vs. GPT-5.6 Sol
  11. 20GPT-6 Luna vs. Grok 4.7
  12. 21GPT-6 Luna vs. Gemini 3.6 Flash
  13. 22GPT-6 Sol vs. GPT-6 Luna
  14. 23Claude Opus 4.6 vs. GPT-6 Luna
  15. 24Claude Sonnet 4.5 vs. GPT-6 Luna
  16. 25GPT-6 Luna vs. Muse Spark 1.3
  17. 26GPT-6 Luna vs. DeepSeek-V4-Flash
  18. 27Claude Opus 5.5 vs. GPT-6 Luna
  19. 28GPT-6 Luna vs. Qwen 3.8 27B
  20. 29GPT-6 Luna vs. Qwen 3.8 Max 0902
  21. 30GPT-6 Luna vs. GLM-5.2
  22. 31GPT-6 Luna vs. GPT-5.5
  23. 32GPT-6 Luna vs. Gemini 3.7 Flash
  24. 33Claude Fable 5.1 vs. GPT-6 Luna
  25. 34GPT-6 Luna vs. GLM-5.3
  26. 35GPT-6 Luna vs. Grok 4.6
  27. 36Claude Opus 4.5 vs. GPT-6 Luna
  28. 37GPT-6 Luna vs. MiMo-V2.5
  29. 38Claude Fable 5 vs. GPT-6 Luna
  30. 39GPT-6 Luna vs. Mistral Large 4
  31. 40GPT-6 Luna vs. Gemini 3.5 Flash
  32. 41GPT-6.1 Terra vs. GPT-6 Luna
  33. 42GPT-6 Luna vs. Mistral Medium 3.5
  34. 43GPT-6 Luna vs. Grok 4.5
  35. 44Claude Opus 4.7 vs. GPT-6 Luna
  36. 45GPT-6 Luna vs. Gemini 4 Argon
  37. 46Claude Opus 5 vs. GPT-6 Luna
  38. 47GPT-6 Luna vs. Gemini 4 Carbon
  39. 48GPT-6 Luna vs. Muse Wonder
  40. 49GPT-6 Luna vs. Muse Wonder Full
  41. 50GPT-6 Luna vs. Grok 4.3
  42. 51GPT-6 Luna vs. Kimi K3.1 Pro
  43. 52GPT-6 Luna vs. Kimi K3
  44. 53GPT-6 Luna vs. Kimi K2.6
  45. 54GPT-6 Luna vs. GLM-5.1
  46. 55GPT-6 Luna vs. Mistral Large 3
  47. 56GPT-6 Luna vs. MiMo-V2.5-Pro

All specifications

Architecture

Knowledge cutoff
May 18, 2026
Source: Knowledge cutoff

Input and output

Context window
1,050,000 tokens
Source: Context window
Maximum output
128,000 tokens
Source: Maximum output
Input
Text, Image
Source: Input
Output
Text
Source: Output
Reasoning mode
none, low, medium, high, xhigh, max
Source: Reasoning mode
Tool calling
Yes
Source: Tool calling

Watermarking and provenance

AI watermarking refers to invisible signals embedded in the output. Visible marks and provenance metadata are listed separately. Unknown means there is insufficient evidence for that particular field.

AI watermarking
Unknown
no source
Watermarking technique
Not known
no source

Licence and access

Weights
Proprietary
Source: Weights
Release
Sep 22, 2026
Source: Release

API

API model ID
gpt-6-luna
Source: API model ID

Further details

Notes
Released September 22, 2026 as the lowest-cost GPT-6 tier, described by OpenAI as its most efficient model for focused, high-volume tasks. 1.05 million token context window, 128,000 maximum output tokens, and a May 18, 2026 knowledge cutoff. API price $0.10 / $0.50 per million input and output tokens, half of GPT-5.6 Luna's promotional price. Reasoning effort from none to max, with medium as the default. Official API ID: gpt-6-luna.
Source: Notes

Prices

Choose a price view

9 offers, prices in US dollars per 1M tokens, blended from 3 parts input and 1 part output.

Filter offers
ProviderInputOutputCache readCache writeBlended
OpenAIdirect$0.10$0.50$0.01$0.125$0.20
OpenAIabove 272,000 context tokensdirect$0.20$0.75$0.02$0.25$0.34
OpenAIFlex$0.05$0.25n/an/a$0.10
Amazon BedrockGlobal$0.10$0.50n/an/a$0.20
Azure$0.10$0.50n/an/a$0.20
OpenAI$0.10$0.50n/an/a$0.20
Amazon BedrockUs-east-1$0.11$0.55n/an/a$0.22
AzureEU$0.11$0.55n/an/a$0.22
AzureUS$0.11$0.55n/an/a$0.22
OpenAIFast$0.20$1n/an/a$0.40

Cache prices come from the direct tariff; OpenRouter does not report them for the other providers. Direct price according to the developer, checked Sep 22, 2026. Provider prices via OpenRouter, as of Nov 7, 2026. Open the LLM price index

2 price changes since tracking began.

InputOutput

$0$0.20$0.40$0.60$0.80Sep 22, 2026Nov 7, 2026
Daily observed price in the LLM price index in US dollars per 1M tokens. The index uses a market price from several sources, which can differ from the developer's direct price.

Free to use at OpenAI (ChatGPT Free), more from $8 a month (ChatGPT Go). Through other providers from $1 a month (Command Code Go, with limited credits). 57 plans in Germany.

Filter plans
PlanMonthly list priceNote
ChatGPT FreeOpenAIfreedeveloper's own plan
ChatGPT GoOpenAI$8developer's own plan
ChatGPT PlusOpenAI$20developer's own plan
ChatGPT Business Standard-PlatzOpenAI$25developer's own plan, with limited credit, for teams, per seat
ChatGPT Pro $100OpenAI$100developer's own plan, with limited credit
ChatGPT Business Premium-PlatzOpenAI$125developer's own plan, with limited credit, for teams, per seat
ChatGPT EnterpriseOpenAIn/adeveloper's own plan, for enterprises, per seat
ChatGPT Pro $500OpenAI$500developer's own plan, with limited credit
ElevenLabs Freefreewith limited credit
Genspark Freefreewith limited credit
JetBrains AI Freefreewith limited credit
Lovable Freefreewith limited credit
Zed Studentfree
Command Code Go$1with limited credit
ElevenLabs Starter$6with limited credit
Command Code GOAT$10with limited credit
GitHub Copilot Pro$10with limited credit
Zed Pro$10
JetBrains AI Pro$10with limited credit
GitHub Copilot Business$19with limited credit, for teams, per seat
Command Code Pro$20with limited credit
Replit Core$20
ElevenLabs Creator$22with limited credit
JetBrains AI Pro$20with limited credit, for teams, per seat
Lovable Pro$25with limited credit
Genspark Plus$24.99with limited credit
Langdock Business Standard€25for teams, per seat
JetBrains AI Ultimate$30with limited credit
GitHub Copilot Enterprise$39with limited credit, for enterprises, per seat
GitHub Copilot Pro+$39with limited credit
Genspark for Business Team$40with limited credit, for teams, per seat
Lovable Business$50with limited credit, for teams
Mindverse Studio Team€49for teams, per seat
Higgsfield Plus€59with limited credit
Mindverse Studio Pro€59per seat
JetBrains AI Ultimate$60with limited credit, for teams, per seat
Higgsfield Team€79with limited credit, for teams, per seat
ElevenLabs Pro$99with limited credit
Command Code Max 10×$100with limited credit
GitHub Copilot Max$100with limited credit
Replit Pro$100
Krea Max$105with limited credit
Langdock Business Max€99for teams, per seat
Higgsfield Ultra€129with limited credit
Higgsfield Scale€169with limited credit, for teams, per seat
Command Code Max 20×$200with limited credit
Krea Business$200with limited credit, for teams
Genspark Pro$249.99with limited credit
ElevenLabs Scale$299with limited credit, for teams
ElevenLabs Business$990with limited credit, for teams
ElevenLabs Enterprisen/afor enterprises
Genspark for Business Enterprisen/awith limited credit, for enterprises, per seat
Higgsfield Enterprisen/afor enterprises
JetBrains AI Enterprisen/awith limited credit, for enterprises, per seat
Krea Enterprisen/afor enterprises
Lovable Enterprisen/afor enterprises
Replit Enterprisen/afor enterprises

All plans in the AI subscription comparison

Frequently asked questions about GPT-6 Luna

How good is GPT-6 Luna in benchmarks?

Decent: Rank 35 of 92 in the overall index.

Overall index (Gradually Meta-Score v4) from 48 benchmark results · data through Nov 7, 2026

IntelligenceOverall index in points, 100 = reference group average · higher is better
Step 5 Preview97.3
Gemini 3.5 Flash96.9
Gemini 3.6 Flash96.7
GPT-6 LunaRank 3596.3
Grok 4.594.6
GLM-5.3-Flash94.2
GPT-5.6 Luna93.9

What is the Overall index (Gradually Meta-Score v4)?

A point value that combines many independent benchmarks into one number. 100 points is the average of a fixed reference group, higher is better. GPT-6 Luna scores 96.3 points, which is rank 35 of 92.

Own analysis by gradually.ai, method benchmark-meta-score-v4 · for GPT-6 Luna from 48 test series

Which data
Only current, reviewed results from independent evaluators such as Artificial Analysis, Vals AI, LMArena, LiveBench and Epoch AI. Vendor claims and historical or disputed values do not count.
One value per test
For each source and test series the latest retrieval with one fixed setup counts. When a source tests several reasoning levels, the highest documented one applies. A series needs at least 5 models.
Making tests comparable
Percentages are converted so that gaps near 0 and near 100 % count fairly, then every series is put on the same scale. A hard test therefore does not weigh more than an easy one.
Shared strength
A statistical model estimates, from all series at once, one shared capability per model and, per area, how far a model deviates from it. Missing tests are never counted as zero.
Weighting
Core areas (Coding, Reasoning, Mathematics, Knowledge, Agents, General and Multimodal) count 75 % together, the domain areas Finance, Legal and Health 25 %.
The point scale
The value is measured against a fixed reference group of 29 models, much like an IQ score: 100 points is its average and 15 points one standard deviation of the group. The scale is open at both ends and is not a percentage. A model 15 points ahead does better in roughly three of four benchmark comparisons. New models do not shift older values.
Place by score
The place follows the order of the scores among all models with a place, such as "rank 14 of 95". A second calculation checks whether a lead is reliable by recomputing the score 200 times with randomly redrawn test families. If a model is not almost always ahead there, the two models count as level.
Minimum evidence
A value needs at least 8 test series from 2 sources and 3 areas, a place only with enough precision. Missing core areas are flagged as "estimated".
What it is not
Not a test run by gradually.ai and no verdict on every single task. For a specific task the area values and the individual benchmarks matter more.

How much does GPT-6 Luna cost?

Through the API $0.10 per 1M input tokens and $0.50 output. That is cheap.

Prices from Nov 7, 2026

Output price since tracking beganDollars per 1M tokens · lower is better

Sep 22, 2026Nov 7, 2026

First price on Sep 22, 2026: $0.50. Since Sep 24, 2026: $0.50.

What is the knowledge cutoff of GPT-6 Luna?

May 18, 2026, according to OpenAI. That is 4 months before release.

Stated by OpenAI

How large is the context window of GPT-6 Luna?

1.05 M tokens. That is how much text GPT-6 Luna reads at once, about 1,580 A4 pages.

Page count as a rule of thumb from Artificial Analysis

Context windowTokens the model reads at once · higher is better
GPT-6 LunaRank 2 of 1021.05M
GPT-5.6 Luna1.05M
Gemini 3.6 Flash1.05M
Gemini 3.5 Flash1.05M
GLM-5.3-Flash1M
Claude Opus 4.71M
Grok 4.5500K

How fast is GPT-6 Luna?

101 tokens per second. That is faster than a typical model at 87.

Measured by Artificial Analysis on Nov 6, 2026. AA 3.0.0, including time to first token, averaged across available workloads and five days.

SpeedTokens per second · higher is better
Gemini 3.5 Flash184
Gemini 3.6 Flash182
Step 5 Preview132
GPT-6 LunaRank 40 of 100101
GPT-5.6 Luna94
Grok 4.571
GLM-5.3-Flash56

Can I run GPT-6 Luna locally?

No. OpenAI does not publish the weights.

Stated by OpenAI

Open weights
no
License
n/a
Parameters
n/a
active per token
n/a

Where can I use GPT-6 Luna?

Free to use at OpenAI. Including other providers that makes 57 plans in Germany, plus the API.

Subscription comparison, prices in Germany incl. VAT

At OpenAI

8 plans, free (ChatGPT Free).

Through other providers

49 plans from 12 providers, from $1 a month (Command Code Go), with limited credits.

Through the API

$0.10 input, $0.50 output per 1M tokens, unchanged since Sep 24, 2026.

Is GPT-6 Luna better than GPT-5.6 Luna?

Not clearly in the overall index: both are level. It leads in Mathematics and Knowledge.

GPT-5.6 Luna as predecessor according to Introducing GPT-6 Sol and Luna, checked Sep 22, 2026

IntelligenceOverall index, 100 points = average · higher is better
96.3

GPT-6 Luna

Rank 35

93.9

GPT-5.6 Luna

Rank 38

SpeedTokens per second · higher is better
101

GPT-6 Luna

fairly fast

94

GPT-5.6 Luna

fairly fast

PriceDollars per 1M tokens, 3 parts input to 1 part output · lower is better
$0.20

GPT-6 Luna

cheaper

$0.45

GPT-5.6 Luna

2.3 times the price

GPT-6 LunaGPT-5.6 Luna100 points = average, higher is better
Codinglevel13 and 11 testsGPT-6 Luna: 97.5GPT-5.6 Luna: 96.0
Reasoninglevel4 and 3 testsGPT-6 Luna: 97.8GPT-5.6 Luna: 98.1
MathematicsGPT-6 Luna aheadGPT-6 Luna: 105.5GPT-5.6 Luna: 94.9
KnowledgeGPT-6 Luna aheadGPT-6 Luna: 89.2GPT-5.6 Luna: 83.9
Agentslevel4 and 6 testsGPT-6 Luna: 99.5GPT-5.6 Luna: 97.6
GeneralGPT-6 Luna slightly aheadnot certain · 5 tests eachGPT-6 Luna: 94.4GPT-5.6 Luna: 90.9
Financelevel5 and 6 testsGPT-6 Luna: 98.3GPT-5.6 Luna: 98.2
LegalGPT-5.6 Luna slightly aheadnot certain · 3 and 2 testsGPT-6 Luna: 90.7GPT-5.6 Luna: 95.2
Healthlevel2 tests eachGPT-6 Luna: 95.2GPT-5.6 Luna: 92.4
Multimodallevel2 and 3 testsGPT-6 Luna: 92.0GPT-5.6 Luna: 92.2

Sources and data date

Show all 112 sources

Benchmark sources at a glance

Which independent evaluators tested this model. This is coverage, not a quality ranking.

EvaluatorTest seriesComposite indicesRecorded active measurements
Artificial Analysis14086
Vals AI285291
LMArena4043
LiveBench7146
Epoch AI6013
ARC Prize0024
Scale AI Evals004

Without vendor claims and historical or disputed results; those stay labelled in the single values. 42 measurements are not yet assigned to a test series.

TypeEvidence and data date
Speed

OpenAI, Max effort. AA 3.0.0, including time to first token, averaged across available workloads and five days. Retrieved November 6, 2026.

Price

Base API prices without caching or batch discounts. Higher context tiers and other rates are listed under Costs.

Input

Documented modalities. Retrieved September 22, 2026.

Output

Documented modalities. Retrieved September 22, 2026.

Research statusResearch date September 22, 2026. 73 source URLs checked. This documents the inspected sources, not an exhaustive inventory of every publication.
Not found in the inspected sources

parameters-billions

Original wording

OpenAI does not publish parameter counts.

Unresolved

fresh-agent-arena-leaderboard

Note

The current Agent Arena leaderboard was reviewed in the rendered web reader, but the raw endpoint returned HTTP 403. No dynamic values were added without a complete captured source body.

Not published

confidence-interval-95

Original wording

No per-model 95% interval for this row is published in the paper’s Table 6; no interval has been inferred.

Not published

api-snapshot-id

Original wording

The paper gives the exact API alias and release date but not a pinned provider snapshot identifier.

Not published

serving-revision-and-test-denominators

Note

ARC Prize pages do not state per-row N, CI, or immutable served revision. Parallel omits model snapshot and varies reasoning/token limits by provider guidance.

Unresolved

model snapshot, evaluation run date and per-model N

Original wording

The opened public benchmark article does not give GPT-6 Luna's pinned API snapshot, an evaluation run date for this score table, or a per-model sample count. None is inferred from dataset descriptions.

Not published

PRBench row subset and model-specific run settings

Note

The current leaderboard page does not identify whether this row uses the full or hard subset, or publish the model-specific generation settings or measurement date.

Additional sourceModel metadata (retrieved September 22, 2026) · Introducing GPT-6 Sol and GPT-6 Luna · Editorial description reviewed October 4, 2026
Additional sourceArtificial Analysis (retrieved October 19, 2026; November 2, 2026; November 7, 2026)123456789
Additional sourceArtificial Analysis (retrieved October 19, 2026; October 29, 2026; November 2, 2026; November 7, 2026)12
Additional sourceArtificial Analysis (retrieved October 19, 2026)12
Additional sourceArtificial Analysis (retrieved October 19, 2026; November 2, 2026)12
Additional sourceArtificial Analysis (retrieved November 5, 2026; November 7, 2026)
Additional sourceArtificial Analysis (retrieved November 7, 2026)12
Additional sourceLMArena (retrieved October 30, 2026)1234
Additional sourceLMArena (retrieved October 28, 2026)12
Additional sourceLMArena (retrieved October 16, 2026)1234
Additional sourceVals AI (retrieved November 7, 2026)1234567891011121314151617181920212223242526
Additional sourceVals AI (retrieved October 16, 2026; November 7, 2026)123
Additional sourceVals AI (retrieved October 16, 2026; October 31, 2026; November 7, 2026)
Additional sourceVals AI (retrieved October 17, 2026; November 7, 2026)
Additional sourceVals AI (retrieved October 16, 2026; October 30, 2026; October 31, 2026)
Additional sourceVals AI (retrieved October 28, 2026; November 7, 2026)
Additional sourceLiveBench (retrieved October 16, 2026)1 (unavailable on November 2, 2026) https://livebench.ai/table_2026_09_02.csv2 (unavailable on November 2, 2026) https://livebench.ai/breakdown_2026_09_02.json
Additional sourceArena AI (retrieved October 17, 2026)
Additional sourcePolicyBench (PolicyEngine), official frozen US paper and leaderboard (retrieved October 17, 2026)
Additional sourceARC Prize Verified Leaderboard (retrieved October 17, 2026)
Additional sourceParallel Search Capability Leaderboard (retrieved October 17, 2026)
Additional sourceAndroid Developers, Android Bench leaderboard (retrieved October 17, 2026)
Additional sourceVetEval, GPT-6 Luna model page (retrieved October 17, 2026)
Additional sourceBANGLAPLAN research team, Constraint-Based Planning and Decision-Making in Bangla (retrieved October 17, 2026)
Additional sourceJoonlab GPT-6.1 Sol benchmark, pinned data commit (retrieved October 17, 2026)123
Additional sourceEpoch AI, AI systems are improving rapidly at Slay the Spire and its sequel (retrieved October 17, 2026)
Additional sourceVeriContest paper authors (retrieved October 18, 2026)
Additional sourceEpoch AI benchmark run dataset snapshot (retrieved October 19, 2026; October 28, 2026)
Additional sourceAssemblyAI Voice Standard Bench (retrieved October 19, 2026)
Additional sourceRoboflow Vision Evals (retrieved October 19, 2026; October 28, 2026)
Additional sourceAgent Arena (retrieved October 20, 2026)
Additional sourceVulcanBench Frontier v4, Code quality protocol v3.16 (retrieved October 20, 2026)
Additional sourceOpenAI (retrieved October 22, 2026)
Additional sourceuhyo, React Proficiency Benchmark (retrieved October 22, 2026)
Additional sourceOpenAI Deployment Safety Hub, GPT-6.1 Sol system-card addendum (retrieved October 23, 2026)
Additional sourceOpenAI, GPT-6.1 Sol System Card Addendum (retrieved October 23, 2026)
Additional sourceLiveBench (retrieved October 28, 2026)12
Additional sourceScale AI (retrieved October 28, 2026)
Additional sourceTerminal-Bench (retrieved October 28, 2026)
Additional sourceDuelLab GameBench 2 model results (retrieved October 28, 2026; November 2, 2026; November 5, 2026)
Additional sourceParallel Search Capability Leaderboard (retrieved October 28, 2026; November 5, 2026)
Additional sourceTowards AI ToneBench (retrieved October 28, 2026; October 30, 2026)123
Additional sourceGoogle on Kaggle (retrieved October 28, 2026)1234
Additional sourceMathBench.ai (retrieved October 28, 2026)
Additional sourceScale AI HSS (retrieved October 28, 2026)
Additional sourceScale AI DistressBench (retrieved October 28, 2026)
Additional sourceScale AI FORTRESS (retrieved October 28, 2026)
Additional sourceParallel Search Capability Leaderboard (retrieved November 5, 2026)
Additional sourceOpenRouter: Popularity index (derived), CC BY 4.0
Additional sourceVercel AI Gateway: Popularity index (derived), CC BY 4.0
Additional sourceOllama: cumulative downloads for the popularity index
Additional sourceReplicate: cumulative runs for the popularity index
Additional sourceGoogle Trending Now: limited feed selection for Germany and the US
Additional sourceCreative Commons Attribution 4.0