
Claude Fable 5
Unavailable in this round
Anthropic
Claude Fable 5 was the generally available half of the model core it shared with Claude Mythos 5 from June 9, 2026. It was the direct predecessor to Claude Fable 5.1, combining demanding software work, knowledge work, and vision with safety classifiers.
Its availability followed an unusual path. A report from Amazon researchers described a method that could bypass Fable 5 safeguards during vulnerability research, after which US export controls suspended access from June 12 through June 30. Fable returned globally on July 1. Anthropic now labels it legacy, while keeping its API available and pointing new integrations to Fable 5.1.
| Specification | Value and source |
|---|---|
| Weights | ProprietarySource |
| Access | APISource |
| Context window | 1,000,000 tokensSource |
| Knowledge cutoff | January 2026Source |
| Notes | Mythos-class tier above Opus, most capable widely-released model, 1M context (new tokenizer, ~30% more tokens per text vs. pre-Opus-4.7 models), 128K output, adaptive thinking only, safety classifiers with refusal fallback to Opus 4.8. Briefly suspended 2026-06-12 to 2026-06-30 under a US export control directive after a jailbreak was found; generally available again since 2026-07-01.Source |
| API model ID | claude-fable-5Source |
| Source status | active (legacy)Source |
| Release | 2026-06-09Source |
| Maximum output | 128,000 tokensSource |
| Input | Text, imagesSource |
| Output | TextSource |
| Reasoning mode | adaptive (always on); default highSource |
| Knowledge cutoff | 2026-01Source |
| Tool calling | YesSource |
| Structured output | YesSource |
Benchmark meta-analysis
These Gradually indexes place selected published measurements on a 0 to 100 scale. They are not accuracy percentages and do not guarantee results in your application.
Retrieval dates of the sources used 2026-08-26 - 2026-10-19
Index 85.1 / 100
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Not enough coverage for a score yet
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Index 79.1 / 100
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Index 88.6 / 100
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Index 98.1 / 100
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Not enough coverage for a score yet
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Not enough coverage for a score yet
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Index 93.1 / 100
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Index 94.4 / 100
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Index 91.9 / 100
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Not enough coverage for a score yet
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Not enough coverage for a score yet
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Not enough coverage for a score yet
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Not enough coverage for a score yet
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Method version: benchmark-meta-score-v1
The index includes active measurements from reviewed primary sources when at least five models are compared in the same documented comparison slice across dataset, harness, agent, tools, and trial count. Each benchmark series and evaluator contributes one shared setup slice from the newest capture; when dates match, the wider slice is used. When one source and series include several explicitly documented reasoning tiers, the highest documented tier (none through max) is selected, never the best result value. The explicit source label “Non-reasoning” is treated as none. When selecting between multiple results, unknown or ambiguous tiers exclude the model from that series. Unambiguous single configurations do not require a tier ordering. The best individual result for each model is not selected. Equal raw values share the same rank percentile. Multiple series from the same evaluator within a family receive equal weight; evaluators within a family, families within an area, and areas in the overall index then receive equal weight. Unmeasured series remain visible in coverage and bounds. An overall score requires at least four areas, six test families, and two sources. An area score requires at least two test families. Every overall and area score also requires at least 50% of its panel weight.
Published model-specific parameters can differ. This is not a controlled experiment; comparisons with such differences are marked provisional.
Unmeasured portions are not entered as zero. They reduce coverage and contribute only to the displayed bounds. Scores with different coverage are therefore not equally complete.
The bounds hold observed percentiles fixed and allow missing contributions anywhere from 0 to 100. They are not confidence intervals or predictions of future recalculations.
The source count is not a count of independent experiments.
OECD handbook on composite indicatorsAll 43 test families and 12 of 47 raw measurements are listed here. The complete calculation for every model is available in the JSON export.
Nominal family weight in the overall panel: 1.43 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Nominal family weight in the overall panel: 0.6 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Nominal family weight in the overall panel: 0.6 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Nominal family weight in the overall panel: 1.02 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Nominal family weight in the overall panel: 0.6 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Nominal family weight in the overall panel: 1.02 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Nominal family weight in the overall panel: 0.6 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Nominal family weight in the overall panel: 1.43 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Nominal family weight in the overall panel: 2.38 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Nominal family weight in the overall panel: 1.02 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Nominal family weight in the overall panel: 1.02 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Nominal family weight in the overall panel: 1.43 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Nominal family weight in the overall panel: 1.02 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.02 % · Coverage of this test family: 50 %
Nominal family weight in the overall panel: 0.48 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 7.14 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.43 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.79 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.79 % · Coverage of this test family: 50 %
Nominal family weight in the overall panel: 1.02 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.79 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 0.48 % · Coverage of this test family: 50 %
Nominal family weight in the overall panel: 0.48 % · Coverage of this test family: 83 %
Nominal family weight in the overall panel: 0.48 % · Coverage of this test family: 50 %
Nominal family weight in the overall panel: 0.48 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.02 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.02 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.02 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 0.48 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.79 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.79 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.79 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 2.38 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 2.38 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 2.38 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.02 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 0.48 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.43 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 3.57 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 3.57 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.02 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.02 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 0.48 % · Coverage of this test family: 100 %
Each evaluator measures different capabilities under its own conditions. Test series, composite indices and their components stay separate. The detailed results below retain their scales, configurations and source dates.
| Evaluator | Test series | Composite indices | Recorded active measurements |
|---|---|---|---|
| Artificial Analysis | 10 | 1 | 13 |
| Vals AI | 27 | 2 | 211 |
| LMArena | 4 | 0 | 43 |
| LiveBench | 0 | 1 | 8 |
| Epoch AI | 6 | 0 | 12 |
| Scale AI Evals | 3 | 0 | 3 |
Coverage is not a quality ranking. Overlapping tests and multiple settings do not count as independent experiments. Vendor claims, historical and disputed results are excluded from this overview and remain labelled in the detailed evidence.
Page 1 of 25
A regularly refreshed mix of objectively scored tasks across seven categories. The composite applies only to the specific release and its weighting.
| Sub-task | Claude Fable 5 (This model) | GPT-5.6 Sol | GPT-5.6 Terra | GPT-5.5 |
|---|---|---|---|---|
| Agentic coding | 62.2 (best value in this row) | 56.2 | 54.9 | 54 |
| Overall | 82.97 (best value in this row) | 81.05 | 77.94 | 80.19 |
| Coding | 86 (best value in this row) | 83.9 | 78.2 | 82.1 |
| Data analysis | 80.5 | 79.8 | 79.3 | 81.6 (best value in this row) |
| Instruction following | 75.8 (best value in this row) | 71.8 | 64.6 | 70.7 |
| Language | 90.7 (best value in this row) | 87.7 | 82.9 | 87.4 |
| Mathematics | 96 | 96.2 (best value in this row) | 94.9 | 95.9 |
| Reasoning | 89.7 | 91.7 (best value in this row) | 90.6 | 89.7 |
Unit: pointshigher is betterAs of September 2, 2026Source: LiveBenchbars scaled within each row, not across rows
Overall
1,161 complex, often multimodal puzzles test creative problem solving beyond well-defined academic tasks. Puzzle solving is a narrow specialty and does not replace professional or everyday task evaluation.
higher is betterAs of August 26, 2026Scale: 0% - 100%
Overall
600 realistic finance questions with weighted criteria, including a 300-question hard subset. An o4-mini judge scores the responses, so domain correctness and operational reliability remain separate questions.
higher is betterAs of August 26, 2026Scale: 0% - 100%
Overall
500 realistic legal questions with weighted criteria across jurisdictions and practice areas. The benchmark measures professional response quality but cannot replace legal review or human accountability.
higher is betterAs of August 26, 2026Scale: 0% - 100%
Binary resolution, pass@1
20 multi-hour repository tasks test very long software work with binary end-to-end resolution. Scores belong to the v1.0 agent setup. SWE-Marathon v1.1 has been released since July 2026. This dataset records v1.0 results only.
Note (Claude Fable 5): Two refusals and three unavailable provider-ban trials were counted as zero.
higher is betterAs of August 9, 2026Scale: 0% - 100%
Page 1 of 25
One SVG prompt and fixed output settings. Captures are shown only with 0 reported reasoning tokens or documented lack of reasoning controls. Identical test conditions do not make the models' internal compute identical.
Unavailable in this round
A community classic for free-form SVG drawing.
Claude Fable 5
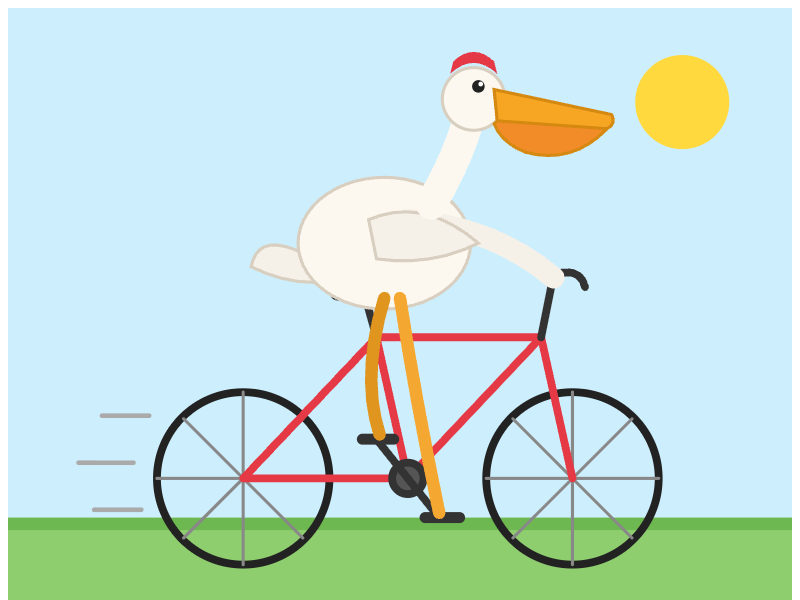
Reasoning (requested): high
Visually reviewed. This individual test does not establish overall model quality.
Generate an SVG of a pelican riding a bicycle
Token limit including reasoning: 8,192 tokens
Task origin (Simon Willison)59.8 / 100