
Grok 4.5
Unavailable in this round
xAI
Grok 4.5 was trained for multi-step software engineering and technical work.
xAI shows complete applications from short specifications and points to Rust, C, and C++ tasks. The weights are not open, so Grok 4.5 remains a service model rather than a locally downloadable checkpoint.
The index averages rank percentiles from 10 documented comparison cohorts.
Page 1 of 17
Kaggle score
1,000 verified short-answer prompts test factual knowledge without search or other tools. It does not measure document grounding, web research, or a RAG system.
higher is betterAs of August 9, 2026Scale: 0% - 100%
Binary resolution, pass@1
20 multi-hour repository tasks test very long software work with binary end-to-end resolution. Scores belong to the v1.0 agent setup. SWE-Marathon v1.1 has been released since July 2026. This dataset records v1.0 results only.
Note: Two refusals and three unavailable provider-ban trials were counted as zero.
higher is betterAs of August 9, 2026Scale: 0% - 100%
| Sub-task | Grok 4.5 (This model) | Grok 4.3 |
|---|---|---|
| CLI | 25.46% (best value in this row) | 9.06% |
| COBOL | 70% (best value in this row) | 0% |
higher is betterAs of August 11, 2026Source: Vals AIbars scaled within each row, not across rows
Code Quality
higher is betterAs of August 11, 2026Scale: 0 rating - 4.08 rating
Overall
higher is betterAs of September 29, 2026Scale: 0% - 100%
Overall
502 technical decision points from engineering and research workflows. Each choice is presented in both answer orders. The overall score averages engineering and research and requires both answer orders to be correct. Unparseable responses count as wrong. Reasoning settings and output budget are part of the setup.
Note (Grok 4.5): 10 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 0 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 0 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 0 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 0 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 17 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 0 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 0 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 3 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 2 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 112 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 24 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 93 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 459 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
higher is betterAs of September 26, 2026Scale: 0% - 100%
Overall
higher is betterAs of September 29, 2026Scale: 0% - 100%
Overall
higher is betterAs of September 29, 2026Scale: 0% - 100%
Page 1 of 17
One SVG prompt and fixed output settings. Captures are shown only with 0 reported reasoning tokens or documented lack of reasoning controls. Identical test conditions do not make the models' internal compute identical.
Unavailable in this round
A community classic for free-form SVG drawing.
Grok 4.5
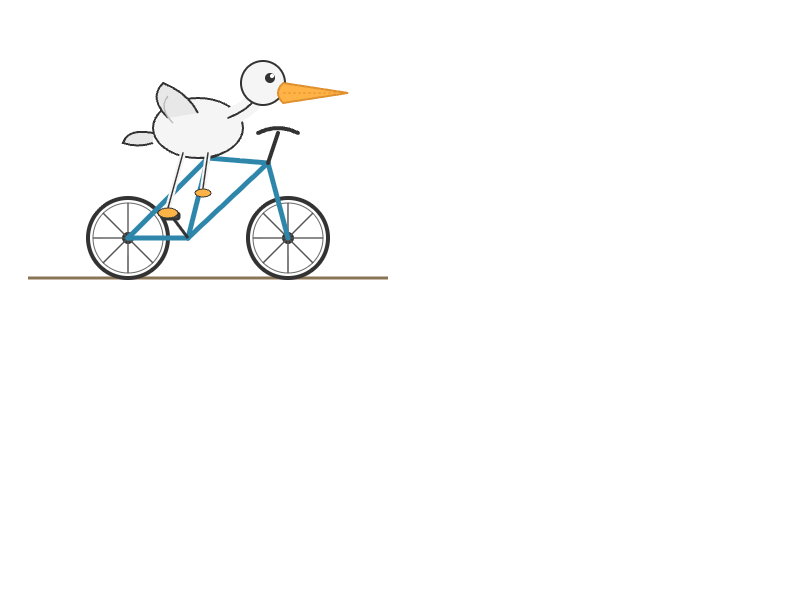
Reasoning (requested): high
Visually reviewed. This individual test does not establish overall model quality.
Generate an SVG of a pelican riding a bicycle
Token limit including reasoning: 8,192 tokens
Task origin (Simon Willison)50.6 / 100
| Specification | Value and source |
|---|---|
| Weights | ProprietarySource |
| Access | APISource |
| Context window | 500,000 tokensSource |
| Knowledge cutoff | February 1, 2026Source |
| Notes | Coding/agentic flagship (first release under SpaceXAI), 500K context, parameter count not disclosedSource |
| API model ID | grok-4.5Source |
| Source status | activeSource |
| Release | 2026-07-16Source |
| Maximum output | not statedSource |
| Input | Text, ImageSource |
| Output | TextSource |
| Tool calling | YesSource |
| Structured output | YesSource |
| Knowledge cutoff | 2026-02-01Source |
| Reasoning mode | low, medium, high, xhighSource |