
GPT-5.6 Terra
Unavailable in this round
OpenAI
OpenAI made GPT-5.6 Terra the default tier for Free and Go users in ChatGPT Work and Codex. Paid users could select Terra alongside GPT-5.6 Sol and GPT-5.6 Luna and choose its reasoning effort.
Terra also supports the programmatic tool calling introduced with GPT-5.6. The model coordinates tools through programs it writes and filters intermediate results before continuing its work.
The LLM comparison hub's selected-panel index averages rank percentiles from 10 documented comparison cohorts. Benchmark meta-scores are shown in the benchmark section.
Benchmark meta-analysis
These Gradually indexes place selected published measurements on a 0 to 100 scale. They are not accuracy percentages and do not guarantee results in your application.
Retrieval dates of the sources used 2026-10-15 - 2026-10-19
Index 63.7 / 100
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Index 69.1 / 100
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Not enough coverage for a score yet
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Not enough coverage for a score yet
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Index 58.1 / 100
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Index 80.3 / 100
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Index 57.0 / 100
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Index 73.4 / 100
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Index 58.5 / 100
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Index 49.6 / 100
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Not enough coverage for a score yet
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Index 60.0 / 100
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Not enough coverage for a score yet
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Not enough coverage for a score yet
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Method version: benchmark-meta-score-v1
The index includes active measurements from reviewed primary sources when at least five models are compared in the same documented comparison slice across dataset, harness, agent, tools, and trial count. Each benchmark series and evaluator contributes one shared setup slice from the newest capture; when dates match, the wider slice is used. When one source and series include several explicitly documented reasoning tiers, the highest documented tier (none through max) is selected, never the best result value. The explicit source label “Non-reasoning” is treated as none. When selecting between multiple results, unknown or ambiguous tiers exclude the model from that series. Unambiguous single configurations do not require a tier ordering. The best individual result for each model is not selected. Equal raw values share the same rank percentile. Multiple series from the same evaluator within a family receive equal weight; evaluators within a family, families within an area, and areas in the overall index then receive equal weight. Unmeasured series remain visible in coverage and bounds. An overall score requires at least four areas, six test families, and two sources. An area score requires at least two test families. Every overall and area score also requires at least 50% of its panel weight.
Published model-specific parameters can differ. This is not a controlled experiment; comparisons with such differences are marked provisional.
Unmeasured portions are not entered as zero. They reduce coverage and contribute only to the displayed bounds. Scores with different coverage are therefore not equally complete.
The bounds hold observed percentiles fixed and allow missing contributions anywhere from 0 to 100. They are not confidence intervals or predictions of future recalculations.
The source count is not a count of independent experiments.
OECD handbook on composite indicatorsAll 41 test families and 12 of 45 raw measurements are listed here. The complete calculation for every model is available in the JSON export.
Nominal family weight in the overall panel: 0.6 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Nominal family weight in the overall panel: 1.02 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Nominal family weight in the overall panel: 0.6 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Nominal family weight in the overall panel: 0.6 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Nominal family weight in the overall panel: 1.02 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Nominal family weight in the overall panel: 0.6 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Nominal family weight in the overall panel: 1.43 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Nominal family weight in the overall panel: 0.6 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Nominal family weight in the overall panel: 2.38 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Nominal family weight in the overall panel: 1.02 % · Coverage of this test family: 50 %
Published configurations differ within this cohort.
Nominal family weight in the overall panel: 1.02 % · Coverage of this test family: 50 %
Published configurations differ within this cohort.
Nominal family weight in the overall panel: 1.43 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Nominal family weight in the overall panel: 1.79 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.79 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 0.48 % · Coverage of this test family: 50 %
Nominal family weight in the overall panel: 0.48 % · Coverage of this test family: 83 %
Nominal family weight in the overall panel: 0.48 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 0.48 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.02 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 7.14 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.02 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.02 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 0.48 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 0.48 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.79 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.79 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.79 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 2.38 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 2.38 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 2.38 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.02 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 0.48 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.43 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 3.57 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 0.6 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 3.57 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.43 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.02 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 1.02 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 0.48 % · Coverage of this test family: 100 %
Nominal family weight in the overall panel: 0.48 % · Coverage of this test family: 100 %
Each evaluator measures different capabilities under its own conditions. Test series, composite indices and their components stay separate. The detailed results below retain their scales, configurations and source dates.
| Evaluator | Test series | Composite indices | Recorded active measurements |
|---|---|---|---|
| Artificial Analysis | 13 | 1 | 80 |
| Vals AI | 30 | 2 | 217 |
| LMArena | 3 | 0 | 42 |
| LiveBench | 0 | 1 | 8 |
| ARC Prize | 2 | 0 | 8 |
Coverage is not a quality ranking. Overlapping tests and multiple settings do not count as independent experiments. Vendor claims, historical and disputed results are excluded from this overview and remain labelled in the detailed evidence.
Page 1 of 35
Overall
1,266 hard-to-find research tasks with short, unambiguous answers. The benchmark rewards persistent fact finding and only partly represents open-ended research reports or typical user questions.
Note (GPT-5.6 Terra): Editorial selection from the vendor table, not a complete extract of the comparison cohort.
Note: Editorial selection from the vendor table, not a complete extract of the comparison cohort.
Note: Editorial selection from the vendor table, not a complete extract of the comparison cohort.
Note: Editorial selection from the vendor table, not a complete extract of the comparison cohort.
Note: Editorial selection from the vendor table, not a complete extract of the comparison cohort.
Note: Editorial selection from the vendor table, not a complete extract of the comparison cohort.
higher is betterAs of September 2, 2026Scale: 0% - 100%
A regularly refreshed mix of objectively scored tasks across seven categories. The composite applies only to the specific release and its weighting.
| Sub-task | GPT-5.6 Terra (This model) | Claude Fable 5 | GPT-5.6 Sol | GPT-5.5 |
|---|---|---|---|---|
| Agentic coding | 54.9 | 62.2 (best value in this row) | 56.2 | 54 |
| Coding | 78.2 | 86 (best value in this row) | 83.9 | 82.1 |
| Data analysis | 79.3 | 80.5 | 79.8 | 81.6 (best value in this row) |
| Overall | 77.94 | 82.97 (best value in this row) | 81.05 | 80.19 |
| Instruction following | 64.6 | 75.8 (best value in this row) | 71.8 | 70.7 |
| Language | 82.9 | 90.7 (best value in this row) | 87.7 | 87.4 |
| Mathematics | 94.9 | 96 | 96.2 (best value in this row) | 95.9 |
| Reasoning | 90.6 | 89.7 | 91.7 (best value in this row) | 89.7 |
Unit: pointshigher is betterAs of September 2, 2026Source: LiveBenchbars scaled within each row, not across rows
Overall
502 technical decision points from engineering and research workflows. Each choice is presented in both answer orders. The overall score averages engineering and research and requires both answer orders to be correct. Unparseable responses count as wrong. Reasoning settings and output budget are part of the setup.
Note (GPT-5.6 Terra): 0 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 0 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 0 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 0 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 10 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 17 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 0 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 0 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 3 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 2 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 112 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 24 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 93 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Note: 459 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
higher is betterAs of September 26, 2026Scale: 0% - 100%
Overall
Agentic evaluation of tasks in reproducible terminal environments. The agent, tools, environment, and reasoning level are part of the result. Scores from older Terminal-Bench versions are not directly comparable.
Note (GPT-5.6 Terra): Selection of exactly identified models from the official 35-row leaderboard. Agents and reasoning efforts differ. These values do not belong to the separate Vals Mini-SWE-agent cohort.
Note: Selection of exactly identified models from the official 35-row leaderboard. Agents and reasoning efforts differ. These values do not belong to the separate Vals Mini-SWE-agent cohort.
Note: Selection of exactly identified models from the official 35-row leaderboard. Agents and reasoning efforts differ. These values do not belong to the separate Vals Mini-SWE-agent cohort.
higher is betterAs of October 15, 2026Scale: 0% - 100%
Page 1 of 35
One SVG prompt and fixed output settings. Captures are shown only with 0 reported reasoning tokens or documented lack of reasoning controls. Identical test conditions do not make the models' internal compute identical.
Unavailable in this round
A community classic for free-form SVG drawing.
GPT-5.6 Terra
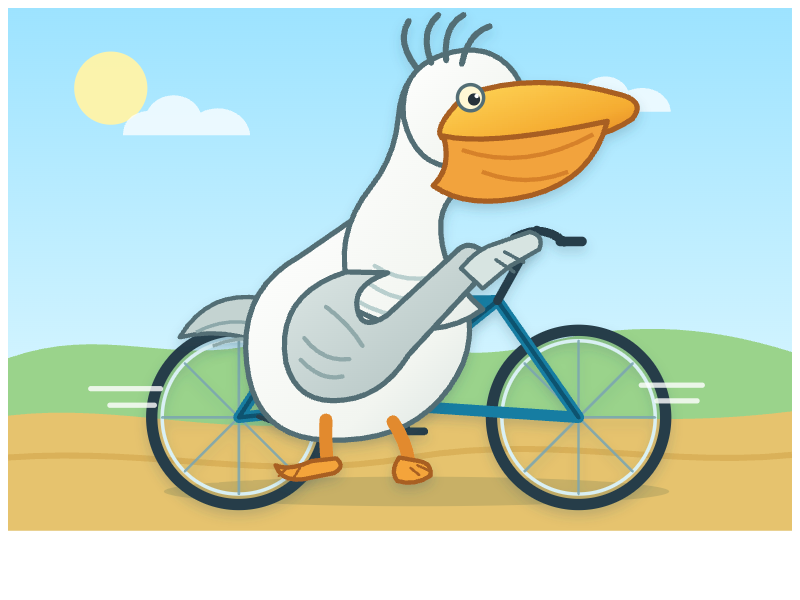
Reasoning (requested): high
Visually reviewed. This individual test does not establish overall model quality.
Generate an SVG of a pelican riding a bicycle
Token limit including reasoning: 8,192 tokens
Task origin (Simon Willison)64.2 / 100
| Specification | Value and source |
|---|---|
| Weights | ProprietarySource |
| Access | APISource |
| Context window | 1,050,000 tokensSource |
| Knowledge cutoff | February 16, 2026Source |
| Notes | Balanced tier of the GPT-5.6 family. Generally available from 2026-07-09. Default model for Free and Go users on ChatGPT Work and Codex, effort-selectable on paid tiers. Matches GPT-5.5 quality at roughly half the price ($2.50 input / $15 output per 1M tokens). Terminal-Bench 2.1 82.5%.Source |
| API model ID | gpt-5.6-terraSource |
| Maximum output | 128,000 tokensSource |
| Knowledge cutoff | 2026-02-16Source |
| Input | Text, ImageSource |
| Output | TextSource |
| Reasoning mode | none, low, medium, high, xhigh, maxSource |
| API interfaces | Responses API, Chat Completions APISource |
| Tool calling | YesSource |
| Structured output | YesSource |
| Release | 2026-07-09Source |