Compare published benchmark results from matching versions and cohorts, API pricing, and technical specifications. Any documented test setup differences remain visible.
shared result series
49
distinct benchmarks
22
latest retrieval
2026-09-29
Change model selection
Specifications
General specifications
Release date, availability, context window, architecture, and published parameter counts at a glance. Undisclosed details remain marked as unavailable.
Specifications for GPT-5.6 Terra and Mistral Medium 3.5
The table compares official standard API rates per 1M tokens, including published cache pricing. Batch, fast, priority, regional surcharges, tool calls, and cloud platform pricing are excluded.
API pricing for GPT-5.6 Terra and Mistral Medium 3.5
Key to the marks:better valuebetter, but not conclusivetie
Pricing by provider
Direct developer pricing and provider endpoint tariffs routed through OpenRouter are listed separately. Prices are in USD per 1M tokens. Context-dependent direct tiers plus regional, Flex, Priority, and other OpenRouter tariffs remain individually identifiable.
Provider pricing for GPT-5.6 Terra and Mistral Medium 3.5
Only published results with the same benchmark version, task, metric, and comparison cohort are paired. Different reasoning levels, agents, harnesses, or output limits appear directly in the table.
Capability profile from matched benchmarks
Each axis averages directly matched benchmark families. A value of 100 means the stronger value within this pair, not a universal quality score.
GPT-5.6 Terra
Mistral Medium 3.5
Coding: 100 / 28.1 (3 benchmark families)
Reasoning: 100 / 38.3 (1 benchmark family)
Mathematics: 100 / 12.2 (1 benchmark family)
Knowledge: 100 / 86.9 (1 benchmark family)
Finance: 100 / 56.7 (6 benchmark families)
Legal: 100 / 36.1 (2 benchmark families)
Agentic tasks: 100 / 50.2 (1 benchmark family)
Health: 100 / 79.7 (2 benchmark families)
20 matched rows from 20 benchmark families were considered. The radar shows 8 of 10 comparable categories.
GPT-5.6 TerraMistral Medium 3.5
Code MigrationOverall. Higher is better. No documented setup difference
GPT-5.6 TerraWinner47.804 %
Mistral Medium 3.55.127 %
CorpFin v2Overall. Higher is better. No documented setup difference
GPT-5.6 TerraWinner65.307 %
Mistral Medium 3.558.78 %
EMBOverall. Higher is better. No documented setup difference
GPT-5.6 TerraWinner66.205 %
Mistral Medium 3.511.185 %
Finance Agent (v2)Overall. Higher is better. No documented setup difference
GPT-5.6 TerraWinner54.436 %
Mistral Medium 3.532.103 %
GPQA DiamondOverall. Higher is better. No documented setup difference
GPT-5.6 TerraWinner90.909 %
Mistral Medium 3.534.848 %
Harvey's Legal Agent BenchmarkOverall · Task fully resolved. Higher is better. No documented setup difference
GPT-5.6 TerraWinner0.833 %
Mistral Medium 3.50.417 %
Legal Research BenchOverall · All-pass. Higher is better. No documented setup difference
GPT-5.6 TerraWinner41.346 %
Mistral Medium 3.59.135 %
LMArena Text, Style ControlOverall. Higher is better. Test setup not documented as identical
GPT-5.6 TerraHigher measured value1,465.012
Mistral Medium 3.51,426.128
MedCodeOverall. Higher is better. No documented setup difference
GPT-5.6 TerraWinner43.414 %
Mistral Medium 3.533.752 %
MedScribeOverall. Higher is better. No documented setup difference
GPT-5.6 TerraWinner82.869 %
Mistral Medium 3.567.728 %
MMLU-ProOverall. Higher is better. No documented setup difference
GPT-5.6 TerraWinner86.659 %
Mistral Medium 3.575.335 %
MortgageTaxOverall. Higher is better. No documented setup difference
GPT-5.6 TerraWinner67.329 %
Mistral Medium 3.528.895 %
Key to the marks:better valuebetter, but not conclusivetie
Benchmark scores for GPT-5.6 Terra and Mistral Medium 3.5
Benchmark and task
GPT-5.6 Terra
Mistral Medium 3.5
Source
Code MigrationOverallTest details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is better
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 35,323 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 11,693 anonymous pairwise votes.
Higher measured value1,465.012
95% confidence interval: ±4.484The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,426.128
95% confidence interval: ±6.42The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: arxiv:2609.25804v2Metric: both-orders-correct, engineering/research macro averageScoring: Higher is betterGPT-5.6 Terra: Reasoning: default, Output limit: 65,536 tokens, Attempts: 502 questions, two option orders each Mistral Medium 3.5: Reasoning: high, Output limit: 65,536 tokens, Attempts: 502 questions, two option orders eachSame prompt for all models. Each of 502 questions is shown twice with the options reversed. Average of engineering and research success rates, requiring both orders to be correct. 65,536-token output budget; unparseable answers count as wrong.
Higher measured value54 %
0 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
37.7 %
24 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
LMArena Text, Style ControlBusiness, management and financeTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 6,719 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 2,256 anonymous pairwise votes.
Higher measured value1,465.595
95% confidence interval: ±8.012The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,430.173
95% confidence interval: ±12.827The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 2,786 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 621 anonymous pairwise votes.
Higher measured value1,515.521
95% confidence interval: ±11.87The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,446.524
95% confidence interval: ±23.931The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 9,671 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 3,282 anonymous pairwise votes.
Higher measured value1,515.765
95% confidence interval: ±6.983The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,477.898
95% confidence interval: ±10.854The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 7,285 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 1,999 anonymous pairwise votes.
Higher measured value1,427.927
95% confidence interval: ±8.055The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,397.828
95% confidence interval: ±13.94The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 14,288 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 5,562 anonymous pairwise votes.
Higher measured value1,471.311
95% confidence interval: ±5.972The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,442.84
95% confidence interval: ±8.53The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlEntertainment, sports and mediaTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 8,870 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 2,618 anonymous pairwise votes.
Higher measured value1,431.725
95% confidence interval: ±7.383The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,394.24
95% confidence interval: ±12.151The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 26,279 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 8,856 anonymous pairwise votes.
Higher measured value1,472.298
95% confidence interval: ±5.902The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,419.562
95% confidence interval: ±8.482The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 4,170 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 1,205 anonymous pairwise votes.
Higher measured value1,503.975
95% confidence interval: ±9.777The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,433.7
95% confidence interval: ±17.235The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 1,080 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 453 anonymous pairwise votes.
Higher measured value1,497.767
95% confidence interval: ±19.526The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,435.855
95% confidence interval: ±29.943The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 556 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 173 anonymous pairwise votes.
Higher measured value1,480.973
95% confidence interval: ±25.503The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,447.96
95% confidence interval: ±43.885The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 23,384 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 7,627 anonymous pairwise votes.
Higher measured value1,487.623
95% confidence interval: ±5.24The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,444.677
95% confidence interval: ±7.686The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 9,312 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 3,821 anonymous pairwise votes.
Higher measured value1,488.994
95% confidence interval: ±7.007The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,455.806
95% confidence interval: ±10.148The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 12,681 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 3,827 anonymous pairwise votes.
Higher measured value1,461.52
95% confidence interval: ±6.366The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,420.763
95% confidence interval: ±10.011The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 687 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 188 anonymous pairwise votes.
Higher measured value1,418.19
95% confidence interval: ±23.335The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,392.677
95% confidence interval: ±43.291The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlLegal and governmentTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 3,037 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 893 anonymous pairwise votes.
Higher measured value1,475.63
95% confidence interval: ±11.483The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,437.755
95% confidence interval: ±20.721The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlLife, physical and social scienceTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 5,778 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 1,939 anonymous pairwise votes.
Higher measured value1,476.248
95% confidence interval: ±8.424The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,435.825
95% confidence interval: ±13.971The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 16,723 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 5,065 anonymous pairwise votes.
Higher measured value1,466.564
95% confidence interval: ±6.008The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,428.117
95% confidence interval: ±9.119The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 1,552 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 565 anonymous pairwise votes.
Higher measured value1,478.041
95% confidence interval: ±14.946The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,428.606
95% confidence interval: ±24.143The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 1,977 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 653 anonymous pairwise votes.
Higher measured value1,484.216
95% confidence interval: ±13.727The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,438.481
95% confidence interval: ±22.896The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlMedicine and healthcareTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 2,578 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 844 anonymous pairwise votes.
Higher measured value1,464.487
95% confidence interval: ±12.478The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,421.161
95% confidence interval: ±21.257The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 5,820 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 1,925 anonymous pairwise votes.
Higher measured value1,470.553
95% confidence interval: ±8.502The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,432.256
95% confidence interval: ±14.007The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 21,028 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 6,131 anonymous pairwise votes.
Higher measured value1,453.774
95% confidence interval: ±5.34The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,406.139
95% confidence interval: ±8.159The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 504 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 235 anonymous pairwise votes.
Higher measured value1,461.59
95% confidence interval: ±25.783The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,415.979
95% confidence interval: ±38.135The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 3,933 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 1,242 anonymous pairwise votes.
Higher measured value1,466.955
95% confidence interval: ±9.836The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,410.34
95% confidence interval: ±17.157The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlSoftware and IT servicesTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 13,888 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 4,587 anonymous pairwise votes.
Higher measured value1,503.978
95% confidence interval: ±6.109The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,468.806
95% confidence interval: ±9.304The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 1,029 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 393 anonymous pairwise votes.
Higher measured value1,466.513
95% confidence interval: ±19.34The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,392.394
95% confidence interval: ±31.573The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlWriting, literature and languageTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 9,613 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 2,919 anonymous pairwise votes.
Higher measured value1,445.239
95% confidence interval: ±7.087The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,403.766
95% confidence interval: ±11.409The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Key to the marks:better valuebetter, but not conclusivetie
Our model tests
Our tests
Compare how the models respond to the same prompt. Each test shows the first attempt, with no subsequent fixes to the generated code. These results do not contribute to an overall score.
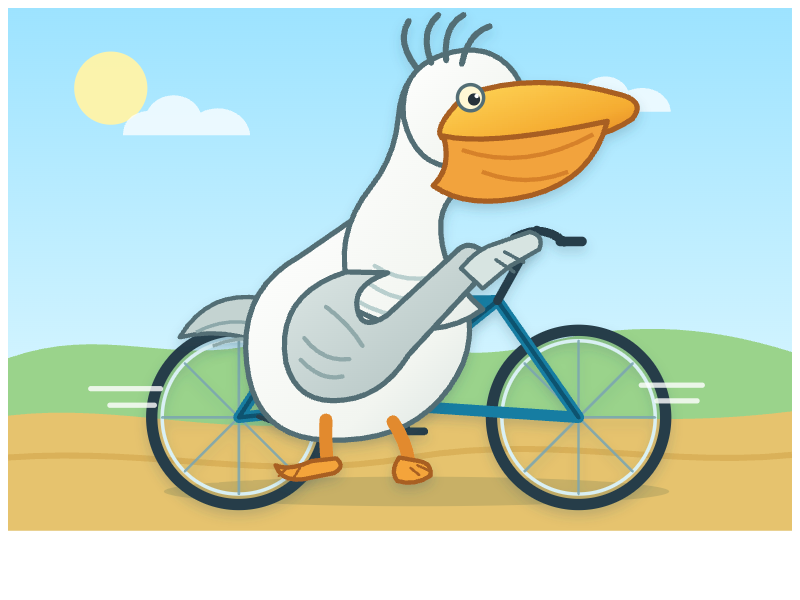
Pelican on a bicycle
A community classic for free-form SVG drawing.
GPT-5.6 Terra
A community classic for free-form SVG drawing.
Reasoning (requested): high
First attempt
Run date
7 Sept 2026
API provider
openrouter
Requested API model
openai/gpt-5.6-terra
API model reported in response
openai/gpt-5.6-terra
Reasoning setting
high
Pinned endpoint
OpenAI | openai/gpt-5.6-terra-20260709
Temperature
Provider default
Token limit including reasoning
8,192 tokens
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating
Response time
64.6 s
Visually reviewed. This individual test does not establish overall model quality.
Mistral Medium 3.5
API access was unavailable for this run. The model was not evaluated.
Reasoning (requested): high
First attempt
Run date
7 Sept 2026
API provider
openrouter
Requested API model
mistralai/mistral-medium-3-5
Reasoning setting
high
Pinned endpoint
Mistral | mistralai/mistral-medium-3.5-20260430
Temperature
Provider default
Token limit including reasoning
8,192 tokens
Test protocol
community-visual-tests-v1
Technical checks
Not run
Not yet visually reviewed. A successful recording does not confirm correct physics or full compliance with the prompt.
Your workload, budget, and required context length matter most. A coding benchmark says little about visual understanding or agent performance.
The standard price table uses direct developer rates. The provider comparison labels OpenRouter endpoints, regions, and special tariffs separately.
Every result links to its measurement source and retrieval date. Labels distinguish vendor reports, official benchmark leaderboards, and independent evaluations. Disputed or archived results are excluded.
More matchups
Related LLM comparisons
Compare GPT-5.6 Terra and Mistral Medium 3.5 with other leading models using the same data and benchmark logic.