Compare published benchmark results from matching versions and cohorts, API pricing, and technical specifications. Any documented test setup differences remain visible.
shared result series
44
distinct benchmarks
17
latest retrieval
2026-09-29
Change model selection
Specifications
General specifications
Release date, availability, context window, architecture, and published parameter counts at a glance. Undisclosed details remain marked as unavailable.
The table compares official standard API rates per 1M tokens, including published cache pricing. Batch, fast, priority, regional surcharges, tool calls, and cloud platform pricing are excluded.
Key to the marks:better valuebetter, but not conclusivetie
Pricing by provider
Direct developer pricing and provider endpoint tariffs routed through OpenRouter are listed separately. Prices are in USD per 1M tokens. Context-dependent direct tiers plus regional, Flex, Priority, and other OpenRouter tariffs remain individually identifiable.
Provider pricing for GLM-5.2 and Mistral Medium 3.5
Only published results with the same benchmark version, task, metric, and comparison cohort are paired. Different reasoning levels, agents, harnesses, or output limits appear directly in the table.
Capability profile from matched benchmarks
Each axis averages directly matched benchmark families. A value of 100 means the stronger value within this pair, not a universal quality score.
GLM-5.2
Mistral Medium 3.5
Coding: 100 / 32.7 (3 benchmark families)
Reasoning: 100 / 40.7 (1 benchmark family)
Knowledge: 100 / 86.9 (1 benchmark family)
Finance: 100 / 66.1 (4 benchmark families)
Legal: 100 / 17.6 (2 benchmark families)
Agentic tasks: 100 / 57.5 (1 benchmark family)
Health: 100 / 81.9 (2 benchmark families)
Overall: 100 / 33.8 (1 benchmark family)
15 matched rows from 15 benchmark families were considered. The radar shows 8 of 8 comparable categories.
GLM-5.2Mistral Medium 3.5
Code MigrationOverall. Higher is better. No documented setup difference
GLM-5.2Winner37.87 %
Mistral Medium 3.55.127 %
CorpFin v2Overall. Higher is better. No documented setup difference
GLM-5.2Winner66.123 %
Mistral Medium 3.558.78 %
EMBOverall. Higher is better. No documented setup difference
GLM-5.2Winner61.532 %
Mistral Medium 3.511.185 %
Finance Agent (v2)Overall. Higher is better. No documented setup difference
GLM-5.2Winner49.699 %
Mistral Medium 3.532.103 %
GPQA DiamondOverall. Higher is better. No documented setup difference
GLM-5.2Winner85.606 %
Mistral Medium 3.534.848 %
Harvey's Legal Agent BenchmarkOverall · Task fully resolved. Higher is better. No documented setup difference
GLM-5.2Winner7.083 %
Mistral Medium 3.50.417 %
Legal Research BenchOverall · All-pass. Higher is better. No documented setup difference
GLM-5.2Winner31.25 %
Mistral Medium 3.59.135 %
LMArena Text, Style ControlOverall. Higher is better. Test setup not documented as identical
GLM-5.2Higher measured value1,475.557
Mistral Medium 3.51,426.128
MedCodeOverall. Higher is better. No documented setup difference
GLM-5.2Winner40.771 %
Mistral Medium 3.533.752 %
MedScribeOverall. Higher is better. No documented setup difference
GLM-5.2Winner83.534 %
Mistral Medium 3.567.728 %
MMLU-ProOverall. Higher is better. No documented setup difference
GLM-5.2Winner86.714 %
Mistral Medium 3.575.335 %
SWE-bench VerifiedOverall. Higher is better. No documented setup difference
GLM-5.2Winner82.8 %
Mistral Medium 3.566.4 %
Key to the marks:better valuebetter, but not conclusivetie
Benchmark scores for GLM-5.2 and Mistral Medium 3.5
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 43,570 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 11,693 anonymous pairwise votes.
Higher measured value1,475.557
95% confidence interval: ±4.358The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,426.128
95% confidence interval: ±6.42The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: arxiv:2609.25804v2Metric: both-orders-correct, engineering/research macro averageScoring: Higher is betterGLM-5.2: Reasoning: max, Temperature: 1, Output limit: 65,536 tokens, Attempts: 502 questions, two option orders each Mistral Medium 3.5: Reasoning: high, Output limit: 65,536 tokens, Attempts: 502 questions, two option orders eachSame prompt for all models. Each of 502 questions is shown twice with the options reversed. Average of engineering and research success rates, requiring both orders to be correct. 65,536-token output budget; unparseable answers count as wrong.
Higher measured value53.9 %
17 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
37.7 %
24 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
LMArena Text, Style ControlBusiness, management and financeTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 8,496 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 2,256 anonymous pairwise votes.
Higher measured value1,463.368
95% confidence interval: ±7.203The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,430.173
95% confidence interval: ±12.827The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 3,128 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 621 anonymous pairwise votes.
Higher measured value1,518.609
95% confidence interval: ±11.079The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,446.524
95% confidence interval: ±23.931The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 12,052 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 3,282 anonymous pairwise votes.
Higher measured value1,512.102
95% confidence interval: ±6.495The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,477.898
95% confidence interval: ±10.854The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 8,448 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 1,999 anonymous pairwise votes.
Higher measured value1,454.763
95% confidence interval: ±7.533The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,397.828
95% confidence interval: ±13.94The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 18,051 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 5,562 anonymous pairwise votes.
Higher measured value1,481.183
95% confidence interval: ±5.559The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,442.84
95% confidence interval: ±8.53The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlEntertainment, sports and mediaTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 10,636 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 2,618 anonymous pairwise votes.
Higher measured value1,445.789
95% confidence interval: ±6.89The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,394.24
95% confidence interval: ±12.151The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 32,339 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 8,856 anonymous pairwise votes.
Higher measured value1,485.037
95% confidence interval: ±5.681The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,419.562
95% confidence interval: ±8.482The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 4,697 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 1,205 anonymous pairwise votes.
Higher measured value1,500.072
95% confidence interval: ±9.185The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,433.7
95% confidence interval: ±17.235The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 1,542 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 453 anonymous pairwise votes.
Higher measured value1,488.582
95% confidence interval: ±16.675The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,435.855
95% confidence interval: ±29.943The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 782 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 173 anonymous pairwise votes.
Higher measured value1,476.834
95% confidence interval: ±21.913The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,447.96
95% confidence interval: ±43.885The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 28,818 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 7,627 anonymous pairwise votes.
Higher measured value1,495.897
95% confidence interval: ±5.005The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,444.677
95% confidence interval: ±7.686The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 12,159 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 3,821 anonymous pairwise votes.
Higher measured value1,496.813
95% confidence interval: ±6.415The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,455.806
95% confidence interval: ±10.148The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 15,327 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 3,827 anonymous pairwise votes.
Higher measured value1,469.988
95% confidence interval: ±5.931The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,420.763
95% confidence interval: ±10.011The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 836 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 188 anonymous pairwise votes.
Higher measured value1,447.697
95% confidence interval: ±21.297The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,392.677
95% confidence interval: ±43.291The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlLegal and governmentTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 3,585 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 893 anonymous pairwise votes.
Higher measured value1,487.63
95% confidence interval: ±10.515The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,437.755
95% confidence interval: ±20.721The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlLife, physical and social scienceTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 7,201 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 1,939 anonymous pairwise votes.
Higher measured value1,497.498
95% confidence interval: ±7.623The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,435.825
95% confidence interval: ±13.971The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 20,329 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 5,065 anonymous pairwise votes.
Higher measured value1,486.388
95% confidence interval: ±5.639The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,428.117
95% confidence interval: ±9.119The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 1,958 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 565 anonymous pairwise votes.
Higher measured value1,486.645
95% confidence interval: ±13.46The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,428.606
95% confidence interval: ±24.143The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 2,410 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 653 anonymous pairwise votes.
Higher measured value1,493.721
95% confidence interval: ±12.422The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,438.481
95% confidence interval: ±22.896The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlMedicine and healthcareTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 3,220 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 844 anonymous pairwise votes.
Higher measured value1,490.857
95% confidence interval: ±11.206The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,421.161
95% confidence interval: ±21.257The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 7,051 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 1,925 anonymous pairwise votes.
Higher measured value1,474.795
95% confidence interval: ±7.81The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,432.256
95% confidence interval: ±14.007The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 25,507 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 6,131 anonymous pairwise votes.
Higher measured value1,462.33
95% confidence interval: ±5.052The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,406.139
95% confidence interval: ±8.159The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 715 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 235 anonymous pairwise votes.
Higher measured value1,454.509
95% confidence interval: ±22.526The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,415.979
95% confidence interval: ±38.135The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 4,911 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 1,242 anonymous pairwise votes.
Higher measured value1,471.865
95% confidence interval: ±8.938The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,410.34
95% confidence interval: ±17.157The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlSoftware and IT servicesTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 17,288 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 4,587 anonymous pairwise votes.
Higher measured value1,505.718
95% confidence interval: ±5.716The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,468.806
95% confidence interval: ±9.304The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 1,283 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 393 anonymous pairwise votes.
Higher measured value1,477.12
95% confidence interval: ±17.336The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,392.394
95% confidence interval: ±31.573The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlWriting, literature and languageTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGLM-5.2: Snapshot: glm-5.2-max, Reasoning: max, Harness: Arena text, style control Mistral Medium 3.5: Snapshot: mistral-medium-3.5, Harness: Arena text, style controlGLM-5.2: Style-controlled Arena rating from 11,517 anonymous pairwise votes.Mistral Medium 3.5: Style-controlled Arena rating from 2,919 anonymous pairwise votes.
Higher measured value1,459.023
95% confidence interval: ±6.581The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,403.766
95% confidence interval: ±11.409The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Key to the marks:better valuebetter, but not conclusivetie
Our model tests
Our tests
Compare how the models respond to the same prompt. Each test shows the latest attempt, with no subsequent fixes to the generated code. Earlier runs remain available in the test details. These results do not contribute to an overall score.
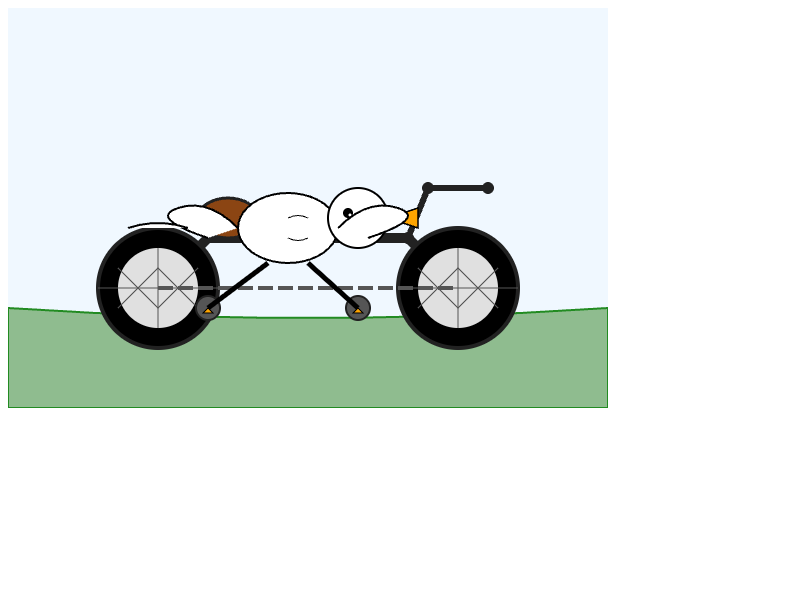
Pelican on a bicycle
A community classic for free-form SVG drawing.
GLM-5.2
The response reached the token limit. No complete recording is available.
Reasoning (requested): high
Current attempt
Run date
2 Oct 2026
API provider
openrouter
Requested API model
z-ai/glm-5.2
API model reported in response
z-ai/glm-5.2
Reasoning setting
high
Pinned endpoint
Z.AI | z-ai/glm-5.2-20260616
Temperature
Provider default
Token limit including reasoning
8,192 tokens
Test protocol
community-visual-tests-v1
Technical checks
Failed
Response time
84 s
Not yet visually reviewed. A successful recording does not confirm correct physics or full compliance with the prompt.
Earlier attempts (2)
1 Oct 2026API request failedReasoning setting: high
7 Sept 2026API request failedReasoning setting: high
Mistral Medium 3.5
A community classic for free-form SVG drawing.
Reasoning (requested): high
Current attempt
Run date
1 Oct 2026
API provider
openrouter
Requested API model
mistralai/mistral-medium-3-5
API model reported in response
mistralai/mistral-medium-3-5
Reasoning setting
high
Pinned endpoint
Mistral | mistralai/mistral-medium-3.5-20260430
Temperature
Provider default
Token limit including reasoning
8,192 tokens
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating
Response time
38.7 s
Visually reviewed. This individual test does not establish overall model quality.
Earlier attempts (1)
7 Sept 2026API request failedReasoning setting: high
Your workload, budget, and required context length matter most. A coding benchmark says little about visual understanding or agent performance.
The standard price table uses direct developer rates. The provider comparison labels OpenRouter endpoints, regions, and special tariffs separately.
Every result links to its measurement source and retrieval date. Labels distinguish vendor reports, official benchmark leaderboards, and independent evaluations. Disputed or archived results are excluded.
More matchups
Related LLM comparisons
Compare GLM-5.2 and Mistral Medium 3.5 with other leading models using the same data and benchmark logic.