Compare published benchmark results from matching versions and cohorts, API pricing, and technical specifications. Any documented test setup differences remain visible.
shared result series
117
distinct benchmarks
23
latest retrieval
2026-09-04
Change model selection
Specifications
General specifications
Release date, availability, context window, architecture, and published parameter counts at a glance. Undisclosed details remain marked as unavailable.
The table compares official standard API rates per 1M tokens, including published cache pricing. Batch, fast, priority, regional surcharges, tool calls, and cloud platform pricing are excluded.
Key to the marks:better valuebetter, but not conclusivetie
Pricing by provider
Direct developer pricing and provider endpoint tariffs routed through OpenRouter are listed separately. Prices are in USD per 1M tokens. Context-dependent direct tiers plus regional, Flex, Priority, and other OpenRouter tariffs remain individually identifiable.
Only published results with the same benchmark version, task, metric, and comparison cohort are paired. Different reasoning levels, agents, harnesses, or output limits appear directly in the table.
Capability profile from matched benchmarks
Each axis averages directly matched benchmark families. A value of 100 means the stronger value within this pair, not a universal quality score.
GPT-5.6 Terra
MiMo-V2.5
Coding: 100 / 63.9 (4 benchmark families)
Reasoning: 100 / 89.7 (1 benchmark family)
Mathematics: 100 / 21.6 (1 benchmark family)
Knowledge: 100 / 95.7 (1 benchmark family)
Finance: 100 / 84.9 (5 benchmark families)
Legal: 83.3 / 71.6 (3 benchmark families)
Agentic tasks: 100 / 78.3 (1 benchmark family)
Multimodal: 100 / 92.5 (1 benchmark family)
24 matched rows from 22 benchmark families were considered. The radar shows 8 of 11 comparable categories.
GPT-5.6 TerraMiMo-V2.5
Code MigrationOverall. Higher is better. No documented setup difference
GPT-5.6 TerraWinner47.804 %
MiMo-V2.514.228 %
CorpFin v2Overall. Higher is better. No documented setup difference
GPT-5.6 TerraWinner65.307 %
MiMo-V2.559.907 %
EMBOverall. Higher is better. No documented setup difference
GPT-5.6 TerraWinner66.205 %
MiMo-V2.555.092 %
Finance Agent (v2)Overall. Higher is better. No documented setup difference
GPT-5.6 TerraWinner54.436 %
MiMo-V2.536.728 %
GPQA DiamondOverall. Higher is better. No documented setup difference
GPT-5.6 TerraWinner90.909 %
MiMo-V2.581.566 %
Harvey's Legal Agent BenchmarkOverall · Task fully resolved. Higher is better. No documented setup difference
GPT-5.6 Terra0.833 %
MiMo-V2.5Winner1.667 %
Legal Research BenchOverall · All-pass. Higher is better. No documented setup difference
GPT-5.6 TerraWinner41.346 %
MiMo-V2.59.135 %
LegalBenchOverall. Higher is better. No documented setup difference
GPT-5.6 TerraWinner85.105 %
MiMo-V2.578.886 %
LiveCodeBench v6Overall. Higher is better. No documented setup difference
GPT-5.6 TerraWinner85.93 %
MiMo-V2.581.512 %
LMArena Text, Style ControlOverall. Higher is better. Test setup not documented as identical
GPT-5.6 TerraHigher measured value1,466.233
MiMo-V2.51,433.798
MedCodeOverall. Higher is better. No documented setup difference
GPT-5.6 TerraWinner43.414 %
MiMo-V2.531.895 %
MedScribeOverall. Higher is better. No documented setup difference
GPT-5.6 TerraWinner82.869 %
MiMo-V2.572.151 %
Key to the marks:better valuebetter, but not conclusivetie
Benchmark scores for GPT-5.6 Terra and MiMo-V2.5
Benchmark and task
GPT-5.6 Terra
MiMo-V2.5
Source
Code MigrationOverallTest details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is better
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control MiMo-V2.5: Snapshot: mimo-v2.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 23,942 anonymous pairwise votes.MiMo-V2.5: Style-controlled Arena rating from 44,540 anonymous pairwise votes.
Higher measured value1,466.233
95% confidence interval: ±5.062The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,433.798
95% confidence interval: ±4.342The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
LMArena Text, Style ControlBusiness, management and financeTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control MiMo-V2.5: Snapshot: mimo-v2.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 4,559 anonymous pairwise votes.MiMo-V2.5: Style-controlled Arena rating from 9,127 anonymous pairwise votes.
Higher measured value1,467.133
95% confidence interval: ±9.403The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,441.542
95% confidence interval: ±7.42The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 30,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 30,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 2.1Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control MiMo-V2.5: Snapshot: mimo-v2.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 1,627 anonymous pairwise votes.MiMo-V2.5: Style-controlled Arena rating from 2,140 anonymous pairwise votes.
Higher measured value1,518.544
95% confidence interval: ±15.369The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,483.45
95% confidence interval: ±13.352The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 30,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 30,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 2.1Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 1Metric: mean reviewer code-quality ratingScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Terra: Snapshot: gpt-5.6-terra-xhigh, Reasoning: xhigh, Harness: Arena text, style control MiMo-V2.5: Snapshot: mimo-v2.5, Harness: Arena text, style controlGPT-5.6 Terra: Style-controlled Arena rating from 6,608 anonymous pairwise votes.MiMo-V2.5: Style-controlled Arena rating from 12,854 anonymous pairwise votes.
Higher measured value1,518.601
95% confidence interval: ±8.056The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,491.02
95% confidence interval: ±6.676The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 30,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 30,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 2.1Metric: accuracyScoring: Higher is betterGPT-5.6 Terra: Reasoning: xhigh, Output limit: 128,000 tokens MiMo-V2.5: Temperature: 1, Top P: 0.95, Output limit: 128,000 tokens
Key to the marks:better valuebetter, but not conclusivetie
Our model tests
Community tests you can inspect
Compare how the models respond to the same prompt. Each test shows the first attempt, with no subsequent fixes to the generated code. These results do not contribute to an overall score.
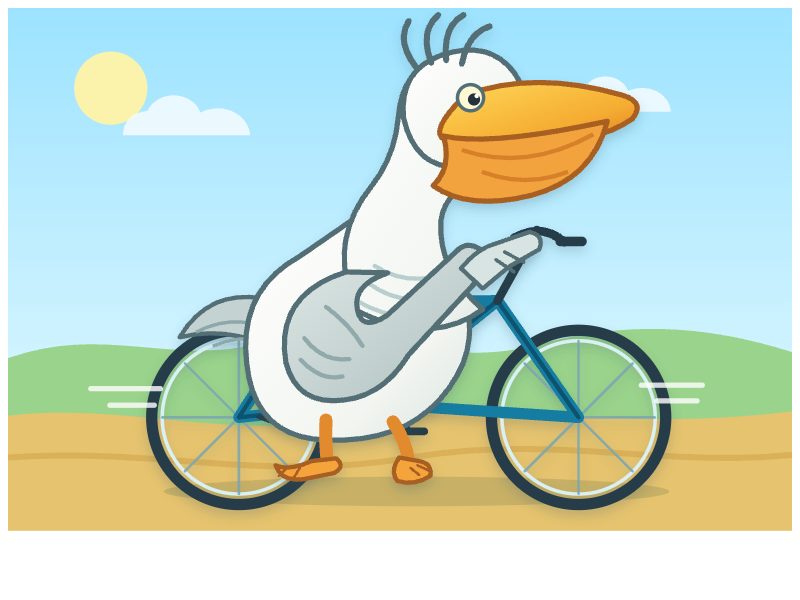
Pelican on a bicycle
A community classic for free-form SVG drawing.
GPT-5.6 Terra
A community classic for free-form SVG drawing.First attempt
Run date
7 Sept 2026
API provider
openrouter
Requested API model
openai/gpt-5.6-terra
API model reported in response
openai/gpt-5.6-terra
Pinned endpoint
OpenAI | openai/gpt-5.6-terra-20260709
Reasoning setting
high
Temperature
Provider default
Token limit including reasoning
8,192 tokens
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating
Response time
64.6 s
Visually reviewed. This individual test does not establish overall model quality.
MiMo-V2.5
API access was unavailable for this run. The model was not evaluated.
First attempt
Run date
7 Sept 2026
API provider
openrouter
Requested API model
xiaomi/mimo-v2.5
Pinned endpoint
Xiaomi | xiaomi/mimo-v2.5-20260422
Reasoning setting
high
Temperature
Provider default
Token limit including reasoning
8,192 tokens
Test protocol
community-visual-tests-v1
Technical checks
Not run
Not yet visually reviewed. A successful recording does not confirm correct physics or full compliance with the prompt.
Your workload, budget, and required context length matter most. A coding benchmark says little about visual understanding or agent performance.
The standard price table uses direct developer rates. The provider comparison labels OpenRouter endpoints, regions, and special tariffs separately.
Every result links to its measurement source and retrieval date. Labels distinguish vendor reports, official benchmark leaderboards, and independent evaluations. Disputed or archived results are excluded.
More matchups
Related LLM comparisons
Compare GPT-5.6 Terra and MiMo-V2.5 with other leading models using the same data and benchmark logic.