
Ling 3.0 Flash
inclusionAI
Ling 3.0 Flash stands out for low active compute alongside a large model capacity. It has 124 billion total parameters but activates about 5.1 billion per token; 35 KDA, 7 MLA layers, 512 experts, and top-8 routing support a 262,144-token context. InclusionAI presents it as the next generation after Ring 2.6 1T.
Reasoning is enabled by default and can be disabled for fast responses. The model card lists tool calls, caching, and testing across more than 10,000 interactive environments as its target. MIT permits reuse of the weights.
The index averages rank percentiles from 10 documented comparison cohorts.
Page 1 of 3
Overall
higher is betterAs of September 29, 2026Scale: 0% - 100%
Overall
higher is betterAs of September 29, 2026Scale: 0% - 100%
Overall
higher is betterAs of September 29, 2026Scale: 0% - 100%
Overall
higher is betterAs of September 29, 2026Scale: 0% - 100%
Overall
higher is betterAs of September 29, 2026Scale: 0% - 100%
Overall
higher is betterAs of September 29, 2026Scale: 0% - 100%
Overall · Task fully resolved
higher is betterAs of September 29, 2026Scale: 0% - 100%
Overall
higher is betterAs of September 29, 2026Scale: 0% - 100%
Overall · All-pass
higher is betterAs of September 29, 2026Scale: 0% - 100%
Overall
higher is betterAs of September 29, 2026Scale: 0% - 100%
Overall
higher is betterAs of September 29, 2026Scale: 0% - 100%
Overall
higher is betterAs of September 29, 2026Scale: 0% - 100%
Page 1 of 3
One SVG prompt and fixed output settings. Captures are shown only with 0 reported reasoning tokens or documented lack of reasoning controls. Identical test conditions do not make the models' internal compute identical.
A community classic for free-form SVG drawing.
Ling 3.0 Flash
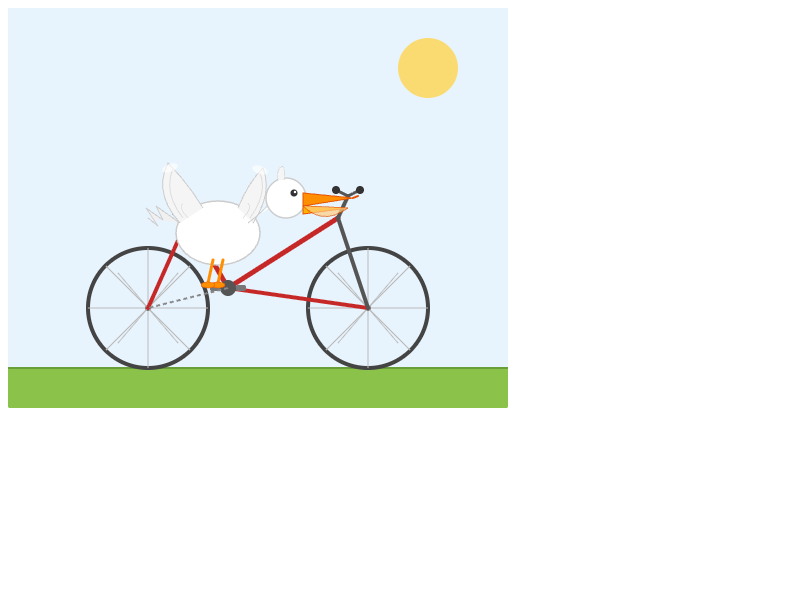
Reasoning (requested): high
Visually reviewed. This individual test does not establish overall model quality.
Generate an SVG of a pelican riding a bicycle
Token limit including reasoning: 8,192 tokens
Task origin (Simon Willison)39.3 / 100
| Specification | Value and source |
|---|---|
| Weights | Open weightsSource |
| Access | API, LocalSource |
| Parameters | 124BSource |
| Active parameters | 5.1BSource |
| Context window | 262,144 tokensSource |
| License | MITSource |
| Parameters | 124 BSource |
| Active parameters | 5.1 BSource |
| Architecture | hybrid-linear MoE, 35 KDA layers plus 7 gated MLA layers, 512 routed experts plus one shared expert, top-8 activeSource |
| Context training schedule | 8K -> 32K -> 256KSource |
| Input | TextSource |
| Output | TextSource |
| Reasoning mode | thinking mode enabled by default; temperature 0.6, top_p 0.95, top_k 20Source |
| Tool calling | YesSource |
| Type | Evidence and data date |
|---|---|
| Speed | InclusionAI. Output speed after the first streaming chunk, not total response time. Retrieved September 8, 2026. |
| Price | Base API prices without caching or batch discounts. Higher context tiers and other rates are listed under Costs. |
| Input | Documented modalities. Retrieved September 8, 2026. |
| Output | Documented modalities. Retrieved September 8, 2026. |
| Research status | Research date September 8, 2026. 2 source URLs checked. This documents the inspected sources, not an exhaustive inventory of every publication. |
| Not found in the inspected sources | knowledge-cutoff Original wording The exact Ling-3.0-Flash card does not publish a training-data cutoff. |
| Additional source | Vals AI (retrieved September 29, 2026) |
| Additional source | Vals AI (retrieved September 29, 2026) |
| Additional source | Vals AI (retrieved September 29, 2026) |
| Additional source | Vals AI (retrieved September 29, 2026) |
| Additional source | Vals AI (retrieved September 29, 2026) |
| Additional source | Vals AI (retrieved September 29, 2026) |
| Additional source | Vals AI (retrieved September 29, 2026) |
| Additional source | Vals AI (retrieved September 29, 2026) |
| Additional source | Vals AI (retrieved September 29, 2026) |
| Additional source | Vals AI (retrieved September 29, 2026) |
| Additional source | Vals AI (retrieved September 29, 2026) |
| Additional source | Vals AI (retrieved September 29, 2026) |
| Additional source | Vals AI (retrieved September 29, 2026) |
| Additional source | Vals AI (retrieved September 29, 2026) |
| Additional source | Vals AI (retrieved September 29, 2026) |
| Additional source | Vals AI (retrieved September 29, 2026) |
| Additional source | Vals AI (retrieved September 29, 2026) |
| Additional source | Vals AI (retrieved September 29, 2026) |
| Additional source | Vals AI (retrieved September 29, 2026) |
| Additional source | OpenRouter: Popularity index (derived), CC BY 4.0 |
| Additional source | Vercel AI Gateway: Popularity index (derived), CC BY 4.0 |
| Additional source | Creative Commons Attribution 4.0 |