DeepSeekLanguage modelActive

DeepSeek-V4.1-Flash

DeepSeek-V4.1-Flash is in the upper middle: Rank 29 of 91 in the overall index. Through the API it is cheap.

IntelligenceRank 29 of 91

99.7Overall indexhigher is better

SpeedRank 14 of 100

176Tokens per secondhigher is better

PriceRank 12 of 94

Input $0.15 · Output $0.60

$0.26per 1M tokenslower is better

ContextRank 31 of 101

1Mtokens at once≈ 1,500 A4 pages

PopularityRank 298 of 875

38out of 100same as last month

Summary

It is cheap: $0.26 per 1M tokens (input and output blended); a typical model costs $1.56. At 176 tokens per second it writes faster than a typical model (87). Estimated without own results in: Reasoning and Knowledge.

New in DeepSeek-V4.1-Flash are native image input and asymmetric activation. DeepSeek describes 552 billion backbone parameters, 8 billion active parameters during prefill, 16 billion during decoding, and a 1,000,000-token context window. Reasoning effort can be adjusted more finely than in the original V4-Flash line.

On September 10, 2026, DeepSeek retired the old V4-Flash and V4-Flash-Vision-Exp routes and temporarily redirected them here. The deepseek-flash API name therefore describes the current service rather than the old weights by default.

DeepSeek-V4.1-Flash benchmarks

Overall index (Gradually Meta-Score v4)

20 of 91 models

4 models in this view are measured at a lower reasoning effort than max in the overall index. Dashed column: lower reasoning effort than the top.

GPT-6 Astramax121.3
GPT-6.1 Solmax119.2
Muse Wondermax113.4
GPT-6 Solmax110.6
GPT-5.6 Solmax108.7
DeepSeek-V4.1-Flashmax99.7

DeepSeek-V4.1-Flash by reasoning effort

Points on the overall index scale. The value at max is DeepSeek-V4.1-Flash's overall index; the other efforts derive from the same Artificial Analysis test series. Missing efforts are never estimated.

6080100120nonelowmediumhighxhighmaxGLM-5.3 · low: 89.3GLM-5.3 · max: 100.7GPT-5.6 Terra · low: 83.4GPT-5.6 Terra · medium: 88.1GPT-5.6 Terra · high: 93.7GPT-5.6 Terra · xhigh: 96.3GPT-5.6 Terra · max: 100.7DeepSeek-V4.1-Flash · none: 84.6DeepSeek-V4.1-Flash · max: 99.7
DeepSeek-V4.1-Flashnone 84.6 · max 99.7GLM-5.3low 89.3 · max 100.7GPT-5.6 Terralow 83.4 · medium 88.1 · high 93.7 · xhigh 96.3 · max 100.7Filled dot: effort of the overall index. Shading: 95% range.

Source: Meta-Score v4; tiers: Artificial Analysis

Speed

20 of 100 models

Mercury 2.5576tokens/s · Configuration Reasoning enabled; effort unspecified · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
Gemini 3.1 Flash-Lite336tokens/s · Configuration High effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
Gemini 3.5 Flash-Lite299tokens/s · Configuration High effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
Nemotron 3.5 Lightning245tokens/s · Configuration Reasoning enabled; effort unspecified · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
Claude Haiku 5.5236tokens/s · Configuration Max effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
o3-mini230tokens/s · Configuration High effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
Ling 3.0 Flash199tokens/s · Configuration Reasoning enabled; effort unspecified · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
DeepSeek-V3 0324195tokens/s · Configuration Non-reasoning · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
GPT-5.4 mini191tokens/s · Configuration Xhigh effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
Gemini 3 Flash Preview191tokens/s · Configuration Non-reasoning · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
Gemini 3.5 Flash184tokens/s · Configuration High effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
Gemini 3.6 Flash182tokens/s · Configuration High effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
Command A Plus177tokens/s · Configuration Reasoning enabled; effort unspecified · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
DeepSeek-V4.1-Flash176tokens/s · Configuration Max effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
DeepSeek V4.1 Flash 1017172tokens/s · Configuration Max effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
Qwen 3.7 Max165tokens/s · Configuration Reasoning enabled; effort unspecified · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
GPT-5.4 nano153tokens/s · Configuration Xhigh effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
GPT OSS 20B152tokens/s · Configuration High effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
GPT OSS 120B151tokens/s · Configuration High effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06
Claude Sonnet 5.5151tokens/s · Configuration Max effort · AA 3.0.0, including time to first token, averaged across available workloads and five days · Retrieved 2026-11-06

Output tokens per second, measured by Artificial Analysis

Intelligence vs. price

most attractive area: stronger and cheaper than half of the models shownbest intelligence for the price

80100120$0.10$0.50$2$10$20Gemini 3.6 Flash: 96.7, $1.50Step 5 Preview: 97.3, $1.43MiMo V2.6 Flash: 98.3, $0.18Claude Opus 4.8: 99.0, $10Qwen 3.8 Max 0902: 100.3, $2.48GLM-5.3: 100.7, $2.15GPT-5.6 Terra: 100.7, $4.50MiMo V2.6 Pro: 100.9, $0.54GPT-5.5: 100.9, $11.25Kimi K3: 101.2, $6Grok 4.6: 102.4, $3Grok 4.7: 103.3, $3Claude Haiku 5.5: 103.4, $0.20GPT-6.1 Terra: 105.2, $2Gemini 3.8 Flash: 106.5, $1.50DeepSeek V4.1 Flash 1017: 106.6, $0.26Muse Spark 1.3: 107.4, $2GPT-5.6 Sol: 108.7, $8GPT-6 Sol: 110.6, $4Claude Fable 5: 112.5, $20Kimi K3.1 Pro: 112.9, $4Muse Wonder: 113.4, $8Claude Opus 5: 117.2, $10GPT-6.1 Sol: 119.2, $4GPT-6 Astra: 121.3, $20Gemini 4 Argon: 122.3, $4Claude Sonnet 5.5: 122.8, $4Claude Fable 5.1: 123.8, $20Claude Opus 5.5: 126.1, $8DeepSeek-V4.1-Flash: 99.7, $0.26DeepSeek-V4.1-FlashClaude Opus 5.5Claude Fable 5.1Claude Sonnet 5.5Gemini 4 ArgonGPT-6 AstraGPT-6.1 SolClaude Opus 5Muse WonderKimi K3.1 ProClaude Fable 5GPT-6 SolGPT-5.6 SolMuse Spark 1.3DeepSeek V4.1 Flash 1017Gemini 3.8 FlashGPT-6.1 TerraClaude Haiku 5.5Grok 4.7Grok 4.6Kimi K3GPT-5.5MiMo V2.6 ProGPT-5.6 TerraGLM-5.3Qwen 3.8 Max 0902Claude Opus 4.8MiMo V2.6 FlashStep 5 PreviewGemini 3.6 FlashPrice per 1M tokens (blended)Overall index

DeepSeek-V4.1-Flash by task area

Points, 100 = reference group average · higher is better

AgentsRank 17 of 83106.4
FinanceRank 24 of 96103.7
LegalRank 29 of 66100.8
CodingRank 30 of 9098.8
Mathematicstoo little data97.3
GeneralRank 28 of 6097.1
MultimodalRank 17 of 4695.7
HealthRank 27 of 6895.5

Light bar: too few results for a rank yet. No tests yet: Reasoning, Knowledge.

Text Arena

How people rate the answers in blind comparisons, Elo points with style control · higher is better

20 of 40 models

as of October 30, 2026 · Source: LMArena

WebDev Arena

How people rate generated websites and web apps in blind comparisons, Elo points · higher is better

20 of 43 models

as of October 30, 2026 · Source: LMArena

Terminal-Bench 4.0

Share of tasks the model solves as an agent in the terminal, in percent · higher is better

20 of 38 models

as of November 6, 2026 · Source: Vals AI

Vibe Code Bench

Share of apps the model builds correctly from a description, in percent · higher is better

20 of 51 models

as of November 6, 2026 · Source: Vals AI

Show all 723 published benchmark results

Page 1 of 62

Published benchmarks

LMArena Text, Style Control

Russian prompts

Note (DeepSeek-V4.1-Flash): The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result.

DeepSeek-V4.1-Flash1,479.62 rating
GPT-6 Astra1,470.69 rating

higher is betterAs of October 30, 2026Scale: 0 rating - 1,479.62 rating

Source: LMArena
gradually.ai
Methodology and context
Comparison cohort
lmarena-text-style-control:2026-10-28:russian
Metric
style-controlled Bradley-Terry rating
Scale
No upper bound is documented. The chart spans the recorded values and zero.
Participants
2
Methodology and context
Arena rating from 1,938 published pairwise votes.. Source model ID: lmarena/DeepSeek-V4.1-Flash-20260910 (Max). Source model name: DeepSeek-V4.1-Flash. Provider reported by source: DeepSeek. Model snapshot: DeepSeek-V4.1-Flash-20260910 (Max). Evaluator: LMArena. Dataset type: public-crowdsourced-preferences. Leaderboard date: 2026-10-28. Harness: Arena Text, style control. Reasoning effort: max. Source ID: lmarena. Evidence capture ID: lmarena-323062f70843f40e3f739865c3fe9d806126e412-c2c334909874. Source payload hash: c2c334909874e3f6fdc66b3dd9ed16f71e1a541453d48b55891e61757486d682. Parser version: lmarena-dataset-v1. Imported at: 2026-10-30
Source: LMArena

Coding

Code Migration v1.1

Sub-taskDeepSeek-V4.1-Flash (This model)DeepSeek V4.1 Flash 1017
CLI47.75%59.2% (best value in this row)
COBOL92.5% (best value in this row)92.5% (best value in this row)
Code Quality3.68% (best value in this row)3.48%
Overall58.94%67.52% (best value in this row)

higher is betterAs of November 6, 2026Source: Vals AIbars scaled within each row, not across rows

Methodology and context
Metric
accuracy

Recorded measurement details

LMArena Text, Style Control: Russian prompts (Show measurement, test conditions, and source)
Source value
1479.6194284504727
Score
1479.6194284504727
Metric
style-controlled Bradley-Terry rating
Unit
rating
Benchmark version
style-control-v1
Category
general
Task
russian
Task label
Russian prompts
Direction
Higher is better
Comparison cohort
lmarena-text-style-control:2026-10-28:russian
Confidence interval
13.751435
Source type
official-leaderboard
Evaluator
LMArena
Status
active
Retrieved at
2026-10-30
Methodology
Arena rating from 1,938 published pairwise votes.. Source model ID: lmarena/DeepSeek-V4.1-Flash-20260910 (Max). Source model name: DeepSeek-V4.1-Flash. Provider reported by source: DeepSeek. Model snapshot: DeepSeek-V4.1-Flash-20260910 (Max). Evaluator: LMArena. Dataset type: public-crowdsourced-preferences. Leaderboard date: 2026-10-28. Harness: Arena Text, style control. Reasoning effort: max. Source ID: lmarena. Evidence capture ID: lmarena-323062f70843f40e3f739865c3fe9d806126e412-c2c334909874. Source payload hash: c2c334909874e3f6fdc66b3dd9ed16f71e1a541453d48b55891e61757486d682. Parser version: lmarena-dataset-v1. Imported at: 2026-10-30
Comparison methodology
Arena rating from 1,938 published pairwise votes.. Harness: Arena Text, style control. Reasoning effort: max
Context
The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result.
Source LMArena
Code Migration v1.1: CLI (Show measurement, test conditions, and source)
Source value
47.747
Score
47.747
Metric
accuracy
Unit
%
Benchmark version
1.1
Category
coding
Task
cli
Task label
CLI
Direction
Higher is better
Comparison cohort
vals-code-migration-v1-1:1.1:cli
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-06
Methodology
Source model ID: deepseek/deepseek-v4.1-flash. Source model name: DeepSeek-V4.1-Flash. Provider reported by source: DeepSeek. Evaluator: Vals AI. Dataset type: private. Leaderboard date: 2026-10-30. Reasoning effort: max. Temperature: 1. Top P: 1. Maximum output tokens: 384000. Latency in seconds: 7584.512. Standard error: 2.674. Cost per task in USD: 1.270159. Source ID: vals-ai. Evidence capture ID: vals-code-migration-v1-1-2026-11-06-4085f8f7e916. Source payload hash: 4085f8f7e916ea8f5f458829ef9b624e3f87c68dc0e79642e03f1c9b679b61c0. Parser version: vals-astro-v4. Imported at: 2026-11-06
Comparison methodology
Reasoning effort: max. Temperature: 1. Top P: 1. Maximum output tokens: 384000
Source Vals AI
Code Migration v1.1: COBOL (Show measurement, test conditions, and source)
Source value
92.5
Score
92.5
Metric
accuracy
Unit
%
Benchmark version
1.1
Category
coding
Task
cobol
Task label
COBOL
Direction
Higher is better
Comparison cohort
vals-code-migration-v1-1:1.1:cobol
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-06
Methodology
Source model ID: deepseek/deepseek-v4.1-flash. Source model name: DeepSeek-V4.1-Flash. Provider reported by source: DeepSeek. Evaluator: Vals AI. Dataset type: private. Leaderboard date: 2026-10-30. Reasoning effort: max. Temperature: 1. Top P: 1. Maximum output tokens: 384000. Latency in seconds: 4505.811. Standard error: 6.962. Cost per task in USD: 0.54491. Source ID: vals-ai. Evidence capture ID: vals-code-migration-v1-1-2026-11-06-4085f8f7e916. Source payload hash: 4085f8f7e916ea8f5f458829ef9b624e3f87c68dc0e79642e03f1c9b679b61c0. Parser version: vals-astro-v4. Imported at: 2026-11-06
Comparison methodology
Reasoning effort: max. Temperature: 1. Top P: 1. Maximum output tokens: 384000
Source Vals AI
Code Migration v1.1: Code Quality (Show measurement, test conditions, and source)
Source value
3.675
Score
3.675
Metric
accuracy
Unit
%
Benchmark version
1.1
Category
coding
Task
code_quality
Task label
Code Quality
Direction
Higher is better
Comparison cohort
vals-code-migration-v1-1:1.1:code_quality
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-06
Methodology
Source model ID: deepseek/deepseek-v4.1-flash. Source model name: DeepSeek-V4.1-Flash. Provider reported by source: DeepSeek. Evaluator: Vals AI. Dataset type: private. Leaderboard date: 2026-10-30. Reasoning effort: max. Temperature: 1. Top P: 1. Maximum output tokens: 384000. Latency in seconds: 6814.837. Standard error: 0.036. Cost per task in USD: 1.088847. Source ID: vals-ai. Evidence capture ID: vals-code-migration-v1-1-2026-11-06-4085f8f7e916. Source payload hash: 4085f8f7e916ea8f5f458829ef9b624e3f87c68dc0e79642e03f1c9b679b61c0. Parser version: vals-astro-v4. Imported at: 2026-11-06
Comparison methodology
Reasoning effort: max. Temperature: 1. Top P: 1. Maximum output tokens: 384000
Source Vals AI
Code Migration v1.1: Overall (Show measurement, test conditions, and source)
Source value
58.936
Score
58.936
Metric
accuracy
Unit
%
Benchmark version
1.1
Category
coding
Task
overall
Task label
Overall
Direction
Higher is better
Comparison cohort
vals-code-migration-v1-1:1.1:overall
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-06
Methodology
Source model ID: deepseek/deepseek-v4.1-flash. Source model name: DeepSeek-V4.1-Flash. Provider reported by source: DeepSeek. Evaluator: Vals AI. Dataset type: private. Leaderboard date: 2026-10-30. Reasoning effort: max. Temperature: 1. Top P: 1. Maximum output tokens: 384000. Latency in seconds: 6814.837. Standard error: 2.656. Cost per task in USD: 1.088847. Source ID: vals-ai. Evidence capture ID: vals-code-migration-v1-1-2026-11-06-4085f8f7e916. Source payload hash: 4085f8f7e916ea8f5f458829ef9b624e3f87c68dc0e79642e03f1c9b679b61c0. Parser version: vals-astro-v4. Imported at: 2026-11-06
Comparison methodology
Reasoning effort: max. Temperature: 1. Top P: 1. Maximum output tokens: 384000
Source Vals AI

Page 1 of 62

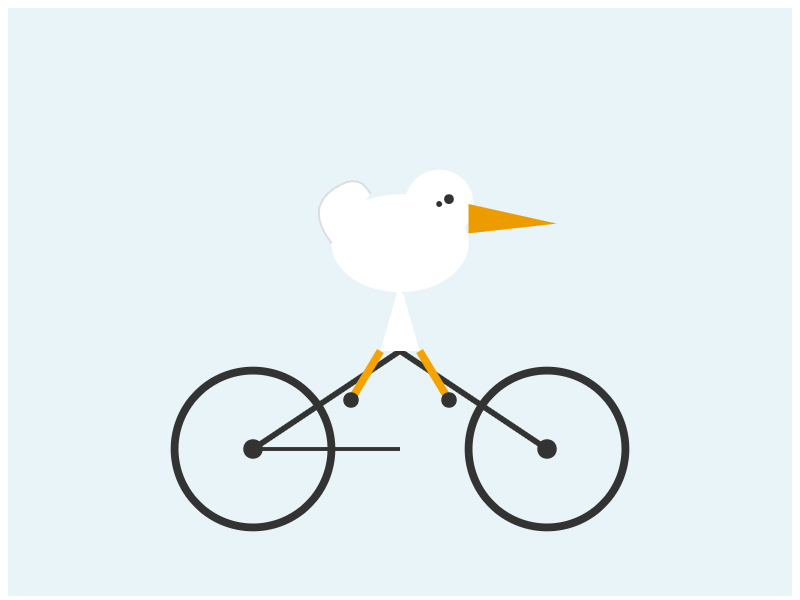
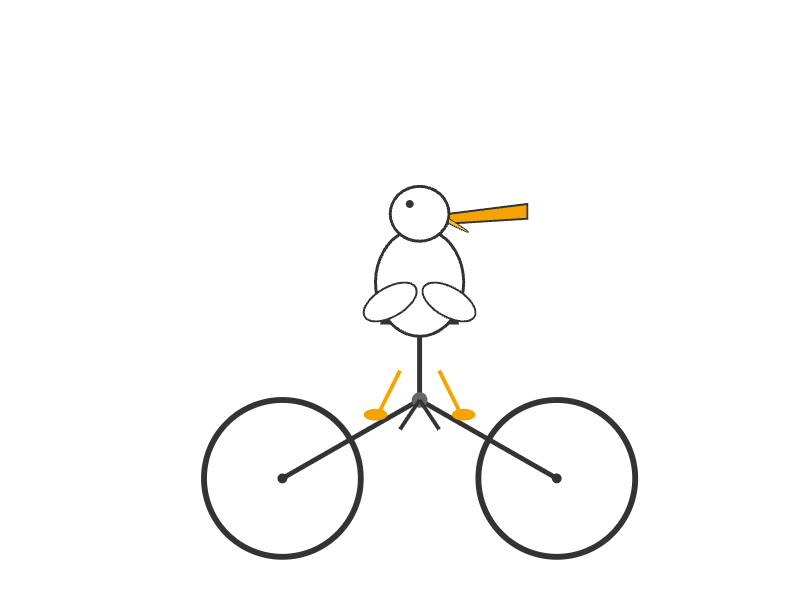
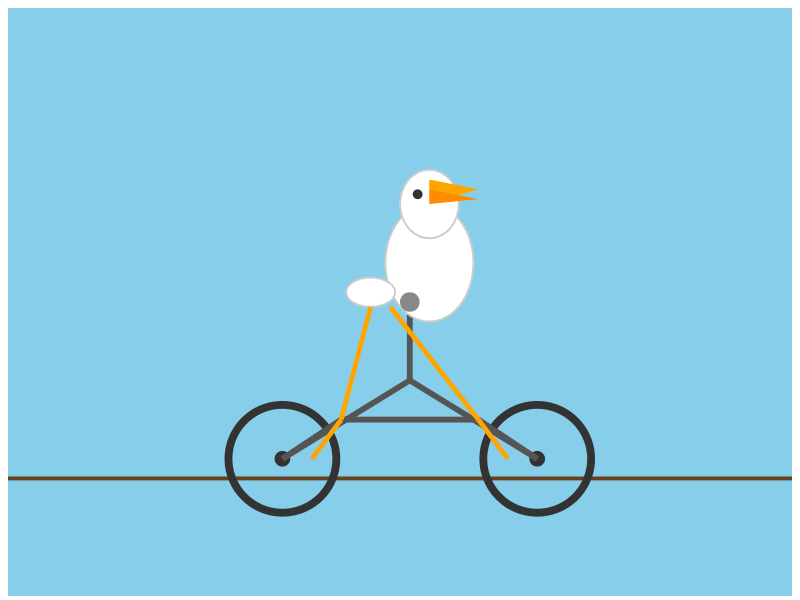
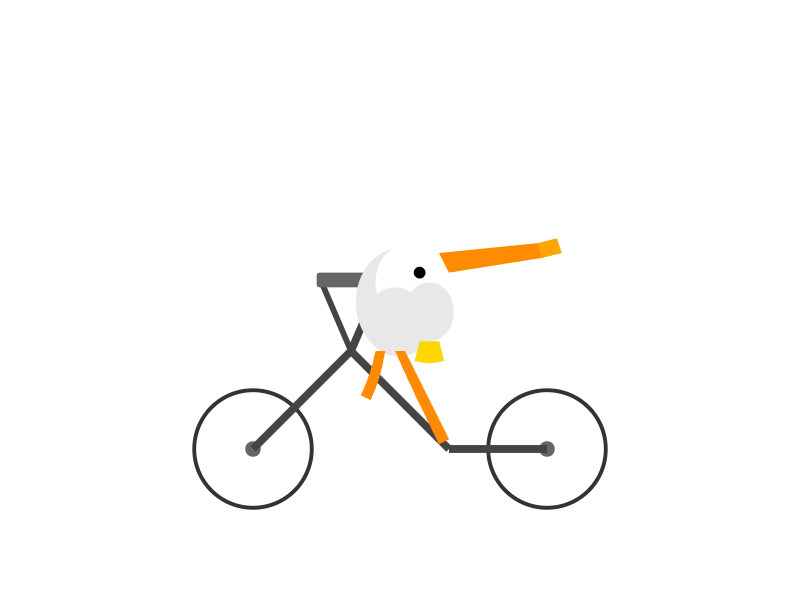
See for yourself: one prompt, one attempt

SVG short test

One SVG task with the same fixed settings for every model, without hidden thinking.

DeepSeek-V4.1-Flash

DeepSeek-V4.1-Flash: SVG short test

Prompt

Return only one standalone SVG of a pelican riding a bicycle. Use viewBox="0 0 800 600", simple shapes, two clearly visible wheels and a recognizable pelican with a long beak. At most 30 SVG elements and 1800 characters. No Markdown, explanations, comments, scripts, animation, CSS or external resources.

Oct 14, 2026 · $0.0001

Test details
Test run
Oct 14, 2026
Provider
decart/fp4
API model
deepseek/deepseek-v4.1-flash
Output
590 tokens
Reasoning
API reports 0 reasoning tokens
Cost of the attempt
$0.0001
Test round
43b8c5c46830
Earlier tests

The response reached the token limit. No complete recording is available.

Pelican on a bicycle

Prompt

Generate an SVG of a pelican riding a bicycle

Oct 5, 2026 · 26 s · $0.0049

Not yet visually reviewed. A successful recording does not confirm correct physics or full compliance with the prompt.

Test details
Run date
Oct 5, 2026
API provider
openrouter
Requested API model
deepseek/deepseek-v4.1-flash
Reasoning setting
high
Token limit including reasoning
8,192 tokens
Output tokens
8,191 tokens
Cost of the attempt
$0.0049
Response time
25.8 s
API model reported in response
deepseek/deepseek-v4.1-flash
Pinned endpoint
DeepSeek | deepseek/deepseek-v4.1-flash-20260910
Temperature
Provider default
Test protocol
community-visual-tests-v1
Technical checks
Failed

Earlier attempts (2)

  • Oct 2, 2026API request failedReasoning setting: high
  • Oct 1, 2026API request failedReasoning setting: high
Task origin: Simon Willison

Same prompt, four models

From the SVG short test: a pelican riding a bicycle, the same fixed settings without reasoning for every model, one attempt per model. An impression, not a score.

Popularity compared

How often the model is searched for, used and mentioned, compared with every model of its category.

Popularity index

The 100 most popular models of this category, 0 to 100, higher is more popular

20 of 101 models

As of November 2026 · Source: gradually.ai popularity index

Over time

Weekly values from October 18, 2026 to November 5, 2026

DeepSeek-V4.1-FlashGemini 3.6 FlashGemini 3.5 FlashGPT-5.4Mistral Medium 3.5

DeepSeek-V4.1-Flash compared

Compare with another model

The most popular comparisons

  1. 1Claude Opus 5.5 vs. DeepSeek-V4.1-Flash
  2. 2Gemini 3.8 Flash vs. DeepSeek-V4.1-Flash
  3. 3GPT-6 Luna vs. DeepSeek-V4.1-Flash
  4. 4Muse Spark 1.3 vs. DeepSeek-V4.1-Flash
  5. 5Claude Haiku 5.5 vs. DeepSeek-V4.1-Flash
  6. 6Claude Sonnet 5.5 vs. DeepSeek-V4.1-Flash
  7. 7GPT-6 Sol vs. DeepSeek-V4.1-Flash
  8. 8GPT-6 Astra vs. DeepSeek-V4.1-Flash
  9. 9Claude Sonnet 5 vs. DeepSeek-V4.1-Flash
Show all 55 comparisons
  1. 10Grok 4.7 vs. DeepSeek-V4.1-Flash
  2. 11Claude Opus 5 vs. DeepSeek-V4.1-Flash
  3. 12GPT-5.6 Terra vs. DeepSeek-V4.1-Flash
  4. 13DeepSeek-V4.1-Flash vs. GLM-5.3-Flash
  5. 14Claude Opus 4.6 vs. DeepSeek-V4.1-Flash
  6. 15Claude Sonnet 4.6 vs. DeepSeek-V4.1-Flash
  7. 16DeepSeek-V4.1-Flash vs. Qwen 3.8 Max 0902
  8. 17GPT-6.1 Sol vs. DeepSeek-V4.1-Flash
  9. 18DeepSeek-V4-Pro vs. DeepSeek-V4.1-Flash
  10. 19DeepSeek-V4.1-Flash vs. Mistral Large 4
  11. 20DeepSeek-V4.1-Flash vs. MiMo-V2.5-Pro
  12. 21Gemini 3.5 Flash-Lite vs. DeepSeek-V4.1-Flash
  13. 22Claude Haiku 4.5 vs. DeepSeek-V4.1-Flash
  14. 23Gemini 3.1 Pro Preview vs. DeepSeek-V4.1-Flash
  15. 24DeepSeek-V4.1-Flash vs. GLM-5.2
  16. 25Gemini 3.6 Flash vs. DeepSeek-V4.1-Flash
  17. 26DeepSeek-V4.1-Flash vs. GLM-5.3
  18. 27GPT-5.6 Sol vs. DeepSeek-V4.1-Flash
  19. 28Claude Opus 4.8 vs. DeepSeek-V4.1-Flash
  20. 29DeepSeek-V4.1-Flash vs. Kimi K3
  21. 30Grok 4.6 vs. DeepSeek-V4.1-Flash
  22. 31Claude Fable 5 vs. DeepSeek-V4.1-Flash
  23. 32GPT-5.6 Luna vs. DeepSeek-V4.1-Flash
  24. 33Claude Opus 4.7 vs. DeepSeek-V4.1-Flash
  25. 34Claude Sonnet 4.5 vs. DeepSeek-V4.1-Flash
  26. 35Claude Opus 4.5 vs. DeepSeek-V4.1-Flash
  27. 36Claude Fable 5.1 vs. DeepSeek-V4.1-Flash
  28. 37DeepSeek-V4.1-Flash vs. Mistral Medium 3.5
  29. 38DeepSeek-V4.1-Flash vs. MiMo-V2.5
  30. 39DeepSeek-V4.1-Flash vs. GLM-5.1
  31. 40DeepSeek-V4.1-Flash vs. Mistral Large 3
  32. 41GPT-5.5 vs. DeepSeek-V4.1-Flash
  33. 42Muse Wonder Full vs. DeepSeek-V4.1-Flash
  34. 43GPT-6.1 Terra vs. DeepSeek-V4.1-Flash
  35. 44GPT-5.4 vs. DeepSeek-V4.1-Flash
  36. 45GPT-5.4 mini vs. DeepSeek-V4.1-Flash
  37. 46Gemini 4 Carbon vs. DeepSeek-V4.1-Flash
  38. 47Gemini 4 Argon vs. DeepSeek-V4.1-Flash
  39. 48Gemini 3.7 Flash vs. DeepSeek-V4.1-Flash
  40. 49Gemini 3.5 Flash vs. DeepSeek-V4.1-Flash
  41. 50Muse Wonder vs. DeepSeek-V4.1-Flash
  42. 51Grok 4.5 vs. DeepSeek-V4.1-Flash
  43. 52Grok 4.3 vs. DeepSeek-V4.1-Flash
  44. 53DeepSeek-V4.1-Flash vs. Kimi K3.1 Pro
  45. 54DeepSeek-V4.1-Flash vs. Kimi K2.6
  46. 55DeepSeek-V4.1-Flash vs. Qwen 3.8 27B

All specifications

Architecture

Parameters
552B
Source: Parameters
Architecture
Causal Encoder-Decoder MoE (20-layer encoder, 20-layer decoder); 8B active parameters per token on prefill, 16B on decode
Source: Architecture
Training tokens
45T
Source: Training tokens

Input and output

Context window
1,000,000 tokens
Source: Context window
Input
Text, Image
Source: Input
Output
Text
Source: Output
Reasoning effort
1-100
Source: Reasoning effort
Tool calling
Yes
Source: Tool calling

Watermarking and provenance

AI watermarking refers to invisible signals embedded in the output. Visible marks and provenance metadata are listed separately. Unknown means there is insufficient evidence for that particular field.

AI watermarking
Unknown
no source
Watermarking technique
Not known
no source

Licence and access

Weights
Open weights
Source: Weights
Access
API, Local
Source: Access
License
MIT
Source: License
Release
Sep 10, 2026
Source: Release

API

API model ID
deepseek-flash (legacy names deepseek-v4-flash and deepseek-v4-flash-vision-exp are routed to this model)
Source: API model ID

Further details

Notes
552B total, 8B active during input prefill and 16B during output decoding, 1M context, multimodal and MIT-licensed
Source: Notes
Active input parameters
8 B
Source: Active input parameters
Active output parameters
16 B
Source: Active output parameters

Prices

Choose a price view

39 offers, prices in US dollars per 1M tokens, blended from 3 parts input and 1 part output.

Filter offers
ProviderInputOutputCache readBlended
DeepSeekOff-Peakdirect$0.15$0.60$0.003$0.26
OpenInferenceFP4$0.0175$0.40n/a$0.11
MorphFP8$0.022$0.40n/a$0.12
RelaceFP4$0.006$0.50n/a$0.13
DeepInfraFP8, Flex$0.112$0.336n/a$0.17
WaferUS$0.051$0.567n/a$0.18
DeepInfraFP8$0.14$0.42n/a$0.21
InferenceNetFP8$0.103$0.60n/a$0.23
InferenceNetUS$0.103$0.60n/a$0.23
AtlasCloudFP8$0.135$0.54n/a$0.24
StreamLakeFP8$0.147$0.588n/a$0.26
CoreWeaveFP8$0.13$0.65n/a$0.26
Alibaba$0.15$0.60n/a$0.26
Mancer 2FP8$0.15$0.75n/a$0.30
WaferMXFP4$0.19$0.65n/a$0.31
DeepInfraFP8, Priority$0.21$0.63n/a$0.32
GMICloudFP8$0.18$0.72n/a$0.32
Reka$0.12$0.96n/a$0.33
NovitaFP8$0.195$0.78n/a$0.34
FireworksSpot$0.21$0.84n/a$0.37
Phala$0.21$0.84n/a$0.37
DigitalOcean$0.225$0.90n/a$0.39
PrimeIntellect$0.156$1.20n/a$0.42
MakoraFP8$0.26$1.17n/a$0.49
CrusoeFP8$0.29$1.20n/a$0.52
BaiduFP8$0.30$1.20n/a$0.52
BaseTen$0.30$1.20n/a$0.52
BaseTenUS$0.30$1.20n/a$0.52
Cohere$0.30$1.20n/a$0.52
Fireworks$0.30$1.20n/a$0.52
GoogleGlobal$0.30$1.20n/a$0.52
Modal$0.30$1.20n/a$0.52
NebiusFP8$0.30$1.20n/a$0.52
ParasailFP8$0.30$1.20n/a$0.52
SiliconFlowFP8$0.30$1.20n/a$0.52
Together$0.30$1.20n/a$0.52
VeniceFP8$0.30$1.20n/a$0.52
FireworksUS$0.45$1.80n/a$0.79
ParasailFast$0.45$1.80n/a$0.79

Cache prices come from the direct tariff; OpenRouter does not report them for the other providers. Direct price according to the developer, checked Oct 26, 2026. Provider prices via OpenRouter, as of Nov 6, 2026. Open the LLM price index

More price tiers and rules
API input (Off-Peak)
$0.15 per 1M tokensSource
API output (Off-Peak)
$0.6 per 1M tokensSource
Cache read (Off-Peak)
$0.003 per 1M tokensSource
Peak hours (UTC)
Mon, Tue, Wed, Thu, Fri, 01:00-04:00 UTC; Mon, Tue, Wed, Thu, Fri, 06:00-10:00 UTC. Off-peak rates apply at all other times.Source
API input (Peak)
$0.3 per 1M tokensSource
API output (Peak)
$1.2 per 1M tokensSource
Cache read (Peak)
$0.006 per 1M tokensSource

7 price changes since tracking began.

InputOutput

$0$0.50$1$1.50Sep 23, 2026Nov 6, 2026
Daily observed price in the LLM price index in US dollars per 1M tokens. The index uses a market price from several sources, which can differ from the developer's direct price.

No DeepSeek subscription includes this model. Through other providers from ≈ €1.06 a month (Command Code Go, with limited credits). 28 plans in Germany.

Filter plans
PlanMonthly priceNote
Genspark Freefreewith limited credit
Command Code Go≈ €1.06with limited credit
Token Plan Individual LiteAlibaba Cloud (Qwen)≈ €6.36with limited credit
Poe Basic€6.83with limited credit
Command Code GOAT≈ €10.60with limited credit
Token Plan Individual EssentialAlibaba Cloud (Qwen)≈ €10.60with limited credit
Token Plan Individual StandardAlibaba Cloud (Qwen)≈ €19.08with limited credit
Command Code Pro≈ €21.20with limited credit
Token Plan Team Team Standard SeatAlibaba Cloud (Qwen)≈ €21.20with limited credit, for teams, per seat
Warp Build≈ €21.20with limited credit
Genspark Plus≈ €26.50with limited credit
Poe Plus€27.36with limited credit
Genspark for Business Team≈ €42.41with limited credit, for teams, per seat
Warp Business≈ €53.01with limited credit, for teams, per seat
Mindverse Studio Team€58.31for teams, per seat
Poe Pro€68.41with limited credit
Mindverse Studio Pro€70.21per seat
Token Plan Individual ProAlibaba Cloud (Qwen)≈ €72.10with limited credit
Token Plan Team Team Pro SeatAlibaba Cloud (Qwen)≈ €79.52with limited credit, for teams, per seat
Command Code Max 10×≈ €106.02with limited credit
Poe Advanced€136.84with limited credit
Command Code Max 20×≈ €212.05with limited credit
Token Plan Team Team Max SeatAlibaba Cloud (Qwen)≈ €212.05with limited credit, for teams, per seat
Warp Max≈ €212.05
Genspark Pro≈ €265.05with limited credit
Poe Max€342.11with limited credit
Genspark for Business Enterprisen/awith limited credit, for enterprises, per seat
Warp Enterprisen/afor enterprises

All plans in the AI subscription comparison

Frequently asked questions about DeepSeek-V4.1-Flash

How good is DeepSeek-V4.1-Flash in benchmarks?

Decent: Rank 29 of 91 in the overall index.

Overall index (Gradually Meta-Score v4) from 35 benchmark results · data through Nov 6, 2026

IntelligenceOverall index in points, 100 = reference group average · higher is better
GPT-5.6 Terra100.7
GLM-5.3100.7
Qwen 3.8 Max 0902100.3
DeepSeek-V4.1-FlashRank 2999.7
Claude Opus 4.899.0
MiMo V2.6 Flash98.3
Step 5 Preview97.3

What is the Overall index (Gradually Meta-Score v4)?

A point value that combines many independent benchmarks into one number. 100 points is the average of a fixed reference group, higher is better. DeepSeek-V4.1-Flash scores 99.7 points, which is rank 29 of 91.

Own analysis by gradually.ai, method benchmark-meta-score-v4 · for DeepSeek-V4.1-Flash from 35 test series

Which data
Only current, reviewed results from independent evaluators such as Artificial Analysis, Vals AI, LMArena, LiveBench and Epoch AI. Vendor claims and historical or disputed values do not count.
One value per test
For each source and test series the latest retrieval with one fixed setup counts. When a source tests several reasoning levels, the highest documented one applies. A series needs at least 5 models.
Making tests comparable
Percentages are converted so that gaps near 0 and near 100 % count fairly, then every series is put on the same scale. A hard test therefore does not weigh more than an easy one.
Shared strength
A statistical model estimates, from all series at once, one shared capability per model and, per area, how far a model deviates from it. Missing tests are never counted as zero.
Weighting
Core areas (Coding, Reasoning, Mathematics, Knowledge, Agents, General and Multimodal) count 75 % together, the domain areas Finance, Legal and Health 25 %.
The point scale
The value is measured against a fixed reference group of 29 models, much like an IQ score: 100 points is its average and 15 points one standard deviation of the group. The scale is open at both ends and is not a percentage. A model 15 points ahead does better in roughly three of four benchmark comparisons. New models do not shift older values.
Place by score
The place follows the order of the scores among all models with a place, such as "rank 14 of 95". A second calculation checks whether a lead is reliable by recomputing the score 200 times with randomly redrawn test families. If a model is not almost always ahead there, the two models count as level.
Minimum evidence
A value needs at least 8 test series from 2 sources and 3 areas, a place only with enough precision. Missing core areas are flagged as "estimated".
What it is not
Not a test run by gradually.ai and no verdict on every single task. For a specific task the area values and the individual benchmarks matter more.

How much does DeepSeek-V4.1-Flash cost?

Through the API $0.15 per 1M input tokens and $0.60 output. That is cheap.

Prices from Nov 6, 2026

Output price since tracking beganDollars per 1M tokens · lower is better

Sep 23, 2026Nov 6, 2026

First price on Sep 23, 2026: $1. Since Oct 12, 2026: $1.

How large is the context window of DeepSeek-V4.1-Flash?

1 M tokens. That is how much text DeepSeek-V4.1-Flash reads at once, about 1,500 A4 pages.

Page count as a rule of thumb from Artificial Analysis

Context windowTokens the model reads at once · higher is better
GPT-5.6 Terra1.05M
GPT-5.51.05M
Gemini 3.5 Flash1.05M
DeepSeek-V4.1-FlashRank 31 of 1011M
Qwen 3.8 Max 09021M
Claude Opus 4.81M
GLM-5.31M

How fast is DeepSeek-V4.1-Flash?

176 tokens per second. That is faster than a typical model at 87.

Measured by Artificial Analysis on Nov 6, 2026. AA 3.0.0, including time to first token, averaged across available workloads and five days.

SpeedTokens per second · higher is better
DeepSeek-V4.1-FlashRank 14 of 100176
Step 5 Preview132
GPT-5.6 Terra100
Claude Opus 4.882
GLM-5.363
Qwen 3.8 Max 090246
MiMo V2.6 Flash35

Can I run DeepSeek-V4.1-Flash locally?

Yes, the weights are open. With 552B parameters it needs a lot of memory, more a server than a laptop.

Stated by DeepSeek

Open weights
yes
License
MIT
Parameters
552B
active per token
n/a

Where can I use DeepSeek-V4.1-Flash?

Not in a DeepSeek subscription. Including other providers that makes 28 plans in Germany, plus the API.

Subscription comparison, prices in Germany incl. VAT

At DeepSeek

No DeepSeek subscription includes this model.

Through other providers

28 plans from 6 providers, from ≈ €1.06 a month (Command Code Go), with limited credits.

Through the API

$0.15 input, $0.60 output per 1M tokens according to the provider; the price index has listed it at $0.30 and $1 since Sep 26, 2026.

Is DeepSeek-V4.1-Flash better than DeepSeek-V4-Flash?

There is too little data for an overall comparison. It leads in Agents.

DeepSeek-V4-Flash as predecessor according to DeepSeek-V4.1-Flash release, checked Sep 23, 2026

IntelligenceOverall index, 100 points = average · higher is better
99.7

DeepSeek-V4.1-Flash

Rank 29

n/a

DeepSeek-V4-Flash

not ranked yet

SpeedTokens per second · higher is better
176

DeepSeek-V4.1-Flash

fast

123

DeepSeek-V4-Flash

fairly fast

PriceDollars per 1M tokens, 3 parts input to 1 part output · lower is better
$0.26

DeepSeek-V4.1-Flash

1.4 times the price

$0.19

DeepSeek-V4-Flash

cheaper

DeepSeek-V4.1-FlashDeepSeek-V4-Flash100 points = average, higher is better
Codingonly DeepSeek-V4.1-Flash has a scoreDeepSeek-V4.1-Flash: 98.8DeepSeek-V4-Flash: not enough data
Mathematicsonly DeepSeek-V4.1-Flash has a scoreDeepSeek-V4.1-Flash: 97.3DeepSeek-V4-Flash: not enough data
AgentsDeepSeek-V4.1-Flash aheadDeepSeek-V4.1-Flash: 106.4DeepSeek-V4-Flash: 83.1
Generalonly DeepSeek-V4.1-Flash has a scoreDeepSeek-V4.1-Flash: 97.1DeepSeek-V4-Flash: not enough data
Financeonly DeepSeek-V4.1-Flash has a scoreDeepSeek-V4.1-Flash: 103.7DeepSeek-V4-Flash: not enough data
Legalonly DeepSeek-V4.1-Flash has a scoreDeepSeek-V4.1-Flash: 100.8DeepSeek-V4-Flash: not enough data
Healthonly DeepSeek-V4.1-Flash has a scoreDeepSeek-V4.1-Flash: 95.5DeepSeek-V4-Flash: not enough data
Multimodalonly DeepSeek-V4.1-Flash has a scoreDeepSeek-V4.1-Flash: 95.7DeepSeek-V4-Flash: not enough data

Sources and data date

Show all 98 sources

Benchmark sources at a glance

Which independent evaluators tested this model. This is coverage, not a quality ranking.

EvaluatorTest seriesComposite indicesRecorded active measurements
Artificial Analysis508
Vals AI283211
LMArena3042
LiveBench0045
ARC Prize0016
Scale AI Evals001

Without vendor claims and historical or disputed results; those stay labelled in the single values. 62 measurements are not yet assigned to a test series.

TypeEvidence and data date
Speed

Median across serving providers, Max effort. AA 3.0.0, including time to first token, averaged across available workloads and five days. Retrieved November 6, 2026.

Price

Off-peak API prices. Higher rates apply during the provider's peak hours. All rates and the UTC schedule are listed under Costs.

Input

Documented modalities. Retrieved September 23, 2026.

Output

Documented modalities. Retrieved September 23, 2026.

Research statusResearch date September 24, 2026. 39 source URLs checked. This documents the inspected sources, not an exhaustive inventory of every publication.
Unresolved

active-parameters-billions

Original wording

The card publishes two values (8B per token on prefill, 16B on decode); no single active-parameter count applies.

Not published

knowledge-cutoff

Original wording

Neither the model card nor the release post states a knowledge cutoff.

Unresolved

NL2Repo-Bench score discrepancy

Note

The existing model-card record reports 64.0, while a separate official release note reports 65.4. The new 65.4 observation is marked disputed; evaluation date, score unit, and setup for that value are not disclosed.

Not published

reasoning effort and pass@k

Note

The cited result does not report reasoning effort or pass@k; exact task date and serving/checkpoint details are recorded in the benchmark configuration.

Not published

DeepSeek V4.1 Flash vendor benchmark run metadata

Note

The model card states reasoning_effort=100, temperature=1.0, and top_p=0.95 for Instruct results, but does not disclose task dates, row-specific units, or all harness/settings.

Additional sourceArtificial Analysis (retrieved October 19, 2026; November 2, 2026; November 6, 2026)1234
Additional sourceArtificial Analysis (retrieved October 19, 2026)12345678910
Additional sourceArtificial Analysis (retrieved October 19, 2026; November 2, 2026)
Additional sourceArtificial Analysis (retrieved October 19, 2026; October 29, 2026; November 2, 2026; November 6, 2026)
Additional sourceLMArena (retrieved October 30, 2026)123
Additional sourceLMArena (retrieved October 28, 2026)12
Additional sourceLMArena (retrieved October 16, 2026)123
Additional sourceVals AI (retrieved November 6, 2026)1234567891011121314151617181920212223242526
Additional sourceVals AI (retrieved October 16, 2026; November 6, 2026)1234
Additional sourceVals AI (retrieved October 16, 2026)12
Additional sourceVals AI (retrieved October 16, 2026; October 31, 2026; November 6, 2026)
Additional sourceVals AI (retrieved October 16, 2026; October 30, 2026; October 31, 2026)
Additional sourceDeepSeek V4.1 Flash model card (retrieved September 24, 2026)
Additional sourceDeepSeek official release notes (retrieved October 15, 2026)
Additional sourceLlamaIndex / Run-Llama ExtractBench (retrieved October 15, 2026)
Additional sourceLiveBench (retrieved October 16, 2026; October 18, 2026) (unavailable on November 2, 2026) https://livebench.ai/table_2026_09_02.csv
Additional sourceLiveBench (retrieved October 16, 2026) (unavailable on November 2, 2026) https://livebench.ai/breakdown_2026_09_02.json
Additional sourceARC Prize Verified results (retrieved October 17, 2026)
Additional sourceBizBench (retrieved October 17, 2026)
Additional sourceAgenticBBO-Bench (retrieved October 17, 2026)
Additional sourceDeepSeek official API changelog, V4.1 Flash-1017 update (retrieved October 18, 2026) · DeepSeek API changelog · Editorial description reviewed October 2, 2026
Additional sourceParallel Search Capability Leaderboard (retrieved October 18, 2026)
Additional sourceLlamaIndex ParseBench, shown in the official DeepSeek Hugging Face model-page Eval Results section (retrieved October 20, 2026)
Additional sourceServeLearnBench paper, arXiv:2610.07792v1 (retrieved October 21, 2026)
Additional sourceCao et al. (Mine Odyssey) (retrieved October 22, 2026)
Additional sourceDeepSeek-AI, DeepSeek-V4.1-Flash model card (retrieved October 22, 2026)
Additional sourceMachine Spirituality (retrieved October 23, 2026)
Additional sourceForcebench (retrieved October 23, 2026)
Additional sourceForcebench (retrieved October 24, 2026)
Additional sourceDuelLab GameBench 2 model results (retrieved October 28, 2026; November 2, 2026; November 5, 2026)
Additional sourceParallel Search Capability Leaderboard (retrieved October 28, 2026; November 5, 2026)
Additional sourceTowards AI ToneBench (retrieved October 28, 2026; October 30, 2026)1234
Additional sourceGoogle DeepMind on Kaggle (retrieved October 28, 2026)
Additional sourceScale AI DistressBench (retrieved October 28, 2026)
Additional sourceParallel Search Capability Leaderboard (retrieved November 5, 2026)
Additional sourceAlman Institut (retrieved November 6, 2026)
Additional sourceModel metadata (retrieved September 24, 2026) · DeepSeek V4.1 lifecycle notice · Editorial description reviewed October 2, 2026
Additional sourceModel metadata (retrieved September 24, 2026)
Additional sourceOpenRouter: Popularity index (derived), CC BY 4.0
Additional sourceVercel AI Gateway: Popularity index (derived), CC BY 4.0
Additional sourceOllama: cumulative downloads for the popularity index
Additional sourceReplicate: cumulative runs for the popularity index
Additional sourceGoogle Trending Now: limited feed selection for Germany and the US
Additional sourceCreative Commons Attribution 4.0
Additional sourceDeepSeek V4.1 Flash 1017 release (2026-10-24)