Compare published benchmark results from matching versions and cohorts, API pricing, and technical specifications. Any documented test setup differences remain visible.
shared result series
155
distinct benchmarks
22
latest retrieval
2026-09-29
Change model selection
Specifications
General specifications
Release date, availability, context window, architecture, and published parameter counts at a glance. Undisclosed details remain marked as unavailable.
Specifications for Claude Fable 5 and DeepSeek-V4-Pro
The table compares official standard API rates per 1M tokens, including published cache pricing. Batch, fast, priority, regional surcharges, tool calls, and cloud platform pricing are excluded.
API pricing for Claude Fable 5 and DeepSeek-V4-Pro
DeepSeek-V4-Pro: peak pricing is $1.32 input / $3.96 output per 1M tokens during Mon, Tue, Wed, Thu, Fri, 01:00-04:00 UTC; Mon, Tue, Wed, Thu, Fri, 06:00-10:00 UTC; off-peak rates apply at all other times.
Claude Fable 5DeepSeek-V4-Pro
API inputUSD per 1M tokens, base tier
Claude Fable 5$10
DeepSeek-V4-ProLower price$0.66
API outputUSD per 1M tokens, base tier
Claude Fable 5$50
DeepSeek-V4-ProLower price$1.98
Cache readUSD per 1M tokens, base tier
Claude Fable 5$1
DeepSeek-V4-ProLower price$0.022
Key to the marks:better valuebetter, but not conclusivetie
Pricing by provider
Direct developer pricing and provider endpoint tariffs routed through OpenRouter are listed separately. Prices are in USD per 1M tokens. Context-dependent direct tiers plus regional, Flex, Priority, and other OpenRouter tariffs remain individually identifiable.
Provider pricing for Claude Fable 5 and DeepSeek-V4-Pro
Only published results with the same benchmark version, task, metric, and comparison cohort are paired. Different reasoning levels, agents, harnesses, or output limits appear directly in the table.
Capability profile from matched benchmarks
Each axis averages directly matched benchmark families. A value of 100 means the stronger value within this pair, not a universal quality score.
Claude Fable 5
DeepSeek-V4-Pro
Coding: 100 / 56.4 (5 benchmark families)
Reasoning: 100 / 95.9 (1 benchmark family)
Mathematics: 100 / 16.8 (1 benchmark family)
Knowledge: 100 / 95.4 (1 benchmark family)
Finance: 100 / 82.3 (5 benchmark families)
Legal: 100 / 56.9 (3 benchmark families)
Agentic tasks: 100 / 62.3 (1 benchmark family)
Productivity: 100 / 89.3 (1 benchmark family)
22 matched rows from 21 benchmark families were considered. The radar shows 8 of 10 comparable categories.
Claude Fable 5DeepSeek-V4-Pro
Code MigrationOverall. Higher is better. No documented setup difference
Claude Fable 5Winner55.065 %
DeepSeek-V4-Pro26.201 %
CorpFin v2Overall. Higher is better. No documented setup difference
Claude Fable 5Winner71.834 %
DeepSeek-V4-Pro61.383 %
EMBOverall. Higher is better. No documented setup difference
Claude Fable 5Winner73.666 %
DeepSeek-V4-Pro51.623 %
Finance Agent (v2)Overall. Higher is better. No documented setup difference
Claude Fable 5Winner56.314 %
DeepSeek-V4-Pro44.083 %
GPQA DiamondOverall. Higher is better. No documented setup difference
Claude Fable 5Winner93.182 %
DeepSeek-V4-Pro89.394 %
Harvey's Legal Agent BenchmarkOverall · Task fully resolved. Higher is better. No documented setup difference
Claude Fable 5Winner11.25 %
DeepSeek-V4-Pro3.75 %
IOIIOI 2024. Higher is better. Test setup not documented as identical
Claude Fable 5Higher measured value100 %
DeepSeek-V4-Pro31.333 %
Legal Research BenchOverall · All-pass. Higher is better. No documented setup difference
Claude Fable 5Winner49.519 %
DeepSeek-V4-Pro23.077 %
LegalBenchOverall. Higher is better. No documented setup difference
Claude Fable 5Winner88.561 %
DeepSeek-V4-Pro80.323 %
LiveCodeBench v6Overall. Higher is better. No documented setup difference
Claude Fable 5Winner89.778 %
DeepSeek-V4-Pro87.484 %
MedCodeOverall. Higher is better. No documented setup difference
Claude Fable 5Winner56.07 %
DeepSeek-V4-Pro40.455 %
MedScribeOverall. Higher is better. No documented setup difference
Claude Fable 5Winner88.522 %
DeepSeek-V4-Pro75.144 %
Key to the marks:better valuebetter, but not conclusivetie
Benchmark scores for Claude Fable 5 and DeepSeek-V4-Pro
Benchmark and task
Claude Fable 5
DeepSeek-V4-Pro
Source
Code MigrationOverallTest details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is better
Test setup not documented as identicalNo direct winnerVersion: 2.1Metric: accuracyScoring: Higher is betterDeepSeek-V4-Pro: Output limit: 128,000 tokens
Test setup not documented as identicalNo direct winnerVersion: 2.1Metric: accuracyScoring: Higher is betterDeepSeek-V4-Pro: Output limit: 128,000 tokens
Key to the marks:better valuebetter, but not conclusivetie
Our model tests
Our tests
Compare how the models respond to the same prompt. Each test shows the first attempt, with no subsequent fixes to the generated code. These results do not contribute to an overall score.
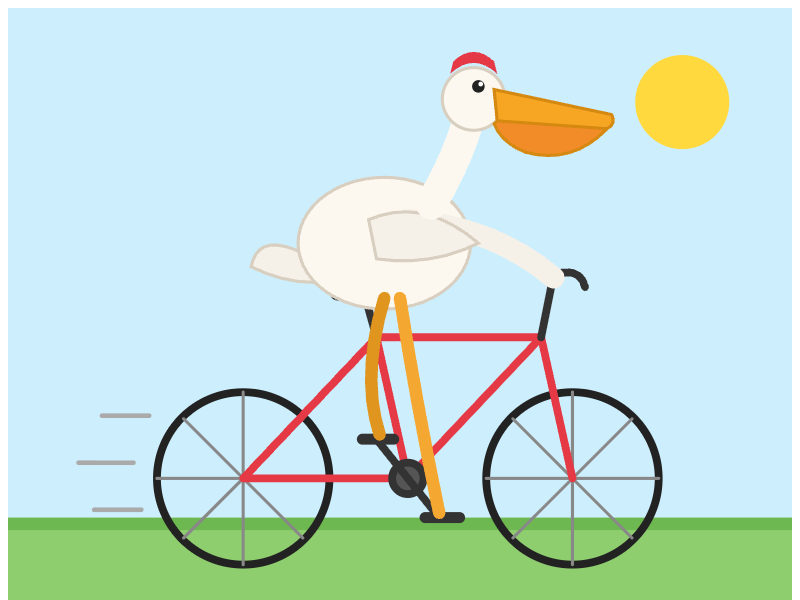
Pelican on a bicycle
A community classic for free-form SVG drawing.
Claude Fable 5
A community classic for free-form SVG drawing.
Reasoning (requested): high
First attempt
Run date
7 Sept 2026
API provider
openrouter
Requested API model
anthropic/claude-fable-5
API model reported in response
anthropic/claude-fable-5
Reasoning setting
high
Pinned endpoint
Anthropic | anthropic/claude-5-fable-20260609
Temperature
Provider default
Token limit including reasoning
8,192 tokens
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating
Response time
53.1 s
Visually reviewed. This individual test does not establish overall model quality.
DeepSeek-V4-Pro
API access was unavailable for this run. The model was not evaluated.
Reasoning (requested): high
First attempt
Run date
7 Sept 2026
API provider
openrouter
Requested API model
deepseek/deepseek-v4-pro-0813
Reasoning setting
high
Pinned endpoint
DeepSeek | deepseek/deepseek-v4-pro-20260813
Temperature
Provider default
Token limit including reasoning
8,192 tokens
Test protocol
community-visual-tests-v1
Technical checks
Not run
Not yet visually reviewed. A successful recording does not confirm correct physics or full compliance with the prompt.
Your workload, budget, and required context length matter most. A coding benchmark says little about visual understanding or agent performance.
The standard price table uses direct developer rates. The provider comparison labels OpenRouter endpoints, regions, and special tariffs separately.
Every result links to its measurement source and retrieval date. Labels distinguish vendor reports, official benchmark leaderboards, and independent evaluations. Disputed or archived results are excluded.
More matchups
Related LLM comparisons
Compare Claude Fable 5 and DeepSeek-V4-Pro with other leading models using the same data and benchmark logic.