AnthropicDeepSeekLLM matchup
Claude Sonnet 5.5vs.DeepSeek-V4-Pro
Which one is better?
Claude Sonnet 5.5 performs better than DeepSeek-V4-Pro, but costs 3 times (input) and 5.1 times (output) as much.
Claude Sonnet 5.5
Rank 5
DeepSeek-V4-Pro
Rank 48
Claude Sonnet 5.5
DeepSeek-V4-Pro
Claude Sonnet 5.5
DeepSeek-V4-Pro
Claude Sonnet 5.5
Rank 21 of 478
DeepSeek-V4-Pro
Rank 25 of 478
Choose Claude Sonnet 5.5 for
No clear advantage for DeepSeek-V4-Pro.
Where is the difference?
Strengths at a glance
Sonnet 5.5DeepSeek-V4-ProMedian of all ranked models
95 % range: Sonnet 5.5 119.5 to 130.9, DeepSeek-V4-Pro 85.5 to 96.6.
The same values and verdicts as the bars below. In the close-up the net starts at 70 points, just below the weaker model's lowest value; the reference group average is 100. Not in the net because a model has no own value there or the data are too thin: Multimodal.
Sonnet 5.5 is ahead in 9 of 10 areas, DeepSeek-V4-Pro in none.
Sonnet 5.5 ahead: 9too little data: 1
Bar length shows the gap in index points (full width 15 points, one standard deviation of the reference group). Solid means clearly ahead, hatched not certain yet, a thin grey bar level.
Show 3 more areas that do not count toward the overall index
Bar length shows the gap in index points (full width 15 points, one standard deviation of the reference group). Solid means clearly ahead, hatched not certain yet, a thin grey bar level.
Claude Sonnet 5.5 vs. DeepSeek-V4-Pro at the same effort
Both models measured at the same reasoning efforts. This shows whether a lead comes from the model or only from more compute.
The gap compares only the Artificial Analysis test series in which both models are measured at that effort. Tied below 3 points, ahead only beyond two standard errors.
Which model for which task?
Everyday tasks, translated from the area values above. Each row names the values it rests on.
Claude Sonnet 5.5 vs. DeepSeek-V4-Pro in our own test
The same prompt for both models. We show the latest attempt without fixes; it does not count toward the overall index.
Claude Sonnet 5.5
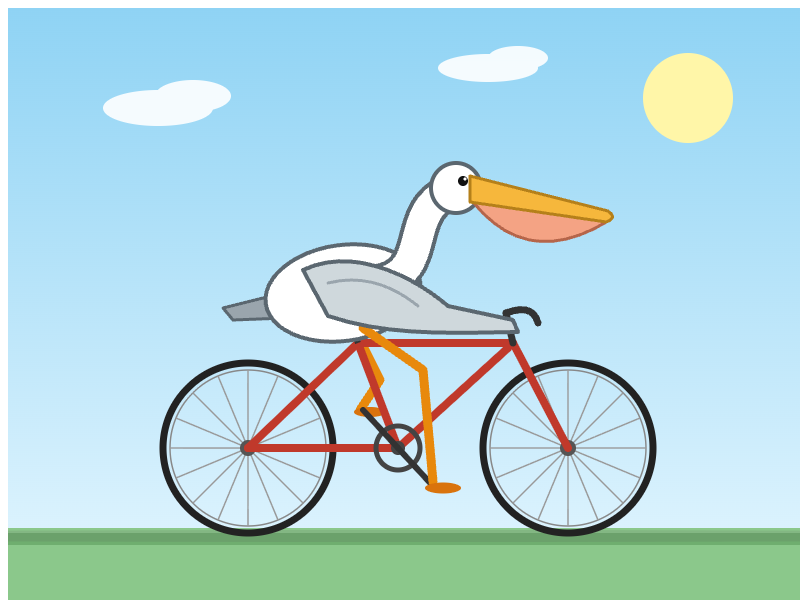
Oct 1, 2026 · 28 s · $0.04
Test details
- Run date
- Oct 1, 2026
- API provider
- openrouter
- Requested API model
- anthropic/claude-sonnet-5.5
- Reasoning setting
- high
- Token limit including reasoning
- 8,192 tokens
- Output tokens
- 3,886 tokens
- Cost of the attempt
- $0.0389
- Response time
- 28.2 s
- API model reported in response
- anthropic/claude-sonnet-5.5
- Pinned endpoint
- Anthropic | anthropic/claude-sonnet-5.5-20260928
- Temperature
- Provider default
- Test protocol
- community-visual-tests-v1
- Technical checks
- Passed, not a quality rating
Visually reviewed. This individual test does not establish overall model quality.
DeepSeek-V4-Pro
The response reached the token limit. No complete recording is available.
Oct 5, 2026 · 68 s · $0.02
Not yet visually reviewed. A successful recording does not confirm correct physics or full compliance with the prompt.
Test details
- Run date
- Oct 5, 2026
- API provider
- openrouter
- Requested API model
- deepseek/deepseek-v4-pro-0813
- Reasoning setting
- high
- Token limit including reasoning
- 8,192 tokens
- Output tokens
- 8,192 tokens
- Cost of the attempt
- $0.0163
- Response time
- 67.6 s
- API model reported in response
- deepseek/deepseek-v4-pro-0813
- Pinned endpoint
- DeepSeek | deepseek/deepseek-v4-pro-20260813
- Temperature
- Provider default
- Test protocol
- community-visual-tests-v1
- Technical checks
- Failed
Earlier attempts (3)
- Oct 2, 2026API request failedReasoning setting: high
- Oct 1, 2026API request failedReasoning setting: high
- Sep 7, 2026API request failedReasoning setting: high
SVG short test
SVG short test
One SVG task with the same fixed settings for every model, without hidden thinking.
Prompt
Return only one standalone SVG of a pelican riding a bicycle. Use viewBox="0 0 800 600", simple shapes, two clearly visible wheels and a recognizable pelican with a long beak. At most 30 SVG elements and 1800 characters. No Markdown, explanations, comments, scripts, animation, CSS or external resources.
Claude Sonnet 5.5
Unavailable in this round
DeepSeek-V4-Pro
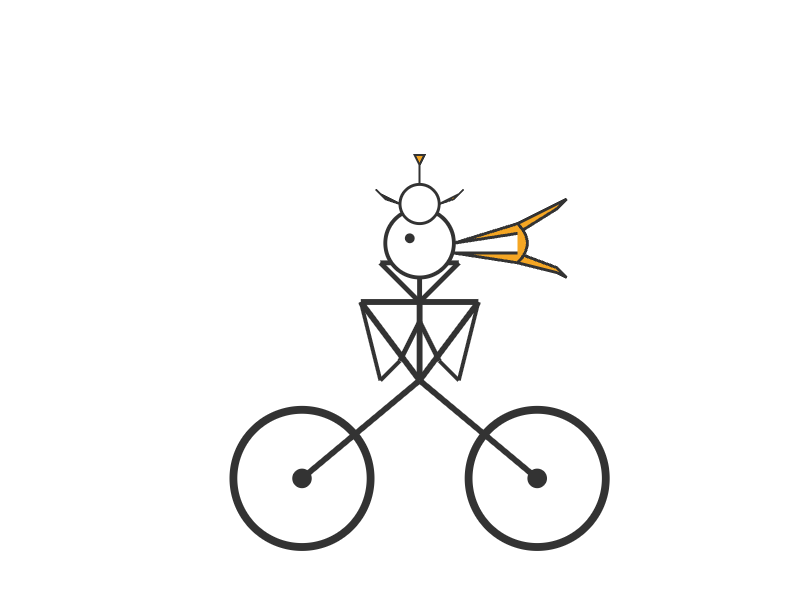
Oct 14, 2026 · $0.0020
Test details
- Test run
- Oct 14, 2026
- Provider
- streamlake
- API model
- deepseek/deepseek-v4-pro-0813
- Output
- 963 tokens
- Reasoning
- API reports 0 reasoning tokens
- Cost of the attempt
- $0.0020
- Test round
- 43b8c5c46830
Claude Sonnet 5.5 and DeepSeek-V4-Pro in the overall index
Every model with a place in the overall index, both models of this matchup highlighted. You can add or hide other models.
Overall index (Gradually Meta-Score v5)
20 of 95 models
Popularity compared
How often the models are searched for, used and mentioned, on a scale from 0 to 100.
Both are about as popular: Claude Sonnet 5.5 79, DeepSeek-V4-Pro 76 out of 100.
Over time
Weekly values from October 18, 2026 to November 13, 2026
Claude Sonnet 5.5DeepSeek-V4-Pro
All data side by side
The better value is bold. For the overall index only when the gap is clear.
| Metric | Claude Sonnet 5.5 | DeepSeek-V4-Pro |
|---|---|---|
| Intelligence | ||
| Overall indexpoints, 100 = reference group average, higher is better | 121.9 | 87.1 |
| Rank | Rank 5 of 95 | Rank 48 of 95 |
| Price per 1M tokens | ||
| Inputwhat you send | $2 | $0.66 |
| Outputwhat the model writes | $10 | $1.98 |
| Cost per task (own tests)average of 1 original-protocol task both models passed (SVG short test not included) | $0.042 | $0.021 |
| Speed | ||
| Tokens per second | 103 | 44 |
| Popularity | ||
| Popularitysearch, usage and mentions, 0 to 100 | 79Rank 21 of 478 | 76Rank 25 of 478 |
| Technical | ||
| Context windowhow much text the model reads at once | 1 M tokens≈ 1,500 A4 pages | 1 M tokens≈ 1,500 A4 pages |
| Knowledge cutoff | June 2026 | n/a |
| Released | Sep 28, 2026 | Apr 24, 2026 |
| Availability | Active | Active |
| Open weights | no | yes |
- DeepSeek-V4-Pro: At peak times (Mon, Tue, Wed, Thu, Fri, 01:00-04:00 UTC; Mon, Tue, Wed, Thu, Fri, 06:00-10:00 UTC) the price is $1.32 input and $3.96 output per 1M tokens. The table shows the off-peak price.
Prices without caching or batch discounts · Page count as a rule of thumb from Artificial Analysis
Is there a better choice?
Overall index 110.5, rank 14$0.10 input and $0.50 output per 1M tokens
View profileOverall index 130.9, rank 1$8 input and $40 output per 1M tokens
Sonnet 5.5 vs. Claude Fable 5.2Shared benchmarks
Single results from the same benchmark version, task and metric. A value is bold only with the same test setup and a clear gap.
A: Claude Sonnet 5.5B: DeepSeek-V4-Pro
Show 54 more benchmarks
More comparisons
Compare Claude Sonnet 5.5 and DeepSeek-V4-Pro with the models people compare them with most often.
Compare another matchup
Predecessor and successor
The most popular comparisons
- 1Claude Sonnet 5.5 vs. Gemini 3.8 Flash
- 2Claude Opus 5.5 vs. DeepSeek-V4-Pro
- 3Claude Sonnet 5.5 vs. DeepSeek-V4.1-Flash
- 4Claude Opus 5.5 vs. Claude Sonnet 5.5
- 5Claude Sonnet 5.5 vs. GLM-5.3
- 6Claude Sonnet 5.5 vs. Claude Haiku 5.5
- 7Claude Sonnet 5.5 vs. Claude Opus 5
- 8Claude Sonnet 5.5 vs. Grok 4.7
- 9Claude Sonnet 5.5 vs. GPT-5.6 Terra
Show all 70 comparisons
- 10GPT-6 Luna vs. DeepSeek-V4-Pro
- 11Claude Sonnet 5.5 vs. Claude Fable 5.1
- 12Claude Sonnet 5.5 vs. Gemini 3.1 Pro Preview
- 13Claude Sonnet 5.5 vs. DeepSeek V4.1 Flash 1017
- 14Claude Sonnet 5.5 vs. GPT-6 Luna
- 15Claude Sonnet 5.5 vs. Kimi K3
- 16Gemini 3.8 Flash vs. DeepSeek-V4-Pro
- 17Claude Sonnet 5.5 vs. Qwen 3.8 27B
- 18Claude Sonnet 5.5 vs. Claude Opus 4.6
- 19DeepSeek-V4-Pro vs. DeepSeek-V4.1-Flash
- 20Claude Sonnet 5.5 vs. GPT-5.6 Luna
- 21Claude Opus 5 vs. DeepSeek-V4-Pro
- 22Claude Sonnet 5.5 vs. GLM-5.2
- 23Claude Sonnet 5.5 vs. DeepSeek-V4-Flash
- 24DeepSeek-V4-Pro vs. DeepSeek V4.1 Flash 1017
- 25Claude Sonnet 5.5 vs. GPT-6 Sol
- 26Claude Sonnet 5.5 vs. Gemini 3.5 Flash-Lite
- 27DeepSeek-V4-Pro vs. Qwen 3.8 27B
- 28Claude Haiku 5.5 vs. DeepSeek-V4-Pro
- 29Claude Sonnet 5.5 vs. Claude Fable 5
- 30Claude Sonnet 5.5 vs. Qwen 3.8 Max 0902
- 31Claude Sonnet 5.5 vs. Gemini 3.6 Flash
- 32Claude Sonnet 5.5 vs. Claude Sonnet 4.6
- 33Claude Sonnet 5.5 vs. GPT-5.6 Sol
- 34DeepSeek-V4-Pro vs. GLM-5.3
- 35DeepSeek-V4-Pro vs. Kimi K3
- 36Grok 4.7 vs. DeepSeek-V4-Pro
- 37Claude Sonnet 5.5 vs. GLM-5.3-Flash
- 38GPT-5.6 Sol vs. DeepSeek-V4-Pro
- 39DeepSeek-V4-Pro vs. Qwen 3.8 Max 0902
- 40Claude Sonnet 5.5 vs. Muse Spark 1.3
- 41Claude Sonnet 5.5 vs. Claude Opus 4.7
- 42DeepSeek-V4-Pro vs. GLM-5.3-Flash
- 43Claude Sonnet 5.5 vs. GPT-6 Astra
- 44Claude Sonnet 5.5 vs. Claude Opus 4.8
- 45DeepSeek-V4-Pro vs. Mistral Large 4
- 46DeepSeek-V4-Pro vs. MiMo-V2.5-Pro
- 47GPT-6 Sol vs. DeepSeek-V4-Pro
- 48Claude Sonnet 5.5 vs. Kimi K2.6
- 49Claude Sonnet 5.5 vs. Grok 4.6
- 50DeepSeek-V4-Pro vs. MiMo-V2.5
- 51Claude Sonnet 5.5 vs. GPT-6.1 Sol
- 52Claude Sonnet 5.5 vs. Claude Sonnet 4.5
- 53Claude Sonnet 5.5 vs. Gemini 3.7 Flash
- 54Claude Sonnet 5.5 vs. Claude Haiku 4.5
- 55Claude Sonnet 5.5 vs. Mistral Large 4
- 56Claude Sonnet 5.5 vs. Mistral Medium 3.5
- 57Claude Sonnet 5.5 vs. GPT-5.4
- 58Claude Sonnet 5.5 vs. Gemini 3.5 Flash
- 59Claude Sonnet 5.5 vs. GPT-5.5
- 60Claude Opus 4.5 vs. DeepSeek-V4-Pro
- 61Claude Sonnet 5.5 vs. Claude Opus 4.5
- 62Claude Sonnet 5.5 vs. Kimi K3.1 Pro
- 63Claude Sonnet 5.5 vs. GPT-6.1 Terra
- 64Gemini 4 Argon vs. DeepSeek-V4-Pro
- 65Claude Sonnet 5.5 vs. Muse Wonder Full
- 66DeepSeek-V4-Pro vs. Kimi K3.1 Pro
- 67Claude Sonnet 5.5 vs. Gemini 4 Argon
- 68GPT-6.1 Sol vs. DeepSeek-V4-Pro
- 69Claude Sonnet 5.5 vs. Gemini 4 Carbon
- 70GPT-6.1 Terra vs. DeepSeek-V4-Pro