OpenAIDeepSeekLLM matchup

GPT-5.6 Solvs.DeepSeek-V4-Pro

Which one is better?

GPT-5.6 Sol performs better than DeepSeek-V4-Pro, but costs 6.1 times (input) and 10.1 times (output) as much.

GPT-5.6 Sol ahead
IntelligenceOverall index, 100 points = average
109.3

GPT-5.6 Sol

Rank 15

87.1

DeepSeek-V4-Pro

Rank 48

GPT-5.6 Sol faster
SpeedTokens per second
71

GPT-5.6 Sol

41

DeepSeek-V4-Pro

DeepSeek-V4-Pro cheaper
Price$ per 1M tokens
$8

GPT-5.6 Sol

$0.99

DeepSeek-V4-Pro

about as popular
Popularity0 to 100
78

GPT-5.6 Sol

Rank 22 of 504

75

DeepSeek-V4-Pro

Rank 26 of 504

Above 272,000 tokens of context, GPT-5.6 Sol costs more: $8 input and $30 output per 1M tokens.

Choose GPT-5.6 Sol for

ReasoningLegalHealthCodingFinanceAgents

No clear advantage for DeepSeek-V4-Pro.

Where is the difference?

Strengths at a glance

GPT-5.6 SolDeepSeek-V4-ProMedian of all ranked models

9011013070CodingGPT-5.6 SolReasoningGPT-5.6 SolAgentsGPT-5.6 SolFinanceGPT-5.6 SolLegalGPT-5.6 SolHealthGPT-5.6 Sol
CodingGPT-5.6 Sol ahead
GPT-5.6 Sol111.9Rank 16
DeepSeek-V4-Pro91.1Rank 53
Median of ranked models87.5

95 % range: GPT-5.6 Sol 107.2 to 116.7, DeepSeek-V4-Pro 85.2 to 96.9.

AreaGPT-5.6 SolDeepSeek-V4-Pro

The same values and verdicts as the bars below. In the close-up the net starts at 70 points, just below the weaker model's lowest value; the reference group average is 100. Not in the net because a model has no own value there or the data are too thin: Mathematics, Knowledge, General, Multimodal.

GPT-5.6 Sol is ahead in 6 of 10 areas, DeepSeek-V4-Pro in none.

GPT-5.6 Sol ahead: 6too little data: 4

Areas in the overall index
ReasoningGPT-5.6 Sol +33116.7 to 84.1
CodingGPT-5.6 Sol +21111.9 to 91.1
AgentsGPT-5.6 Sol +12105.9 to 93.9
Generaltoo little data112.8 to 87.6
Mathematicstoo little data108.1 to 85.3
Knowledgetoo little data106.6 to 89.1
Multimodalonly GPT-5.6 Sol has a score
Specialist fields
LegalGPT-5.6 Sol +24107.1 to 83.1
HealthGPT-5.6 Sol +22101.1 to 79.4
FinanceGPT-5.6 Sol +16103.6 to 87.4

Bar length shows the gap in index points (full width 15 points, one standard deviation of the reference group). Solid means clearly ahead, hatched not certain yet, a thin grey bar level.

Show 3 more areas that do not count toward the overall index
Productivitytoo little data109.2 to 90.9
Cybersecurityonly GPT-5.6 Sol has a score
Searchonly GPT-5.6 Sol has a score

Bar length shows the gap in index points (full width 15 points, one standard deviation of the reference group). Solid means clearly ahead, hatched not certain yet, a thin grey bar level.

Which model for which task?

Everyday tasks, translated from the area values above. Each row names the values it rests on.

Writing and debugging codeGPT-5.6 SolCoding 111.9 to 91.1
Maths and data analysisGPT-5.6 SolMathematics 108.1 to 85.3 (too little data), Reasoning 116.7 to 84.1
Facts and researchopenKnowledge 106.6 to 89.1 (too little data), Search without a score for DeepSeek-V4-Pro
Agents and workflowsGPT-5.6 SolAgents 105.9 to 93.9
Fast chat repliesGPT-5.6 Sol71 to 41 tokens per second
Security analysisopenCybersecurity without a score for DeepSeek-V4-Pro
Many requests on a small budgetDeepSeek-V4-Pro$8 to $0.99 per 1M tokens
Finance, legal and medical textsGPT-5.6 SolFinance 103.6 to 87.4, Legal 107.1 to 83.1, Health 101.1 to 79.4
Images, screenshots and PDFsopenMultimodal without a score for DeepSeek-V4-Pro

GPT-5.6 Sol vs. DeepSeek-V4-Pro in our own test

The same prompt for both models. We show the latest attempt without fixes; it does not count toward the overall index.

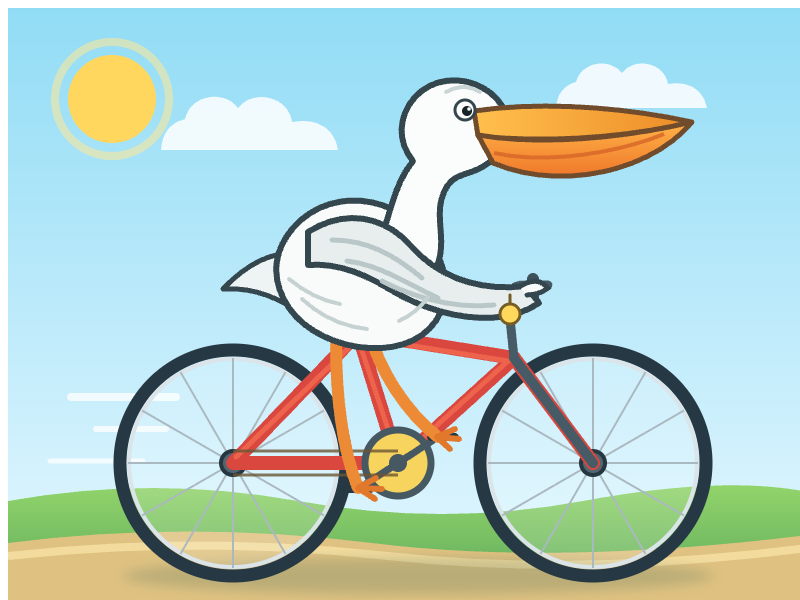
Pelican on a bicycle

Prompt

Generate an SVG of a pelican riding a bicycle

Task origin: Simon Willison

GPT-5.6 Sol

GPT-5.6 Sol: Pelican on a bicycle
A community classic for free-form SVG drawing.

Oct 1, 2026 · 59 s · $0.05

Test details
Run date
Oct 1, 2026
API provider
openrouter
Requested API model
openai/gpt-5.6-sol
Reasoning setting
high
Token limit including reasoning
8,192 tokens
Output tokens
4,633 tokens
Cost of the attempt
$0.0464
Response time
58.7 s
API model reported in response
openai/gpt-5.6-sol
Pinned endpoint
OpenAI | openai/gpt-5.6-sol-20260709
Temperature
Provider default
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating

Visually reviewed. This individual test does not establish overall model quality.

Earlier attempts (1)

  • Sep 7, 2026API request failedReasoning setting: high

DeepSeek-V4-Pro

The response reached the token limit. No complete recording is available.

Oct 5, 2026 · 68 s · $0.02

Not yet visually reviewed. A successful recording does not confirm correct physics or full compliance with the prompt.

Test details
Run date
Oct 5, 2026
API provider
openrouter
Requested API model
deepseek/deepseek-v4-pro-0813
Reasoning setting
high
Token limit including reasoning
8,192 tokens
Output tokens
8,192 tokens
Cost of the attempt
$0.0163
Response time
67.6 s
API model reported in response
deepseek/deepseek-v4-pro-0813
Pinned endpoint
DeepSeek | deepseek/deepseek-v4-pro-20260813
Temperature
Provider default
Test protocol
community-visual-tests-v1
Technical checks
Failed

Earlier attempts (3)

  • Oct 2, 2026API request failedReasoning setting: high
  • Oct 1, 2026API request failedReasoning setting: high
  • Sep 7, 2026API request failedReasoning setting: high
SVG short test

SVG short test

One SVG task with the same fixed settings for every model, without hidden thinking.

Prompt

Return only one standalone SVG of a pelican riding a bicycle. Use viewBox="0 0 800 600", simple shapes, two clearly visible wheels and a recognizable pelican with a long beak. At most 30 SVG elements and 1800 characters. No Markdown, explanations, comments, scripts, animation, CSS or external resources.

GPT-5.6 Sol

Unavailable in this round

DeepSeek-V4-Pro
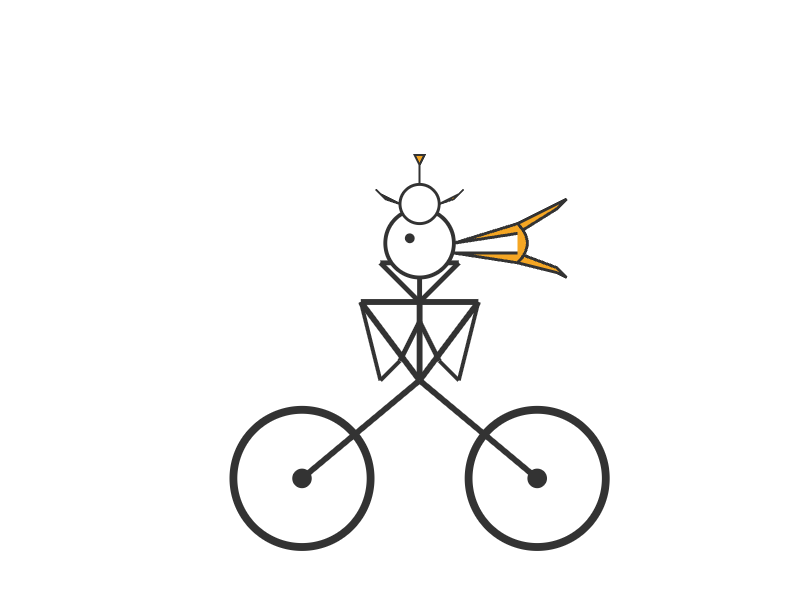
DeepSeek-V4-Pro: SVG short test

Oct 14, 2026 · $0.0020

Test details
Test run
Oct 14, 2026
Provider
streamlake
API model
deepseek/deepseek-v4-pro-0813
Output
963 tokens
Reasoning
API reports 0 reasoning tokens
Cost of the attempt
$0.0020
Test round
43b8c5c46830

GPT-5.6 Sol and DeepSeek-V4-Pro in the overall index

Every model with a place in the overall index, both models of this matchup highlighted. You can add or hide other models.

Overall index (Gradually Meta-Score v6)

20 of 95 models

Claude Fable 5.2max130.9
Gemini 4 Carbonhigh127.0
Claude Opus 5.5max125.7
Claude Fable 5.1max124.1
Claude Sonnet 5.5max121.9
Gemini 4 Argonhigh121.2
GPT-6 Astramax119.6
Muse Wonder Fullmax118.4
GPT-6.1 Solmax117.5
Claude Opus 5max117.3
Muse Wondermax113.7
Claude Fable 5max112.8
Kimi K3.1 Promax112.6
Muse Ember 1.0max110.5
GPT-5.6 Solmax109.3
GPT-6 Solmax108.4
Gemini 3.7 Flashhigh107.7
DeepSeek V4.1 Flash 1017max107.1
GPT-6.1 Terramax106.5
DeepSeek-V4-Promax87.1

Popularity compared

How often the models are searched for, used and mentioned, on a scale from 0 to 100.

Both are about as popular: GPT-5.6 Sol 78, DeepSeek-V4-Pro 75 out of 100.

Over time

Weekly values from October 18, 2026 to November 16, 2026

GPT-5.6 SolDeepSeek-V4-Pro

All data side by side

The better value is bold. For the overall index only when the gap is clear.

MetricGPT-5.6 SolDeepSeek-V4-Pro
Intelligence
Overall indexpoints, 100 = reference group average, higher is better109.387.1
RankRank 15 of 95Rank 48 of 95
Price per 1M tokens
Inputwhat you send$4above 272,000 tokens: $8$0.66
Outputwhat the model writes$20above 272,000 tokens: $30$1.98
Cost per task (own tests)average of 1 original-protocol task both models passed (SVG short test not included)$0.059$0.021
Speed
Tokens per second7141
Popularity
Popularitysearch, usage and mentions, 0 to 10078Rank 22 of 50475Rank 26 of 504
Technical
Context windowhow much text the model reads at once1.05 M tokens≈ 1,580 A4 pages1 M tokens≈ 1,500 A4 pages
Knowledge cutoffFeb 16, 2026n/a
ReleasedJul 9, 2026Apr 24, 2026
AvailabilityActiveActive
Open weightsnoyes
  • DeepSeek-V4-Pro: At peak times (Mon, Tue, Wed, Thu, Fri, 01:00-04:00 UTC; Mon, Tue, Wed, Thu, Fri, 06:00-10:00 UTC) the price is $1.32 input and $3.96 output per 1M tokens. The table shows the off-peak price.

Prices without caching or batch discounts · Page count as a rule of thumb from Artificial Analysis

Is there a better choice?

Successor of GPT-5.6 SolGPT-6 Astra

Overall index 119.6, rank 7$10 input and $50 output per 1M tokens

DeepSeek-V4-Pro vs. GPT-6 Astra
Cheaper than DeepSeek-V4-ProMuse Ember 1.0

Overall index 110.5, rank 14$0.10 input and $0.50 output per 1M tokens

View profile
Best model in the overall indexClaude Fable 5.2

Overall index 130.9, rank 1$8 input and $40 output per 1M tokens

Shared benchmarks

Single results from the same benchmark version, task and metric. A value is bold only with the same test setup and a clear gap.

A: GPT-5.6 SolB: DeepSeek-V4-Pro

Code MigrationOverall · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 52.9%DeepSeek-V4-Pro: 26.2%Vals AIAs of 10/29/2026
CorpFin v2Overall · higher is betterGPT-5.6 Sol: 64.4%DeepSeek-V4-Pro: 61.4%Vals AIAs of 08/12/2026
EMBOverall · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 72.3%DeepSeek-V4-Pro: 51.6%Vals AIAs of 10/20/2026
Finance Agent (v2)Overall · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 53.8%DeepSeek-V4-Pro: 44.1%Vals AIAs of 10/29/2026
GDPval-AAOverall · higher is betterGPT-5.6 Sol: 1,617.8 eloDeepSeek-V4-Pro: 1,457.4 eloArtificial AnalysisAs of 11/07/2026
GPQA DiamondOverall · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 95.2%DeepSeek-V4-Pro: 89.4%Vals AIAs of 09/01/2026
Legal Research BenchOverall · All-pass · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 48.1%DeepSeek-V4-Pro: 23.1%Vals AIAs of 11/05/2026
LegalBenchOverall · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 87.0%DeepSeek-V4-Pro: 80.3%Vals AIAs of 10/13/2026
LiveCodeBenchOverall · higher is betterGPT-5.6 Sol: 82.6%DeepSeek-V4-Pro: 87.5%Vals AIAs of 09/01/2026
LMArena Text, Style ControlOverall · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 1,485DeepSeek-V4-Pro: 1,455LMArenaAs of 11/11/2026
Show 54 more benchmarks
MedCodeOverall · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 44.0%DeepSeek-V4-Pro: 40.5%Vals AIAs of 10/29/2026
MedScribeOverall · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 85.2%DeepSeek-V4-Pro: 75.1%Vals AIAs of 10/29/2026
MMLU ProOverall · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 89.1%DeepSeek-V4-Pro: 87.2%Vals AIAs of 09/01/2026
ProgramBenchOverall · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 1.5%DeepSeek-V4-Pro: 0.0%Vals AIAs of 11/05/2026
ProofBench v1.1Overall · higher is betterGPT-5.6 Sol: 83%DeepSeek-V4-Pro: 16%Vals AIAs of 10/29/2026
Public Benefits Bench v1.1Overall · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 66.5%DeepSeek-V4-Pro: 62.9%Vals AIAs of 10/12/2026
SkillsBenchOverall · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 54.1%DeepSeek-V4-Pro: 51.3%Vals AIAs of 10/29/2026
SWE-bench VerifiedOverall · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 96.2%DeepSeek-V4-Pro: 77.4%Vals AIAs of 09/01/2026
Tax Agent BenchOverall · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 31.1%DeepSeek-V4-Pro: 25.2%Vals AIAs of 11/05/2026
TaxEval v2Overall · higher is betterGPT-5.6 Sol: 74.8%DeepSeek-V4-Pro: 72.1%Vals AIAs of 09/01/2026
Terminal-Bench 4.0Overall · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 37.9%DeepSeek-V4-Pro: 11.1%Vals AIAs of 11/05/2026
Vibe Code Bench v1.1Overall · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 80.5%DeepSeek-V4-Pro: 49.9%Vals AIAs of 11/05/2026
Code MigrationCLI · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 47.2%DeepSeek-V4-Pro: 15.5%Vals AIAs of 10/29/2026
CorpFin v2Exact Pages · higher is betterGPT-5.6 Sol: 61.5%DeepSeek-V4-Pro: 59.2%Vals AIAs of 08/12/2026
EMBComps · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 71.3%DeepSeek-V4-Pro: 57.4%Vals AIAs of 10/20/2026
Finance Agent (v2)Adjustments · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 49.2%DeepSeek-V4-Pro: 41.6%Vals AIAs of 10/29/2026
GPQA DiamondFew-Shot CoT · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 94.9%DeepSeek-V4-Pro: 90.4%Vals AIAs of 09/01/2026
Legal Research BenchAdministrative / Regulatory · All-pass · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 60.6%DeepSeek-V4-Pro: 28.8%Vals AIAs of 11/05/2026
LegalBenchConclusion Tasks · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 90.5%DeepSeek-V4-Pro: 89.1%Vals AIAs of 10/13/2026
LiveCodeBenchEasy · higher is betterGPT-5.6 Sol: 98.1%DeepSeek-V4-Pro: 98.8%Vals AIAs of 09/01/2026
LMArena Text, Style ControlBusiness, management and finance · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 1,488DeepSeek-V4-Pro: 1,448LMArenaAs of 11/11/2026
MMLU ProBiology · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 94.6%DeepSeek-V4-Pro: 92.9%Vals AIAs of 09/01/2026
ProgramBenchAlmost Resolved · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 23%DeepSeek-V4-Pro: 0%Vals AIAs of 11/05/2026
SkillsBenchNo Skills · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 43.3%DeepSeek-V4-Pro: 27.2%Vals AIAs of 10/29/2026
SWE-bench Verified<15 min fix · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 97.4%DeepSeek-V4-Pro: 87.6%Vals AIAs of 09/01/2026
Tax Agent BenchControversy & Precedence Analysis · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 20.0%DeepSeek-V4-Pro: 12.3%Vals AIAs of 11/05/2026
TaxEval v2Correctness · higher is betterGPT-5.6 Sol: 65.0%DeepSeek-V4-Pro: 60.6%Vals AIAs of 09/01/2026
Terminal-Bench 4.0Hardware · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 0%DeepSeek-V4-Pro: 0%Vals AIAs of 11/05/2026
Code MigrationCOBOL · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 70.0%DeepSeek-V4-Pro: 58.4%Vals AIAs of 10/29/2026
CorpFin v2Max Fitting Context · higher is betterGPT-5.6 Sol: 65.2%DeepSeek-V4-Pro: 63.1%Vals AIAs of 08/12/2026
EMBDataroom · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 85.2%DeepSeek-V4-Pro: 62.6%Vals AIAs of 10/20/2026
Finance Agent (v2)All-Pass · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 41.4%DeepSeek-V4-Pro: 31.4%Vals AIAs of 10/29/2026
GPQA DiamondZero-Shot CoT · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 95.5%DeepSeek-V4-Pro: 88.4%Vals AIAs of 09/01/2026
Legal Research BenchAdministrative / Regulatory · Weighted partial credit (weighted pass) · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 90.7%DeepSeek-V4-Pro: 83.4%Vals AIAs of 11/05/2026
LegalBenchInterpretation Tasks · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 84.4%DeepSeek-V4-Pro: 75.2%Vals AIAs of 10/13/2026
LiveCodeBenchHard · higher is betterGPT-5.6 Sol: 67.4%DeepSeek-V4-Pro: 72.6%Vals AIAs of 09/01/2026
LMArena Text, Style ControlChinese · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 1,540DeepSeek-V4-Pro: 1,500LMArenaAs of 11/11/2026
MMLU ProBusiness · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 93.3%DeepSeek-V4-Pro: 91.9%Vals AIAs of 09/01/2026
ProgramBenchFully Resolved · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 1.5%DeepSeek-V4-Pro: 0.0%Vals AIAs of 11/05/2026
SkillsBenchWith Skills · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 54.1%DeepSeek-V4-Pro: 51.3%Vals AIAs of 10/29/2026
SWE-bench Verified>4 hours · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 100%DeepSeek-V4-Pro: 0%Vals AIAs of 09/01/2026
Tax Agent BenchControversy & Precedence Analysis (weighted pass) · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 68.5%DeepSeek-V4-Pro: 54.8%Vals AIAs of 11/05/2026
TaxEval v2Stepwise Reasoning · higher is betterGPT-5.6 Sol: 84.5%DeepSeek-V4-Pro: 83.6%Vals AIAs of 09/01/2026
Terminal-Bench 4.0Media · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 25%DeepSeek-V4-Pro: 0%Vals AIAs of 11/05/2026
Code MigrationCode Quality · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 3.847 / 5DeepSeek-V4-Pro: 3.401 / 5Vals AIAs of 10/29/2026
CorpFin v2Shared Max Context · higher is betterGPT-5.6 Sol: 66.4%DeepSeek-V4-Pro: 61.9%Vals AIAs of 08/12/2026
EMBDCF · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 62.8%DeepSeek-V4-Pro: 44.4%Vals AIAs of 10/20/2026
Finance Agent (v2)Comparables · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 45.3%DeepSeek-V4-Pro: 39.6%Vals AIAs of 10/29/2026
Legal Research BenchBusiness & Commercial · All-pass · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 53.5%DeepSeek-V4-Pro: 23.3%Vals AIAs of 11/05/2026
LegalBenchIssue Tasks · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 91.4%DeepSeek-V4-Pro: 84.6%Vals AIAs of 10/13/2026
LiveCodeBenchMedium · higher is betterGPT-5.6 Sol: 82.2%DeepSeek-V4-Pro: 91.1%Vals AIAs of 09/01/2026
LMArena Text, Style ControlCoding · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 1,533DeepSeek-V4-Pro: 1,488LMArenaAs of 11/11/2026
MMLU ProChemistry · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 92.0%DeepSeek-V4-Pro: 92.5%Vals AIAs of 09/01/2026
ProgramBenchRaw Pass Rate · higher is betterTest setup not documented as identicalGPT-5.6 Sol: 77.6%DeepSeek-V4-Pro: 47.8%Vals AIAs of 11/05/2026

More comparisons

Compare GPT-5.6 Sol and DeepSeek-V4-Pro with the models people compare them with most often.

Compare another matchup

The most popular comparisons

  1. 1Claude Opus 5.5 vs. DeepSeek-V4-Pro
  2. 2GPT-6 Sol vs. GPT-5.6 Sol
  3. 3GPT-5.6 Sol vs. Gemini 3.8 Flash
  4. 4DeepSeek-V4-Pro vs. DeepSeek-V4.1-Flash
  5. 5GPT-6 Luna vs. DeepSeek-V4-Pro
  6. 6Claude Opus 5.5 vs. GPT-5.6 Sol
  7. 7Claude Sonnet 5.5 vs. DeepSeek-V4-Pro
  8. 8Gemini 3.8 Flash vs. DeepSeek-V4-Pro
  9. 9GPT-6.1 Sol vs. GPT-5.6 Sol
Show all 54 comparisons
  1. 10GPT-6 Luna vs. GPT-5.6 Sol
  2. 11Claude Opus 5 vs. DeepSeek-V4-Pro
  3. 12GPT-5.6 Sol vs. GLM-5.3-Flash
  4. 13DeepSeek-V4-Pro vs. Qwen 3.8 27B
  5. 14Grok 4.7 vs. DeepSeek-V4-Pro
  6. 15Claude Haiku 5.5 vs. DeepSeek-V4-Pro
  7. 16Claude Sonnet 5.5 vs. GPT-5.6 Sol
  8. 17DeepSeek-V4-Pro vs. DeepSeek V4.1 Flash 1017
  9. 18DeepSeek-V4-Pro vs. Kimi K3
  10. 19DeepSeek-V4-Pro vs. MiMo-V2.5-Pro
  11. 20GPT-5.6 Sol vs. DeepSeek-V4.1-Flash
  12. 21DeepSeek-V4-Pro vs. GLM-5.3
  13. 22DeepSeek-V4-Pro vs. Qwen 3.8 Max 0902
  14. 23GPT-5.6 Sol vs. DeepSeek-V4-Flash
  15. 24GPT-5.6 Sol vs. Grok 4.7
  16. 25DeepSeek-V4-Pro vs. MiMo-V2.5
  17. 26Claude Fable 5.1 vs. GPT-5.6 Sol
  18. 27DeepSeek-V4-Pro vs. GLM-5.3-Flash
  19. 28GPT-5.6 Sol vs. Qwen 3.8 27B
  20. 29GPT-5.6 Sol vs. DeepSeek V4.1 Flash 1017
  21. 30GPT-5.6 Sol vs. Muse Spark 1.3
  22. 31DeepSeek-V4-Pro vs. Kimi K3.1 Pro
  23. 32DeepSeek-V4-Pro vs. Mistral Large 4
  24. 33GPT-5.6 Sol vs. GPT-5.6 Luna
  25. 34GPT-5.6 Luna vs. DeepSeek-V4-Pro
  26. 35Claude Sonnet 5 vs. GPT-5.6 Sol
  27. 36Claude Haiku 5.5 vs. GPT-5.6 Sol
  28. 37DeepSeek-V4-Pro vs. DeepSeek-V4-Flash
  29. 38DeepSeek-V4-Pro vs. GLM-5.2
  30. 39Claude Sonnet 5 vs. DeepSeek-V4-Pro
  31. 40GPT-6 Sol vs. DeepSeek-V4-Pro
  32. 41GPT-5.6 Sol vs. Gemini 3.1 Pro Preview
  33. 42GPT-5.6 Sol vs. Grok 4.6
  34. 43Claude Sonnet 4.6 vs. GPT-5.6 Sol
  35. 44GPT-5.6 Sol vs. Kimi K3.1 Pro
  36. 45DeepSeek-V4-Pro vs. Mistral Medium 3.5
  37. 46GPT-5.6 Sol vs. GPT-5.4
  38. 47Claude Opus 4.5 vs. DeepSeek-V4-Pro
  39. 48GPT-5.6 Sol vs. Gemini 4 Argon
  40. 49GPT-6.1 Terra vs. GPT-5.6 Sol
  41. 50Gemini 4 Argon vs. DeepSeek-V4-Pro
  42. 51GPT-5.6 Sol vs. Gemini 4 Carbon
  43. 52Gemini 4 Carbon vs. DeepSeek-V4-Pro
  44. 53GPT-6.1 Terra vs. DeepSeek-V4-Pro
  45. 54GPT-6.1 Sol vs. DeepSeek-V4-Pro