
Head-to-head comparison

GPT-5.6 Sol vs. GPT-5.6 Luna

Compare published benchmark results from matching versions and cohorts, API pricing, and technical specifications. Any documented test setup differences remain visible.

shared result series
222
distinct benchmarks
37
latest retrieval
2026-09-29

Change model selection

Specifications

General specifications

Release date, availability, context window, architecture, and published parameter counts at a glance. Undisclosed details remain marked as unavailable.

Specifications for GPT-5.6 Sol and GPT-5.6 Luna
AttributeGPT-5.6 SolGPT-5.6 Luna
ProviderOpenAIOpenAI
ReleasedJul 9, 2026Jul 9, 2026
AvailabilityActiveActive
Model typeProprietaryProprietary
ParametersNot publishedNot published
ArchitectureNot publishedNot published
Context window1,050,000 tokens1,050,000 tokens
Knowledge cutoffFebruary 16, 2026February 16, 2026
Technical sourcesModel, Context, Knowledge cutoffModel, Context, Knowledge cutoff

Pricing

API pricing compared

The table compares official standard API rates per 1M tokens, including published cache pricing. Batch, fast, priority, regional surcharges, tool calls, and cloud platform pricing are excluded.

API pricing for GPT-5.6 Sol and GPT-5.6 Luna
Price typeGPT-5.6 SolGPT-5.6 Luna
API input$4 ≤272K / $8 >272K$0.2 ≤272K / $0.4 >272K
API output$20 ≤272K / $30 >272K$1.2 ≤272K / $1.8 >272K
Cache read$0.4 ≤272K / $0.8 >272K$0.02 ≤272K / $0.04 >272K
Cache write (5 min.)$5 ≤272K / $10 >272K$0.25 ≤272K / $0.5 >272K
Cache write (1 hr.)Not listedNot listed
Price verified09/22/2026 Source09/22/2026 Source
GPT-5.6 SolGPT-5.6 Luna
API inputUSD per 1M tokens, base tier
GPT-5.6 Sol$4
GPT-5.6 LunaLower price$0.2
API outputUSD per 1M tokens, base tier
GPT-5.6 Sol$20
GPT-5.6 LunaLower price$1.2
Cache readUSD per 1M tokens, base tier
GPT-5.6 Sol$0.4
GPT-5.6 LunaLower price$0.02

Key to the marks:better valuebetter, but not conclusivetie

Pricing by provider

Direct developer pricing and provider endpoint tariffs routed through OpenRouter are listed separately. Prices are in USD per 1M tokens. Context-dependent direct tiers plus regional, Flex, Priority, and other OpenRouter tariffs remain individually identifiable.

Provider pricing for GPT-5.6 Sol and GPT-5.6 Luna
ModelProviderPurchase route and tariffInput per 1M tokensOutput per 1M tokensSource
GPT-5.6 SolOpenAIDirect from developerUp to 272,000 context tokens$4$20Source09/22/2026
OpenAIDirect from developerAbove 272,000 context tokens$8$30Source09/22/2026
Amazon BedrockVia OpenRouteramazon-bedrock/us-east-1$4.4$22Source10/03/2026
AzureVia OpenRouterazure$4$20Source10/03/2026
AzureVia OpenRouterazure/eu$4.4$22Source10/03/2026
AzureVia OpenRouterazure/us$4.4$22Source10/03/2026
OpenAIVia OpenRouteropenai$2$10Source10/03/2026
OpenAIVia OpenRouteropenai/fast$4$20Source10/03/2026
OpenAIVia OpenRouteropenai/flexLowest listed price: $1Lowest listed price: $5Source10/03/2026
GPT-5.6 LunaOpenAIDirect from developerUp to 272,000 context tokens$0.2$1.2Source09/22/2026
OpenAIDirect from developerAbove 272,000 context tokens$0.4$1.8Source09/22/2026
Amazon BedrockVia OpenRouteramazon-bedrock/us-east-1$0.22$1.32Source10/03/2026
AzureVia OpenRouterazure$0.2$1.2Source10/03/2026
AzureVia OpenRouterazure/eu$0.22$1.32Source10/03/2026
AzureVia OpenRouterazure/us$0.22$1.32Source10/03/2026
OpenAIVia OpenRouteropenai$0.2$1.2Source10/03/2026
OpenAIVia OpenRouteropenai/fast$0.4$2.4Source10/03/2026
OpenAIVia OpenRouteropenai/flexLowest listed price: $0.1Lowest listed price: $0.6Source10/03/2026

Performance

Shared benchmarks

Only published results with the same benchmark version, task, metric, and comparison cohort are paired. Different reasoning levels, agents, harnesses, or output limits appear directly in the table.

Capability profile from matched benchmarks

Each axis averages directly matched benchmark families. A value of 100 means the stronger value within this pair, not a universal quality score.

255075100CodingReasoningMathematicsKnowledgeFinanceLegalAgentic tasksMultimodal
GPT-5.6 Sol
GPT-5.6 Luna
Coding: 98.6 / 74.5 (8 benchmark families)
Reasoning: 100 / 76.4 (3 benchmark families)
Mathematics: 100 / 85.3 (2 benchmark families)
Knowledge: 100 / 96.7 (2 benchmark families)
Finance: 99 / 96.9 (7 benchmark families)
Legal: 99 / 94.7 (4 benchmark families)
Agentic tasks: 97.2 / 64.4 (3 benchmark families)
Multimodal: 100 / 95.7 (1 benchmark family)

216 matched rows from 35 benchmark families were considered. The radar shows 8 of 15 comparable categories.

GPT-5.6 SolGPT-5.6 Luna
ARC-AGI-2Overall. Higher is better. No documented setup difference
GPT-5.6 SolWinner85.4 %
GPT-5.6 Luna29.3 %
ARC-AGI-3RHAE overall score. Higher is better. Test setup not documented as identical
GPT-5.6 SolHigher measured value2.15 %
GPT-5.6 Luna0.18 %
BioMysteryBenchOverall. Higher is better. No documented setup difference
GPT-5.6 SolWinner71.111 %
GPT-5.6 Luna61.481 %
BrowseCompOverall. Higher is better. No documented setup difference
GPT-5.6 SolWinner90.4 %
GPT-5.6 Luna83.3 %
Code MigrationOverall. Higher is better. No documented setup difference
GPT-5.6 SolWinner52.916 %
GPT-5.6 Luna44.55 %
CorpFin v2Overall. Higher is better. No documented setup difference
GPT-5.6 SolWinner64.375 %
GPT-5.6 Luna64.219 %
CyberBench v1.1Overall. Higher is better. No documented setup difference
GPT-5.6 SolWinner76.31 %
GPT-5.6 Luna73.631 %
EMBOverall. Higher is better. No documented setup difference
GPT-5.6 SolWinner72.339 %
GPT-5.6 Luna67.116 %
Finance Agent (v2)Overall. Higher is better. No documented setup difference
GPT-5.6 Sol53.756 %
GPT-5.6 LunaWinner55.044 %
GPQA DiamondOverall. Higher is better. No documented setup difference
GPT-5.6 SolWinner95.202 %
GPT-5.6 Luna91.666 %
Harvey's Legal Agent BenchmarkOverall · Task fully resolved. Higher is better. No documented setup difference
GPT-5.6 SolWinner2.5 %
GPT-5.6 Luna1.25 %
IOIOverall. Higher is better. No documented setup difference
GPT-5.6 SolWinner91.167 %
GPT-5.6 Luna61.778 %

Key to the marks:better valuebetter, but not conclusivetie

Benchmark scores for GPT-5.6 Sol and GPT-5.6 Luna
Benchmark and taskGPT-5.6 SolGPT-5.6 LunaSource
ARC-AGI-2Overall
Test details
No documented difference in the test setupVersion: 2Metric: exact task accuracyScoring: Higher is betterSettings: Reasoning: high, Attempts: two exact output guesses per taskThe same verified test with five reasoning levels per model.
Winner85.4 %
29.3 %
ARC Prize
Source details
Data as of: 07/09/2026
ARC-AGI-3RHAE overall score
Test details
Test setup not documented as identicalNo direct winnerVersion: ARC-AGI-3 2026 verifiedMetric: RHAE scoreScoring: Higher is betterGPT-5.6 Sol: Reasoning: high, Agent: ARC Prize official harness, Harness: ARC Prize official harness
GPT-5.6 Luna: Reasoning: max, Agent: ARC Prize official harness, Harness: ARC Prize official harness
Official ARC Prize harness on unseen interactive environments. Reasoning levels remain separate.
Higher measured value2.15 %
0.18 %
ARC Prize
Source details
Data as of: 08/26/2026
BioMysteryBenchOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Harness: Terminus 2
Winner71.111 %
61.481 %
Vals AI
Source details
Data as of: 09/27/2026
BrowseCompOverall
Test details
No documented difference in the test setupVersion: 1,266 tasksMetric: accuracyScoring: Higher is betterCross-vendor comparison table with browsing tools. Exact agent systems differ.
Winner90.4 %
Editorial selection from the vendor table, not a complete extract of the comparison cohort.
83.3 %
Editorial selection from the vendor table, not a complete extract of the comparison cohort.
OpenAI
Source details
Data as of: 07/09/2026
Code MigrationOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is better
Winner52.916 %
44.55 %
Vals AI
Source details
Data as of: 09/27/2026
CorpFin v2Overall
Test details
No documented difference in the test setupVersion: 2Metric: accuracyScoring: Higher is better
Winner64.375 %
64.219 %
Vals AI
Source details
Data as of: 08/12/2026
CyberBench v1.1Overall
Test details
No documented difference in the test setupVersion: 1.1Metric: accuracyScoring: Higher is better
Winner76.31 %
73.631 %
Vals AI
Source details
Data as of: 09/27/2026
EMBOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is better
Winner72.339 %
67.116 %
Vals AI
Source details
Data as of: 09/27/2026
Finance Agent (v2)Overall
Test details
No documented difference in the test setupVersion: 2Metric: accuracyScoring: Higher is better
53.756 %
Winner55.044 %
Vals AI
Source details
Data as of: 09/27/2026
GPQA DiamondOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is better
Winner95.202 %
91.666 %
Vals AI
Source details
Data as of: 09/01/2026
Harvey's Legal Agent BenchmarkOverall · Task fully resolved
Test details
No documented difference in the test setupVersion: 1Metric: task resolution rateScoring: Higher is better
Winner2.5 %
1.25 %
Vals AI
Source details
Data as of: 09/27/2026
IOIOverall
Test details
No documented difference in the test setupVersion: 2Metric: accuracyScoring: Higher is better
Winner91.167 %
61.778 %
Vals AI
Source details
Data as of: 09/27/2026
Legal Research BenchOverall · All-pass
Test details
No documented difference in the test setupVersion: 1Metric: all-pass rateScoring: Higher is better
Winner48.077 %
36.538 %
Vals AI
Source details
Data as of: 09/27/2026
LegalBenchOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is better
Winner86.965 %
84.034 %
Vals AI
Source details
Data as of: 09/27/2026
LMArena Text, Style ControlOverall
Test details
No documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Sol: Snapshot: gpt-5.6-sol-xhigh, Reasoning: xhigh, Harness: Arena text, style control
GPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control
GPT-5.6 Sol: Style-controlled Arena rating from 34,258 anonymous pairwise votes.GPT-5.6 Luna: Style-controlled Arena rating from 35,823 anonymous pairwise votes.
Winner1,483.171
95% confidence interval: ±4.527The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,453.977
95% confidence interval: ±4.487The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena
Source details
Data as of: 09/25/2026
MedCodeOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is better
Winner43.974 %
42.391 %
Vals AI
Source details
Data as of: 09/26/2026
MedScribeOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is better
Winner85.233 %
84.391 %
Vals AI
Source details
Data as of: 09/26/2026
MMLU-ProOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is better
Winner89.1 %
86.036 %
Vals AI
Source details
Data as of: 09/01/2026
MMMU-ProOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is better
Winner88.844 %
85.029 %
Vals AI
Source details
Data as of: 09/01/2026
MortgageTaxOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is better
67.289 %
Winner67.29 %
Vals AI
Source details
Data as of: 09/01/2026
MysteryMechanismOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is better
Winner33.333 %
14.414 %
Vals AI
Source details
Data as of: 09/27/2026
ProgramBenchOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is better
Winner1.5 %
0 %
Vals AI
Source details
Data as of: 09/27/2026
ProofBenchOverall
Test details
No documented difference in the test setupVersion: 1.1Metric: accuracyScoring: Higher is better
Winner83 %
60 %
Vals AI
Source details
Data as of: 09/28/2026
Public Benefits Bench v1.1Overall
Test details
No documented difference in the test setupVersion: 1.1Metric: accuracyScoring: Higher is better
Winner66.509 %
61.164 %
Vals AI
Source details
Data as of: 09/27/2026
SAGEOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is better
Winner52.563 %
44.22 %
Vals AI
Source details
Data as of: 09/26/2026
SkillsBenchOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Harness: OpenHands
54.1 %
Winner60.447 %
Vals AI
Source details
Data as of: 09/27/2026
SWE-bench VerifiedOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is better
Winner96.2 %
93 %
Vals AI
Source details
Data as of: 09/01/2026
Taste-BenchOverall
Test details
Test setup not documented as identicalNo direct winnerVersion: arxiv:2609.25804v2Metric: both-orders-correct, engineering/research macro averageScoring: Higher is betterGPT-5.6 Sol: Reasoning: xhigh, Output limit: 65,536 tokens, Attempts: 502 questions, two option orders each
GPT-5.6 Luna: Reasoning: default, Output limit: 65,536 tokens, Attempts: 502 questions, two option orders each
Same prompt for all models. Each of 502 questions is shown twice with the options reversed. Average of engineering and research success rates, requiring both orders to be correct. 65,536-token output budget; unparseable answers count as wrong.
Higher measured value59.7 %
0 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
49 %
0 of 1,004 responses were unparseable and counted as wrong. Not a Gradually test.
Taste-Bench paper
Source details
Data as of: 09/23/2026
Tax Agent BenchOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is better
Winner67.955 %
60.815 %
Vals AI
Source details
Data as of: 09/27/2026
TaxEval v2Overall
Test details
No documented difference in the test setupVersion: 2Metric: accuracyScoring: Higher is better
74.775 %
Winner76.166 %
Vals AI
Source details
Data as of: 09/01/2026
Terminal-Bench 2.1Overall
Test details
No documented difference in the test setupVersion: 2.1Metric: accuracyScoring: Higher is better
Winner85.768 %
79.026 %
Vals AI
Source details
Data as of: 09/27/2026
Terminal-Bench 4.0Overall
Test details
No documented difference in the test setupVersion: 4.0Metric: accuracyScoring: Higher is better
Winner27.778 %
4.545 %
Vals AI
Source details
Data as of: 09/27/2026
Terminal-Bench ScienceOverall
Test details
No documented difference in the test setupVersion: 0.1Metric: accuracyScoring: Higher is better
Winner12.857 %
5.714 %
Vals AI
Source details
Data as of: 09/27/2026
Vals IndexOverall
Test details
No documented difference in the test setupVersion: 2Metric: weighted index scoreScoring: Higher is better
Winner63.709 %
59.881 %
Vals AI
Source details
Data as of: 09/27/2026
Vals Multimodal IndexOverall
Test details
No documented difference in the test setupVersion: 1.2Metric: weighted index scoreScoring: Higher is better
Winner72.64 %
69.058 %
Vals AI
Source details
Data as of: 08/11/2026
Vibe Code Bench 1-100Overall
Test details
No documented difference in the test setupVersion: 1.0Metric: accuracyScoring: Higher is betterSettings: Harness: OpenHands
20.011 %
Winner22.594 %
Vals AI
Source details
Data as of: 09/22/2026
Vibe Code Bench v1.1Overall
Test details
No documented difference in the test setupVersion: 1.1Metric: accuracyScoring: Higher is betterSettings: Harness: OpenHands
Winner80.495 %
77.055 %
Vals AI
Source details
Data as of: 09/27/2026
ARC-AGI-2Overall
Test details
No documented difference in the test setupVersion: 2Metric: exact task accuracyScoring: Higher is betterSettings: Reasoning: low, Attempts: two exact output guesses per taskThe same verified test with five reasoning levels per model.
Winner42.5 %
5.1 %
ARC Prize
Source details
Data as of: 07/09/2026
ARC-AGI-3RHAE overall score
Test details
Test setup not documented as identicalNo direct winnerVersion: ARC-AGI-3 2026 verifiedMetric: RHAE scoreScoring: Higher is betterGPT-5.6 Sol: Reasoning: low, Agent: ARC Prize official harness, Harness: ARC Prize official harness
GPT-5.6 Luna: Reasoning: max, Agent: ARC Prize official harness, Harness: ARC Prize official harness
Official ARC Prize harness on unseen interactive environments. Reasoning levels remain separate.
Higher measured value0.33 %
0.18 %
ARC Prize
Source details
Data as of: 08/26/2026
BrowseCompOverall
Test details
Test setup not documented as identicalNo direct winnerVersion: 1,266 tasksMetric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: ultraCross-vendor comparison table with browsing tools. Exact agent systems differ.
Higher measured value92.2 %
Editorial selection from the vendor table, not a complete extract of the comparison cohort.
83.3 %
Editorial selection from the vendor table, not a complete extract of the comparison cohort.
OpenAI
Source details
Data as of: 07/09/2026
Code MigrationCLI
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: max, Output limit: 128,000 tokens
Winner47.221 %
36.067 %
Vals AI
Source details
Data as of: 08/09/2026
CorpFin v2Exact Pages
Test details
No documented difference in the test setupVersion: 2Metric: accuracyScoring: Higher is betterSettings: Reasoning: max, Output limit: 128,000 tokens
61.538 %
Winner63.52 %
Vals AI
Source details
Data as of: 08/06/2026
CyberBench v1.1Patch
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is better
Winner83.051 %
79.661 %
Vals AI
Source details
Data as of: 08/03/2026
EMBComps
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: max, Output limit: 128,000 tokens
Winner71.309 %
54.573 %
Vals AI
Source details
Data as of: 08/06/2026
Finance Agent (v2)Adjustments
Test details
No documented difference in the test setupVersion: 2Metric: accuracyScoring: Higher is betterSettings: Reasoning: max, Output limit: 128,000 tokens
49.233 %
Winner52.027 %
Vals AI
Source details
Data as of: 08/06/2026
GPQA DiamondFew-Shot CoT
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: max, Output limit: 128,000 tokens
Winner94.949 %
92.424 %
Vals AI
Source details
Data as of: 08/09/2026
Harvey's Legal Agent BenchmarkAntitrust Competition · Criteria passed
Test details
No documented difference in the test setupVersion: 1Metric: criteria pass rateScoring: Higher is betterSettings: Reasoning: max, Output limit: 128,000 tokens
78.623 %
Winner85.145 %
Vals AI
Source details
Data as of: 08/07/2026
IOIIOI 2024
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: max, Output limit: 128,000 tokens
Winner85 %
78 %
Vals AI
Source details
Data as of: 08/09/2026
Legal Research BenchAdministrative / Regulatory · All-pass
Test details
No documented difference in the test setupVersion: 1Metric: all-pass rateScoring: Higher is betterSettings: Reasoning: max, Output limit: 128,000 tokens
Winner60.606 %
48.485 %
Vals AI
Source details
Data as of: 08/06/2026
LegalBenchConclusion Tasks
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: max, Output limit: 128,000 tokens
Winner90.492 %
88.864 %
Vals AI
Source details
Data as of: 08/09/2026
LMArena Text, Style ControlBusiness, management and finance
Test details
No documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Sol: Snapshot: gpt-5.6-sol-xhigh, Reasoning: xhigh, Harness: Arena text, style control
GPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control
GPT-5.6 Sol: Style-controlled Arena rating from 6,528 anonymous pairwise votes.GPT-5.6 Luna: Style-controlled Arena rating from 6,871 anonymous pairwise votes.
Winner1,485.385
95% confidence interval: ±8.098The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,463.458
95% confidence interval: ±7.984The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena
Source details
Data as of: 09/25/2026
MMLU-ProBiology
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: max, Output limit: 128,000 tokens
Winner94.561 %
93.305 %
Vals AI
Source details
Data as of: 08/09/2026
MortgageTaxNumerical Extraction
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: max, Output limit: 128,000 tokens
75.119 %
Winner75.596 %
Vals AI
Source details
Data as of: 08/09/2026
ProgramBenchAlmost Resolved
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: max, Output limit: 128,000 tokens
Winner23 %
9 %
Vals AI
Source details
Data as of: 08/09/2026
SAGEAutomata
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: max, Output limit: 30,000 tokens
Winner39.682 %
31.35 %
Vals AI
Source details
Data as of: 08/09/2026
SkillsBenchNo Skills
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: max, Harness: OpenHands, Output limit: 128,000 tokens
43.312 %
Winner45.189 %
Vals AI
Source details
Data as of: 08/07/2026
SWE-bench Verified<15 min fix
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: max, Output limit: 128,000 tokens
Winner97.423 %
96.392 %
Vals AI
Source details
Data as of: 08/08/2026
TaxEval v2Correctness
Test details
No documented difference in the test setupVersion: 2Metric: accuracyScoring: Higher is betterSettings: Reasoning: max, Output limit: 128,000 tokens
65.004 %
Winner66.558 %
Vals AI
Source details
Data as of: 08/09/2026
Terminal-Bench 2.1Easy
Test details
No documented difference in the test setupVersion: 2.1Metric: accuracyScoring: Higher is betterSettings: Reasoning: max, Output limit: 128,000 tokens
Winner91.667 %
83.333 %
Vals AI
Source details
Data as of: 08/06/2026
Vals IndexCorpFin v2
Test details
No documented difference in the test setupVersion: 1.2Metric: benchmark scoreScoring: Higher is betterSettings: Reasoning: max, Output limit: 128,000 tokens
Winner66.434 %
65.035 %
Vals AI
Source details
Data as of: 08/09/2026
Vals Multimodal IndexCorpFin v2
Test details
No documented difference in the test setupVersion: 1.2Metric: benchmark scoreScoring: Higher is betterSettings: Reasoning: max, Output limit: 128,000 tokens
Winner66.434 %
65.035 %
Vals AI
Source details
Data as of: 08/09/2026
ARC-AGI-2Overall
Test details
No documented difference in the test setupVersion: 2Metric: exact task accuracyScoring: Higher is betterSettings: Reasoning: max, Attempts: two exact output guesses per taskThe same verified test with five reasoning levels per model.
Winner92.5 %
59.5 %
ARC Prize
Source details
Data as of: 07/09/2026
ARC-AGI-3RHAE overall score
Test details
No documented difference in the test setupVersion: ARC-AGI-3 2026 verifiedMetric: RHAE scoreScoring: Higher is betterSettings: Reasoning: max, Agent: ARC Prize official harness, Harness: ARC Prize official harnessOfficial ARC Prize harness on unseen interactive environments. Reasoning levels remain separate.
Winner7.78 %
0.18 %
ARC Prize
Source details
Data as of: 08/26/2026
Code MigrationCOBOL
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: max, Output limit: 128,000 tokens
Tie70 %
Tie70 %
Vals AI
Source details
Data as of: 08/09/2026

Key to the marks:better valuebetter, but not conclusivetie

Our model tests

Our tests

Compare how the models respond to the same prompt. Each test shows the first attempt, with no subsequent fixes to the generated code. These results do not contribute to an overall score.

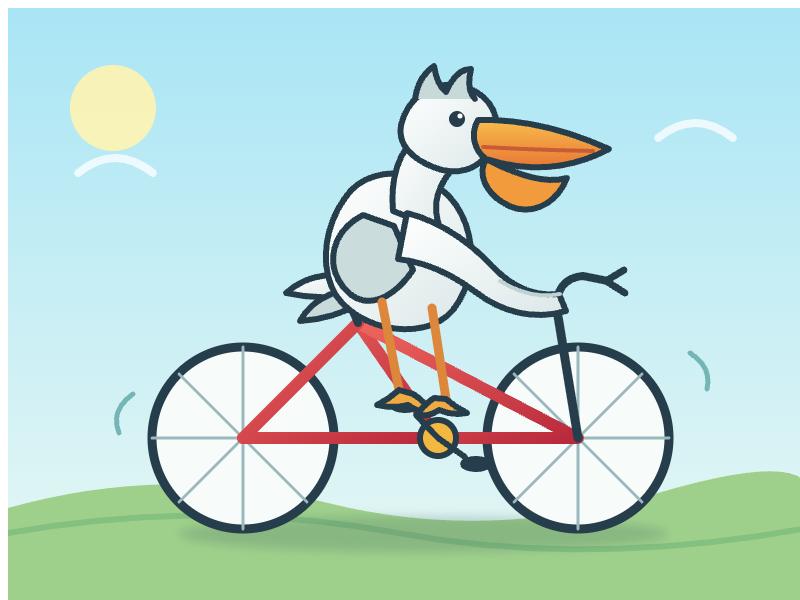
Pelican on a bicycle

A community classic for free-form SVG drawing.

GPT-5.6 Sol

API access was unavailable for this run. The model was not evaluated.

Reasoning (requested): high

First attempt
Run date
7 Sept 2026
API provider
openrouter
Requested API model
openai/gpt-5.6-sol
Reasoning setting
high
Pinned endpoint
OpenAI | openai/gpt-5.6-sol-20260709
Temperature
Provider default
Token limit including reasoning
8,192 tokens
Test protocol
community-visual-tests-v1
Technical checks
Not run

Not yet visually reviewed. A successful recording does not confirm correct physics or full compliance with the prompt.

GPT-5.6 Luna

GPT-5.6 Luna: Pelican on a bicycle
A community classic for free-form SVG drawing.

Reasoning (requested): high

First attempt
Run date
7 Sept 2026
API provider
openrouter
Requested API model
openai/gpt-5.6-luna
API model reported in response
openai/gpt-5.6-luna
Reasoning setting
high
Pinned endpoint
OpenAI | openai/gpt-5.6-luna-20260709
Temperature
Provider default
Token limit including reasoning
8,192 tokens
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating
Response time
49.9 s

Visually reviewed. This individual test does not establish overall model quality.

Prompt and test conditions

Generate an SVG of a pelican riding a bicycle

Token limit including reasoning: 8,192 tokens

Task origin (Simon Willison)

How to read this comparison

Winning one benchmark is not an overall verdict

Your workload, budget, and required context length matter most. A coding benchmark says little about visual understanding or agent performance.

The standard price table uses direct developer rates. The provider comparison labels OpenRouter endpoints, regions, and special tariffs separately.

Every result links to its measurement source and retrieval date. Labels distinguish vendor reports, official benchmark leaderboards, and independent evaluations. Disputed or archived results are excluded.

More matchups

Compare GPT-5.6 Sol and GPT-5.6 Luna with other leading models using the same data and benchmark logic.
View the complete LLM comparison