Claude Opus 5.5
Unavailable in this round
Head-to-head comparison
Compare published benchmark results from matching versions and cohorts, API pricing, and technical specifications. Any documented test setup differences remain visible.
Specifications
Release date, availability, context window, architecture, and published parameter counts at a glance. Undisclosed details remain marked as unavailable.
| Attribute | Claude Opus 5.5 | GPT-5.6 Luna |
|---|---|---|
| Provider | Anthropic | OpenAI |
| Released | Sep 22, 2026 | Jul 9, 2026 |
| Availability | Active | Active |
| Model type | Proprietary | Proprietary |
| Parameters | Not published | Not published |
| Architecture | Not published | Not published |
| Context window | 1,000,000 tokens | 1,050,000 tokens |
| Knowledge cutoff | June 2026 | February 16, 2026 |
| Technical sources | Model | Model, Context, Knowledge cutoff |
Pricing
The table compares official standard API rates per 1M tokens, including published cache pricing. Batch, fast, priority, regional surcharges, tool calls, and cloud platform pricing are excluded.
| Price type | Claude Opus 5.5 | GPT-5.6 Luna |
|---|---|---|
| API input | $4 | $0.2 ≤272K / $0.4 >272K |
| API output | $20 | $1.2 ≤272K / $1.8 >272K |
| Cache read | $0.2 | $0.02 ≤272K / $0.04 >272K |
| Cache write (5 min.) | $5 | $0.25 ≤272K / $0.5 >272K |
| Cache write (1 hr.) | $8 | Not listed |
| Price verified | 09/22/2026 Source | 09/22/2026 Source |
Key to the marks:better valuebetter, but not conclusivetie
Direct developer pricing and provider endpoint tariffs routed through OpenRouter are listed separately. Prices are in USD per 1M tokens. Context-dependent direct tiers plus regional, Flex, Priority, and other OpenRouter tariffs remain individually identifiable.
| Model | Provider | Purchase route and tariff | Input per 1M tokens | Output per 1M tokens | Source |
|---|---|---|---|---|---|
| Claude Opus 5.5 | Anthropic | Direct from developerStandard API | Lowest listed price: $4 | Lowest listed price: $20 | Source09/22/2026 |
| Amazon Bedrock | Via OpenRouteramazon-bedrock | Lowest listed price: $4 | Lowest listed price: $20 | Source10/17/2026 | |
| Amazon Bedrock | Via OpenRouteramazon-bedrock/eu-west-1 | $4.4 | $22 | Source10/17/2026 | |
| Amazon Bedrock | Via OpenRouteramazon-bedrock/us-east-1 | $4.4 | $22 | Source10/17/2026 | |
| Anthropic | Via OpenRouteranthropic | Lowest listed price: $4 | Lowest listed price: $20 | Source10/17/2026 | |
| Anthropic | Via OpenRouteranthropic/fast | $8 | $40 | Source10/17/2026 | |
| Azure | Via OpenRouterazure/global | Lowest listed price: $4 | Lowest listed price: $20 | Source10/17/2026 | |
| Azure | Via OpenRouterazure/us | $4.4 | $22 | Source10/17/2026 | |
| Claude Platform on AWS | Via OpenRouterclaude-on-aws | Lowest listed price: $4 | Lowest listed price: $20 | Source10/17/2026 | |
| Via OpenRoutergoogle-vertex/europe | $4.4 | $22 | Source10/17/2026 | ||
| Via OpenRoutergoogle-vertex/global | Lowest listed price: $4 | Lowest listed price: $20 | Source10/17/2026 | ||
| Via OpenRoutergoogle-vertex/us | $4.4 | $22 | Source10/17/2026 | ||
| GPT-5.6 Luna | OpenAI | Direct from developerUp to 272,000 context tokens | $0.2 | $1.2 | Source09/22/2026 |
| OpenAI | Direct from developerAbove 272,000 context tokens | $0.4 | $1.8 | Source09/22/2026 | |
| Amazon Bedrock | Via OpenRouteramazon-bedrock/us-east-1 | $0.22 | $1.32 | Source10/17/2026 | |
| Azure | Via OpenRouterazure | $0.2 | $1.2 | Source10/17/2026 | |
| Azure | Via OpenRouterazure/eu | $0.22 | $1.32 | Source10/17/2026 | |
| Azure | Via OpenRouterazure/us | $0.22 | $1.32 | Source10/17/2026 | |
| OpenAI | Via OpenRouteropenai | $0.2 | $1.2 | Source10/17/2026 | |
| OpenAI | Via OpenRouteropenai/fast | $0.4 | $2.4 | Source10/17/2026 | |
| OpenAI | Via OpenRouteropenai/flex | Lowest listed price: $0.1 | Lowest listed price: $0.6 | Source10/17/2026 |
Performance
Only published results with the same benchmark version, task, metric, and comparison cohort are paired. Different reasoning levels, agents, harnesses, or output limits appear directly in the table.
Each axis averages directly matched benchmark families. A value of 100 means the stronger value within this pair, not a universal quality score.
Not enough directly matched categories for a reliable radar
Only 0 of at least 5 categories have comparable, direct model measurements. The benchmark tables below show the available evidence without filling missing axes.
Key to the marks:better valuebetter, but not conclusivetie
| Benchmark and task | Claude Opus 5.5 | GPT-5.6 Luna | Source |
|---|---|---|---|
BioMysteryBenchOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Harness: Terminus 2, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Harness: Terminus 2, Output limit: 128,000 tokens | Higher measured value79.259 % | 61.481 % | Vals AISource detailsData as of: 10/12/2026 |
Code MigrationOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value66.646 % | 44.55 % | Vals AISource detailsData as of: 10/12/2026 |
CyberBench v1.1OverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1.1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 55.357 % | Higher measured value73.631 % | Vals AISource detailsData as of: 10/12/2026 |
EMBOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value75.938 % | 67.116 % | Vals AISource detailsData as of: 10/12/2026 |
Finance Agent (v2)OverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value58.587 % | 55.044 % | Vals AISource detailsData as of: 10/12/2026 |
Harvey's Legal Agent BenchmarkOverall · Task fully resolvedTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: task resolution rateScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value3.75 % | 1.25 % | Vals AISource detailsData as of: 10/12/2026 |
IOIOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value95.056 % | 61.778 % | Vals AISource detailsData as of: 10/14/2026 |
Legal Research BenchOverall · All-passTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: all-pass rateScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value50.481 % | 36.538 % | Vals AISource detailsData as of: 10/12/2026 |
LMArena Text, Style ControlOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 5.5: Snapshot: claude-opus-5.5-high, Reasoning: high, Harness: Arena Text, style control GPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena Text, style controlClaude Opus 5.5: Arena rating from 7,687 published pairwise votes.GPT-5.6 Luna: Arena rating from 41,103 published pairwise votes. | Higher measured value1,508.083 95% confidence interval: ±7.535The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,452.509 95% confidence interval: ±4.306The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Vision, Style ControlOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 5.5: Snapshot: claude-opus-5.5-high, Reasoning: high, Harness: Arena Vision, style control GPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena Vision, style controlClaude Opus 5.5: Arena rating from 2,508 published pairwise votes.GPT-5.6 Luna: Arena rating from 11,086 published pairwise votes. | Higher measured value1,292.688 95% confidence interval: ±12.73The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,257.662 95% confidence interval: ±7.463The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/09/2026 |
MedCodeOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 30,000 tokens | Higher measured value49.797 % | 42.391 % | Vals AISource detailsData as of: 10/13/2026 |
MedScribeOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 30,000 tokens | Higher measured value91.43 % | 84.391 % | Vals AISource detailsData as of: 10/13/2026 |
MysteryMechanismOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value49.55 % | 14.414 % | Vals AISource detailsData as of: 10/12/2026 |
ProgramBenchOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: fully resolved rateScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value18.5 % | 0 % | Vals AISource detailsData as of: 10/12/2026 |
ProofBenchOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1.1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value100 % | 60 % | Vals AISource detailsData as of: 10/12/2026 |
Public Benefits Bench v1.1OverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1.1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value70.636 % | 61.164 % | Vals AISource detailsData as of: 10/12/2026 |
SAGEOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 30,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 30,000 tokens | Higher measured value45.831 % | 44.22 % | Vals AISource detailsData as of: 10/08/2026 |
SRE BenchOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: fully solved rateScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value33.588 % | 1.527 % | Vals AISource detailsData as of: 10/14/2026 |
Tax Agent BenchOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value45.573 % | 24.815 % | Vals AISource detailsData as of: 10/12/2026 |
Terminal-Bench 2.1OverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 2.1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: high, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value87.64 % | 79.026 % | Vals AISource detailsData as of: 09/28/2026 |
Terminal-Bench 4.0OverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 4.0Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value65.152 % | 11.616 % | Vals AISource detailsData as of: 10/13/2026 |
Terminal-Bench ScienceOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 0.1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Harness: Mini-SWE-agent, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Harness: Mini-SWE-agent, Output limit: 128,000 tokens | Higher measured value47.143 % | 0 % | Vals AISource detailsData as of: 10/14/2026 |
Vals IndexOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 2.1Metric: weighted index scoreScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value66.972 % | 51.687 % | Vals AISource detailsData as of: 10/13/2026 |
Vibe Code Bench 1-100OverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1.0Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: xhigh, Harness: OpenHands, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Harness: OpenHands, Output limit: 128,000 tokens | Higher measured value30.361 % | 22.594 % | Vals AISource detailsData as of: 10/14/2026 |
Vibe Code Bench v1.1OverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1.1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Harness: OpenHands, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Harness: OpenHands, Output limit: 128,000 tokens | Higher measured value90.294 % | 77.055 % | Vals AISource detailsData as of: 10/12/2026 |
BioMysteryBenchHardTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Harness: Terminus 2, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Harness: Terminus 2, Output limit: 128,000 tokens | Higher measured value47.059 % | 27.451 % | Vals AISource detailsData as of: 10/12/2026 |
Code MigrationCLITest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value65.528 % | 36.067 % | Vals AISource detailsData as of: 10/12/2026 |
CyberBench v1.1PatchTest detailsTest setup not documented as identicalNo direct winnerVersion: 1.1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value85.714 % | 83.929 % | Vals AISource detailsData as of: 10/12/2026 |
EMBCompsTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value76.405 % | 54.573 % | Vals AISource detailsData as of: 10/12/2026 |
Finance Agent (v2)AdjustmentsTest detailsTest setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value54.528 % | 52.027 % | Vals AISource detailsData as of: 10/12/2026 |
Harvey's Legal Agent BenchmarkAntitrust Competition · Criteria passedTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: criteria pass rateScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 82.246 % | Higher measured value85.145 % | Vals AISource detailsData as of: 10/12/2026 |
IOIIOI 2024Test detailsTest setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value100 % | 85 % | Vals AISource detailsData as of: 10/14/2026 |
Legal Research BenchAdministrative / Regulatory · All-passTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: all-pass rateScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value65.152 % | 48.485 % | Vals AISource detailsData as of: 10/12/2026 |
LMArena Text, Style ControlBusiness, management and financeTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 5.5: Snapshot: claude-opus-5.5-high, Reasoning: high, Harness: Arena Text, style control GPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena Text, style controlClaude Opus 5.5: Arena rating from 1,370 published pairwise votes.GPT-5.6 Luna: Arena rating from 7,709 published pairwise votes. | Higher measured value1,492.054 95% confidence interval: ±16.446The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,461.658 95% confidence interval: ±7.593The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Vision, Style ControlCreative writing visionTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 5.5: Snapshot: claude-opus-5.5-high, Reasoning: high, Harness: Arena Vision, style control GPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena Vision, style controlClaude Opus 5.5: Arena rating from 219 published pairwise votes.GPT-5.6 Luna: Arena rating from 969 published pairwise votes. | Higher measured value1,301.035 95% confidence interval: ±42.823The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,258.178 95% confidence interval: ±20.085The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/09/2026 |
ProgramBenchAlmost ResolvedTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: almost-resolved rateScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value65 % | 9 % | Vals AISource detailsData as of: 10/12/2026 |
SAGEAutomataTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 30,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 30,000 tokens | Higher measured value32.54 % | 31.35 % | Vals AISource detailsData as of: 10/08/2026 |
SRE BenchCapability ScoreTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: capability scoreScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value53.562 % | 6.361 % | Vals AISource detailsData as of: 10/14/2026 |
Tax Agent BenchControversy & Precedence AnalysisTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value30 % | 10 % | Vals AISource detailsData as of: 10/12/2026 |
Terminal-Bench 2.1EasyTest detailsTest setup not documented as identicalNo direct winnerVersion: 2.1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: high, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value100 % | 83.333 % | Vals AISource detailsData as of: 09/28/2026 |
Terminal-Bench 4.0HardwareTest detailsTest setup not documented as identicalNo direct winnerVersion: 4.0Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value60 % | 0 % | Vals AISource detailsData as of: 10/13/2026 |
Terminal-Bench ScienceEarth SciencesTest detailsTest setup not documented as identicalNo direct winnerVersion: 0.1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Harness: Mini-SWE-agent, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Harness: Mini-SWE-agent, Output limit: 128,000 tokens | Higher measured value37.5 % | 0 % | Vals AISource detailsData as of: 10/14/2026 |
Vals IndexCode MigrationTest detailsTest setup not documented as identicalNo direct winnerVersion: 2.1Metric: benchmark scoreScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value68.901 % | 44.774 % | Vals AISource detailsData as of: 10/13/2026 |
BioMysteryBenchHuman-solvableTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Harness: Terminus 2, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Harness: Terminus 2, Output limit: 128,000 tokens | Higher measured value86.758 % | 69.406 % | Vals AISource detailsData as of: 10/12/2026 |
Code MigrationCOBOLTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | No direct winner70 % | No direct winner70 % | Vals AISource detailsData as of: 10/12/2026 |
CyberBench v1.1PoCTest detailsTest setup not documented as identicalNo direct winnerVersion: 1.1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 25 % | Higher measured value63.333 % | Vals AISource detailsData as of: 10/12/2026 |
EMBDataroomTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value84.873 % | 83.009 % | Vals AISource detailsData as of: 10/12/2026 |
Finance Agent (v2)All-PassTest detailsTest setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value48.111 % | 43.285 % | Vals AISource detailsData as of: 10/12/2026 |
Harvey's Legal Agent BenchmarkAntitrust Competition · Task fully resolvedTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: task resolution rateScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | No direct winner0 % | No direct winner0 % | Vals AISource detailsData as of: 10/12/2026 |
IOIIOI 2025Test detailsTest setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value100 % | 49.833 % | Vals AISource detailsData as of: 10/14/2026 |
Legal Research BenchAdministrative / Regulatory · Weighted partial creditTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: weighted partial-credit scoreScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 85.427 % | Higher measured value87.513 % | Vals AISource detailsData as of: 10/12/2026 |
LMArena Text, Style ControlChineseTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 5.5: Snapshot: claude-opus-5.5-high, Reasoning: high, Harness: Arena Text, style control GPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena Text, style controlClaude Opus 5.5: Arena rating from 704 published pairwise votes.GPT-5.6 Luna: Arena rating from 3,212 published pairwise votes. | Higher measured value1,574.432 95% confidence interval: ±22.751The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,476.812 95% confidence interval: ±11.28The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Vision, Style ControlDiagramTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 5.5: Snapshot: claude-opus-5.5-high, Reasoning: high, Harness: Arena Vision, style control GPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena Vision, style controlClaude Opus 5.5: Arena rating from 589 published pairwise votes.GPT-5.6 Luna: Arena rating from 2,783 published pairwise votes. | Higher measured value1,324.12 95% confidence interval: ±25.101The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,279.537 95% confidence interval: ±11.779The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/09/2026 |
ProgramBenchFully ResolvedTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: fully resolved rateScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value18.5 % | 0 % | Vals AISource detailsData as of: 10/12/2026 |
SAGECalculusTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 30,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 30,000 tokens | Higher measured value83.642 % | 64.506 % | Vals AISource detailsData as of: 10/08/2026 |
SRE BenchFully SolvedTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: fully solved rateScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value33.588 % | 1.527 % | Vals AISource detailsData as of: 10/14/2026 |
Tax Agent BenchControversy & Precedence AnalysisTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value66.871 % | 61.219 % | Vals AISource detailsData as of: 10/12/2026 |
Terminal-Bench 2.1HardTest detailsTest setup not documented as identicalNo direct winnerVersion: 2.1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: high, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value81.111 % | 70 % | Vals AISource detailsData as of: 09/28/2026 |
Terminal-Bench 4.0MediaTest detailsTest setup not documented as identicalNo direct winnerVersion: 4.0Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value75 % | 0 % | Vals AISource detailsData as of: 10/13/2026 |
Terminal-Bench ScienceEngineering SciencesTest detailsTest setup not documented as identicalNo direct winnerVersion: 0.1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Harness: Mini-SWE-agent, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Harness: Mini-SWE-agent, Output limit: 128,000 tokens | Higher measured value22.222 % | 0 % | Vals AISource detailsData as of: 10/14/2026 |
Vals IndexEMBTest detailsTest setup not documented as identicalNo direct winnerVersion: 2.1Metric: benchmark scoreScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value75.938 % | 67.116 % | Vals AISource detailsData as of: 10/13/2026 |
Code MigrationCode QualityTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: mean reviewer code-quality ratingScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value4.541 / 5 | 3.195 / 5 | Vals AISource detailsData as of: 10/12/2026 |
EMBDCFTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value70.139 % | 60.482 % | Vals AISource detailsData as of: 10/12/2026 |
Finance Agent (v2)ComparablesTest detailsTest setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterClaude Opus 5.5: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 45.756 % | Higher measured value48.285 % | Vals AISource detailsData as of: 10/12/2026 |
Key to the marks:better valuebetter, but not conclusivetie | |||
Our model tests
One SVG prompt and fixed output settings. Captures are shown only with 0 reported reasoning tokens or documented lack of reasoning controls. Identical test conditions do not make the models' internal compute identical.
Shared test round: 4ae5d8eeb9a9
Unavailable in this round
Unavailable in this round
A community classic for free-form SVG drawing.
Claude Opus 5.5
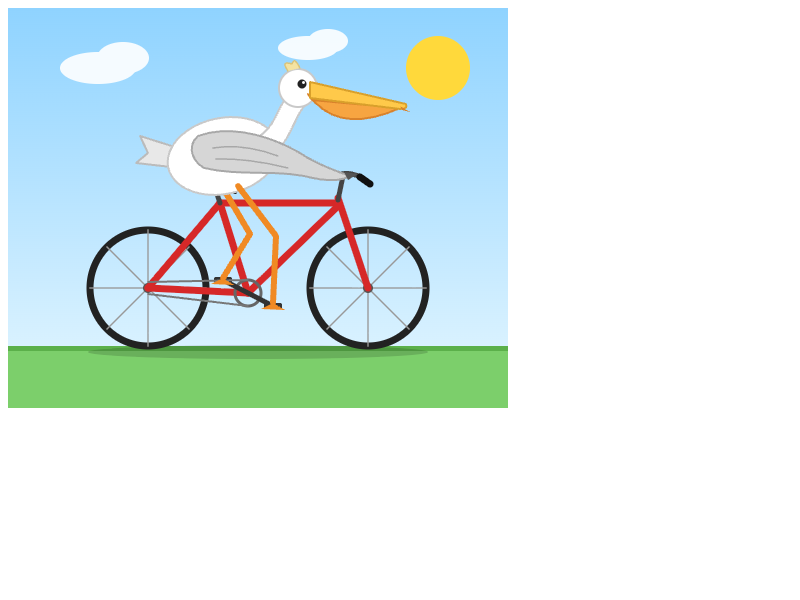
Reasoning (requested): high
Visually reviewed. This individual test does not establish overall model quality.
GPT-5.6 Luna
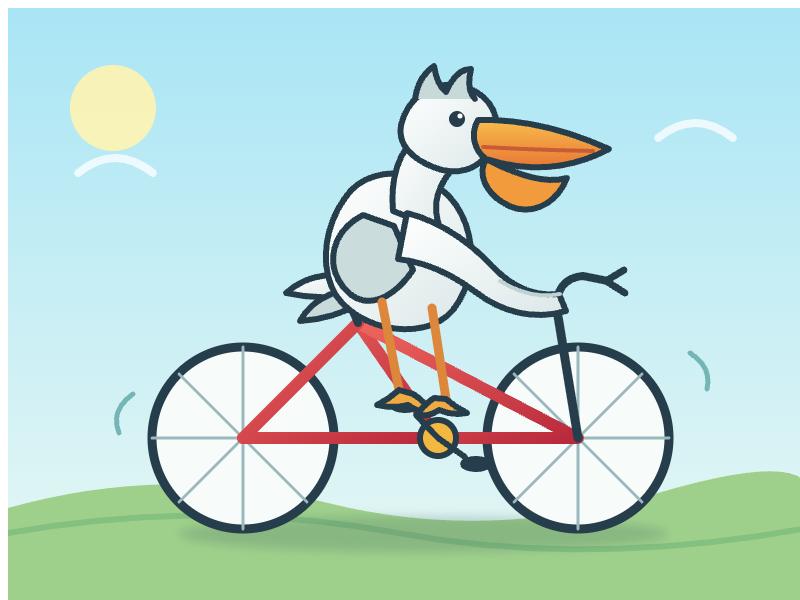
Reasoning (requested): high
Visually reviewed. This individual test does not establish overall model quality.
Generate an SVG of a pelican riding a bicycle
Token limit including reasoning: 8,192 tokens
Task origin (Simon Willison)How to read this comparison
Your workload, budget, and required context length matter most. A coding benchmark says little about visual understanding or agent performance.
The standard price table uses direct developer rates. The provider comparison labels OpenRouter endpoints, regions, and special tariffs separately.
Every result links to its measurement source and retrieval date. Labels distinguish vendor reports, official benchmark leaderboards, and independent evaluations. Disputed or archived results are excluded.
More matchups
Compare Claude Opus 5.5 and GPT-5.6 Luna with other leading models using the same data and benchmark logic.