DeepSeekLanguage modelActive

DeepSeek-V4.1-Flash

DeepSeek-V4.1-Flash is in the middle group: Rank 33 of 95 in the overall index. Through the API it is cheap.

IntelligenceRank 33 of 95 · middle group

100.0Overall indexhigher is better

29 of 37 test series come from Vals AI.

SpeedRank 8 of 99

125Tokens per secondhigher is better

PriceRank 14 of 102

Input $0.15 · Output $0.60

$0.26per 1M tokenslower is better

ContextRank 37 of 111

1Mtokens at once≈ 1,500 A4 pages

PopularityTop group about equally popular, 46 models

87out of 100new calculation

based on two data groups, mostly search, range 77 to 96

Compare with another model

Summary

It is cheap: $0.26 per 1M tokens (input and output blended); a typical model costs $1.50. At 125 tokens per second it writes faster than a typical model (65). Estimated without own results in: Reasoning and Knowledge.

New in DeepSeek-V4.1-Flash are native image input and asymmetric activation. DeepSeek describes 552 billion backbone parameters, 8 billion active parameters during prefill, 16 billion during decoding, and a 1,000,000-token context window. Reasoning effort can be adjusted more finely than in the original V4-Flash line.

On September 10, 2026, DeepSeek retired the old V4-Flash and V4-Flash-Vision-Exp routes and temporarily redirected them here. The deepseek-flash API name therefore describes the current service rather than the old weights by default.

Prices

Choose a price view

37 offers, prices in US dollars per 1M tokens, blended from 3 parts input and 1 part output.

Filter offers
ProviderInputOutputCache readBlended
DeepSeekOff-Peakdirect$0.15$0.60$0.003$0.26
BaiduFP8$0.0507$0.2028n/a$0.089
Alibaba$0.09$0.36n/a$0.16
WaferUS$0.051$0.567n/a$0.18
NovitaFP8$0.12$0.48n/a$0.21
River$0.12$0.48n/a$0.21
DeepInfraFP8$0.14$0.42n/a$0.21
RelaceFP4$0.12$0.50n/a$0.22
InferenceNetFP8$0.103$0.60n/a$0.23
InferenceNetUS$0.103$0.60n/a$0.23
AtlasCloudFP8$0.135$0.54n/a$0.24
Reka$0.12$0.64n/a$0.25
StreamLakeFP8$0.147$0.588n/a$0.26
CoreWeaveFP8$0.13$0.65n/a$0.26
Cloudflare$0.10$0.90n/a$0.30
WaferMXFP4$0.19$0.65n/a$0.31
CohereFP8$0.195$0.66n/a$0.31
DeepInfraFP8, Priority$0.21$0.63n/a$0.32
GMICloudFP8$0.18$0.72n/a$0.32
Mancer 2FP8$0.2125$0.75n/a$0.35
FireworksSpot$0.21$0.84n/a$0.37
OpenInferenceFP4$0.09$1.20n/a$0.37
DigitalOcean$0.225$0.90n/a$0.39
MakoraFP8$0.26$1.17n/a$0.49
CrusoeFP8$0.29$1.20n/a$0.52
BaseTen$0.30$1.20n/a$0.52
BaseTenUS$0.30$1.20n/a$0.52
Fireworks$0.30$1.20n/a$0.52
GoogleGlobal$0.30$1.20n/a$0.52
Modal$0.30$1.20n/a$0.52
ParasailFP8$0.30$1.20n/a$0.52
SiliconFlowFP8$0.30$1.20n/a$0.52
Together$0.30$1.20n/a$0.52
VeniceFP8$0.30$1.20n/a$0.52
FireworksUS$0.45$1.80n/a$0.79
ParasailFast$0.45$1.80n/a$0.79
VeniceUltrafast$3$12n/a$5.25

Cache prices come from the direct tariff; OpenRouter does not report them for the other providers. Direct price according to the developer, checked Oct 26, 2026. Provider prices via OpenRouter, as of Nov 18, 2026. Open the LLM price index

More price tiers and rules
API input (Off-Peak)
$0.15 per 1M tokensSource
API output (Off-Peak)
$0.6 per 1M tokensSource
Cache read (Off-Peak)
$0.003 per 1M tokensSource
Peak hours (UTC)
Mon, Tue, Wed, Thu, Fri, 01:00-04:00 UTC; Mon, Tue, Wed, Thu, Fri, 06:00-10:00 UTC. Off-peak rates apply at all other times.Source
API input (Peak)
$0.3 per 1M tokensSource
API output (Peak)
$1.2 per 1M tokensSource
Cache read (Peak)
$0.006 per 1M tokensSource

8 price changes since tracking began.

InputOutput

$0$0.50$1$1.50Sep 23, 2026Nov 18, 2026
Daily observed price in the LLM price index in US dollars per 1M tokens. The index uses a market price from several sources, which can differ from the developer's direct price.

No DeepSeek subscription includes this model. Through other providers from $1 a month (Command Code Go, with limited credits). 28 plans in Germany.

Filter plans
PlanMonthly list priceNote
Genspark Freefreewith limited credit
Command Code Go$1with limited credit
Token Plan Individual LiteAlibaba Cloud (Qwen)$6with limited credit
Poe Basic$4.99with limited credit
Command Code GOAT$10with limited credit
Token Plan Individual EssentialAlibaba Cloud (Qwen)$10with limited credit
Token Plan Individual StandardAlibaba Cloud (Qwen)$18with limited credit
Command Code Pro$20with limited credit
Token Plan Team Standard SeatAlibaba Cloud (Qwen)$20with limited credit, for teams, per seat
Warp Build$20with limited credit
Genspark Plus$24.99with limited credit
Poe Plus$19.99with limited credit
Genspark for Business Team$40with limited credit, for teams, per seat
Token Plan Individual ProAlibaba Cloud (Qwen)$43with limited credit
Warp Business$50with limited credit, for teams, per seat
Mindverse Studio Team€49for teams, per seat
Poe Pro$49.99with limited credit
Mindverse Studio Pro€59per seat
Token Plan Team Pro SeatAlibaba Cloud (Qwen)$75with limited credit, for teams, per seat
Command Code Max 10×$100with limited credit
Poe Advanced$99.99with limited credit
Command Code Max 20×$200with limited credit
Token Plan Team Max SeatAlibaba Cloud (Qwen)$200with limited credit, for teams, per seat
Warp Max$200
Genspark Pro$249.99with limited credit
Poe Max$249.99with limited credit
Genspark for Business Enterprisen/awith limited credit, for enterprises, per seat
Warp Enterprisen/afor enterprises

All plans in the AI subscription comparison

DeepSeek-V4.1-Flash benchmarks

Overall index (Gradually Meta-Score v6)

20 of 95 models

GPT-6 Astramax119.6
GPT-6.1 Solmax117.5
Muse Wondermax113.7
GPT-5.6 Solmax109.3
GPT-6 Solmax108.4
DeepSeek-V4.1-Flashmax100.0

DeepSeek-V4.1-Flash by reasoning effort

Points on the overall index scale. The value at max is DeepSeek-V4.1-Flash's overall index; the other efforts derive from the same Artificial Analysis test series. Missing efforts are never estimated.

  • none82.295% range 62.9 to 101.5
  • maxeffort of the overall index100.095% range 93.3 to 106.7
GPT-5.6 Terralow 79.9 · medium 85.6 · high 92.3 · xhigh 95.5 · max 100.9Mistral Large 4medium 96.8 · high 100.9

Source: Meta-Score v6; tiers: Artificial Analysis

Speed

20 of 99 models

Claude Haiku 5.5160tokens/s · Median across providers on OpenRouter from the readings of the last 24 hours (each covering the last 30 minutes), excluding time to first token · Retrieved 2026-11-18
Nemotron 3.5 Lightning147tokens/s · Median across providers on OpenRouter from the readings of the last 24 hours (each covering the last 30 minutes), excluding time to first token · Retrieved 2026-11-18
Inkling Small146tokens/s · Median across providers on OpenRouter from the readings of the last 24 hours (each covering the last 30 minutes), excluding time to first token · Retrieved 2026-11-18
Gemini 3.1 Flash-Lite141tokens/s · Median across providers on OpenRouter from the readings of the last 24 hours (each covering the last 30 minutes), excluding time to first token · Retrieved 2026-11-18
Gemini 3.5 Flash-Lite131tokens/s · Median across providers on OpenRouter from the readings of the last 24 hours (each covering the last 30 minutes), excluding time to first token · Retrieved 2026-11-18
Mistral Medium 3.5129tokens/s · Median across providers on OpenRouter from the readings of the last 24 hours (each covering the last 30 minutes), excluding time to first token · Retrieved 2026-11-18
DeepSeek V4.1 Flash 1017128tokens/s · Median across providers on OpenRouter from the readings of the last 24 hours (each covering the last 30 minutes), excluding time to first token · Retrieved 2026-11-18
DeepSeek-V4.1-Flash125tokens/s · Median across providers on OpenRouter from the readings of the last 24 hours (each covering the last 30 minutes), excluding time to first token · Retrieved 2026-11-18
Gemini 3.5 Flash125tokens/s · Median across providers on OpenRouter from the readings of the last 24 hours (each covering the last 30 minutes), excluding time to first token · Retrieved 2026-11-18
Gemini 3.6 Flash122tokens/s · Median across providers on OpenRouter from the readings of the last 24 hours (each covering the last 30 minutes), excluding time to first token · Retrieved 2026-11-18
MiniMax M2.7114tokens/s · Median across providers on OpenRouter from the readings of the last 24 hours (each covering the last 30 minutes), excluding time to first token · Retrieved 2026-11-18
GPT OSS 120B113tokens/s · Median across providers on OpenRouter from the readings of the last 24 hours (each covering the last 30 minutes), excluding time to first token · Retrieved 2026-11-18
Mistral Small 4109tokens/s · Median across providers on OpenRouter from the readings of the last 24 hours (each covering the last 30 minutes), excluding time to first token · Retrieved 2026-11-18
GPT-5.4 mini108tokens/s · Median across providers on OpenRouter from the readings of the last 24 hours (each covering the last 30 minutes), excluding time to first token · Retrieved 2026-11-18
Muse Spark 1.3107tokens/s · Median across providers on OpenRouter from the readings of the last 24 hours (each covering the last 30 minutes), excluding time to first token · Retrieved 2026-11-18
GPT-5 nano107tokens/s · Median across providers on OpenRouter from the readings of the last 24 hours (each covering the last 30 minutes), excluding time to first token · Retrieved 2026-11-18
Claude Sonnet 5.5106tokens/s · Median across providers on OpenRouter from the readings of the last 24 hours (each covering the last 30 minutes), excluding time to first token · Retrieved 2026-11-18
GPT OSS 20B105tokens/s · Median across providers on OpenRouter from the readings of the last 24 hours (each covering the last 30 minutes), excluding time to first token · Retrieved 2026-11-18
GPT-4.1 nano99tokens/s · Median across providers on OpenRouter from the readings of the last 24 hours (each covering the last 30 minutes), excluding time to first token · Retrieved 2026-11-18
Grok 4.20 Reasoning95tokens/s · Median across providers on OpenRouter from the readings of the last 24 hours (each covering the last 30 minutes), excluding time to first token · Retrieved 2026-11-18

Output tokens per second, measured by OpenRouter

Intelligence vs. price

most attractive area: stronger and cheaper than half of the models shownbest intelligence for the price

100120140$0.20$1$5$20MiniMax M3.1 Flash: 100.6, $0.26GPT-5.6 Terra: 100.9, $4.50Mistral Large 4: 100.9, $1.05GLM-5.3: 101.0, $2.15MiMo V2.6 Pro: 101.3, $0.54GPT-5.5: 101.4, $11.25Kimi K3: 101.5, $6Grok 4.6: 102.1, $3Claude Haiku 5.5: 102.7, $0.20Grok 4.7: 103.6, $3Qwen 3.8 Max 0902: 104.1, $2.48Muse Spark 1.3: 104.3, $2Gemini 3.8 Flash: 106.4, $1.50GPT-6.1 Terra: 106.5, $2DeepSeek V4.1 Flash 1017: 107.1, $0.26GPT-6 Sol: 108.4, $4GPT-5.6 Sol: 109.3, $8Muse Ember 1.0: 110.5, $0.20Kimi K3.1 Pro: 112.6, $4Claude Fable 5: 112.8, $20Muse Wonder: 113.7, $8Claude Opus 5: 117.3, $10GPT-6.1 Sol: 117.5, $4GPT-6 Astra: 119.6, $20Gemini 4 Argon: 121.2, $4Claude Sonnet 5.5: 121.9, $4Claude Fable 5.1: 124.1, $20Claude Opus 5.5: 125.7, $8Gemini 4 Carbon: 127.0, $4Claude Fable 5.2: 130.9, $16DeepSeek-V4.1-Flash: 100.0, $0.26Claude Fable 5.2Gemini 4 CarbonPrice per 1M tokens, blended (log scale)Overall index
More models in the chart (29)
  • Claude Opus 5.5125.7 · $8
  • Claude Fable 5.1124.1 · $20
  • Claude Sonnet 5.5121.9 · $4
  • Gemini 4 Argon121.2 · $4
  • GPT-6 Astra119.6 · $20
  • GPT-6.1 Sol117.5 · $4
  • Claude Opus 5117.3 · $10
  • Muse Wonder113.7 · $8
  • Claude Fable 5112.8 · $20
  • Kimi K3.1 Pro112.6 · $4
  • Muse Ember 1.0110.5 · $0.20
  • GPT-5.6 Sol109.3 · $8
  • GPT-6 Sol108.4 · $4
  • DeepSeek V4.1 Flash 1017107.1 · $0.26
  • GPT-6.1 Terra106.5 · $2
  • Gemini 3.8 Flash106.4 · $1.50
  • Muse Spark 1.3104.3 · $2
  • Qwen 3.8 Max 0902104.1 · $2.48
  • Grok 4.7103.6 · $3
  • Claude Haiku 5.5102.7 · $0.20
  • Grok 4.6102.1 · $3
  • Kimi K3101.5 · $6
  • GPT-5.5101.4 · $11.25
  • MiMo V2.6 Pro101.3 · $0.54
  • GLM-5.3101.0 · $2.15
  • Mistral Large 4100.9 · $1.05
  • GPT-5.6 Terra100.9 · $4.50
  • MiniMax M3.1 Flash100.6 · $0.26
  • DeepSeek-V4.1-Flash100.0 · $0.26

DeepSeek-V4.1-Flash by task area

Points, 100 = reference group average · higher is better

AgentsRank 18 of 102107.9
FinanceRank 29 of 112103.8
LegalRank 32 of 80101.9
GeneralRank 31 of 6999.3
CodingRank 34 of 11699.0
Mathematicstoo little data96.4
MultimodalRank 17 of 4795.0
HealthRank 31 of 7193.9

Light bar: too few results for a rank yet. No tests yet: Reasoning, Knowledge.

Best LLM by task:CodingMathAI agentsGeneral tasksFinanceLegalMedicineImage understanding

Text Arena

How people rate the answers in blind comparisons, Elo points with style control · higher is better

20 of 40 models

as of November 13, 2026 · Source: LMArena

WebDev Arena

How people rate generated websites and web apps in blind comparisons, Elo points · higher is better

20 of 43 models

as of November 16, 2026 · Source: LMArena

Terminal-Bench 4.0

Share of tasks the model solves as an agent in the terminal, in percent · higher is better

20 of 39 models

as of November 10, 2026 · Source: Vals AI

Vibe Code Bench

Share of apps the model builds correctly from a description, in percent · higher is better

20 of 52 models

as of November 10, 2026 · Source: Vals AI

Show all 910 published benchmark results

Page 1 of 77

Published benchmarks

General tasks

LMArena Text, Style Control

Math

Note (DeepSeek-V4.1-Flash): The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result.

GPT-6.1 Sol1,499.34 rating
DeepSeek-V4.1-Flash1,494.95 rating

higher is betterAs of November 13, 2026Scale: 0 rating - 1,499.34 rating

Source: LMArena
gradually.ai
Methodology and context
Comparison cohort
lmarena-text-style-control:2026-11-11:math
Metric
style-controlled Bradley-Terry rating
Scale
No upper bound is documented. The chart spans the recorded values and zero.
Participants
2
Methodology and context
Arena rating from 691 published pairwise votes.. Source model ID: lmarena/DeepSeek-V4.1-Flash-20260910 (Max). Source model name: DeepSeek-V4.1-Flash. Provider reported by source: DeepSeek. Model snapshot: DeepSeek-V4.1-Flash-20260910 (Max). Evaluator: LMArena. Dataset type: public-crowdsourced-preferences. Leaderboard date: 2026-11-11. Harness: Arena Text, style control. Reasoning effort: max. Source ID: lmarena. Evidence capture ID: lmarena-4ca698d9bb5780db156459679d5c7e6dff4edbd3-7776030d6555. Source payload hash: 7776030d6555dc9a24385787c2f0e27cdeb6d9530b1cfb8d3b2e553c04d60f2f. Parser version: lmarena-dataset-v1. Imported at: 2026-11-13
Source: LMArena

Access to Justice Benchmark

Overall

DeepSeek-V4.1-Flash72.86%

higher is betterAs of November 10, 2026Scale: 0% - 100%

Source: Vals AI
gradually.ai
Methodology and context
Comparison cohort
vals-a2j:1:overall
Metric
accuracy
Scale
0-100
Participants
2
Methodology and context
Source model ID: deepseek/deepseek-v4.1-flash. Source model name: DeepSeek-V4.1-Flash. Provider reported by source: DeepSeek. Evaluator: Vals AI. Dataset type: private. Leaderboard date: 2026-11-10. Reasoning effort: max. Temperature: 1. Top P: 1. Maximum output tokens: 384000. Latency in seconds: 559.654. Standard error: 0.716. Cost per task in USD: 0.108645. Source ID: vals-ai. Evidence capture ID: vals-a2j-2026-11-10-4dfe72d80b11. Source payload hash: 4dfe72d80b11c04636d5896b782aef36d0f143e51101a31154739fa2d3ff00eb. Parser version: vals-astro-v4. Imported at: 2026-11-10
Source: Vals AI

Coding

Code Migration v1.1

Sub-taskDeepSeek-V4.1-Flash (This model)DeepSeek V4.1 Flash 1017
CLI47.75%59.2% (best value in this row)
COBOL92.5% (best value in this row)92.5% (best value in this row)
Code Quality3.68% (best value in this row)3.48%
Overall58.94%67.52% (best value in this row)

higher is betterAs of November 7, 2026Source: Vals AIbars scaled within each row, not across rows

Methodology and context
Metric
accuracy

Recorded measurement details

LMArena Text, Style Control: Math (Show measurement, test conditions, and source)
Source value
1,494.9491805249
Metric
style-controlled Bradley-Terry rating
Unit
rating
Benchmark version
style-control-v1
Category
general
Task
math
Task label
Math
Direction
Higher is better
Comparison cohort
lmarena-text-style-control:2026-11-11:math
Confidence interval
21.902243
Source type
official-leaderboard
Evaluator
LMArena
Status
active
Retrieved at
2026-11-13
Methodology
Arena rating from 691 published pairwise votes.. Source model ID: lmarena/DeepSeek-V4.1-Flash-20260910 (Max). Source model name: DeepSeek-V4.1-Flash. Provider reported by source: DeepSeek. Model snapshot: DeepSeek-V4.1-Flash-20260910 (Max). Evaluator: LMArena. Dataset type: public-crowdsourced-preferences. Leaderboard date: 2026-11-11. Harness: Arena Text, style control. Reasoning effort: max. Source ID: lmarena. Evidence capture ID: lmarena-4ca698d9bb5780db156459679d5c7e6dff4edbd3-7776030d6555. Source payload hash: 7776030d6555dc9a24385787c2f0e27cdeb6d9530b1cfb8d3b2e553c04d60f2f. Parser version: lmarena-dataset-v1. Imported at: 2026-11-13
Comparison methodology
Arena rating from 691 published pairwise votes.. Harness: Arena Text, style control. Reasoning effort: max
Context
The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result.
Source LMArena
Access to Justice Benchmark: Overall (Show measurement, test conditions, and source)
Source value
72.862
Metric
accuracy
Unit
%
Benchmark version
1
Category
general
Task
overall
Task label
Overall
Direction
Higher is better
Comparison cohort
vals-a2j:1:overall
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-10
Methodology
Source model ID: deepseek/deepseek-v4.1-flash. Source model name: DeepSeek-V4.1-Flash. Provider reported by source: DeepSeek. Evaluator: Vals AI. Dataset type: private. Leaderboard date: 2026-11-10. Reasoning effort: max. Temperature: 1. Top P: 1. Maximum output tokens: 384000. Latency in seconds: 559.654. Standard error: 0.716. Cost per task in USD: 0.108645. Source ID: vals-ai. Evidence capture ID: vals-a2j-2026-11-10-4dfe72d80b11. Source payload hash: 4dfe72d80b11c04636d5896b782aef36d0f143e51101a31154739fa2d3ff00eb. Parser version: vals-astro-v4. Imported at: 2026-11-10
Source Vals AI
Code Migration v1.1: CLI (Show measurement, test conditions, and source)
Source value
47.747
Metric
accuracy
Unit
%
Benchmark version
1.1
Category
coding
Task
cli
Task label
CLI
Direction
Higher is better
Comparison cohort
vals-code-migration-v1-1:1.1:cli
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-07
Methodology
Source model ID: deepseek/deepseek-v4.1-flash. Source model name: DeepSeek-V4.1-Flash. Provider reported by source: DeepSeek. Evaluator: Vals AI. Dataset type: private. Leaderboard date: 2026-10-30. Reasoning effort: max. Temperature: 1. Top P: 1. Maximum output tokens: 384000. Latency in seconds: 7584.512. Standard error: 2.674. Cost per task in USD: 1.270159. Source ID: vals-ai. Evidence capture ID: vals-code-migration-v1-1-2026-11-07-4085f8f7e916. Source payload hash: 4085f8f7e916ea8f5f458829ef9b624e3f87c68dc0e79642e03f1c9b679b61c0. Parser version: vals-astro-v4. Imported at: 2026-11-07
Source Vals AI
Code Migration v1.1: COBOL (Show measurement, test conditions, and source)
Source value
92.5
Metric
accuracy
Unit
%
Benchmark version
1.1
Category
coding
Task
cobol
Task label
COBOL
Direction
Higher is better
Comparison cohort
vals-code-migration-v1-1:1.1:cobol
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-07
Methodology
Source model ID: deepseek/deepseek-v4.1-flash. Source model name: DeepSeek-V4.1-Flash. Provider reported by source: DeepSeek. Evaluator: Vals AI. Dataset type: private. Leaderboard date: 2026-10-30. Reasoning effort: max. Temperature: 1. Top P: 1. Maximum output tokens: 384000. Latency in seconds: 4505.811. Standard error: 6.962. Cost per task in USD: 0.54491. Source ID: vals-ai. Evidence capture ID: vals-code-migration-v1-1-2026-11-07-4085f8f7e916. Source payload hash: 4085f8f7e916ea8f5f458829ef9b624e3f87c68dc0e79642e03f1c9b679b61c0. Parser version: vals-astro-v4. Imported at: 2026-11-07
Source Vals AI
Code Migration v1.1: Code Quality (Show measurement, test conditions, and source)
Source value
3.675
Metric
accuracy
Unit
%
Benchmark version
1.1
Category
coding
Task
code_quality
Task label
Code Quality
Direction
Higher is better
Comparison cohort
vals-code-migration-v1-1:1.1:code_quality
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-07
Methodology
Source model ID: deepseek/deepseek-v4.1-flash. Source model name: DeepSeek-V4.1-Flash. Provider reported by source: DeepSeek. Evaluator: Vals AI. Dataset type: private. Leaderboard date: 2026-10-30. Reasoning effort: max. Temperature: 1. Top P: 1. Maximum output tokens: 384000. Latency in seconds: 6814.837. Standard error: 0.036. Cost per task in USD: 1.088847. Source ID: vals-ai. Evidence capture ID: vals-code-migration-v1-1-2026-11-07-4085f8f7e916. Source payload hash: 4085f8f7e916ea8f5f458829ef9b624e3f87c68dc0e79642e03f1c9b679b61c0. Parser version: vals-astro-v4. Imported at: 2026-11-07
Source Vals AI
Code Migration v1.1: Overall (Show measurement, test conditions, and source)
Source value
58.936
Metric
accuracy
Unit
%
Benchmark version
1.1
Category
coding
Task
overall
Task label
Overall
Direction
Higher is better
Comparison cohort
vals-code-migration-v1-1:1.1:overall
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-07
Methodology
Source model ID: deepseek/deepseek-v4.1-flash. Source model name: DeepSeek-V4.1-Flash. Provider reported by source: DeepSeek. Evaluator: Vals AI. Dataset type: private. Leaderboard date: 2026-10-30. Reasoning effort: max. Temperature: 1. Top P: 1. Maximum output tokens: 384000. Latency in seconds: 6814.837. Standard error: 2.656. Cost per task in USD: 1.088847. Source ID: vals-ai. Evidence capture ID: vals-code-migration-v1-1-2026-11-07-4085f8f7e916. Source payload hash: 4085f8f7e916ea8f5f458829ef9b624e3f87c68dc0e79642e03f1c9b679b61c0. Parser version: vals-astro-v4. Imported at: 2026-11-07
Source Vals AI

Page 1 of 77

DeepSeek-V4.1-Flash in our own test

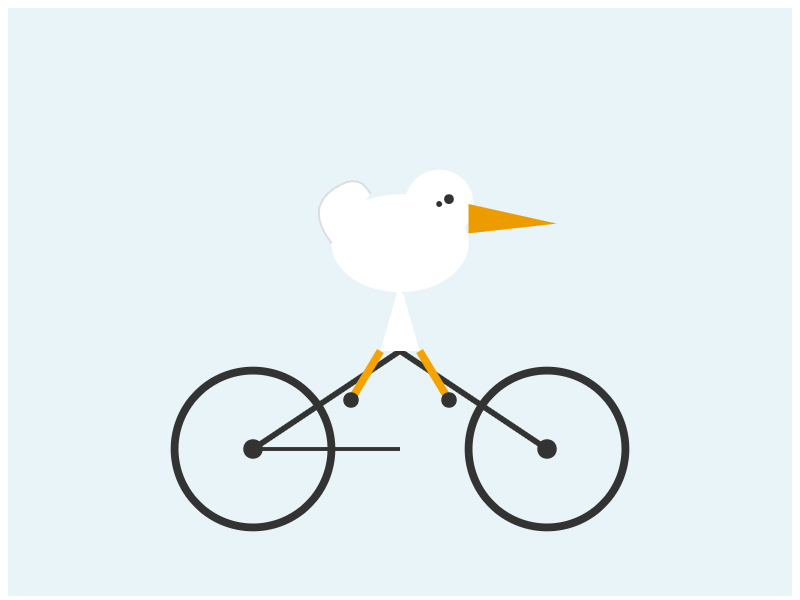
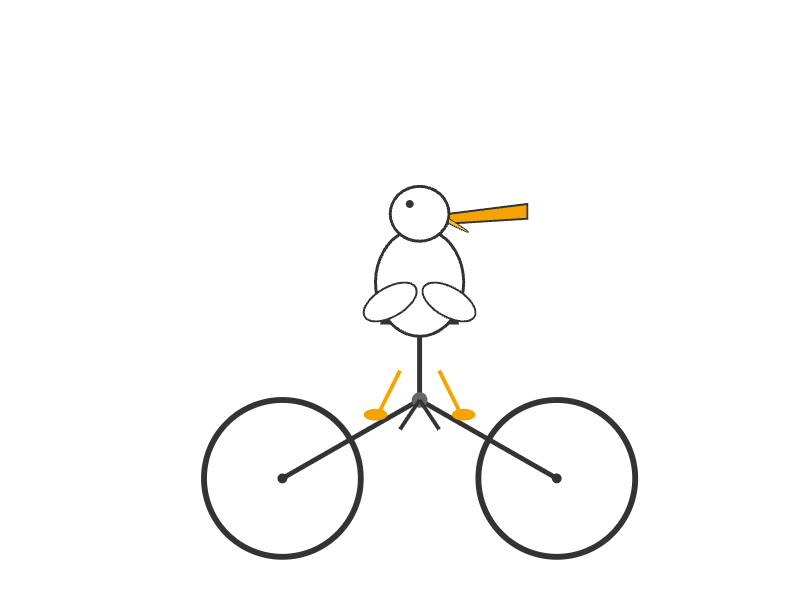
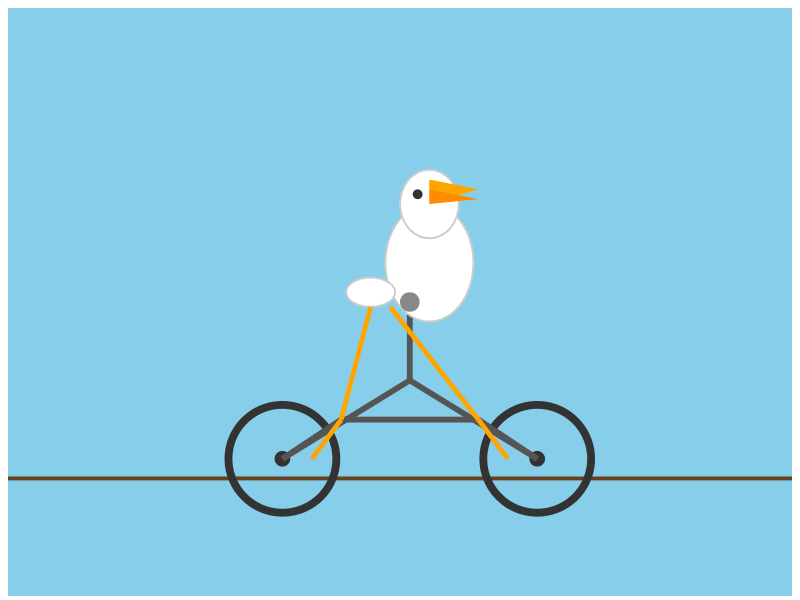
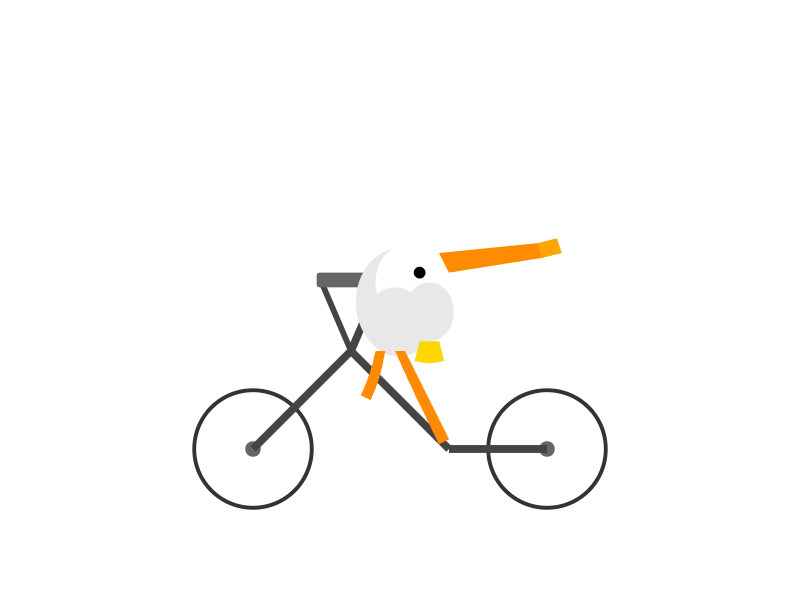
SVG short test

One SVG task with the same fixed settings for every model, without hidden thinking.

DeepSeek-V4.1-Flash

DeepSeek-V4.1-Flash: SVG short test

Prompt

Return only one standalone SVG of a pelican riding a bicycle. Use viewBox="0 0 800 600", simple shapes, two clearly visible wheels and a recognizable pelican with a long beak. At most 30 SVG elements and 1800 characters. No Markdown, explanations, comments, scripts, animation, CSS or external resources.

Oct 14, 2026 · $0.0001

Test details
Test run
Oct 14, 2026
Provider
decart/fp4
API model
deepseek/deepseek-v4.1-flash
Output
590 tokens
Reasoning
API reports 0 reasoning tokens
Cost of the attempt
$0.0001
Test round
43b8c5c46830
Earlier tests

The response reached the token limit. No complete recording is available.

Pelican on a bicycle

Prompt

Generate an SVG of a pelican riding a bicycle

Oct 5, 2026 · 26 s · $0.0049

Not yet visually reviewed. A successful recording does not confirm correct physics or full compliance with the prompt.

Test details
Run date
Oct 5, 2026
API provider
openrouter
Requested API model
deepseek/deepseek-v4.1-flash
Reasoning setting
high
Token limit including reasoning
8,192 tokens
Output tokens
8,191 tokens
Cost of the attempt
$0.0049
Response time
25.8 s
API model reported in response
deepseek/deepseek-v4.1-flash
Pinned endpoint
DeepSeek | deepseek/deepseek-v4.1-flash-20260910
Temperature
Provider default
Test protocol
community-visual-tests-v1
Technical checks
Failed

Earlier attempts (2)

  • Oct 2, 2026API request failedReasoning setting: high
  • Oct 1, 2026API request failedReasoning setting: high
Task origin: Simon Willison

Same prompt, four models

From the SVG short test: a pelican riding a bicycle, the same fixed settings without reasoning for every model, one attempt per model. An impression, not a score.

Popularity compared

How often the model is searched for, used and mentioned, compared with every model of its category.

Popularity index

The 100 most popular models of this category, 0 to 100, higher is more popular

20 of 100 models

As of November 2026 · Source: gradually.ai popularity index

Over time

Weekly values from October 18, 2026 to November 18, 2026

DeepSeek-V4.1-FlashGemini 3.8 Flash 88GLM-5.3 87Claude Opus 5.5 87Kimi K3 85

Method changes in the timeline, a jump at these points is no market event:

  1. 1November 1, 2026: Value only with search or usage data, 30-day attention
  2. 2November 1, 2026: Method version 4 (common scale, shrinkage)
  3. 3November 9, 2026: New topics measurement V20 (daily quorum, short forms)

What is gaining popularity right now, across models, vendors, harnesses and AI subscriptions, is collected in All AI trends.

DeepSeek-V4.1-Flash compared

The most popular comparisons

  1. 1Claude Sonnet 5.5 vs. DeepSeek-V4.1-Flash
  2. 2Gemini 3.8 Flash vs. DeepSeek-V4.1-Flash
  3. 3Muse Spark 1.3 vs. DeepSeek-V4.1-Flash
  4. 4GPT-6 Luna vs. DeepSeek-V4.1-Flash
  5. 5GPT-6 Sol vs. DeepSeek-V4.1-Flash
  6. 6Claude Opus 5.5 vs. DeepSeek-V4.1-Flash
  7. 7Claude Haiku 5.5 vs. DeepSeek-V4.1-Flash
  8. 8Grok 4.7 vs. DeepSeek-V4.1-Flash
  9. 9GPT-6 Astra vs. DeepSeek-V4.1-Flash
Show all 55 comparisons
  1. 10Claude Sonnet 5 vs. DeepSeek-V4.1-Flash
  2. 11GPT-6.1 Sol vs. DeepSeek-V4.1-Flash
  3. 12DeepSeek-V4.1-Flash vs. Qwen 3.8 Max 0902
  4. 13DeepSeek-V4.1-Flash vs. GLM-5.2
  5. 14Claude Opus 5 vs. DeepSeek-V4.1-Flash
  6. 15Claude Opus 4.6 vs. DeepSeek-V4.1-Flash
  7. 16DeepSeek-V4-Pro vs. DeepSeek-V4.1-Flash
  8. 17GPT-5.6 Terra vs. DeepSeek-V4.1-Flash
  9. 18DeepSeek-V4.1-Flash vs. MiMo-V2.5-Pro
  10. 19DeepSeek-V4.1-Flash vs. GLM-5.3-Flash
  11. 20DeepSeek-V4.1-Flash vs. GLM-5.3
  12. 21Claude Sonnet 4.6 vs. DeepSeek-V4.1-Flash
  13. 22GPT-5.6 Luna vs. DeepSeek-V4.1-Flash
  14. 23DeepSeek-V4.1-Flash vs. Qwen 3.8 27B
  15. 24GPT-6.1 Terra vs. DeepSeek-V4.1-Flash
  16. 25DeepSeek-V4.1-Flash vs. Mistral Large 4
  17. 26DeepSeek-V4.1-Flash vs. MiMo-V2.5
  18. 27DeepSeek-V4.1-Flash vs. Kimi K3.1 Pro
  19. 28Claude Fable 5 vs. DeepSeek-V4.1-Flash
  20. 29DeepSeek-V4.1-Flash vs. Kimi K3
  21. 30GPT-5.6 Sol vs. DeepSeek-V4.1-Flash
  22. 31Gemini 3.6 Flash vs. DeepSeek-V4.1-Flash
  23. 32Gemini 3.1 Pro Preview vs. DeepSeek-V4.1-Flash
  24. 33Gemini 3.5 Flash-Lite vs. DeepSeek-V4.1-Flash
  25. 34Claude Opus 4.8 vs. DeepSeek-V4.1-Flash
  26. 35Gemini 4 Carbon vs. DeepSeek-V4.1-Flash
  27. 36DeepSeek-V4.1-Flash vs. Mistral Medium 3.5
  28. 37Claude Haiku 4.5 vs. DeepSeek-V4.1-Flash
  29. 38Claude Sonnet 4.5 vs. DeepSeek-V4.1-Flash
  30. 39Grok 4.6 vs. DeepSeek-V4.1-Flash
  31. 40DeepSeek-V4.1-Flash vs. Mistral Large 3
  32. 41Claude Opus 4.5 vs. DeepSeek-V4.1-Flash
  33. 42Gemini 3.5 Flash vs. DeepSeek-V4.1-Flash
  34. 43Claude Opus 4.7 vs. DeepSeek-V4.1-Flash
  35. 44Muse Wonder vs. DeepSeek-V4.1-Flash
  36. 45Gemini 4 Argon vs. DeepSeek-V4.1-Flash
  37. 46Claude Fable 5.1 vs. DeepSeek-V4.1-Flash
  38. 47GPT-5.5 vs. DeepSeek-V4.1-Flash
  39. 48GPT-5.4 vs. DeepSeek-V4.1-Flash
  40. 49GPT-5.4 mini vs. DeepSeek-V4.1-Flash
  41. 50Gemini 3.7 Flash vs. DeepSeek-V4.1-Flash
  42. 51Muse Wonder Full vs. DeepSeek-V4.1-Flash
  43. 52Grok 4.5 vs. DeepSeek-V4.1-Flash
  44. 53Grok 4.3 vs. DeepSeek-V4.1-Flash
  45. 54DeepSeek-V4.1-Flash vs. Kimi K2.6
  46. 55DeepSeek-V4.1-Flash vs. GLM-5.1

Alternatives to DeepSeek-V4.1-Flash

Stronger, cheaper, open and faster models compared with DeepSeek-V4.1-Flash. Every card names the values it rests on, and a model appears only once.

DeepSeek-V4.1-Flash ranks 33 of 95 in the overall index and costs $0.26 per million tokens.

  • Stronger, not much pricier

    Muse Ember 1.0

    Ahead in the overall index (110.5 vs. 100.0) and cheaper ($0.20 vs. $0.26 per million tokens).

    Compared with DeepSeek-V4.1-Flash: 10.5 points more in the overall index, 76 % of the price.

    Overall index
    110.5
    Price (3:1)
    $0.20
    Speed
    n/a

    Rank 14 · Middle group

    Open the profile

  • Similar strength, cheaper

    MiMo V2.6 Flash

    Level in the overall index (97.3 vs. 100.0) but cheaper: $0.18 instead of $0.26 per million tokens.

    Compared with DeepSeek-V4.1-Flash: 2.7 points fewer in the overall index, 67 % of the price, 67 % slower.

    Overall index
    97.3
    Price (3:1)
    $0.18
    Speed
    42

    Rank 36 · Middle group

    Open the profile

  • With open weights

    Kimi K3.1 Pro

    The best model with open weights, stronger: 112.6 vs. 100.0 in the overall index.

    Compared with DeepSeek-V4.1-Flash: 12.5 points more in the overall index, 15.2 times the price, 52 % slower.

    Overall index
    112.6
    Price (3:1)
    $4
    Speed
    61

    Rank 13 · Middle group

    Head to head: DeepSeek-V4.1-Flash vs. Kimi K3.1 ProOpen the profile

  • Similar strength, faster

    Claude Haiku 5.5

    Level in the overall index (102.7 vs. 100.0) and faster: 160 instead of 125 tokens per second.

    Compared with DeepSeek-V4.1-Flash: 2.7 points more in the overall index, 76 % of the price, 28 % faster.

    Overall index
    102.7
    Price (3:1)
    $0.20
    Speed
    160

    Rank 24 · Middle group

    Head to head: DeepSeek-V4.1-Flash vs. Claude Haiku 5.5Open the profile

  • The successor

    DeepSeek V4.1 Flash 1017

    The successor to DeepSeek-V4.1-Flash. Overall index 107.1 vs. 100.0.

    Compared with DeepSeek-V4.1-Flash: 7.1 points more in the overall index, the same price, 2 % faster.

    Overall index
    107.1
    Price (3:1)
    $0.26
    Speed
    128

    Rank 18 · Middle group

    Head to head: DeepSeek-V4.1-Flash vs. DeepSeek V4.1 Flash 1017Open the profile

Where the alternatives lead DeepSeek-V4.1-Flash

Only areas with a clear lead in the benchmarks. Areas without a clear difference are not listed.

  • Muse Ember 1.0

    Clearly ahead in
    Coding, Finance, Legal

    Clearly behind in
    none

  • Kimi K3.1 Pro

    Clearly ahead in
    Coding, Legal

    Clearly behind in
    none

  • Claude Haiku 5.5

    Clearly ahead in
    Coding, Health

    Clearly behind in
    none

  • DeepSeek V4.1 Flash 1017

    Clearly ahead in
    Coding, Legal

    Clearly behind in
    none

The models around DeepSeek-V4.1-Flash

The nearest generally available models by overall index, with rank, price and speed. Models with limited access and retired models are left out.

  • Overall index
    101.5
    Price (3:1)
    $6
    Speed
    54
  • Overall index
    101.4
    Price (3:1)
    $11.25
    Speed
    60
  • Overall index
    101.3
    Price (3:1)
    $0.54
    Speed
    38
  • Overall index
    101.0
    Price (3:1)
    $2.15
    Speed
    78
  • Overall index
    100.9
    Price (3:1)
    $1.05
    Speed
    52
  • Overall index
    100.9
    Price (3:1)
    $4.50
    Speed
    73
  • Overall index
    100.6
    Price (3:1)
    $0.26
    Speed
    n/a
  • 33DeepSeek-V4.1-Flash(this model)
    Overall index
    100.0
    Price (3:1)
    $0.26
    Speed
    125

Price in dollars per million tokens, mixed from 3 parts input and 1 part output. Speed in tokens per second.

Cost for your load

1,000 requests with 2,000 input and 500 output tokens cost $0.6000 with DeepSeek-V4.1-Flash. Enter your own load in the cost calculator

Compare DeepSeek-V4.1-Flash with the models next to it in the ranking

All specifications

Architecture

Parameters
552B
Source: Parameters
Architecture
Causal Encoder-Decoder MoE (20-layer encoder, 20-layer decoder); 8B active parameters per token on prefill, 16B on decode
Source: Architecture
Training tokens
45T
Source: Training tokens

Input and output

Context window
1,000,000 tokens
Source: Context window
Input
Text, Image
Source: Input
Output
Text
Source: Output
Reasoning effort
1-100
Source: Reasoning effort
Tool calling
Yes
Source: Tool calling

Watermarking and provenance

AI watermarking refers to invisible signals embedded in the output. Visible marks and provenance metadata are listed separately. Unknown means there is insufficient evidence for that particular field.

AI watermarking
Unknown
no source
Watermarking technique
Not known
no source

Licence and access

Weights
Open weights
Source: Weights
Access
API, Local
Source: Access
Shutdown
None announced
no source
License
MIT
Source: License
Release
Sep 10, 2026
Source: Release

API

API model ID
deepseek-flash
Source: API model ID

Further details

Notes
552B total, 8B active during input prefill and 16B during output decoding, 1M context, multimodal and MIT-licensed
Source: Notes
Active input parameters
8 B
Source: Active input parameters
Active output parameters
16 B
Source: Active output parameters

Frequently asked questions about DeepSeek-V4.1-Flash

How good is DeepSeek-V4.1-Flash in benchmarks?

Decent: Rank 33 of 95 in the overall index.

Overall index (Gradually Meta-Score v6) from 37 benchmark results · data through Nov 16, 2026

IntelligenceOverall index in points, 100 = reference group average · higher is better
Mistral Large 4100.9
GPT-5.6 Terra100.9
MiniMax M3.1 Flash100.6
DeepSeek-V4.1-FlashRank 33100.0
Claude Opus 4.899.4
Muse Spark Open97.6
MiMo V2.6 Flash97.3

What is the Overall index (Gradually Meta-Score v6)?

A point value that combines many independent benchmarks into one number. 100 points is the average of a fixed group of 29 models, and a model 15 points ahead does better in roughly three of four benchmark comparisons. DeepSeek-V4.1-Flash scores 100.0 points, which is rank 33 of 95.

Own analysis by gradually.ai, method benchmark-meta-score-v6 · for DeepSeek-V4.1-Flash from 37 test series

How much does DeepSeek-V4.1-Flash cost?

Through the API $0.15 per 1M input tokens and $0.60 output. That is cheap.

Prices from Nov 18, 2026

Output price since tracking beganDollars per 1M tokens · lower is better

Sep 23, 2026Nov 18, 2026

First price on Sep 23, 2026: $1. Since Nov 16, 2026: $0.90.

How large is the context window of DeepSeek-V4.1-Flash?

1 M tokens. That is how much text DeepSeek-V4.1-Flash reads at once, about 1,500 A4 pages.

Page count as a rule of thumb from Artificial Analysis

Context windowTokens the model reads at once · higher is better
GPT-5.6 Terra1.05M
Muse Spark Open1.05M
Mistral Large 41.05M
DeepSeek-V4.1-FlashRank 37 of 1111M
MiniMax M3.1 Flash1M
Claude Opus 4.81M
GLM-5.31M

How fast is DeepSeek-V4.1-Flash?

125 tokens per second. That is faster than a typical model at 65.

Measured by OpenRouter on Nov 18, 2026. Median across providers on OpenRouter from the readings of the last 24 hours (each covering the last 30 minutes), excluding time to first token.

SpeedTokens per second · higher is better
DeepSeek-V4.1-FlashRank 8 of 99125
GLM-5.378
GPT-5.6 Terra73
Claude Opus 4.870
Step 5 Preview65
Mistral Large 452
MiMo V2.6 Flash42

Can I run DeepSeek-V4.1-Flash locally?

Yes, the weights are open. With 552B parameters it needs a lot of memory, more a server than a laptop.

Stated by DeepSeek

Open weights
yes
License
MIT
Parameters
552B
active per token
n/a

Where can I use DeepSeek-V4.1-Flash?

Not in a DeepSeek subscription. Including other providers that makes 28 plans in Germany, plus the API.

Subscription comparison, prices in Germany incl. VAT

At DeepSeek

No DeepSeek subscription includes this model.

Through other providers

28 plans from 6 providers, from $1 a month (Command Code Go), with limited credits.

Through the API

$0.15 input, $0.60 output per 1M tokens according to the provider; the price index has listed it at $0.225 and $0.90 since Nov 16, 2026.

Is DeepSeek-V4.1-Flash better than DeepSeek-V4-Flash?

There is too little data for an overall comparison. It does not clearly lead in any area.

DeepSeek-V4-Flash as predecessor according to DeepSeek-V4.1-Flash release, checked Sep 23, 2026

IntelligenceOverall index, 100 points = average · higher is better
100.0

DeepSeek-V4.1-Flash

Rank 33

n/a

DeepSeek-V4-Flash

not ranked yet

SpeedTokens per second · higher is better
125

DeepSeek-V4.1-Flash

fast

81

DeepSeek-V4-Flash

fairly fast

PriceDollars per 1M tokens, 3 parts input to 1 part output · lower is better
$0.26

DeepSeek-V4.1-Flash

1.5 times the price

$0.18

DeepSeek-V4-Flash

cheaper

DeepSeek-V4.1-FlashDeepSeek-V4-Flash100 points = average, higher is better
Codingonly DeepSeek-V4.1-Flash has a scoreDeepSeek-V4.1-Flash: 99.0DeepSeek-V4-Flash: not enough data
Mathematicsonly DeepSeek-V4.1-Flash has a scoreDeepSeek-V4.1-Flash: 96.4DeepSeek-V4-Flash: not enough data
Agentstoo little dataDeepSeek-V4.1-Flash: 107.9DeepSeek-V4-Flash: 91.9
Generalonly DeepSeek-V4.1-Flash has a scoreDeepSeek-V4.1-Flash: 99.3DeepSeek-V4-Flash: not enough data
Financeonly DeepSeek-V4.1-Flash has a scoreDeepSeek-V4.1-Flash: 103.8DeepSeek-V4-Flash: not enough data
Legalonly DeepSeek-V4.1-Flash has a scoreDeepSeek-V4.1-Flash: 101.9DeepSeek-V4-Flash: not enough data
Healthonly DeepSeek-V4.1-Flash has a scoreDeepSeek-V4.1-Flash: 93.9DeepSeek-V4-Flash: not enough data
Multimodalonly DeepSeek-V4.1-Flash has a scoreDeepSeek-V4.1-Flash: 95.0DeepSeek-V4-Flash: not enough data

Sources and data date

Show all 108 sources

Benchmark sources at a glance

Which independent evaluators tested this model. This is coverage, not a quality ranking.

EvaluatorTest seriesComposite indicesRecorded active measurements
Artificial Analysis508
Vals AI303215
LMArena3042
LiveBench0038
ARC Prize0016
Scale AI Evals001

Without vendor claims and historical or disputed results; those stay labelled in the single values. 55 measurements are not yet assigned to a test series.

TypeEvidence and data date
Speed

OpenRouter. Median across providers on OpenRouter from the readings of the last 24 hours (each covering the last 30 minutes), excluding time to first token. Retrieved November 18, 2026.

Price

Off-peak API prices. Higher rates apply during the provider's peak hours. All rates and the UTC schedule are listed under Costs.

Input

Documented modalities. Retrieved September 23, 2026.

Output

Documented modalities. Retrieved September 23, 2026.

Research statusResearch date September 24, 2026. 40 source URLs checked. This documents the inspected sources, not an exhaustive inventory of every publication.
Unresolved

active-parameters-billions

Original wording

The card publishes two values (8B per token on prefill, 16B on decode); no single active-parameter count applies.

Not published

knowledge-cutoff

Original wording

Neither the model card nor the release post states a knowledge cutoff.

Unresolved

NL2Repo-Bench score discrepancy

Note

The existing model-card record reports 64.0, while a separate official release note reports 65.4. The new 65.4 observation is marked disputed; evaluation date, score unit, and setup for that value are not disclosed.

Not published

reasoning effort and pass@k

Note

The cited result does not report reasoning effort or pass@k; exact task date and serving/checkpoint details are recorded in the benchmark configuration.

Not published

DeepSeek V4.1 Flash vendor benchmark run metadata

Note

The model card states reasoning_effort=100, temperature=1.0, and top_p=0.95 for Instruct results, but does not disclose task dates, row-specific units, or all harness/settings.

Additional sourceArtificial Analysis (retrieved October 19, 2026; November 2, 2026; November 7, 2026)1234
Additional sourceArtificial Analysis (retrieved October 19, 2026)12345678910
Additional sourceArtificial Analysis (retrieved October 19, 2026; November 2, 2026)
Additional sourceArtificial Analysis (retrieved October 19, 2026; October 29, 2026; November 2, 2026; November 7, 2026)
Additional sourceLMArena (retrieved October 30, 2026)123
Additional sourceLMArena (retrieved November 13, 2026)12
Additional sourceLMArena (retrieved October 28, 2026)12
Additional sourceLMArena (retrieved November 9, 2026)123
Additional sourceLMArena (retrieved November 10, 2026)123
Additional sourceLMArena (retrieved October 16, 2026)123
Additional sourceLMArena (retrieved November 16, 2026)
Additional sourceVals AI (retrieved November 10, 2026)
Additional sourceVals AI (retrieved November 7, 2026)12345678910111213141516171819202122232425
Additional sourceVals AI (retrieved October 16, 2026; November 7, 2026)1234
Additional sourceVals AI (retrieved November 13, 2026)
Additional sourceVals AI (retrieved November 7, 2026; November 11, 2026)
Additional sourceVals AI (retrieved October 16, 2026)12
Additional sourceVals AI (retrieved October 16, 2026; October 31, 2026; November 7, 2026)
Additional sourceVals AI (retrieved October 16, 2026; October 30, 2026; October 31, 2026)
Additional sourceDeepSeek V4.1 Flash model card (retrieved September 24, 2026)
Additional sourceDeepSeek official release notes (retrieved October 15, 2026)
Additional sourceLlamaIndex / Run-Llama ExtractBench (retrieved October 15, 2026)
Additional sourceLiveBench (retrieved October 16, 2026; October 18, 2026) (unavailable on November 2, 2026) https://livebench.ai/table_2026_09_02.csv
Additional sourceLiveBench (retrieved October 16, 2026) (unavailable on November 2, 2026) https://livebench.ai/breakdown_2026_09_02.json
Additional sourceARC Prize Verified results (retrieved October 17, 2026)
Additional sourceBizBench (retrieved October 17, 2026)
Additional sourceAgenticBBO-Bench (retrieved October 17, 2026)
Additional sourceDeepSeek official API changelog, V4.1 Flash-1017 update (retrieved October 18, 2026) · DeepSeek API changelog · Editorial description reviewed October 2, 2026
Additional sourceParallel Search Capability Leaderboard (retrieved October 18, 2026)
Additional sourceLlamaIndex ParseBench, shown in the official DeepSeek Hugging Face model-page Eval Results section (retrieved October 20, 2026)
Additional sourceServeLearnBench paper, arXiv:2610.07792v1 (retrieved October 21, 2026)
Additional sourceCao et al. (Mine Odyssey) (retrieved October 22, 2026)
Additional sourceDeepSeek-AI, DeepSeek-V4.1-Flash model card (retrieved October 22, 2026)
Additional sourceMachine Spirituality (retrieved October 23, 2026)
Additional sourceForcebench (retrieved October 23, 2026)
Additional sourceForcebench (retrieved October 24, 2026)
Additional sourceDuelLab GameBench 2 model results (retrieved October 28, 2026; November 2, 2026; November 5, 2026; November 9, 2026; November 11, 2026; November 12, 2026; November 15, 2026)
Additional sourceParallel Search Capability Leaderboard (retrieved October 28, 2026; November 5, 2026)
Additional sourceTowards AI ToneBench (retrieved October 28, 2026; October 30, 2026; November 10, 2026; November 11, 2026)1234
Additional sourceGoogle DeepMind on Kaggle (retrieved October 28, 2026)
Additional sourceScale AI DistressBench (retrieved October 28, 2026)
Additional sourceParallel Search Capability Leaderboard (retrieved November 5, 2026)
Additional sourceAlman Institut (retrieved November 6, 2026)
Additional sourceModel metadata (retrieved September 24, 2026) · DeepSeek V4.1 lifecycle notice · Editorial description reviewed October 2, 2026
Additional sourceModel metadata (retrieved September 24, 2026)
Additional sourceOpenRouter: Popularity index (derived), CC BY 4.0
Additional sourceVercel AI Gateway: Popularity index (derived), CC BY 4.0
Additional sourceOllama: cumulative downloads for the popularity index
Additional sourceReplicate: cumulative runs for the popularity index
Additional sourceGoogle Trending Now: limited feed selection for Germany and the US
Additional sourceCreative Commons Attribution 4.0
Additional sourceDeepSeek V4.1 Flash 1017 release (2026-10-24)