
Gemma 4 31B
Gemma 4 31B is distinguished by its dense architecture, 30.7 billion parameters, and hybrid attention across local and global windows. It is the direct open counterpart to the sparse MoE checkpoint Gemma 4 26B A4B.
Google releases the weights under Apache 2.0. The model card documents text and image input plus reasoning, but no audio. Google defines no hosted Gemini API model ID for the weights.
The LLM comparison hub's selected-panel index averages rank percentiles from 65 documented comparison cohorts. Benchmark meta-scores are shown in the benchmark section.
Benchmark meta-analysis
These Gradually indexes place selected published measurements on a 0 to 100 scale. They are not accuracy percentages and do not guarantee results in your application.
Retrieval dates of the sources used 2026-10-15 - 2026-10-19
Index below 1 / 100
provisional
Estimated without own results in: Mathematics and General
Published configurations differ within this comparison cohort. Treat the index as provisional.
Index below 1 / 100
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Index 1.1 / 100
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Index below 1 / 100
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Index below 1 / 100
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Index below 1 / 100
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Index 21.7 / 100
provisional
Published configurations differ within this comparison cohort. Treat the index as provisional.
Method version: benchmark-meta-score-v3
The index includes active measurements from reviewed primary sources when at least five models are compared in the same documented comparison slice across dataset, harness, agent, tools, and trial count. Each benchmark series and evaluator contributes one shared setup slice from the newest capture. When one source and series include several explicitly documented reasoning tiers, the highest documented tier (none through max) is selected, never the best result value. The explicit source label “Non-reasoning” is treated as none. Unknown or ambiguous tiers exclude the model from that series. Within each series, percentages and rates are logit-transformed, other units stay unchanged, and all values are then standardized. A one-factor model then estimates one shared strength per model and, per series, how sharply it separates the models. Area scores move away from that strength only as far as the model's own results in the area support. The overall score weights the core areas at 75% and finance, law and health at 25%. It requires at least eight test series from two sources and three areas. The 0 to 100 scale refers to a fixed reference group of 29 language models whose average sits at 50.
Published model-specific parameters can differ. This is not a controlled experiment; comparisons with such differences are marked provisional.
Unmeasured series are not entered as zero. Where a model has no own results in a core area, its overall strength stands in, and the note “estimated without own results in …” names the area. Fewer test series lead to a larger standard error.
The 95% interval follows from the standard error of 200 recalculations with randomly redrawn test families. It describes how precisely the recorded test series determine the value. It is no prediction for future tasks or for later recalculations with other participants.
The source count is not a count of independent experiments.
OECD handbook on composite indicatorsAll 11 test families and 12 of 12 raw measurements are listed here. The complete calculation for every model is available in the JSON export.
Family weight in the fixed test panel (informative): 0.89 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Family weight in the fixed test panel (informative): 1.53 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Family weight in the fixed test panel (informative): 0.89 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Family weight in the fixed test panel (informative): 1.53 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Family weight in the fixed test panel (informative): 0.89 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Family weight in the fixed test panel (informative): 0.89 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Family weight in the fixed test panel (informative): 3.57 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Family weight in the fixed test panel (informative): 1.53 % · Coverage of this test family: 50 %
Published configurations differ within this cohort.
Family weight in the fixed test panel (informative): 0.71 % · Coverage of this test family: 67 %
Published configurations differ within this cohort.
Published configurations differ within this cohort.
Family weight in the fixed test panel (informative): 1.19 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Family weight in the fixed test panel (informative): 0 % · Coverage of this test family: 100 %
Published configurations differ within this cohort.
Each evaluator measures different capabilities under its own conditions. Test series, composite indices and their components stay separate. The detailed results below retain their scales, configurations and source dates.
| Evaluator | Test series | Composite indices | Recorded active measurements |
|---|---|---|---|
| Artificial Analysis | 11 | 1 | 27 |
| Vals AI | 4 | 0 | 13 |
Coverage is not a quality ranking. Overlapping tests and multiple settings do not count as independent experiments. Vendor claims, historical and disputed results are excluded from this overview and remain labelled in the detailed evidence.
6 measurements from these sources still lack a verified test-family identity and do not increase the test-series count.
Page 1 of 5
| Sub-task | Gemma 4 31B (This model) | GPT-4.1 | GPT-4.1 mini | GPT-4.1 nano |
|---|---|---|---|---|
| Numerical Extraction | 65.66% | 76.23% (best value in this row) | 72.34% | 54.85% |
| Overall | 61.37% | 65.94% (best value in this row) | 65.5% | 52.82% |
| Semantic Extraction | 57.08% | 55.64% | 58.67% (best value in this row) | 50.8% |
higher is betterAs of October 15, 2026Source: Vals AIbars scaled within each row, not across rows
| Sub-task | Gemma 4 31B (This model) | Gemini 3 Flash Preview | Gemini 3.1 Flash-Lite | Gemini 3.5 Flash | Gemini 3.7 Flash | Gemini 3.6 Flash | Gemini 3.8 Flash | Gemini 3.1 Pro Preview | Gemini 3.5 Flash-Lite |
|---|---|---|---|---|---|---|---|---|---|
| Automata | 41.67% | 43.25% (best value in this row) | 42.06% | 38.49% | 35.32% | 34.92% | 33.33% | 32.14% | 28.97% |
| Linear Algebra | 72.64% | 71.02% | 58.94% | 68.31% | 69.52% | 69.87% | 41.7% | 74.21% (best value in this row) | 63.74% |
| Overall | 55.03% (best value in this row) | 51.85% | 49.54% | 49.89% | 49.23% | 48.69% | 35.06% | 48.68% | 47.3% |
| Partial Differential Equations | 50.79% (best value in this row) | 41.27% | 47.62% | 42.86% | 42.86% | 41.27% | 30.16% | 39.68% | 49.21% |
higher is betterAs of October 15, 2026Source: Vals AIbars scaled within each row, not across rows
Calculus
higher is betterAs of October 15, 2026Scale: 0% - 100%
| Sub-task | Gemma 4 31B (This model) | GPT-4.1 |
|---|---|---|
| Easy | 75% (best value in this row) | 50% |
| Hard | 23.33% (best value in this row) | 3.33% |
| Medium | 45.46% (best value in this row) | 18.18% |
| Overall | 39.33% (best value in this row) | 14.61% |
higher is betterAs of October 15, 2026Source: Vals AIbars scaled within each row, not across rows
Page 1 of 5
One SVG prompt and fixed output settings. Captures are shown only with 0 reported reasoning tokens or documented lack of reasoning controls. Identical test conditions do not make the models' internal compute identical.
A community classic for free-form SVG drawing.
Gemma 4 31B
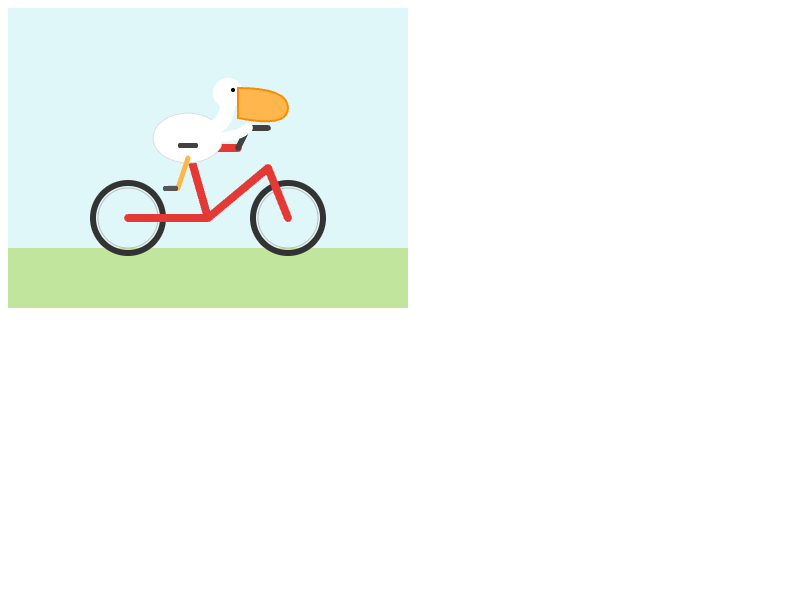
Reasoning (requested): high
Visually reviewed. This individual test does not establish overall model quality.
Generate an SVG of a pelican riding a bicycle
Token limit including reasoning: 8,192 tokens
Task origin (Simon Willison)53.3 / 100
| Specification | Value and source |
|---|---|
| Weights | Open weightsSource |
| Access | API, LocalSource |
| Parameters | 30.7BSource |
| Context window | 262,144 tokensSource |
| Knowledge cutoff | January 2025Source |
| Release | 2026-03-31Source |
| Parameters | 30.7 BSource |
| Input | Text, ImageSource |
| Output | TextSource |
| Architecture | Dense transformer, 30.7B total parameters; hybrid sliding/global attentionSource |
| License | Apache 2.0Source |
| Knowledge cutoff | 2025-01Source |
| Languages | 140+Source |
| Tool calling | YesSource |
| Announcement | 2026-04-02Source |
| Type | Evidence and data date |
|---|---|
| Speed | Google. Output speed after the first streaming chunk, not total response time. Retrieved September 8, 2026. |
| Price | Base API prices without caching or batch discounts. Higher context tiers and other rates are listed under Costs. |
| Input | Documented modalities. Retrieved September 8, 2026. |
| Output | Documented modalities. Retrieved September 8, 2026. |
| Research status | Research date September 8, 2026. 4 source URLs checked. This documents the inspected sources, not an exhaustive inventory of every publication. |
| Not found in the inspected sources | active-parameters-billions Original wording Active parameter count is not separately published for this dense model. |
| Not found in the inspected sources | api-model-id Original wording Gemma is distributed as open weights; the card does not define a hosted Gemini API model ID. |
| Not found in the inspected sources | training-tokens Original wording The Gemma 4 model card describes the dataset but does not publish a token-count total. |
| Additional source | Model metadata · Gemma 4 31B instruction-tuned weights · Editorial description reviewed October 2, 2026 |
| Additional source | Artificial Analysis (retrieved October 19, 2026) |
| Additional source | Artificial Analysis (retrieved October 19, 2026) |
| Additional source | Artificial Analysis (retrieved October 19, 2026) |
| Additional source | Artificial Analysis (retrieved October 19, 2026) |
| Additional source | Artificial Analysis (retrieved October 19, 2026) |
| Additional source | Artificial Analysis (retrieved October 19, 2026) |
| Additional source | Artificial Analysis (retrieved October 19, 2026) |
| Additional source | Artificial Analysis (retrieved October 19, 2026) |
| Additional source | Artificial Analysis (retrieved October 19, 2026) |
| Additional source | Artificial Analysis (retrieved October 19, 2026) |
| Additional source | Artificial Analysis (retrieved October 19, 2026) |
| Additional source | Artificial Analysis (retrieved October 19, 2026) |
| Additional source | Artificial Analysis (retrieved October 19, 2026) |
| Additional source | Artificial Analysis (retrieved October 19, 2026) |
| Additional source | Vals AI (retrieved October 15, 2026) |
| Additional source | Vals AI (retrieved October 15, 2026) |
| Additional source | Vals AI (retrieved October 15, 2026) |
| Additional source | Vals AI (retrieved October 15, 2026) |
| Additional source | Model metadata (retrieved September 8, 2026) |
| Additional source | Model metadata (retrieved September 8, 2026) |
| Additional source | OpenRouter: Popularity index (derived), CC BY 4.0 |
| Additional source | Vercel AI Gateway: Popularity index (derived), CC BY 4.0 |
| Additional source | Ollama: cumulative downloads for the popularity index |
| Additional source | Replicate: cumulative runs for the popularity index |
| Additional source | Google Trending Now: limited feed selection for Germany and the US |
| Additional source | Creative Commons Attribution 4.0 |