Gemma 4 26B A4B
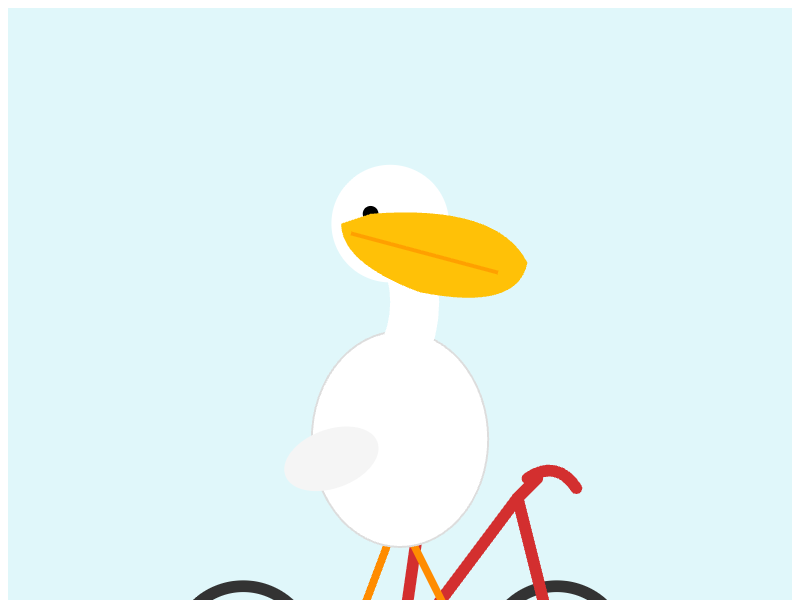
Reasoning (requested): high
Current attempt
- Run date
- 1 Oct 2026
- API provider
- openrouter
- Requested API model
- google/gemma-4-26b-a4b-it
- API model reported in response
- google/gemma-4-26b-a4b-it
- Reasoning setting
- high
- Pinned endpoint
- Darkbloom | google/gemma-4-26b-a4b-it-20260403
- Temperature
- Provider default
- Token limit including reasoning
- 8,192 tokens
- Test protocol
- community-visual-tests-v1
- Technical checks
- Passed, not a quality rating
- Response time
- 86.1 s
Visually reviewed. This individual test does not establish overall model quality.