
Trinity Large Thinking
Unavailable in this round
Arcee AI
Trinity Large Thinking exposes its reasoning trace as visible reasoning blocks. The open sparse MoE has 398 billion total parameters, activates 13 billion, routes four of 256 experts per token alongside shared experts, and starts with six dense layers.
Arcee’s model card lists 524,288 tokens after an extension, while the current executable configuration sets max_position_embeddings to 262,144 and shows no matching RoPE scaling. OpenMDW-1.1 permits use and modification of the weights.
| Specification | Value and source |
|---|---|
| Weights | Open weightsSource |
| Access | API, LocalSource |
| Parameters | 398BSource |
| Active parameters | 13BSource |
| Context window | 262,144 tokensSource |
| License | OpenMDW-1.1Source |
| Parameters | 398 BSource |
| Active parameters | 13 BSource |
| Architecture | sparse MoE AfmoeForCausalLM, 256 experts plus one shared, four active experts, six dense layersSource |
| Pretraining context | 8,192 tokensSource |
| Advertised context window | 524,288 tokens (Vendor-advertised context length after extension. The exact current config.json separately declares max_position_embeddings=262144 with rope_scaling=null.)Source |
| Training tokens | 17TSource |
| Input | TextSource |
| Output | TextSource |
| Reasoning mode | reasoning-optimized; explicit <think>...</think> tracesSource |
| Tool calling | YesSource |
| Model configuration context | 262,144 tokens (Executable config value; distinct from the card's advertised 512K context after extension.)Source |
Page 1 of 2
Overall
higher is betterAs of September 29, 2026Scale: 0% - 100%
Overall
higher is betterAs of September 29, 2026Scale: 0% - 100%
These measurements have no matching peer values under the same test conditions. Their original values and sources remain available here.
Page 1 of 2
One SVG prompt and fixed output settings. Captures are shown only with 0 reported reasoning tokens or documented lack of reasoning controls. Identical test conditions do not make the models' internal compute identical.
Unavailable in this round
A community classic for free-form SVG drawing.
Trinity Large Thinking
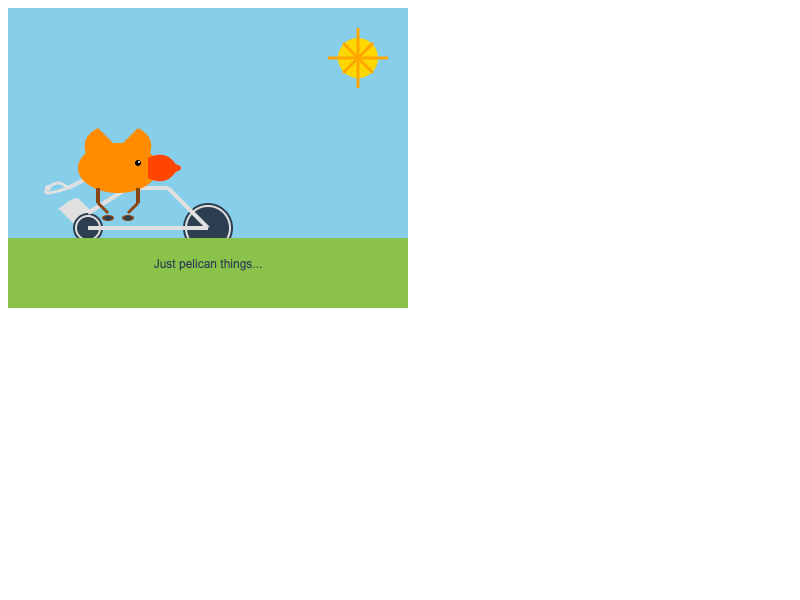
Reasoning (requested): high
Visually reviewed. This individual test does not establish overall model quality.
Generate an SVG of a pelican riding a bicycle
Token limit including reasoning: 8,192 tokens
Task origin (Simon Willison)26.3 / 100
| Type | Evidence and data date |
|---|---|
| Speed | Median across serving providers. Output speed after the first streaming chunk, not total response time. Retrieved September 8, 2026. |
| Price | Base API prices without caching or batch discounts. Higher context tiers and other rates are listed under Costs. |
| Input | Documented modalities. Retrieved September 8, 2026. |
| Output | Documented modalities. Retrieved September 8, 2026. |
| Research status | Research date September 8, 2026. 3 source URLs checked. This documents the inspected sources, not an exhaustive inventory of every publication. |
| Not found in the inspected sources | knowledge-cutoff Original wording The exact Trinity-Large-Thinking card does not publish a knowledge cutoff. |
| Additional source | Vals AI (retrieved September 29, 2026) |
| Additional source | Vals AI (retrieved September 29, 2026) |
| Additional source | Vals AI (retrieved September 29, 2026) |
| Additional source | Model metadata (retrieved September 8, 2026) · Trinity Large Thinking executable configuration · Editorial description reviewed October 2, 2026 |
| Additional source | OpenRouter: Popularity index (derived), CC BY 4.0 |
| Additional source | Vercel AI Gateway: Popularity index (derived), CC BY 4.0 |
| Additional source | Creative Commons Attribution 4.0 |