
GLM-5.1
Z.ai
GLM-5.1 keeps the 744B base of GLM-5 and makes stability on long tasks its documented focus. It activates 40B parameters per token and provides a 200K context. The openly available MoE model remains aimed at demanding text and coding work.
Z.ai documents reasoning and direct responses as separate operating modes. The large parameter count describes the full MoE base, not the compute used for every token. The 744B figure therefore does not mean that all parameters run for every token.
| Specification | Value and source |
|---|---|
| Weights | Open weightsSource |
| Access | API, LocalSource |
| Parameters | 744BSource |
| Active parameters | 40BSource |
| Context window | 200,000 tokensSource |
| Notes | MIT-licensed model with 744B total parameters, 40B active, and a 200K context window.Source |
| License | MITSource |
| Architecture | MoE with DeepSeek Sparse AttentionSource |
| Parameters | 744 BSource |
| Active parameters | 40 BSource |
| Input | TextSource |
| Output | TextSource |
| Reasoning mode | thinking, non-thinkingSource |
| Tool calling | YesSource |
| API model ID | glm-5.1Source |
Page 1 of 16
Russian
Note (GLM-5.1): The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result.
Note: The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result.
higher is betterAs of October 15, 2026Scale: 0 rating - 1,478.72 rating
| Sub-task | GLM-5.1 (This model) | Nemotron 3.5 Lightning |
|---|---|---|
| CLI | 18.83% (best value in this row) | 3.94% |
| COBOL | 46.57% (best value in this row) | 0% |
| Overall | 25.77% (best value in this row) | 2.95% |
higher is betterAs of October 15, 2026Source: Vals AIbars scaled within each row, not across rows
Code Quality
higher is betterAs of October 15, 2026Scale: 0 rating - 3.54 rating
| Sub-task | GLM-5.1 (This model) | Claude Opus 5 | GLM-5.2 |
|---|---|---|---|
| Exact Pages | 61.77% | 68.65% (best value in this row) | 63.64% |
| Max Fitting Context | 66.32% | 75.99% (best value in this row) | 68.42% |
| Overall | 64.45% | 73.19% (best value in this row) | 66.12% |
| Shared Max Context | 65.27% | 74.94% (best value in this row) | 66.32% |
higher is betterAs of October 15, 2026Source: Vals AIbars scaled within each row, not across rows
Page 1 of 16
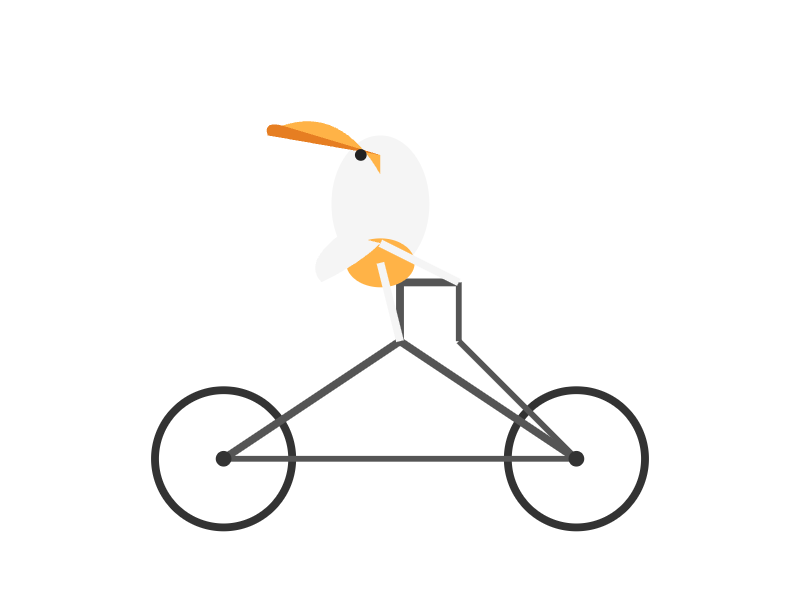
One SVG prompt and fixed output settings. Captures are shown only with 0 reported reasoning tokens or documented lack of reasoning controls. Identical test conditions do not make the models' internal compute identical.
A community classic for free-form SVG drawing.
GLM-5.1
Output withheld for safety
Reasoning (requested): high
Not yet visually reviewed. A successful recording does not confirm correct physics or full compliance with the prompt.
Generate an SVG of a pelican riding a bicycle
Token limit including reasoning: 8,192 tokens
Task origin (Simon Willison)43 / 100