OpenAIMistral AILLM matchup

GPT-6.1 Solvs.Mistral Medium 3.5

Which one is better?

GPT-6.1 Sol performs better than Mistral Medium 3.5, but costs 1.3 times as much.

GPT-6.1 Sol ahead
IntelligenceOverall index, 100 points = average
117.5

GPT-6.1 Sol

Rank 9

46.1

Mistral Medium 3.5

Rank 89

Mistral Medium 3.5 faster
SpeedTokens per second
54

GPT-6.1 Sol

76

Mistral Medium 3.5

Mistral Medium 3.5 cheaper
Price$ per 1M tokens
$4

GPT-6.1 Sol

$3

Mistral Medium 3.5

Popularity0 to 100
n/a

GPT-6.1 Sol

51

Mistral Medium 3.5

Rank 125 of 485

Above 272,000 tokens of context, GPT-6.1 Sol costs more: $4 input and $15 output per 1M tokens.

Choose GPT-6.1 Sol for

ReasoningKnowledgeEducationMultimodalCodingFinanceGeneralMathematicsHealthAgentsLegal

No clear advantage for Mistral Medium 3.5.

Where is the difference?

Strengths at a glance

GPT-6.1 SolMistral Medium 3.5Median of all ranked models

7012017020CodingGPT-6.1 SolReasoningGPT-6.1 SolMathematicsGPT-6.1 SolKnowledgeGPT-6.1 SolAgentsGPT-6.1 SolGeneralGPT-6.1 SolMultimodalGPT-6.1 SolFinanceGPT-6.1 SolLegalGPT-6.1 SolHealthGPT-6.1 Sol
CodingGPT-6.1 Sol ahead
GPT-6.1 Sol120.6Rank 8
Mistral Medium 3.550.1Rank 97
Median of ranked models87.5

95 % range: GPT-6.1 Sol 113.7 to 127.5, Mistral Medium 3.5 43.3 to 56.8.

AreaGPT-6.1 SolMistral Medium 3.5

The same values and verdicts as the bars below. In the close-up the net starts at 20 points, just below the weaker model's lowest value; the reference group average is 100.

GPT-6.1 Sol is ahead in 10 of 10 areas, Mistral Medium 3.5 in none.

GPT-6.1 Sol ahead: 10

Areas in the overall index
ReasoningGPT-6.1 Sol +95122.7 to 28.2
KnowledgeGPT-6.1 Sol +88123.7 to 36.0
MultimodalGPT-6.1 Sol +72118.0 to 46.1
CodingGPT-6.1 Sol +71120.6 to 50.1
GeneralGPT-6.1 Sol +64119.0 to 54.7
MathematicsGPT-6.1 Sol +64124.1 to 60.4
AgentsGPT-6.1 Sol +58112.0 to 54.1
Specialist fields
FinanceGPT-6.1 Sol +69105.8 to 36.6
HealthGPT-6.1 Sol +61110.2 to 49.5
LegalGPT-6.1 Sol +54107.0 to 53.0

Bar length shows the gap in index points (full width 15 points, one standard deviation of the reference group). Solid means clearly ahead, hatched not certain yet, a thin grey bar level.

Show 4 more areas that do not count toward the overall index
EducationGPT-6.1 Sol +75119.9 to 44.7
Cybersecurityonly GPT-6.1 Sol has a score
Searchonly GPT-6.1 Sol has a score
Productivityonly GPT-6.1 Sol has a score

Bar length shows the gap in index points (full width 15 points, one standard deviation of the reference group). Solid means clearly ahead, hatched not certain yet, a thin grey bar level.

GPT-6.1 Sol vs. Mistral Medium 3.5 at the same effort

Both models measured at the same reasoning efforts. This shows whether a lead comes from the model or only from more compute.

highGPT-6.1 Sol ahead
75.9 points gap across 11 shared test series
Overall index (max vs. high)GPT-6.1 Sol ahead
GPT-6.1 Sol 117.5 vs. Mistral Medium 3.5 46.1

The gap compares only the Artificial Analysis test series in which both models are measured at that effort. Tied below 3 points, ahead only beyond two standard errors.

Which model for which task?

Everyday tasks, translated from the area values above. Each row names the values it rests on.

Writing and debugging codeGPT-6.1 SolCoding 120.6 to 50.1
Maths and data analysisGPT-6.1 SolMathematics 124.1 to 60.4, Reasoning 122.7 to 28.2
Facts and researchGPT-6.1 SolKnowledge 123.7 to 36.0, Search without a score for Mistral Medium 3.5
Agents and workflowsGPT-6.1 SolAgents 112.0 to 54.1
Fast chat repliesMistral Medium 3.554 to 76 tokens per second
Security analysisopenCybersecurity without a score for Mistral Medium 3.5
Many requests on a small budgetMistral Medium 3.5$4 to $3 per 1M tokens
Finance, legal and medical textsGPT-6.1 SolFinance 105.8 to 36.6, Legal 107.0 to 53.0, Health 110.2 to 49.5
Images, screenshots and PDFsGPT-6.1 SolMultimodal 118.0 to 46.1

GPT-6.1 Sol vs. Mistral Medium 3.5 in our own test

The same prompt for both models. We show the latest attempt without fixes; it does not count toward the overall index.

Pelican on a bicycle

Prompt

Generate an SVG of a pelican riding a bicycle

Task origin: Simon Willison

GPT-6.1 Sol

GPT-6.1 Sol: Pelican on a bicycle
A community classic for free-form SVG drawing.

Oct 1, 2026 · 84 s · $0.04

Test details
Run date
Oct 1, 2026
API provider
openrouter
Requested API model
openai/gpt-6.1-sol
Reasoning setting
high
Token limit including reasoning
8,192 tokens
Output tokens
3,583 tokens
Cost of the attempt
$0.0359
Response time
83.6 s
API model reported in response
openai/gpt-6.1-sol
Pinned endpoint
OpenAI | openai/gpt-6.1-sol-20260929
Temperature
Provider default
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating

Visually reviewed. This individual test does not establish overall model quality.

Mistral Medium 3.5
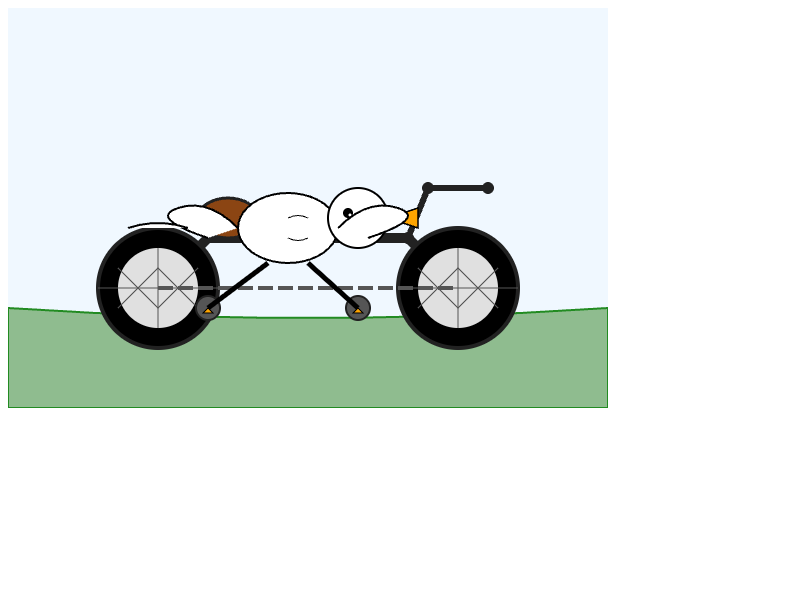
Mistral Medium 3.5: Pelican on a bicycle
A community classic for free-form SVG drawing.

Oct 1, 2026 · 39 s · $0.06

Test details
Run date
Oct 1, 2026
API provider
openrouter
Requested API model
mistralai/mistral-medium-3-5
Reasoning setting
high
Token limit including reasoning
8,192 tokens
Output tokens
8,128 tokens
Cost of the attempt
$0.0610
Response time
38.7 s
API model reported in response
mistralai/mistral-medium-3-5
Pinned endpoint
Mistral | mistralai/mistral-medium-3.5-20260430
Temperature
Provider default
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating

Visually reviewed. This individual test does not establish overall model quality.

Earlier attempts (1)

  • Sep 7, 2026API request failedReasoning setting: high
SVG short test

SVG short test

One SVG task with the same fixed settings for every model, without hidden thinking.

Prompt

Return only one standalone SVG of a pelican riding a bicycle. Use viewBox="0 0 800 600", simple shapes, two clearly visible wheels and a recognizable pelican with a long beak. At most 30 SVG elements and 1800 characters. No Markdown, explanations, comments, scripts, animation, CSS or external resources.

GPT-6.1 Sol

Unavailable in this round

Mistral Medium 3.5
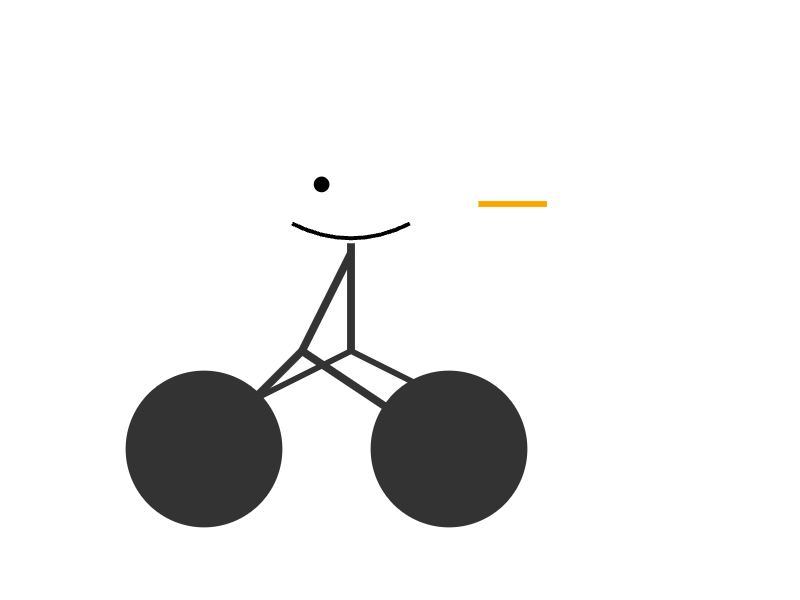
Mistral Medium 3.5: SVG short test

Oct 14, 2026 · $0.0039

Test details
Test run
Oct 14, 2026
Provider
mistral
API model
mistralai/mistral-medium-3-5
Output
502 tokens
Reasoning
API reports 0 reasoning tokens
Cost of the attempt
$0.0039
Test round
43b8c5c46830

GPT-6.1 Sol and Mistral Medium 3.5 in the overall index

Every model with a place in the overall index, both models of this matchup highlighted. You can add or hide other models.

Overall index (Gradually Meta-Score v5)

20 of 95 models

Claude Fable 5.2max130.9
Gemini 4 Carbonhigh127.0
Claude Opus 5.5max125.7
Claude Fable 5.1max124.1
Claude Sonnet 5.5max121.9
Gemini 4 Argonhigh121.2
GPT-6 Astramax119.6
Muse Wonder Fullmax118.4
GPT-6.1 Solmax117.5
Claude Opus 5max117.3
Muse Wondermax113.7
Claude Fable 5max112.8
Kimi K3.1 Promax112.6
Muse Ember 1.0max110.5
GPT-5.6 Solmax109.3
GPT-6 Solmax108.4
Gemini 3.7 Flashhigh107.7
DeepSeek V4.1 Flash 1017max107.1
GPT-6.1 Terramax106.5
Mistral Medium 3.5high46.1

Popularity compared

How often the models are searched for, used and mentioned, on a scale from 0 to 100.

GPT-6.1 Sol has no popularity score yet.

Over time

Weekly values from October 18, 2026 to November 14, 2026

GPT-6.1 SolMistral Medium 3.5

All data side by side

The better value is bold. For the overall index only when the gap is clear.

MetricGPT-6.1 SolMistral Medium 3.5
Intelligence
Overall indexpoints, 100 = reference group average, higher is better117.546.1
RankRank 9 of 95Rank 89 of 95
Price per 1M tokens
Inputwhat you send$2above 272,000 tokens: $4$1.50
Outputwhat the model writes$10above 272,000 tokens: $15$7.50
Cost per task (own tests)average of 3 original-protocol tasks both models passed (SVG short test not included)$0.044$0.087
Speed
Tokens per second5476
Popularity
Popularitysearch, usage and mentions, 0 to 100n/a51Rank 125 of 485
Technical
Context windowhow much text the model reads at once1.05 M tokens≈ 1,580 A4 pages262,144 tokens≈ 390 A4 pages
Knowledge cutoffApr 30, 2026n/a
ReleasedSep 29, 2026Apr 28, 2026
AvailabilityActiveActive
Open weightsnoyes

Prices without caching or batch discounts · Page count as a rule of thumb from Artificial Analysis

Is there a better choice?

Cheaper than Mistral Medium 3.5Muse Ember 1.0

Overall index 110.5, rank 14$0.10 input and $0.50 output per 1M tokens

View profile
Best model in the overall indexClaude Fable 5.2

Overall index 130.9, rank 1$8 input and $40 output per 1M tokens

GPT-6.1 Sol vs. Claude Fable 5.2

Shared benchmarks

Single results from the same benchmark version, task and metric. A value is bold only with the same test setup and a clear gap.

A: GPT-6.1 SolB: Mistral Medium 3.5

Code MigrationOverall · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 65.1%Mistral Medium 3.5: 5.1%Vals AIAs of 10/29/2026
EMBOverall · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 70.8%Mistral Medium 3.5: 11.2%Vals AIAs of 10/20/2026
Finance Agent (v2)Overall · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 52.0%Mistral Medium 3.5: 32.1%Vals AIAs of 10/29/2026
Legal Research BenchOverall · All-pass · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 38.5%Mistral Medium 3.5: 9.1%Vals AIAs of 11/05/2026
LMArena Code Arena WebDevOverall · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,743Mistral Medium 3.5: 1,263LMArenaAs of 11/11/2026
LMArena Text, Style ControlOverall · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,481Mistral Medium 3.5: 1,426LMArenaAs of 11/11/2026
LMArena Vision, Style ControlOverall · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,293Mistral Medium 3.5: 1,199LMArenaAs of 11/09/2026
MedCodeOverall · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 48.8%Mistral Medium 3.5: 33.8%Vals AIAs of 10/29/2026
MedScribeOverall · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 86.5%Mistral Medium 3.5: 67.7%Vals AIAs of 10/29/2026
ProofBench v1.1Overall · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 99%Mistral Medium 3.5: 9%Vals AIAs of 10/29/2026
Show 54 more benchmarks
SAGEOverall · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 90.5%Mistral Medium 3.5: 72.0%Vals AIAs of 11/05/2026
Tax Agent BenchOverall · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 21.8%Mistral Medium 3.5: 4.5%Vals AIAs of 11/05/2026
Vibe Code Bench v1.1Overall · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 88.9%Mistral Medium 3.5: 2.9%Vals AIAs of 11/05/2026
Code MigrationCLI · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 63.5%Mistral Medium 3.5: 5.0%Vals AIAs of 10/29/2026
EMBComps · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 61.8%Mistral Medium 3.5: 18.1%Vals AIAs of 10/20/2026
Finance Agent (v2)Adjustments · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 44.7%Mistral Medium 3.5: 27.3%Vals AIAs of 10/29/2026
Legal Research BenchAdministrative / Regulatory · All-pass · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 53.0%Mistral Medium 3.5: 7.6%Vals AIAs of 11/05/2026
LMArena Code Arena WebDevHTML development · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,794Mistral Medium 3.5: 1,309LMArenaAs of 11/11/2026
LMArena Text, Style ControlBusiness, management and finance · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,480Mistral Medium 3.5: 1,431LMArenaAs of 11/11/2026
LMArena Vision, Style ControlChinese · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,348Mistral Medium 3.5: 1,217LMArenaAs of 11/09/2026
SAGEComputer Science · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 92.4%Mistral Medium 3.5: 72.6%Vals AIAs of 11/05/2026
Tax Agent BenchControversy & Precedence Analysis · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 6.7%Mistral Medium 3.5: 3.3%Vals AIAs of 11/05/2026
Code MigrationCOBOL · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 70.0%Mistral Medium 3.5: 5.5%Vals AIAs of 10/29/2026
EMBDataroom · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 84.5%Mistral Medium 3.5: 13.4%Vals AIAs of 10/20/2026
Finance Agent (v2)All-Pass · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 39.9%Mistral Medium 3.5: 21.6%Vals AIAs of 10/29/2026
Legal Research BenchAdministrative / Regulatory · Weighted partial credit (weighted pass) · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 85.5%Mistral Medium 3.5: 67.5%Vals AIAs of 11/05/2026
LMArena Code Arena WebDevReact development · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,747Mistral Medium 3.5: 1,252LMArenaAs of 11/11/2026
LMArena Text, Style ControlChinese · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,531Mistral Medium 3.5: 1,447LMArenaAs of 11/11/2026
LMArena Vision, Style ControlCreative writing with images · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,303Mistral Medium 3.5: 1,196LMArenaAs of 11/09/2026
SAGELinear Algebra · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 87.2%Mistral Medium 3.5: 64.8%Vals AIAs of 11/05/2026
Tax Agent BenchControversy & Precedence Analysis (weighted pass) · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 64.8%Mistral Medium 3.5: 18.4%Vals AIAs of 11/05/2026
Code MigrationCode Quality · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 4.496 / 5Mistral Medium 3.5: 2.987 / 5Vals AIAs of 10/29/2026
EMBDCF · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 65.3%Mistral Medium 3.5: 2.2%Vals AIAs of 10/20/2026
Finance Agent (v2)Comparables · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 42.6%Mistral Medium 3.5: 31.5%Vals AIAs of 10/29/2026
Legal Research BenchBusiness & Commercial · All-pass · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 39.5%Mistral Medium 3.5: 9.3%Vals AIAs of 11/05/2026
LMArena Code Arena WebDevWeb development · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,743Mistral Medium 3.5: 1,263LMArenaAs of 11/11/2026
LMArena Text, Style ControlCoding · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,540Mistral Medium 3.5: 1,478LMArenaAs of 11/11/2026
LMArena Vision, Style ControlDiagram understanding · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,327Mistral Medium 3.5: 1,242LMArenaAs of 11/09/2026
SAGEPartial Differential Equations · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 90.7%Mistral Medium 3.5: 81.2%Vals AIAs of 11/05/2026
Tax Agent BenchCurrent & Temporal Analysis · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 33.3%Mistral Medium 3.5: 6.5%Vals AIAs of 11/05/2026
EMBLBO · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 64.4%Mistral Medium 3.5: 9.6%Vals AIAs of 10/20/2026
Finance Agent (v2)Disclosure Analysis · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 58.4%Mistral Medium 3.5: 40.2%Vals AIAs of 10/29/2026
Legal Research BenchBusiness & Commercial · Weighted partial credit (weighted pass) · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 84.2%Mistral Medium 3.5: 71.3%Vals AIAs of 11/05/2026
LMArena Text, Style ControlCreative writing · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,449Mistral Medium 3.5: 1,399LMArenaAs of 11/11/2026
LMArena Vision, Style ControlEnglish · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,287Mistral Medium 3.5: 1,218LMArenaAs of 11/09/2026
Tax Agent BenchCurrent & Temporal Analysis (weighted pass) · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 63.4%Mistral Medium 3.5: 29.4%Vals AIAs of 11/05/2026
EMBM&A · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 83.9%Mistral Medium 3.5: 10.7%Vals AIAs of 10/20/2026
Finance Agent (v2)Earnings Analysis · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 71.5%Mistral Medium 3.5: 42.1%Vals AIAs of 10/29/2026
Legal Research BenchCivil Litigation · All-pass · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 29.6%Mistral Medium 3.5: 11.1%Vals AIAs of 11/05/2026
LMArena Text, Style ControlEnglish · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,491Mistral Medium 3.5: 1,443LMArenaAs of 11/11/2026
LMArena Vision, Style ControlHomework · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,357Mistral Medium 3.5: 1,216LMArenaAs of 11/09/2026
Tax Agent BenchFact-Pattern Analysis · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 30.2%Mistral Medium 3.5: 2.3%Vals AIAs of 11/05/2026
EMBMisc · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 61.6%Mistral Medium 3.5: 14.1%Vals AIAs of 10/20/2026
Finance Agent (v2)Financial Modeling · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 23.1%Mistral Medium 3.5: 5.1%Vals AIAs of 10/29/2026
Legal Research BenchCivil Litigation · Weighted partial credit (weighted pass) · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 87.7%Mistral Medium 3.5: 66.0%Vals AIAs of 11/05/2026
LMArena Text, Style ControlEntertainment, sports and media · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,453Mistral Medium 3.5: 1,397LMArenaAs of 11/11/2026
LMArena Vision, Style ControlHumor · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,283Mistral Medium 3.5: 1,197LMArenaAs of 11/09/2026
Tax Agent BenchFact-Pattern Analysis (weighted pass) · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 61.7%Mistral Medium 3.5: 24.4%Vals AIAs of 11/05/2026
EMBOperating · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 73.9%Mistral Medium 3.5: 10.2%Vals AIAs of 10/20/2026
Finance Agent (v2)General Qualitative Analysis · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 63.2%Mistral Medium 3.5: 47.9%Vals AIAs of 10/29/2026
Legal Research BenchConstitutional / Civil Rights · All-pass · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 31.6%Mistral Medium 3.5: 10.5%Vals AIAs of 11/05/2026
LMArena Text, Style ControlExcluding ties · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,494Mistral Medium 3.5: 1,420LMArenaAs of 11/11/2026
LMArena Vision, Style ControlOptical character recognition · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,300Mistral Medium 3.5: 1,215LMArenaAs of 11/09/2026
Tax Agent BenchForms & Filings · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 3.3%Mistral Medium 3.5: 0.0%Vals AIAs of 11/05/2026

More comparisons

Compare GPT-6.1 Sol and Mistral Medium 3.5 with the models people compare them with most often.

Compare another matchup

The most popular comparisons

  1. 1GPT-6.1 Sol vs. GPT-5.6 Sol
  2. 2GPT-6.1 Sol vs. GPT-6.1 Terra
  3. 3GPT-6.1 Sol vs. GPT-6 Astra
  4. 4GPT-6.1 Sol vs. GPT-5.6 Terra
  5. 5DeepSeek-V4.1-Flash vs. Mistral Medium 3.5
  6. 6Claude Opus 5.5 vs. Mistral Medium 3.5
  7. 7GPT-6.1 Sol vs. Gemini 3.8 Flash
  8. 8Qwen 3.8 27B vs. Mistral Medium 3.5
  9. 9GLM-5.2 vs. Mistral Medium 3.5
Show all 53 comparisons
  1. 10GPT-6 Luna vs. Mistral Medium 3.5
  2. 11Claude Sonnet 5.5 vs. Mistral Medium 3.5
  3. 12Claude Opus 5.5 vs. GPT-6.1 Sol
  4. 13Claude Sonnet 4.5 vs. Mistral Medium 3.5
  5. 14Claude Sonnet 5.5 vs. GPT-6.1 Sol
  6. 15DeepSeek V4.1 Flash 1017 vs. Mistral Medium 3.5
  7. 16GPT-6.1 Sol vs. GLM-5.3-Flash
  8. 17GPT-6.1 Sol vs. GPT-6 Luna
  9. 18GPT-6.1 Sol vs. Gemini 4 Carbon
  10. 19GPT-6.1 Sol vs. DeepSeek-V4.1-Flash
  11. 20Mistral Large 4 vs. Mistral Medium 3.5
  12. 21Claude Opus 4.8 vs. GPT-6.1 Sol
  13. 22GPT-6.1 Sol vs. Gemini 4 Argon
  14. 23GPT-6.1 Sol vs. Kimi K3.1 Pro
  15. 24GPT-6.1 Sol vs. DeepSeek-V4-Flash
  16. 25GPT-6.1 Sol vs. GPT-5.4 mini
  17. 26GPT-6.1 Sol vs. GPT-5.4
  18. 27GPT-6.1 Sol vs. DeepSeek V4.1 Flash 1017
  19. 28GPT-6.1 Sol vs. Qwen 3.8 Max 0902
  20. 29Claude Sonnet 4.6 vs. GPT-6.1 Sol
  21. 30Claude Opus 4.6 vs. GPT-6.1 Sol
  22. 31GPT-6.1 Sol vs. GPT-5.6 Luna
  23. 32Claude Sonnet 5 vs. GPT-6.1 Sol
  24. 33Claude Opus 5 vs. GPT-6.1 Sol
  25. 34GPT-6.1 Sol vs. GPT-5.5
  26. 35Claude Haiku 5.5 vs. GPT-6.1 Sol
  27. 36GPT-6.1 Sol vs. Grok 4.7
  28. 37Claude Sonnet 4.5 vs. GPT-6.1 Sol
  29. 38GPT-6.1 Sol vs. Gemini 3.5 Flash
  30. 39Claude Opus 4.7 vs. GPT-6.1 Sol
  31. 40GPT-6.1 Sol vs. GLM-5.3
  32. 41Claude Fable 5.2 vs. GPT-6.1 Sol
  33. 42GPT-6.1 Sol vs. Gemini 3.7 Flash
  34. 43GPT-6.1 Sol vs. Qwen 3.8 27B
  35. 44Claude Fable 5.1 vs. GPT-6.1 Sol
  36. 45GPT-6.1 Sol vs. Gemini 3.1 Pro Preview
  37. 46GPT-6.1 Sol vs. Gemini 3.6 Flash
  38. 47GPT-6.1 Sol vs. Kimi K3
  39. 48Claude Fable 5 vs. GPT-6.1 Sol
  40. 49GPT-6.1 Sol vs. DeepSeek-V4-Pro
  41. 50GPT-6.1 Sol vs. Muse Wonder
  42. 51Claude Haiku 4.5 vs. GPT-6.1 Sol
  43. 52Gemini 4 Argon vs. Mistral Medium 3.5
  44. 53Claude Opus 4.5 vs. GPT-6.1 Sol