OpenAILLM matchup

GPT-6.1 Solvs.GPT-5.4 mini

Is the higher price worth it?

GPT-6.1 Sol performs better than GPT-5.4 mini, but costs 2.7 times (input) and 2.2 times (output) as much.

GPT-6.1 Sol ahead
IntelligenceOverall index, 100 points = average
117.5

GPT-6.1 Sol

Rank 9

75.1

GPT-5.4 mini

Rank 62

GPT-5.4 mini faster
SpeedTokens per second
54

GPT-6.1 Sol

147

GPT-5.4 mini

GPT-5.4 mini cheaper
Price$ per 1M tokens
$4

GPT-6.1 Sol

$1.69

GPT-5.4 mini

Above 272,000 tokens of context, GPT-6.1 Sol costs more: $4 input and $15 output per 1M tokens.

Choose GPT-6.1 Sol for

KnowledgeReasoningCodingMultimodalGeneralLegalAgentsFinance

No clear advantage for GPT-5.4 mini.

Where is the difference?

Strengths at a glance

GPT-6.1 SolGPT-5.4 miniMedian of all ranked models

8510512514565CodingGPT-6.1 SolReasoningGPT-6.1 SolKnowledgeGPT-6.1 SolAgentsGPT-6.1 SolGeneralGPT-6.1 SolMultimodalGPT-6.1 SolFinanceGPT-6.1 SolLegalGPT-6.1 Sol
CodingGPT-6.1 Sol ahead
GPT-6.1 Sol120.6Rank 8
GPT-5.4 mini75.7Rank 71
Median of ranked models87.5

95 % range: GPT-6.1 Sol 113.7 to 127.5, GPT-5.4 mini 71.0 to 80.5.

AreaGPT-6.1 SolGPT-5.4 mini

The same values and verdicts as the bars below. In the close-up the net starts at 65 points, just below the weaker model's lowest value; the reference group average is 100. Not in the net because a model has no own value there or the data are too thin: Mathematics, Health.

GPT-6.1 Sol is ahead in 8 of 10 areas, GPT-5.4 mini in none.

GPT-6.1 Sol ahead: 8too little data: 2

Areas in the overall index
KnowledgeGPT-6.1 Sol +50123.7 to 73.8
ReasoningGPT-6.1 Sol +50122.7 to 72.9
CodingGPT-6.1 Sol +45120.6 to 75.7
MultimodalGPT-6.1 Sol +43118.0 to 75.1
GeneralGPT-6.1 Sol +40119.0 to 79.3
AgentsGPT-6.1 Sol +33112.0 to 78.7
Mathematicsonly GPT-6.1 Sol has a score
Specialist fields
LegalGPT-6.1 Sol +36107.0 to 71.3
FinanceGPT-6.1 Sol +31105.8 to 75.1
Healthonly GPT-6.1 Sol has a score

Bar length shows the gap in index points (full width 15 points, one standard deviation of the reference group). Solid means clearly ahead, hatched not certain yet, a thin grey bar level.

Show 4 more areas that do not count toward the overall index
Cybersecurityonly GPT-6.1 Sol has a score
Searchonly GPT-6.1 Sol has a score
Productivityonly GPT-6.1 Sol has a score
Educationonly GPT-6.1 Sol has a score

Bar length shows the gap in index points (full width 15 points, one standard deviation of the reference group). Solid means clearly ahead, hatched not certain yet, a thin grey bar level.

Which model for which task?

Everyday tasks, translated from the area values above. Each row names the values it rests on.

Writing and debugging codeGPT-6.1 SolCoding 120.6 to 75.7
Maths and data analysisGPT-6.1 SolMathematics without a score for GPT-5.4 mini, Reasoning 122.7 to 72.9
Facts and researchGPT-6.1 SolKnowledge 123.7 to 73.8, Search without a score for GPT-5.4 mini
Agents and workflowsGPT-6.1 SolAgents 112.0 to 78.7
Fast chat repliesGPT-5.4 mini54 to 147 tokens per second
Security analysisopenCybersecurity without a score for GPT-5.4 mini
Many requests on a small budgetGPT-5.4 mini$4 to $1.69 per 1M tokens
Finance, legal and medical textsGPT-6.1 SolFinance 105.8 to 75.1, Legal 107.0 to 71.3, Health without a score for GPT-5.4 mini
Images, screenshots and PDFsGPT-6.1 SolMultimodal 118.0 to 75.1

GPT-6.1 Sol vs. GPT-5.4 mini in our own test

The same prompt for both models. We show the latest attempt without fixes; it does not count toward the overall index.

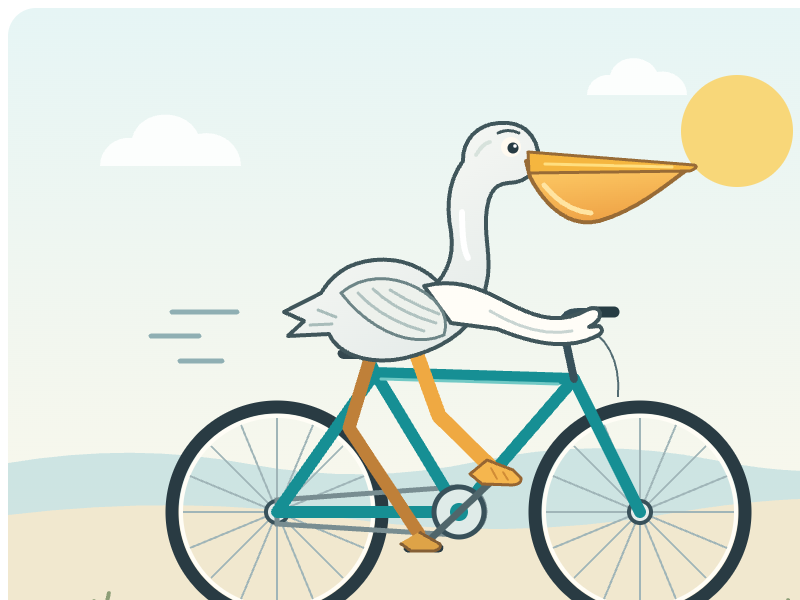
Pelican on a bicycle

Prompt

Generate an SVG of a pelican riding a bicycle

Task origin: Simon Willison

GPT-6.1 Sol

GPT-6.1 Sol: Pelican on a bicycle
A community classic for free-form SVG drawing.

Oct 1, 2026 · 84 s · $0.04

Test details
Run date
Oct 1, 2026
API provider
openrouter
Requested API model
openai/gpt-6.1-sol
Reasoning setting
high
Token limit including reasoning
8,192 tokens
Output tokens
3,583 tokens
Cost of the attempt
$0.0359
Response time
83.6 s
API model reported in response
openai/gpt-6.1-sol
Pinned endpoint
OpenAI | openai/gpt-6.1-sol-20260929
Temperature
Provider default
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating

Visually reviewed. This individual test does not establish overall model quality.

GPT-5.4 mini
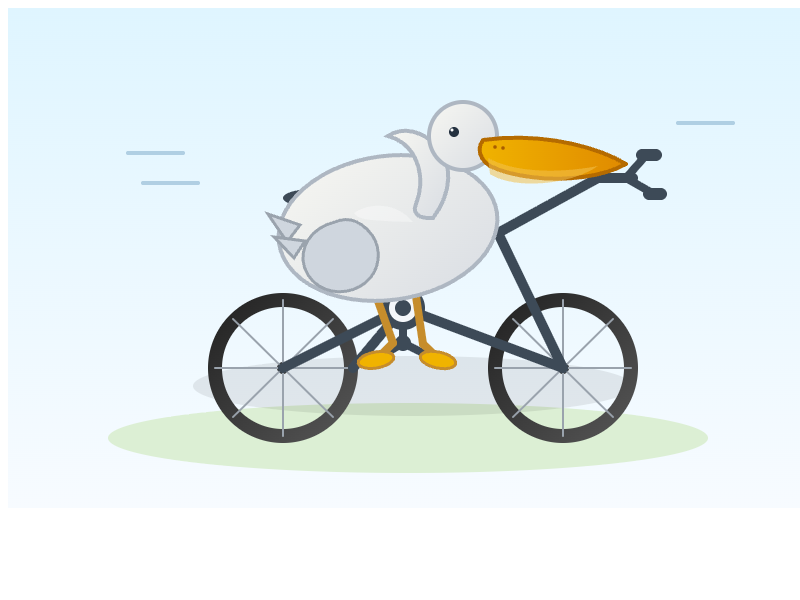
GPT-5.4 mini: Pelican on a bicycle
A community classic for free-form SVG drawing.

Oct 2, 2026 · 14 s · $0.01

Test details
Run date
Oct 2, 2026
API provider
openrouter
Requested API model
openai/gpt-5.4-mini
Reasoning setting
high
Token limit including reasoning
8,192 tokens
Output tokens
3,142 tokens
Cost of the attempt
$0.0142
Response time
13.5 s
API model reported in response
openai/gpt-5.4-mini
Pinned endpoint
OpenAI | openai/gpt-5.4-mini-20260317
Temperature
Provider default
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating

Visually reviewed. This individual test does not establish overall model quality.

Earlier attempts (2)

  • Oct 1, 2026API request failedReasoning setting: high
  • Sep 7, 2026API request failedReasoning setting: high
SVG short test

SVG short test

One SVG task with the same fixed settings for every model, without hidden thinking.

Prompt

Return only one standalone SVG of a pelican riding a bicycle. Use viewBox="0 0 800 600", simple shapes, two clearly visible wheels and a recognizable pelican with a long beak. At most 30 SVG elements and 1800 characters. No Markdown, explanations, comments, scripts, animation, CSS or external resources.

GPT-6.1 Sol

Unavailable in this round

GPT-5.4 mini

Unavailable in this round

GPT-6.1 Sol and GPT-5.4 mini in the overall index

Every model with a place in the overall index, both models of this matchup highlighted. You can add or hide other models.

Overall index (Gradually Meta-Score v5)

20 of 95 models

Claude Fable 5.2max130.9
Gemini 4 Carbonhigh127.0
Claude Opus 5.5max125.7
Claude Fable 5.1max124.1
Claude Sonnet 5.5max121.9
Gemini 4 Argonhigh121.2
GPT-6 Astramax119.6
Muse Wonder Fullmax118.4
GPT-6.1 Solmax117.5
Claude Opus 5max117.3
Muse Wondermax113.7
Claude Fable 5max112.8
Kimi K3.1 Promax112.6
Muse Ember 1.0max110.5
GPT-5.6 Solmax109.3
GPT-6 Solmax108.4
Gemini 3.7 Flashhigh107.7
DeepSeek V4.1 Flash 1017max107.1
GPT-6.1 Terramax106.5
GPT-5.4 minixhigh75.1

All data side by side

The better value is bold. For the overall index only when the gap is clear.

MetricGPT-6.1 SolGPT-5.4 mini
Intelligence
Overall indexpoints, 100 = reference group average, higher is better117.575.1
RankRank 9 of 95Rank 62 of 95
Price per 1M tokens
Inputwhat you send$2above 272,000 tokens: $4$0.75
Outputwhat the model writes$10above 272,000 tokens: $15$4.50
Cost per task (own tests)average of 1 original-protocol task both models passed (SVG short test not included)$0.036$0.014
Speed
Tokens per second54147
Technical
Context windowhow much text the model reads at once1.05 M tokens≈ 1,580 A4 pages400,000 tokens≈ 600 A4 pages
Knowledge cutoffApr 30, 2026Aug 31, 2025
ReleasedSep 29, 2026Mar 17, 2026
AvailabilityActiveActive
Open weightsnono

Prices without caching or batch discounts · Page count as a rule of thumb from Artificial Analysis

Is there a better choice?

Cheaper than GPT-5.4 miniMuse Ember 1.0

Overall index 110.5, rank 14$0.10 input and $0.50 output per 1M tokens

View profile
Best model in the overall indexClaude Fable 5.2

Overall index 130.9, rank 1$8 input and $40 output per 1M tokens

GPT-6.1 Sol vs. Claude Fable 5.2

Shared benchmarks

Single results from the same benchmark version, task and metric. A value is bold only with the same test setup and a clear gap.

A: GPT-6.1 SolB: GPT-5.4 mini

Code MigrationOverall · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 65.1%GPT-5.4 mini: 12.9%Vals AIAs of 10/29/2026
EMBOverall · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 70.8%GPT-5.4 mini: 45.4%Vals AIAs of 10/20/2026
Finance Agent (v2)Overall · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 52.0%GPT-5.4 mini: 45.4%Vals AIAs of 10/29/2026
GDPval-AAOverall · higher is betterGPT-6.1 Sol: 1,554.8 eloGPT-5.4 mini: 1,021.8 eloArtificial AnalysisAs of 11/07/2026
Legal Research BenchOverall · All-pass · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 38.5%GPT-5.4 mini: 12.5%Vals AIAs of 11/05/2026
LMArena Code Arena WebDevOverall · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,743GPT-5.4 mini: 1,398LMArenaAs of 11/11/2026
LMArena Text, Style ControlOverall · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,481GPT-5.4 mini: 1,447LMArenaAs of 11/11/2026
LMArena Vision, Style ControlOverall · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,293GPT-5.4 mini: 1,250LMArenaAs of 11/09/2026
MMMU-ProOverall · higher is betterGPT-6.1 Sol: 85.1%GPT-5.4 mini: 73.3%Artificial AnalysisAs of 11/07/2026
ProgramBenchOverall · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 3%GPT-5.4 mini: 0%Vals AIAs of 11/05/2026
Show 54 more benchmarks
Tax Agent BenchOverall · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 21.8%GPT-5.4 mini: 8.8%Vals AIAs of 11/05/2026
Terminal-Bench 4.0Overall · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 55.1%GPT-5.4 mini: 2.5%Vals AIAs of 11/05/2026
Vibe Code Bench v1.1Overall · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 88.9%GPT-5.4 mini: 48.0%Vals AIAs of 11/05/2026
Code MigrationCLI · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 63.5%GPT-5.4 mini: 8.2%Vals AIAs of 10/29/2026
EMBComps · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 61.8%GPT-5.4 mini: 40.5%Vals AIAs of 10/20/2026
Finance Agent (v2)Adjustments · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 44.7%GPT-5.4 mini: 45.4%Vals AIAs of 10/29/2026
Legal Research BenchAdministrative / Regulatory · All-pass · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 53.0%GPT-5.4 mini: 15.2%Vals AIAs of 11/05/2026
LMArena Code Arena WebDevHTML development · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,794GPT-5.4 mini: 1,420LMArenaAs of 11/11/2026
LMArena Text, Style ControlBusiness, management and finance · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,480GPT-5.4 mini: 1,459LMArenaAs of 11/11/2026
LMArena Vision, Style ControlChinese · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,348GPT-5.4 mini: 1,285LMArenaAs of 11/09/2026
ProgramBenchAlmost Resolved · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 46%GPT-5.4 mini: 3%Vals AIAs of 11/05/2026
Tax Agent BenchControversy & Precedence Analysis · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 6.7%GPT-5.4 mini: 3.3%Vals AIAs of 11/05/2026
Terminal-Bench 4.0Hardware · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 40%GPT-5.4 mini: 0%Vals AIAs of 11/05/2026
Code MigrationCOBOL · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 70.0%GPT-5.4 mini: 27.1%Vals AIAs of 10/29/2026
EMBDataroom · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 84.5%GPT-5.4 mini: 48.3%Vals AIAs of 10/20/2026
Finance Agent (v2)All-Pass · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 39.9%GPT-5.4 mini: 32.4%Vals AIAs of 10/29/2026
Legal Research BenchAdministrative / Regulatory · Weighted partial credit (weighted pass) · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 85.5%GPT-5.4 mini: 69.7%Vals AIAs of 11/05/2026
LMArena Code Arena WebDevReact development · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,747GPT-5.4 mini: 1,386LMArenaAs of 11/11/2026
LMArena Text, Style ControlChinese · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,531GPT-5.4 mini: 1,473LMArenaAs of 11/11/2026
LMArena Vision, Style ControlCreative writing with images · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,303GPT-5.4 mini: 1,225LMArenaAs of 11/09/2026
ProgramBenchFully Resolved · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 3%GPT-5.4 mini: 0%Vals AIAs of 11/05/2026
Tax Agent BenchControversy & Precedence Analysis (weighted pass) · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 64.8%GPT-5.4 mini: 32.2%Vals AIAs of 11/05/2026
Terminal-Bench 4.0Media · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 50%GPT-5.4 mini: 0%Vals AIAs of 11/05/2026
Code MigrationCode Quality · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 4.496 / 5GPT-5.4 mini: 3.053 / 5Vals AIAs of 10/29/2026
EMBDCF · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 65.3%GPT-5.4 mini: 40.6%Vals AIAs of 10/20/2026
Finance Agent (v2)Comparables · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 42.6%GPT-5.4 mini: 40.3%Vals AIAs of 10/29/2026
Legal Research BenchBusiness & Commercial · All-pass · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 39.5%GPT-5.4 mini: 11.6%Vals AIAs of 11/05/2026
LMArena Code Arena WebDevWeb development · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,743GPT-5.4 mini: 1,398LMArenaAs of 11/11/2026
LMArena Text, Style ControlCoding · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,540GPT-5.4 mini: 1,495LMArenaAs of 11/11/2026
LMArena Vision, Style ControlDiagram understanding · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,327GPT-5.4 mini: 1,283LMArenaAs of 11/09/2026
ProgramBenchRaw Pass Rate · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 85.3%GPT-5.4 mini: 54.4%Vals AIAs of 11/05/2026
Tax Agent BenchCurrent & Temporal Analysis · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 33.3%GPT-5.4 mini: 10.0%Vals AIAs of 11/05/2026
Terminal-Bench 4.0ML · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 54.5%GPT-5.4 mini: 0.0%Vals AIAs of 11/05/2026
EMBLBO · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 64.4%GPT-5.4 mini: 41.6%Vals AIAs of 10/20/2026
Finance Agent (v2)Disclosure Analysis · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 58.4%GPT-5.4 mini: 48.3%Vals AIAs of 10/29/2026
Legal Research BenchBusiness & Commercial · Weighted partial credit (weighted pass) · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 84.2%GPT-5.4 mini: 71.2%Vals AIAs of 11/05/2026
LMArena Text, Style ControlCreative writing · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,449GPT-5.4 mini: 1,401LMArenaAs of 11/11/2026
LMArena Vision, Style ControlEnglish · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,287GPT-5.4 mini: 1,247LMArenaAs of 11/09/2026
Tax Agent BenchCurrent & Temporal Analysis (weighted pass) · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 63.4%GPT-5.4 mini: 38.6%Vals AIAs of 11/05/2026
Terminal-Bench 4.0Operations · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 40.7%GPT-5.4 mini: 0.0%Vals AIAs of 11/05/2026
EMBM&A · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 83.9%GPT-5.4 mini: 49.8%Vals AIAs of 10/20/2026
Finance Agent (v2)Earnings Analysis · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 71.5%GPT-5.4 mini: 65.3%Vals AIAs of 10/29/2026
Legal Research BenchCivil Litigation · All-pass · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 29.6%GPT-5.4 mini: 14.8%Vals AIAs of 11/05/2026
LMArena Text, Style ControlEnglish · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,491GPT-5.4 mini: 1,450LMArenaAs of 11/11/2026
LMArena Vision, Style ControlHomework · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,357GPT-5.4 mini: 1,291LMArenaAs of 11/09/2026
Tax Agent BenchFact-Pattern Analysis · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 30.2%GPT-5.4 mini: 7.0%Vals AIAs of 11/05/2026
Terminal-Bench 4.0Science · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 54.8%GPT-5.4 mini: 2.4%Vals AIAs of 11/05/2026
EMBMisc · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 61.6%GPT-5.4 mini: 46.3%Vals AIAs of 10/20/2026
Finance Agent (v2)Financial Modeling · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 23.1%GPT-5.4 mini: 19.6%Vals AIAs of 10/29/2026
Legal Research BenchCivil Litigation · Weighted partial credit (weighted pass) · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 87.7%GPT-5.4 mini: 67.3%Vals AIAs of 11/05/2026
LMArena Text, Style ControlEntertainment, sports and media · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,453GPT-5.4 mini: 1,408LMArenaAs of 11/11/2026
LMArena Vision, Style ControlHumor · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,283GPT-5.4 mini: 1,239LMArenaAs of 11/09/2026
Tax Agent BenchFact-Pattern Analysis (weighted pass) · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 61.7%GPT-5.4 mini: 36.5%Vals AIAs of 11/05/2026
Terminal-Bench 4.0Security · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 93.3%GPT-5.4 mini: 0.0%Vals AIAs of 11/05/2026

More comparisons

Compare GPT-6.1 Sol and GPT-5.4 mini with the models people compare them with most often.

Compare another matchup

The most popular comparisons

  1. 1GPT-6 Luna vs. GPT-5.4 mini
  2. 2GPT-6.1 Sol vs. GPT-5.6 Sol
  3. 3GPT-6.1 Sol vs. GPT-6.1 Terra
  4. 4GPT-5.6 Luna vs. GPT-5.4 mini
  5. 5GPT-6.1 Sol vs. GPT-6 Astra
  6. 6GPT-5.4 mini vs. Gemini 3.8 Flash
  7. 7GPT-6.1 Sol vs. GPT-5.6 Terra
  8. 8Claude Haiku 5.5 vs. GPT-5.4 mini
  9. 9GPT-5.4 mini vs. Qwen 3.8 27B
Show all 50 comparisons
  1. 10GPT-6.1 Sol vs. Gemini 3.8 Flash
  2. 11GPT-5.4 mini vs. DeepSeek-V4-Flash
  3. 12Claude Sonnet 5.5 vs. GPT-5.4 mini
  4. 13Claude Opus 5.5 vs. GPT-6.1 Sol
  5. 14Claude Sonnet 5.5 vs. GPT-6.1 Sol
  6. 15GPT-6.1 Sol vs. GLM-5.3-Flash
  7. 16GPT-6.1 Sol vs. GPT-6 Luna
  8. 17GPT-6.1 Sol vs. Gemini 4 Carbon
  9. 18GPT-6.1 Sol vs. DeepSeek-V4.1-Flash
  10. 19Claude Opus 4.8 vs. GPT-6.1 Sol
  11. 20GPT-6.1 Sol vs. Gemini 4 Argon
  12. 21GPT-6.1 Sol vs. Kimi K3.1 Pro
  13. 22GPT-6.1 Sol vs. DeepSeek-V4-Flash
  14. 23GPT-6.1 Sol vs. GPT-5.4
  15. 24GPT-6.1 Sol vs. DeepSeek V4.1 Flash 1017
  16. 25GPT-6.1 Sol vs. Qwen 3.8 Max 0902
  17. 26Claude Sonnet 4.6 vs. GPT-6.1 Sol
  18. 27Claude Opus 4.6 vs. GPT-6.1 Sol
  19. 28GPT-6.1 Sol vs. GPT-5.6 Luna
  20. 29GPT-6.1 Terra vs. GPT-5.4 mini
  21. 30Claude Sonnet 5 vs. GPT-6.1 Sol
  22. 31Claude Opus 5 vs. GPT-6.1 Sol
  23. 32GPT-6.1 Sol vs. GPT-5.5
  24. 33Claude Haiku 5.5 vs. GPT-6.1 Sol
  25. 34GPT-6.1 Sol vs. Grok 4.7
  26. 35Claude Sonnet 4.5 vs. GPT-6.1 Sol
  27. 36GPT-6.1 Sol vs. Gemini 3.5 Flash
  28. 37Claude Opus 4.7 vs. GPT-6.1 Sol
  29. 38GPT-6.1 Sol vs. GLM-5.3
  30. 39Claude Fable 5.2 vs. GPT-6.1 Sol
  31. 40GPT-6.1 Sol vs. Gemini 3.7 Flash
  32. 41GPT-6.1 Sol vs. Qwen 3.8 27B
  33. 42Claude Fable 5.1 vs. GPT-6.1 Sol
  34. 43GPT-6.1 Sol vs. Gemini 3.1 Pro Preview
  35. 44GPT-6.1 Sol vs. Gemini 3.6 Flash
  36. 45GPT-6.1 Sol vs. Kimi K3
  37. 46Claude Fable 5 vs. GPT-6.1 Sol
  38. 47GPT-6.1 Sol vs. DeepSeek-V4-Pro
  39. 48GPT-6.1 Sol vs. Muse Wonder
  40. 49Claude Haiku 4.5 vs. GPT-6.1 Sol
  41. 50Claude Opus 4.5 vs. GPT-6.1 Sol