OpenAILLM matchup

GPT-6 Solvs.GPT-5.4 mini

Is the higher price worth it?

GPT-6 Sol performs better than GPT-5.4 mini, but costs 2.7 times (input) and 2.2 times (output) as much.

GPT-6 Sol ahead
IntelligenceOverall index, 100 points = average
110.5

GPT-6 Sol

Rank 13

75.6

GPT-5.4 mini

Rank 56

GPT-5.4 mini faster
SpeedTokens per second
111

GPT-6 Sol

191

GPT-5.4 mini

GPT-5.4 mini cheaper
Price$ per 1M tokens
$4

GPT-6 Sol

$1.69

GPT-5.4 mini

GPT-6 Sol more popular
Popularity0 to 100
73

GPT-6 Sol

Rank 3 of 785

59

GPT-5.4 mini

Rank 38 of 785

Above 272,000 tokens of context, GPT-6 Sol costs more: $4 input and $15 output per 1M tokens.

Choose GPT-6 Sol for

ReasoningCodingKnowledgeGeneralLegalMultimodalAgentsFinance

Choose GPT-5.4 mini for

No clear advantage

Where is the difference?

Strengths at a glance

GPT-6 SolGPT-5.4 miniMedian of all ranked models

8510512565CodingGPT-6 SolReasoningGPT-6 SolKnowledgeGPT-6 SolAgentsGPT-6 SolGeneralGPT-6 SolMultimodalGPT-6 SolFinanceGPT-6 SolLegalGPT-6 Sol
CodingGPT-6 Sol ahead
GPT-6 Sol114.9Rank 11
GPT-5.4 mini75.8Rank 65
Median of ranked models84.1

95 % range: GPT-6 Sol 112.2 to 117.6, GPT-5.4 mini 71.9 to 79.8.

AreaGPT-6 SolGPT-5.4 mini

The same values and verdicts as the bars below. In the close-up the net starts at 65 points, just below the weaker model's lowest value; the reference group average is 100. Not in the net because a model has no own value there or the data are too thin: Mathematics, Health.

GPT-6 Sol is ahead in 8 of 10 areas, GPT-5.4 mini in none.

GPT-6 Sol ahead: 8too little data: 2

Areas in the overall index
ReasoningGPT-6 Sol +40114.1 to 74.3
CodingGPT-6 Sol +39114.9 to 75.8
KnowledgeGPT-6 Sol +35109.8 to 74.9
GeneralGPT-6 Sol +33113.0 to 80.4
MultimodalGPT-6 Sol +30106.9 to 76.5
AgentsGPT-6 Sol +28107.2 to 79.0
Mathematicsonly GPT-6 Sol has a score
Specialist fields
LegalGPT-6 Sol +32104.8 to 73.1
FinanceGPT-6 Sol +26101.3 to 75.7
Healthonly GPT-6 Sol has a score

Bar length shows the gap in index points (full width 15 points, one standard deviation of the reference group). Solid means clearly ahead, hatched not certain yet, a thin grey bar level.

Show 3 more areas that do not count toward the overall index
Cybersecurityonly GPT-6 Sol has a score
Searchonly GPT-6 Sol has a score
Productivityonly GPT-6 Sol has a score

Bar length shows the gap in index points (full width 15 points, one standard deviation of the reference group). Solid means clearly ahead, hatched not certain yet, a thin grey bar level.

Which model for which task?

Everyday tasks, translated from the area values above. Each row names the values it rests on.

Writing and debugging codeGPT-6 SolCoding 114.9 to 75.8
Maths and data analysisGPT-6 SolMathematics without a score for GPT-5.4 mini, Reasoning 114.1 to 74.3
Facts and researchGPT-6 SolKnowledge 109.8 to 74.9, Search without a score for GPT-5.4 mini
Agents and workflowsGPT-6 SolAgents 107.2 to 79.0
Fast chat repliesGPT-5.4 mini111 to 191 tokens per second
Security analysisopenCybersecurity without a score for GPT-5.4 mini
Many requests on a small budgetGPT-5.4 mini$4 to $1.69 per 1M tokens
Finance, legal and medical textsGPT-6 SolFinance 101.3 to 75.7, Legal 104.8 to 73.1, Health without a score for GPT-5.4 mini
Images, screenshots and PDFsGPT-6 SolMultimodal 106.9 to 76.5

See for yourself: same task, one attempt

The same prompt for both models. We show the latest attempt without fixes; it does not count toward the overall index.

Pelican on a bicycle

Prompt

Generate an SVG of a pelican riding a bicycle

Task origin: Simon Willison

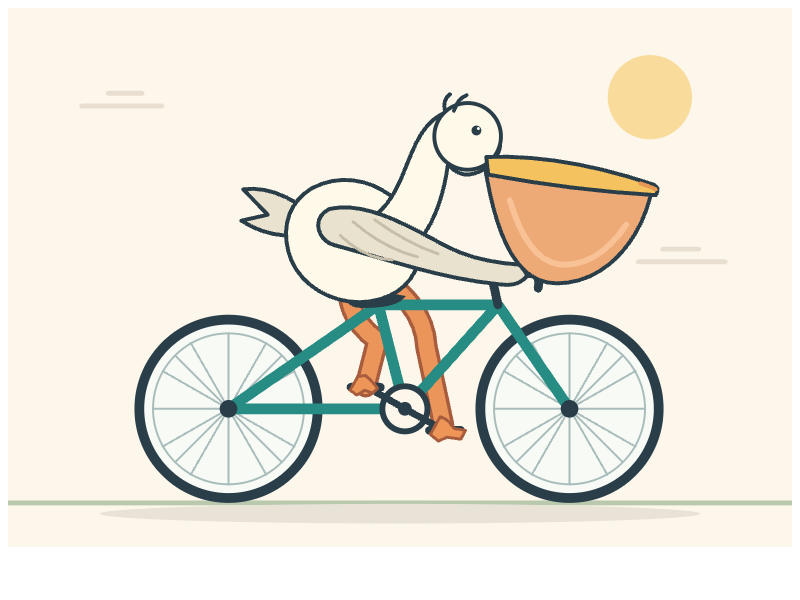
GPT-6 Sol

GPT-6 Sol: Pelican on a bicycle
A community classic for free-form SVG drawing.

Oct 1, 2026 · 80 s · $0.04

Test details
Run date
Oct 1, 2026
API provider
openrouter
Requested API model
openai/gpt-6-sol
Reasoning setting
high
Token limit including reasoning
8,192 tokens
Output tokens
4,389 tokens
Cost of the attempt
$0.0439
Response time
80.5 s
API model reported in response
openai/gpt-6-sol
Pinned endpoint
OpenAI | openai/gpt-6-sol-20260922
Temperature
Provider default
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating

Visually reviewed. This individual test does not establish overall model quality.

GPT-5.4 mini
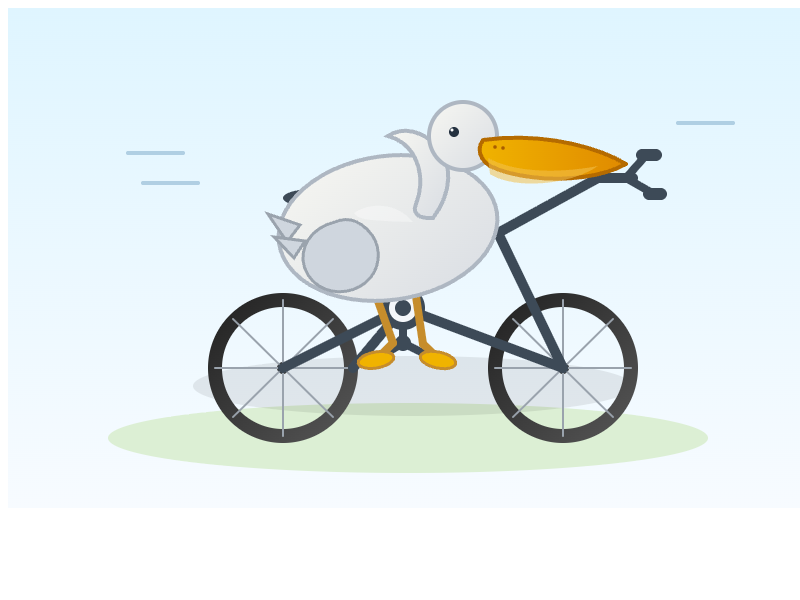
GPT-5.4 mini: Pelican on a bicycle
A community classic for free-form SVG drawing.

Oct 2, 2026 · 14 s · $0.01

Test details
Run date
Oct 2, 2026
API provider
openrouter
Requested API model
openai/gpt-5.4-mini
Reasoning setting
high
Token limit including reasoning
8,192 tokens
Output tokens
3,142 tokens
Cost of the attempt
$0.0142
Response time
13.5 s
API model reported in response
openai/gpt-5.4-mini
Pinned endpoint
OpenAI | openai/gpt-5.4-mini-20260317
Temperature
Provider default
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating

Visually reviewed. This individual test does not establish overall model quality.

Earlier attempts (2)

  • Oct 1, 2026API request failedReasoning setting: high
  • Sep 7, 2026API request failedReasoning setting: high
SVG short test

SVG short test

One SVG task with the same fixed settings for every model, without hidden thinking.

Prompt

Return only one standalone SVG of a pelican riding a bicycle. Use viewBox="0 0 800 600", simple shapes, two clearly visible wheels and a recognizable pelican with a long beak. At most 30 SVG elements and 1800 characters. No Markdown, explanations, comments, scripts, animation, CSS or external resources.

GPT-6 Sol

Unavailable in this round

GPT-5.4 mini

Unavailable in this round

GPT-6 Sol and GPT-5.4 mini in the overall index

Every model with a place in the overall index, both models of this matchup highlighted. You can add or hide other models.

Overall index (Gradually Meta-Score v4)

20 of 92 models

5 models in this view are measured at a lower reasoning effort than max in the overall index. Dashed column: lower reasoning effort than the top.

Claude Opus 5.5max126.1
Gemini 4 Carbonhigh125.8
Claude Fable 5.1max123.8
Claude Sonnet 5.5max122.8
Gemini 4 Argonhigh122.3
GPT-6 Astramax121.3
GPT-6.1 Solmax119.2
Muse Wonder Fullmax118.3
Claude Opus 5max117.2
Muse Wondermax113.4
Kimi K3.1 Promax112.9
Claude Fable 5max112.5
GPT-6 Solmax110.5
GPT-5.6 Solmax108.7
Muse Spark 1.3max107.4
Gemini 3.7 Flashhigh107.1
DeepSeek V4.1 Flash 1017max106.6
Gemini 3.8 Flashhigh106.5
GPT-6.1 Terramax105.3
GPT-5.4 minixhigh75.6

Popularity compared

How often the models are searched for, used and mentioned, on a scale from 0 to 100.

GPT-6 Sol is more popular than GPT-5.4 mini: 73 to 59 out of 100.

Over time

Weekly values from October 18, 2026 to November 7, 2026

GPT-6 SolGPT-5.4 mini

All data side by side

The better value is bold. For the overall index only when the gap is clear.

MetricGPT-6 SolGPT-5.4 mini
Intelligence
Overall indexpoints, 100 = reference group average, higher is better110.575.6
RankRank 13 of 92Rank 56 of 92
Price per 1M tokens
Inputwhat you send$2above 272,000 tokens: $4$0.75
Outputwhat the model writes$10above 272,000 tokens: $15$4.50
Cost per task (own tests)average of 1 original-protocol task both models passed (SVG short test not included)$0.044$0.014
Speed
Tokens per second111191
Popularity
Popularitysearch, usage and mentions, 0 to 10073Rank 3 of 78559Rank 38 of 785
Technical
Context windowhow much text the model reads at once1.05 M tokens≈ 1,580 A4 pages400,000 tokens≈ 600 A4 pages
Knowledge cutoffApr 20, 2026Aug 31, 2025
ReleasedSep 22, 2026Mar 17, 2026
AvailabilityActiveActive
Open weightsnono

Prices without caching or batch discounts · Page count as a rule of thumb from Artificial Analysis

Is there a better choice?

Successor of GPT-6 SolGPT-6.1 Sol

Overall index 119.2, rank 7$2 input and $10 output per 1M tokens

GPT-5.4 mini vs. GPT-6.1 Sol
Cheaper than GPT-5.4 miniDeepSeek V4.1 Flash 1017

Overall index 106.6, rank 17$0.15 input and $0.60 output per 1M tokens

GPT-6 Sol vs. DeepSeek V4.1 Flash 1017
Best model in the overall indexClaude Opus 5.5

Overall index 126.1, rank 1$4 input and $20 output per 1M tokens

GPT-6 Sol vs. Claude Opus 5.5

Shared benchmarks

Single results from the same benchmark version, task and metric. A value is bold only with the same test setup and a clear gap.

A: GPT-6 SolB: GPT-5.4 mini

Code MigrationOverall · higher is betterTest setup not documented as identicalGPT-6 Sol: 57.2%GPT-5.4 mini: 12.9%Vals AIAs of 10/29/2026
EMBOverall · higher is betterTest setup not documented as identicalGPT-6 Sol: 71.5%GPT-5.4 mini: 45.4%Vals AIAs of 10/20/2026
Finance Agent (v2)Overall · higher is betterTest setup not documented as identicalGPT-6 Sol: 49.1%GPT-5.4 mini: 45.4%Vals AIAs of 10/29/2026
GDPval-AAOverall · higher is betterGPT-6 Sol: 1,466.3 eloGPT-5.4 mini: 1,021.8 eloArtificial AnalysisAs of 11/07/2026
Legal Research BenchOverall · All-pass · higher is betterTest setup not documented as identicalGPT-6 Sol: 28.8%GPT-5.4 mini: 12.5%Vals AIAs of 11/05/2026
LMArena Code Arena WebDevOverall · higher is betterTest setup not documented as identicalGPT-6 Sol: 1,678GPT-5.4 mini: 1,397LMArenaAs of 10/28/2026
LMArena Text, Style ControlOverall · higher is betterTest setup not documented as identicalGPT-6 Sol: 1,458GPT-5.4 mini: 1,447LMArenaAs of 10/28/2026
LMArena Vision, Style ControlOverall · higher is betterTest setup not documented as identicalGPT-6 Sol: 1,266GPT-5.4 mini: 1,250LMArenaAs of 10/19/2026
MMMU-ProOverall · higher is betterGPT-6 Sol: 82.5%GPT-5.4 mini: 73.3%Artificial AnalysisAs of 11/07/2026
ProgramBenchOverall · higher is betterTest setup not documented as identicalGPT-6 Sol: 2%GPT-5.4 mini: 0%Vals AIAs of 11/05/2026
Show 54 more benchmarks
Tax Agent BenchOverall · higher is betterTest setup not documented as identicalGPT-6 Sol: 15.0%GPT-5.4 mini: 8.8%Vals AIAs of 11/05/2026
Terminal-Bench 4.0Overall · higher is betterTest setup not documented as identicalGPT-6 Sol: 44.4%GPT-5.4 mini: 2.5%Vals AIAs of 11/05/2026
Vibe Code Bench v1.1Overall · higher is betterTest setup not documented as identicalGPT-6 Sol: 87.8%GPT-5.4 mini: 48.0%Vals AIAs of 11/05/2026
Code MigrationCLI · higher is betterTest setup not documented as identicalGPT-6 Sol: 52.9%GPT-5.4 mini: 8.2%Vals AIAs of 10/29/2026
EMBComps · higher is betterTest setup not documented as identicalGPT-6 Sol: 73.3%GPT-5.4 mini: 40.5%Vals AIAs of 10/20/2026
Finance Agent (v2)Adjustments · higher is betterTest setup not documented as identicalGPT-6 Sol: 43.2%GPT-5.4 mini: 45.4%Vals AIAs of 10/29/2026
Legal Research BenchAdministrative / Regulatory · All-pass · higher is betterTest setup not documented as identicalGPT-6 Sol: 39.4%GPT-5.4 mini: 15.2%Vals AIAs of 11/05/2026
LMArena Code Arena WebDevHTML development · higher is betterTest setup not documented as identicalGPT-6 Sol: 1,680GPT-5.4 mini: 1,419LMArenaAs of 10/28/2026
LMArena Text, Style ControlBusiness, management and finance · higher is betterTest setup not documented as identicalGPT-6 Sol: 1,448GPT-5.4 mini: 1,459LMArenaAs of 10/28/2026
LMArena Vision, Style ControlCreative writing with images · higher is betterTest setup not documented as identicalGPT-6 Sol: 1,252GPT-5.4 mini: 1,226LMArenaAs of 10/19/2026
ProgramBenchAlmost Resolved · higher is betterTest setup not documented as identicalGPT-6 Sol: 32.5%GPT-5.4 mini: 3.0%Vals AIAs of 11/05/2026
Tax Agent BenchControversy & Precedence Analysis · higher is betterTest setup not documented as identicalGPT-6 Sol: 6.7%GPT-5.4 mini: 3.3%Vals AIAs of 11/05/2026
Terminal-Bench 4.0Hardware · higher is betterTest setup not documented as identicalGPT-6 Sol: 6.7%GPT-5.4 mini: 0.0%Vals AIAs of 11/05/2026
Code MigrationCOBOL · higher is betterTest setup not documented as identicalGPT-6 Sol: 70.0%GPT-5.4 mini: 27.1%Vals AIAs of 10/29/2026
EMBDataroom · higher is betterTest setup not documented as identicalGPT-6 Sol: 83.9%GPT-5.4 mini: 48.3%Vals AIAs of 10/20/2026
Finance Agent (v2)All-Pass · higher is betterTest setup not documented as identicalGPT-6 Sol: 36.0%GPT-5.4 mini: 32.4%Vals AIAs of 10/29/2026
Legal Research BenchAdministrative / Regulatory · Weighted partial credit (weighted pass) · higher is betterTest setup not documented as identicalGPT-6 Sol: 80.5%GPT-5.4 mini: 69.7%Vals AIAs of 11/05/2026
LMArena Code Arena WebDevReact development · higher is betterTest setup not documented as identicalGPT-6 Sol: 1,680GPT-5.4 mini: 1,386LMArenaAs of 10/28/2026
LMArena Text, Style ControlChinese · higher is betterTest setup not documented as identicalGPT-6 Sol: 1,485GPT-5.4 mini: 1,474LMArenaAs of 10/28/2026
LMArena Vision, Style ControlDiagram understanding · higher is betterTest setup not documented as identicalGPT-6 Sol: 1,303GPT-5.4 mini: 1,283LMArenaAs of 10/19/2026
ProgramBenchFully Resolved · higher is betterTest setup not documented as identicalGPT-6 Sol: 2%GPT-5.4 mini: 0%Vals AIAs of 11/05/2026
Tax Agent BenchControversy & Precedence Analysis (weighted pass) · higher is betterTest setup not documented as identicalGPT-6 Sol: 50.7%GPT-5.4 mini: 32.2%Vals AIAs of 11/05/2026
Terminal-Bench 4.0Media · higher is betterTest setup not documented as identicalGPT-6 Sol: 41.7%GPT-5.4 mini: 0.0%Vals AIAs of 11/05/2026
Code MigrationCode Quality · higher is betterTest setup not documented as identicalGPT-6 Sol: 4.375 / 5GPT-5.4 mini: 3.053 / 5Vals AIAs of 10/29/2026
EMBDCF · higher is betterTest setup not documented as identicalGPT-6 Sol: 63.1%GPT-5.4 mini: 40.6%Vals AIAs of 10/20/2026
Finance Agent (v2)Comparables · higher is betterTest setup not documented as identicalGPT-6 Sol: 40.8%GPT-5.4 mini: 40.3%Vals AIAs of 10/29/2026
Legal Research BenchBusiness & Commercial · All-pass · higher is betterTest setup not documented as identicalGPT-6 Sol: 27.9%GPT-5.4 mini: 11.6%Vals AIAs of 11/05/2026
LMArena Code Arena WebDevWeb development · higher is betterTest setup not documented as identicalGPT-6 Sol: 1,678GPT-5.4 mini: 1,397LMArenaAs of 10/28/2026
LMArena Text, Style ControlCoding · higher is betterTest setup not documented as identicalGPT-6 Sol: 1,519GPT-5.4 mini: 1,495LMArenaAs of 10/28/2026
LMArena Vision, Style ControlEnglish · higher is betterTest setup not documented as identicalGPT-6 Sol: 1,255GPT-5.4 mini: 1,248LMArenaAs of 10/19/2026
ProgramBenchRaw Pass Rate · higher is betterTest setup not documented as identicalGPT-6 Sol: 81.9%GPT-5.4 mini: 54.4%Vals AIAs of 11/05/2026
Tax Agent BenchCurrent & Temporal Analysis · higher is betterTest setup not documented as identicalGPT-6 Sol: 23.2%GPT-5.4 mini: 10.0%Vals AIAs of 11/05/2026
Terminal-Bench 4.0ML · higher is betterTest setup not documented as identicalGPT-6 Sol: 45.5%GPT-5.4 mini: 0.0%Vals AIAs of 11/05/2026
EMBLBO · higher is betterTest setup not documented as identicalGPT-6 Sol: 59.4%GPT-5.4 mini: 41.6%Vals AIAs of 10/20/2026
Finance Agent (v2)Disclosure Analysis · higher is betterTest setup not documented as identicalGPT-6 Sol: 55.6%GPT-5.4 mini: 48.3%Vals AIAs of 10/29/2026
Legal Research BenchBusiness & Commercial · Weighted partial credit (weighted pass) · higher is betterTest setup not documented as identicalGPT-6 Sol: 80.4%GPT-5.4 mini: 71.2%Vals AIAs of 11/05/2026
LMArena Text, Style ControlCreative writing · higher is betterTest setup not documented as identicalGPT-6 Sol: 1,435GPT-5.4 mini: 1,402LMArenaAs of 10/28/2026
LMArena Vision, Style ControlHomework · higher is betterTest setup not documented as identicalGPT-6 Sol: 1,306GPT-5.4 mini: 1,291LMArenaAs of 10/19/2026
Tax Agent BenchCurrent & Temporal Analysis (weighted pass) · higher is betterTest setup not documented as identicalGPT-6 Sol: 56.1%GPT-5.4 mini: 38.6%Vals AIAs of 11/05/2026
Terminal-Bench 4.0Operations · higher is betterTest setup not documented as identicalGPT-6 Sol: 40.7%GPT-5.4 mini: 0.0%Vals AIAs of 11/05/2026
EMBM&A · higher is betterTest setup not documented as identicalGPT-6 Sol: 83.0%GPT-5.4 mini: 49.8%Vals AIAs of 10/20/2026
Finance Agent (v2)Earnings Analysis · higher is betterTest setup not documented as identicalGPT-6 Sol: 72.4%GPT-5.4 mini: 65.3%Vals AIAs of 10/29/2026
Legal Research BenchCivil Litigation · All-pass · higher is betterTest setup not documented as identicalGPT-6 Sol: 18.5%GPT-5.4 mini: 14.8%Vals AIAs of 11/05/2026
LMArena Text, Style ControlEnglish · higher is betterTest setup not documented as identicalGPT-6 Sol: 1,459GPT-5.4 mini: 1,450LMArenaAs of 10/28/2026
LMArena Vision, Style ControlOptical character recognition · higher is betterTest setup not documented as identicalGPT-6 Sol: 1,285GPT-5.4 mini: 1,262LMArenaAs of 10/19/2026
Tax Agent BenchFact-Pattern Analysis · higher is betterTest setup not documented as identicalGPT-6 Sol: 16.3%GPT-5.4 mini: 7.0%Vals AIAs of 11/05/2026
Terminal-Bench 4.0Science · higher is betterTest setup not documented as identicalGPT-6 Sol: 42.9%GPT-5.4 mini: 2.4%Vals AIAs of 11/05/2026
EMBMisc · higher is betterTest setup not documented as identicalGPT-6 Sol: 65.0%GPT-5.4 mini: 46.3%Vals AIAs of 10/20/2026
Finance Agent (v2)Financial Modeling · higher is betterTest setup not documented as identicalGPT-6 Sol: 19.3%GPT-5.4 mini: 19.6%Vals AIAs of 10/29/2026
Legal Research BenchCivil Litigation · Weighted partial credit (weighted pass) · higher is betterTest setup not documented as identicalGPT-6 Sol: 78.0%GPT-5.4 mini: 67.3%Vals AIAs of 11/05/2026
LMArena Text, Style ControlEntertainment, sports and media · higher is betterTest setup not documented as identicalGPT-6 Sol: 1,430GPT-5.4 mini: 1,409LMArenaAs of 10/28/2026
Tax Agent BenchFact-Pattern Analysis (weighted pass) · higher is betterTest setup not documented as identicalGPT-6 Sol: 49.9%GPT-5.4 mini: 36.5%Vals AIAs of 11/05/2026
Terminal-Bench 4.0Security · higher is betterTest setup not documented as identicalGPT-6 Sol: 60%GPT-5.4 mini: 0%Vals AIAs of 11/05/2026
EMBOperating · higher is betterTest setup not documented as identicalGPT-6 Sol: 72.9%GPT-5.4 mini: 50.8%Vals AIAs of 10/20/2026

More comparisons

Compare GPT-6 Sol and GPT-5.4 mini with the models people compare them with most often.

Compare another matchup

The most popular comparisons

  1. 1GPT-6 Sol vs. GPT-5.6 Sol
  2. 2GPT-6 Luna vs. GPT-5.4 mini
  3. 3GPT-6 Sol vs. DeepSeek-V4.1-Flash
  4. 4GPT-6 Sol vs. Gemini 3.8 Flash
  5. 5GPT-6 Sol vs. GPT-5.6 Terra
  6. 6GPT-6 Astra vs. GPT-6 Sol
  7. 7GPT-6 Sol vs. GLM-5.3-Flash
  8. 8Claude Sonnet 5.5 vs. GPT-6 Sol
  9. 9GPT-6.1 Sol vs. GPT-5.4 mini
Show all 41 comparisons
  1. 10GPT-6 Sol vs. Gemini 3.1 Pro Preview
  2. 11Claude Opus 4.8 vs. GPT-6 Sol
  3. 12GPT-5.6 Luna vs. GPT-5.4 mini
  4. 13GPT-6 Sol vs. GPT-5.4
  5. 14GPT-6 Sol vs. DeepSeek V4.1 Flash 1017
  6. 15GPT-6 Sol vs. Qwen 3.8 27B
  7. 16GPT-6 Sol vs. GPT-6 Luna
  8. 17GPT-6 Sol vs. Kimi K3.1 Pro
  9. 18Claude Sonnet 4.6 vs. GPT-6 Sol
  10. 19GPT-5.4 mini vs. Gemini 3.8 Flash
  11. 20GPT-6 Sol vs. Grok 4.7
  12. 21Claude Haiku 5.5 vs. GPT-6 Sol
  13. 22Claude Opus 5.5 vs. GPT-6 Sol
  14. 23GPT-6 Sol vs. Qwen 3.8 Max 0902
  15. 24Claude Sonnet 5 vs. GPT-6 Sol
  16. 25GPT-6 Sol vs. Kimi K3
  17. 26Claude Fable 5.1 vs. GPT-6 Sol
  18. 27GPT-6 Sol vs. DeepSeek-V4-Pro
  19. 28Claude Haiku 5.5 vs. GPT-5.4 mini
  20. 29GPT-6 Sol vs. GPT-5.6 Luna
  21. 30Claude Opus 5 vs. GPT-6 Sol
  22. 31GPT-5.4 mini vs. Qwen 3.8 27B
  23. 32GPT-6 Sol vs. Mistral Large 4
  24. 33GPT-6 Sol vs. Gemini 4 Argon
  25. 34GPT-6 Sol vs. Gemini 3.6 Flash
  26. 35Claude Opus 4.6 vs. GPT-6 Sol
  27. 36GPT-6 Sol vs. Muse Wonder
  28. 37Claude Haiku 4.5 vs. GPT-6 Sol
  29. 38GPT-6 Sol vs. GPT-5.5
  30. 39GPT-6.1 Terra vs. GPT-6 Sol
  31. 40GPT-6.1 Terra vs. GPT-5.4 mini
  32. 41GPT-6 Sol vs. Gemini 4 Carbon