OpenAIMistral AILLM matchup

GPT-6.1 Solvs.Mistral Large 3

Which one is better?

GPT-6.1 Sol performs better than Mistral Large 3, but costs 4 times (input) and 6.7 times (output) as much.

GPT-6.1 Sol ahead
IntelligenceOverall index, 100 points = average
117.5

GPT-6.1 Sol

Rank 9

32.7

Mistral Large 3

Rank 95

Mistral Large 3 faster
SpeedTokens per second
54

GPT-6.1 Sol

64

Mistral Large 3

Mistral Large 3 cheaper
Price$ per 1M tokens
$4

GPT-6.1 Sol

$0.75

Mistral Large 3

Popularity0 to 100
n/a

GPT-6.1 Sol

48

Mistral Large 3

Rank 146 of 485

Above 272,000 tokens of context, GPT-6.1 Sol costs more: $4 input and $15 output per 1M tokens.

Choose GPT-6.1 Sol for

MathematicsCodingReasoningGeneralKnowledgeMultimodalHealthAgentsLegalFinance

No clear advantage for Mistral Large 3.

Where is the difference?

Strengths at a glance

GPT-6.1 SolMistral Large 3Median of all ranked models

6511516515CodingGPT-6.1 SolReasoningGPT-6.1 SolMathematicsGPT-6.1 SolKnowledgeGPT-6.1 SolAgentsGPT-6.1 SolGeneralGPT-6.1 SolMultimodalGPT-6.1 SolFinanceGPT-6.1 SolLegalGPT-6.1 SolHealthGPT-6.1 Sol
CodingGPT-6.1 Sol ahead
GPT-6.1 Sol120.6Rank 8
Mistral Large 332.0Rank 113
Median of ranked models87.5

95 % range: GPT-6.1 Sol 113.7 to 127.5, Mistral Large 3 19.1 to 44.9.

AreaGPT-6.1 SolMistral Large 3

The same values and verdicts as the bars below. In the close-up the net starts at 15 points, just below the weaker model's lowest value; the reference group average is 100.

GPT-6.1 Sol is ahead in 10 of 10 areas, Mistral Large 3 in none.

GPT-6.1 Sol ahead: 10

Areas in the overall index
MathematicsGPT-6.1 Sol +102124.1 to 22.2
CodingGPT-6.1 Sol +89120.6 to 32.0
ReasoningGPT-6.1 Sol +88122.7 to 34.3
GeneralGPT-6.1 Sol +86119.0 to 33.5
KnowledgeGPT-6.1 Sol +85123.7 to 38.5
MultimodalGPT-6.1 Sol +85118.0 to 32.8
AgentsGPT-6.1 Sol +78112.0 to 34.3
Specialist fields
HealthGPT-6.1 Sol +79110.2 to 30.9
LegalGPT-6.1 Sol +67107.0 to 39.7
FinanceGPT-6.1 Sol +64105.8 to 41.3

Bar length shows the gap in index points (full width 15 points, one standard deviation of the reference group). Solid means clearly ahead, hatched not certain yet, a thin grey bar level.

Show 4 more areas that do not count toward the overall index
Cybersecurityonly GPT-6.1 Sol has a score
Searchonly GPT-6.1 Sol has a score
Productivityonly GPT-6.1 Sol has a score
Educationonly GPT-6.1 Sol has a score

Bar length shows the gap in index points (full width 15 points, one standard deviation of the reference group). Solid means clearly ahead, hatched not certain yet, a thin grey bar level.

Which model for which task?

Everyday tasks, translated from the area values above. Each row names the values it rests on.

Writing and debugging codeGPT-6.1 SolCoding 120.6 to 32.0
Maths and data analysisGPT-6.1 SolMathematics 124.1 to 22.2, Reasoning 122.7 to 34.3
Facts and researchGPT-6.1 SolKnowledge 123.7 to 38.5, Search without a score for Mistral Large 3
Agents and workflowsGPT-6.1 SolAgents 112.0 to 34.3
Fast chat repliesMistral Large 354 to 64 tokens per second
Security analysisopenCybersecurity without a score for Mistral Large 3
Many requests on a small budgetMistral Large 3$4 to $0.75 per 1M tokens
Finance, legal and medical textsGPT-6.1 SolFinance 105.8 to 41.3, Legal 107.0 to 39.7, Health 110.2 to 30.9
Images, screenshots and PDFsGPT-6.1 SolMultimodal 118.0 to 32.8

GPT-6.1 Sol vs. Mistral Large 3 in our own test

The same prompt for both models. We show the latest attempt without fixes; it does not count toward the overall index.

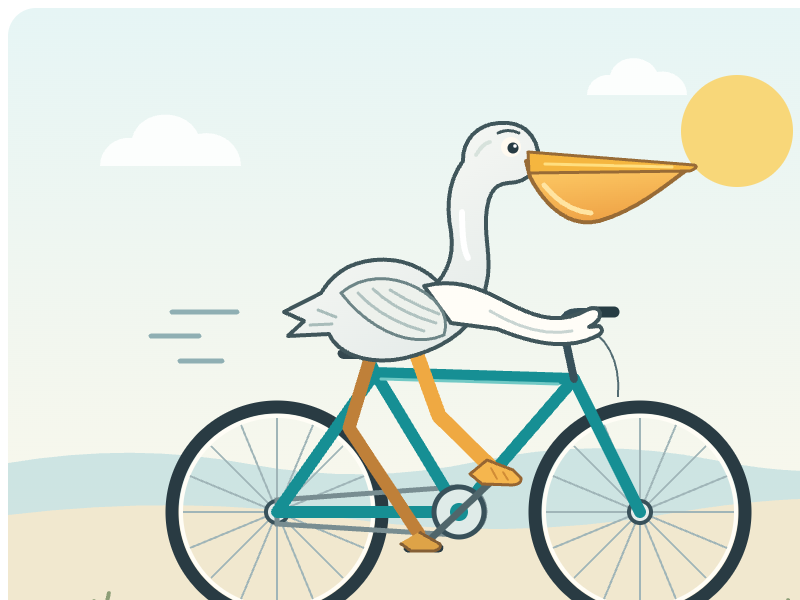
Pelican on a bicycle

Prompt

Generate an SVG of a pelican riding a bicycle

Task origin: Simon Willison

GPT-6.1 Sol

GPT-6.1 Sol: Pelican on a bicycle
A community classic for free-form SVG drawing.

Oct 1, 2026 · 84 s · $0.04

Test details
Run date
Oct 1, 2026
API provider
openrouter
Requested API model
openai/gpt-6.1-sol
Reasoning setting
high
Token limit including reasoning
8,192 tokens
Output tokens
3,583 tokens
Cost of the attempt
$0.0359
Response time
83.6 s
API model reported in response
openai/gpt-6.1-sol
Pinned endpoint
OpenAI | openai/gpt-6.1-sol-20260929
Temperature
Provider default
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating

Visually reviewed. This individual test does not establish overall model quality.

Mistral Large 3
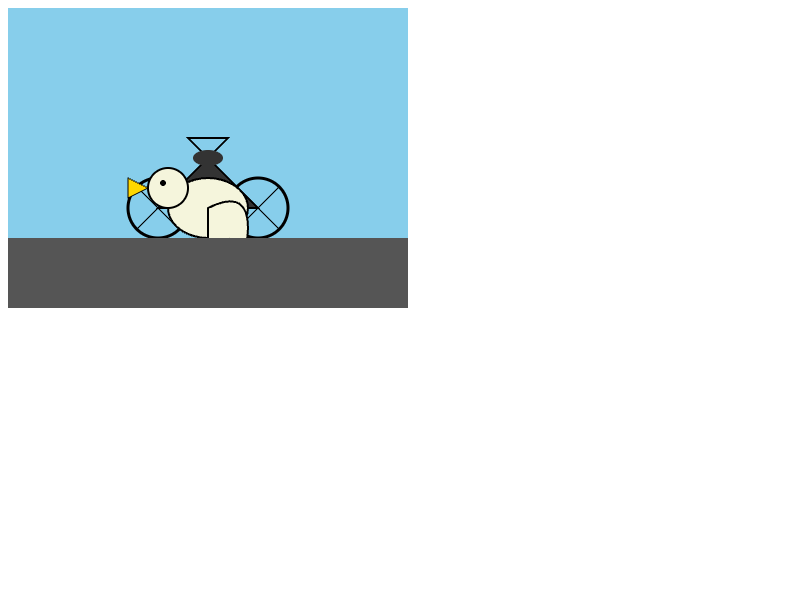
Mistral Large 3: Pelican on a bicycle
A community classic for free-form SVG drawing.

Oct 1, 2026 · 14 s · $0.0022

Test details
Run date
Oct 1, 2026
API provider
openrouter
Requested API model
mistralai/mistral-large-2512
Reasoning setting
not specified
Token limit including reasoning
8,192 tokens
Output tokens
1,451 tokens
Cost of the attempt
$0.0022
Response time
14.2 s
API model reported in response
mistralai/mistral-large-2512
Pinned endpoint
Mistral | mistralai/mistral-large-2512
Temperature
Provider default
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating
Reasoning (model default)
no reasoning mode Source

Visually reviewed. This individual test does not establish overall model quality.

Earlier attempts (1)

  • Sep 7, 2026API request failedReasoning setting: not specified
SVG short test

SVG short test

One SVG task with the same fixed settings for every model, without hidden thinking.

Prompt

Return only one standalone SVG of a pelican riding a bicycle. Use viewBox="0 0 800 600", simple shapes, two clearly visible wheels and a recognizable pelican with a long beak. At most 30 SVG elements and 1800 characters. No Markdown, explanations, comments, scripts, animation, CSS or external resources.

GPT-6.1 Sol

Unavailable in this round

Mistral Large 3

API request failed. The model was not evaluated.

GPT-6.1 Sol and Mistral Large 3 in the overall index

Every model with a place in the overall index, both models of this matchup highlighted. You can add or hide other models.

Overall index (Gradually Meta-Score v5)

20 of 95 models

Claude Fable 5.2max130.9
Gemini 4 Carbonhigh127.0
Claude Opus 5.5max125.7
Claude Fable 5.1max124.1
Claude Sonnet 5.5max121.9
Gemini 4 Argonhigh121.2
GPT-6 Astramax119.6
Muse Wonder Fullmax118.4
GPT-6.1 Solmax117.5
Claude Opus 5max117.3
Muse Wondermax113.7
Claude Fable 5max112.8
Kimi K3.1 Promax112.6
Muse Ember 1.0max110.5
GPT-5.6 Solmax109.3
GPT-6 Solmax108.4
Gemini 3.7 Flashhigh107.7
DeepSeek V4.1 Flash 1017max107.1
GPT-6.1 Terramax106.5
Mistral Large 3none32.7

Popularity compared

How often the models are searched for, used and mentioned, on a scale from 0 to 100.

GPT-6.1 Sol has no popularity score yet.

Over time

Weekly values from October 18, 2026 to November 14, 2026

GPT-6.1 SolMistral Large 3

All data side by side

The better value is bold. For the overall index only when the gap is clear.

MetricGPT-6.1 SolMistral Large 3
Intelligence
Overall indexpoints, 100 = reference group average, higher is better117.532.7
RankRank 9 of 95Rank 95 of 95
Price per 1M tokens
Inputwhat you send$2above 272,000 tokens: $4$0.50
Outputwhat the model writes$10above 272,000 tokens: $15$1.50
Cost per task (own tests)average of 1 original-protocol task both models passed (SVG short test not included)$0.036$0.002
Speed
Tokens per second5464
Popularity
Popularitysearch, usage and mentions, 0 to 100n/a48Rank 146 of 485
Technical
Context windowhow much text the model reads at once1.05 M tokens≈ 1,580 A4 pages262,144 tokens≈ 390 A4 pages
Knowledge cutoffApr 30, 2026n/a
ReleasedSep 29, 2026Dec 2, 2025
AvailabilityActiveActive
Open weightsnoyes

Prices without caching or batch discounts · Page count as a rule of thumb from Artificial Analysis

Is there a better choice?

Cheaper than Mistral Large 3Muse Ember 1.0

Overall index 110.5, rank 14$0.10 input and $0.50 output per 1M tokens

View profile
Best model in the overall indexClaude Fable 5.2

Overall index 130.9, rank 1$8 input and $40 output per 1M tokens

GPT-6.1 Sol vs. Claude Fable 5.2

Shared benchmarks

Single results from the same benchmark version, task and metric. A value is bold only with the same test setup and a clear gap.

A: GPT-6.1 SolB: Mistral Large 3

LMArena Code Arena WebDevOverall · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,743Mistral Large 3: 1,232LMArenaAs of 11/11/2026
LMArena Text, Style ControlOverall · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,481Mistral Large 3: 1,415LMArenaAs of 11/11/2026
LMArena Vision, Style ControlOverall · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,293Mistral Large 3: 1,200LMArenaAs of 11/09/2026
LMArena Code Arena WebDevHTML development · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,794Mistral Large 3: 1,240LMArenaAs of 11/11/2026
LMArena Text, Style ControlBusiness, management and finance · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,480Mistral Large 3: 1,411LMArenaAs of 11/11/2026
LMArena Vision, Style ControlChinese · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,348Mistral Large 3: 1,219LMArenaAs of 11/09/2026
LMArena Code Arena WebDevImage to WebDev · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,696Mistral Large 3: 1,362LMArenaAs of 11/10/2026
LMArena Text, Style ControlChinese · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,531Mistral Large 3: 1,431LMArenaAs of 11/11/2026
LMArena Vision, Style ControlCreative writing with images · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,303Mistral Large 3: 1,198LMArenaAs of 11/09/2026
LMArena Code Arena WebDevWeb development · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,743Mistral Large 3: 1,232LMArenaAs of 11/11/2026
Show 31 more benchmarks
LMArena Text, Style ControlCoding · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,540Mistral Large 3: 1,471LMArenaAs of 11/11/2026
LMArena Vision, Style ControlDiagram understanding · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,327Mistral Large 3: 1,233LMArenaAs of 11/09/2026
LMArena Text, Style ControlCreative writing · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,449Mistral Large 3: 1,375LMArenaAs of 11/11/2026
LMArena Vision, Style ControlEnglish · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,287Mistral Large 3: 1,208LMArenaAs of 11/09/2026
LMArena Text, Style ControlEnglish · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,491Mistral Large 3: 1,427LMArenaAs of 11/11/2026
LMArena Vision, Style ControlHomework · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,357Mistral Large 3: 1,203LMArenaAs of 11/09/2026
LMArena Text, Style ControlEntertainment, sports and media · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,453Mistral Large 3: 1,373LMArenaAs of 11/11/2026
LMArena Vision, Style ControlHumor · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,283Mistral Large 3: 1,186LMArenaAs of 11/09/2026
LMArena Text, Style ControlExcluding ties · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,494Mistral Large 3: 1,402LMArenaAs of 11/11/2026
LMArena Vision, Style ControlOptical character recognition · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,300Mistral Large 3: 1,214LMArenaAs of 11/09/2026
LMArena Text, Style ControlExpert prompts · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,525Mistral Large 3: 1,428LMArenaAs of 11/11/2026
LMArena Text, Style ControlFrench prompts · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,492Mistral Large 3: 1,432LMArenaAs of 11/11/2026
LMArena Text, Style ControlGerman prompts · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,484Mistral Large 3: 1,411LMArenaAs of 11/11/2026
LMArena Text, Style ControlHard prompts · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,504Mistral Large 3: 1,433LMArenaAs of 11/11/2026
LMArena Text, Style ControlHard prompts, English · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,515Mistral Large 3: 1,440LMArenaAs of 11/11/2026
LMArena Text, Style ControlInstruction following · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,482Mistral Large 3: 1,403LMArenaAs of 11/11/2026
LMArena Text, Style ControlJapanese prompts · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,462Mistral Large 3: 1,380LMArenaAs of 11/11/2026
LMArena Text, Style ControlKorean prompts · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,468Mistral Large 3: 1,364LMArenaAs of 11/11/2026
LMArena Text, Style ControlLegal and government · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,504Mistral Large 3: 1,422LMArenaAs of 11/11/2026
LMArena Text, Style ControlLife, physical and social science · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,501Mistral Large 3: 1,429LMArenaAs of 11/11/2026
LMArena Text, Style ControlLonger queries · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,488Mistral Large 3: 1,419LMArenaAs of 11/11/2026
LMArena Text, Style ControlMath · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,499Mistral Large 3: 1,402LMArenaAs of 11/11/2026
LMArena Text, Style ControlMathematical professions · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,521Mistral Large 3: 1,414LMArenaAs of 11/11/2026
LMArena Text, Style ControlMedicine and healthcare · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,483Mistral Large 3: 1,432LMArenaAs of 11/11/2026
LMArena Text, Style ControlMulti-turn · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,486Mistral Large 3: 1,419LMArenaAs of 11/11/2026
LMArena Text, Style ControlNon-English · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,468Mistral Large 3: 1,399LMArenaAs of 11/11/2026
LMArena Text, Style ControlPolish prompts · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,493Mistral Large 3: 1,416LMArenaAs of 11/11/2026
LMArena Text, Style ControlRussian prompts · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,485Mistral Large 3: 1,408LMArenaAs of 11/11/2026
LMArena Text, Style ControlSoftware and IT services · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,527Mistral Large 3: 1,457LMArenaAs of 11/11/2026
LMArena Text, Style ControlSpanish prompts · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,473Mistral Large 3: 1,405LMArenaAs of 11/11/2026
LMArena Text, Style ControlWriting, literature and language · higher is betterTest setup not documented as identicalGPT-6.1 Sol: 1,467Mistral Large 3: 1,390LMArenaAs of 11/11/2026

More comparisons

Compare GPT-6.1 Sol and Mistral Large 3 with the models people compare them with most often.

Compare another matchup

The most popular comparisons

  1. 1GPT-6.1 Sol vs. GPT-5.6 Sol
  2. 2GPT-6.1 Sol vs. GPT-6.1 Terra
  3. 3Claude Opus 5.5 vs. Mistral Large 3
  4. 4GPT-6.1 Sol vs. GPT-6 Astra
  5. 5GPT-6.1 Sol vs. GPT-5.6 Terra
  6. 6GLM-5.3 vs. Mistral Large 3
  7. 7DeepSeek-V4-Flash vs. Mistral Large 3
  8. 8GPT-6.1 Sol vs. Gemini 3.8 Flash
  9. 9Mistral Large 4 vs. Mistral Large 3
Show all 49 comparisons
  1. 10DeepSeek-V4.1-Flash vs. Mistral Large 3
  2. 11Claude Opus 5.5 vs. GPT-6.1 Sol
  3. 12Claude Sonnet 5.5 vs. GPT-6.1 Sol
  4. 13DeepSeek V4.1 Flash 1017 vs. Mistral Large 3
  5. 14GPT-6.1 Sol vs. GLM-5.3-Flash
  6. 15GPT-6.1 Sol vs. GPT-6 Luna
  7. 16GPT-6.1 Sol vs. Gemini 4 Carbon
  8. 17GPT-6.1 Sol vs. DeepSeek-V4.1-Flash
  9. 18Claude Opus 4.8 vs. GPT-6.1 Sol
  10. 19GPT-6.1 Sol vs. Gemini 4 Argon
  11. 20GPT-6.1 Sol vs. Kimi K3.1 Pro
  12. 21GPT-6.1 Sol vs. DeepSeek-V4-Flash
  13. 22GPT-6.1 Sol vs. GPT-5.4 mini
  14. 23GPT-6.1 Sol vs. GPT-5.4
  15. 24GPT-6.1 Sol vs. DeepSeek V4.1 Flash 1017
  16. 25GPT-6.1 Sol vs. Qwen 3.8 Max 0902
  17. 26Claude Sonnet 4.6 vs. GPT-6.1 Sol
  18. 27Claude Opus 4.6 vs. GPT-6.1 Sol
  19. 28GPT-6.1 Sol vs. GPT-5.6 Luna
  20. 29Claude Sonnet 5 vs. GPT-6.1 Sol
  21. 30Claude Opus 5 vs. GPT-6.1 Sol
  22. 31GPT-6.1 Sol vs. GPT-5.5
  23. 32Claude Haiku 5.5 vs. GPT-6.1 Sol
  24. 33GPT-6.1 Sol vs. Grok 4.7
  25. 34Claude Sonnet 4.5 vs. GPT-6.1 Sol
  26. 35GPT-6.1 Sol vs. Gemini 3.5 Flash
  27. 36Claude Opus 4.7 vs. GPT-6.1 Sol
  28. 37GPT-6.1 Sol vs. GLM-5.3
  29. 38Claude Fable 5.2 vs. GPT-6.1 Sol
  30. 39GPT-6.1 Sol vs. Gemini 3.7 Flash
  31. 40GPT-6.1 Sol vs. Qwen 3.8 27B
  32. 41Claude Fable 5.1 vs. GPT-6.1 Sol
  33. 42GPT-6.1 Sol vs. Gemini 3.1 Pro Preview
  34. 43GPT-6.1 Sol vs. Gemini 3.6 Flash
  35. 44GPT-6.1 Sol vs. Kimi K3
  36. 45Claude Fable 5 vs. GPT-6.1 Sol
  37. 46GPT-6.1 Sol vs. DeepSeek-V4-Pro
  38. 47GPT-6.1 Sol vs. Muse Wonder
  39. 48Claude Haiku 4.5 vs. GPT-6.1 Sol
  40. 49Claude Opus 4.5 vs. GPT-6.1 Sol