OpenAIDeepSeekLLM matchup
GPT-5.4vs.DeepSeek-V4-Flash
Which one is better?
DeepSeek-V4-Flash does not have enough benchmark results yet. DeepSeek-V4-Flash is cheaper: GPT-5.4 costs 25 times (input) and 35.7 times (output) as much.
GPT-5.4
Rank 50
DeepSeek-V4-Flash
not ranked yet
GPT-5.4
DeepSeek-V4-Flash
GPT-5.4
DeepSeek-V4-Flash
GPT-5.4
DeepSeek-V4-Flash
Rank 8 of 511
Above 272,000 tokens of context, GPT-5.4 costs more: $5 input and $22.50 output per 1M tokens.
Where is the difference?
Neither model is clearly ahead in any of the 9 areas.
too little data: 9
Bar length shows the gap in index points (full width 15 points, one standard deviation of the reference group). Solid means clearly ahead, hatched not certain yet, a thin grey bar level.
Which model for which task?
Everyday tasks, translated from the area values above. Each row names the values it rests on.
GPT-5.4 vs. DeepSeek-V4-Flash in our own test
The same prompt for both models. We show the latest attempt without fixes; it does not count toward the overall index.
GPT-5.4
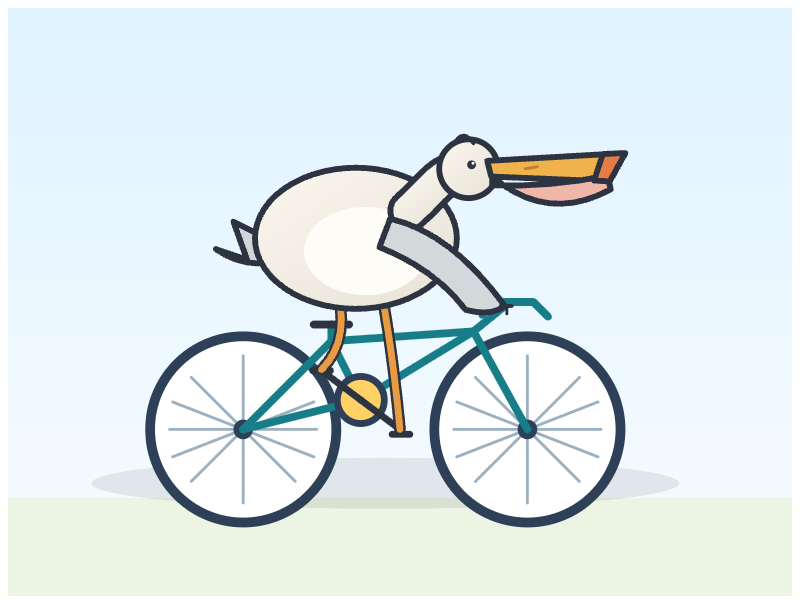
Oct 1, 2026 · 117 s · $0.11
Test details
- Run date
- Oct 1, 2026
- API provider
- openrouter
- Requested API model
- openai/gpt-5.4
- Reasoning setting
- high
- Token limit including reasoning
- 8,192 tokens
- Output tokens
- 7,339 tokens
- Cost of the attempt
- $0.1101
- Response time
- 116.8 s
- API model reported in response
- openai/gpt-5.4
- Pinned endpoint
- OpenAI | openai/gpt-5.4-20260305
- Temperature
- Provider default
- Test protocol
- community-visual-tests-v1
- Technical checks
- Passed, not a quality rating
Visually reviewed. This individual test does not establish overall model quality.
Earlier attempts (1)
- Sep 7, 2026API request failedReasoning setting: high
DeepSeek-V4-Flash
The response reached the token limit. No complete recording is available.
Oct 5, 2026 · 98 s · $0.0011
Not yet visually reviewed. A successful recording does not confirm correct physics or full compliance with the prompt.
Test details
- Run date
- Oct 5, 2026
- API provider
- openrouter
- Requested API model
- deepseek/deepseek-v4-flash-0731
- Reasoning setting
- high
- Token limit including reasoning
- 8,192 tokens
- Output tokens
- 8,192 tokens
- Cost of the attempt
- $0.0011
- Response time
- 97.8 s
- API model reported in response
- deepseek/deepseek-v4-flash-0731
- Pinned endpoint
- StreamLake | deepseek/deepseek-v4-flash-20260731
- Temperature
- Provider default
- Test protocol
- community-visual-tests-v1
- Technical checks
- Failed
Earlier attempts (3)
- Oct 2, 2026API request failedReasoning setting: high
- Oct 1, 2026API request failedReasoning setting: high
- Sep 7, 2026API request failedReasoning setting: high
SVG short test
SVG short test
One SVG task with the same fixed settings for every model, without hidden thinking.
Prompt
Return only one standalone SVG of a pelican riding a bicycle. Use viewBox="0 0 800 600", simple shapes, two clearly visible wheels and a recognizable pelican with a long beak. At most 30 SVG elements and 1800 characters. No Markdown, explanations, comments, scripts, animation, CSS or external resources.
GPT-5.4
Unavailable in this round
DeepSeek-V4-Flash
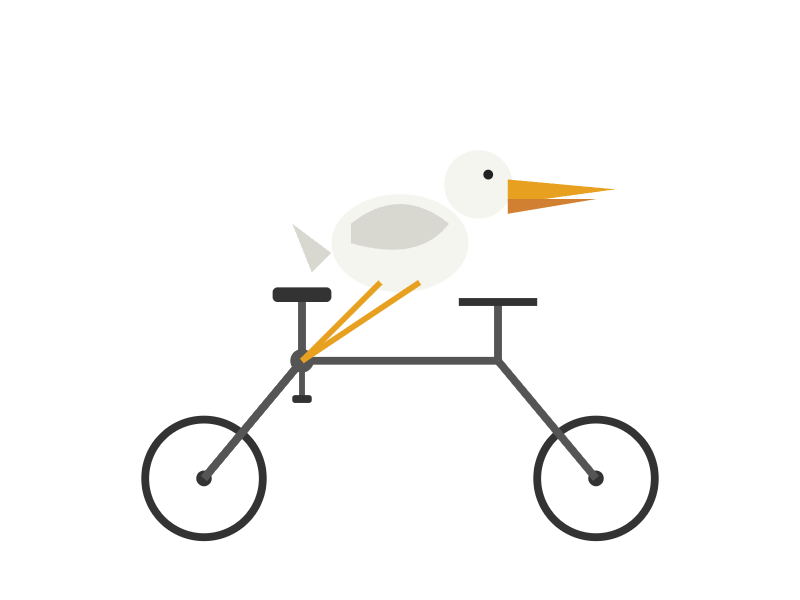
Oct 14, 2026 · $0.0001
Test details
- Test run
- Oct 14, 2026
- Provider
- deepinfra/fp8
- API model
- deepseek/deepseek-v4-flash-0731
- Output
- 798 tokens
- Reasoning
- API reports 0 reasoning tokens
- Cost of the attempt
- $0.0001
- Test round
- 43b8c5c46830
Popularity compared
How often the models are searched for, used and mentioned, on a scale from 0 to 100.
GPT-5.4 has no popularity score yet.
Over time
Weekly values from October 18, 2026 to November 17, 2026
GPT-5.4DeepSeek-V4-Flash
All data side by side
The better value is bold. For the overall index only when the gap is clear.
| Metric | GPT-5.4 | DeepSeek-V4-Flash |
|---|---|---|
| Intelligence | ||
| Overall indexpoints, 100 = reference group average, higher is better | 86.4 | n/a |
| Rank | Rank 50 of 95 | not ranked yet |
| Price per 1M tokens | ||
| Inputwhat you send | $2.50above 272,000 tokens: $5 | $0.10 |
| Outputwhat the model writes | $15above 272,000 tokens: $22.50 | $0.42 |
| Cost per task (own tests)average of 2 original-protocol tasks both models passed (SVG short test not included) | $0.23 | $0.002 |
| Speed | ||
| Tokens per second | 62 | 89 |
| Popularity | ||
| Popularitysearch, usage and mentions, 0 to 100 | n/a | 85Rank 8 of 511 |
| Technical | ||
| Context windowhow much text the model reads at once | 1.05 M tokens≈ 1,580 A4 pages | 1 M tokens≈ 1,500 A4 pages |
| Knowledge cutoff | Aug 31, 2025 | n/a |
| Released | Mar 5, 2026 | Apr 24, 2026 |
| Availability | Active | Limited access |
| Open weights | no | yes |
Prices without caching or batch discounts · Page count as a rule of thumb from Artificial Analysis
Is there a better choice?
Overall index 101.4, rank 27$5 input and $30 output per 1M tokens
DeepSeek-V4-Flash vs. GPT-5.5Overall index 100.0, rank 33$0.15 input and $0.60 output per 1M tokens
GPT-5.4 vs. DeepSeek-V4.1-FlashOverall index 130.9, rank 1$8 input and $40 output per 1M tokens
View profileShared benchmarks
Single results from the same benchmark version, task and metric. A value is bold only with the same test setup and a clear gap.
A: GPT-5.4B: DeepSeek-V4-Flash
Show 23 more benchmarks
More comparisons
Compare GPT-5.4 and DeepSeek-V4-Flash with the models people compare them with most often.
Compare another matchup
Predecessor and successor
The most popular comparisons
- 1DeepSeek-V4-Flash vs. DeepSeek V4.1 Flash 1017
- 2DeepSeek-V4-Flash vs. GLM-5.3-Flash
- 3Claude Haiku 5.5 vs. DeepSeek-V4-Flash
- 4DeepSeek-V4-Flash vs. Qwen 3.8 27B
- 5Gemini 3.8 Flash vs. DeepSeek-V4-Flash
- 6DeepSeek-V4-Flash vs. MiMo-V2.5-Pro
- 7Claude Opus 5.5 vs. DeepSeek-V4-Flash
- 8GPT-6.1 Sol vs. DeepSeek-V4-Flash
- 9GPT-6 Luna vs. DeepSeek-V4-Flash
Show all 48 comparisons
- 10GPT-6 Luna vs. GPT-5.4
- 11GPT-6.1 Terra vs. DeepSeek-V4-Flash
- 12Claude Sonnet 5.5 vs. DeepSeek-V4-Flash
- 13GPT-6 Astra vs. DeepSeek-V4-Flash
- 14DeepSeek-V4-Flash vs. Mistral Large 4
- 15DeepSeek-V4-Flash vs. GLM-5.2
- 16GPT-5.4 vs. GLM-5.3-Flash
- 17DeepSeek-V4-Flash vs. Kimi K3
- 18GPT-6.1 Sol vs. GPT-5.4
- 19GPT-5.6 Luna vs. DeepSeek-V4-Flash
- 20GPT-5.6 Sol vs. DeepSeek-V4-Flash
- 21GPT-6 Sol vs. GPT-5.4
- 22Gemini 4 Carbon vs. DeepSeek-V4-Flash
- 23DeepSeek-V4-Flash vs. Kimi K3.1 Pro
- 24Grok 4.7 vs. DeepSeek-V4-Flash
- 25Claude Sonnet 5 vs. DeepSeek-V4-Flash
- 26DeepSeek-V4-Pro vs. DeepSeek-V4-Flash
- 27GPT-6 Sol vs. DeepSeek-V4-Flash
- 28DeepSeek-V4-Flash vs. GLM-5.1
- 29Grok 4.6 vs. DeepSeek-V4-Flash
- 30Muse Spark 1.3 vs. DeepSeek-V4-Flash
- 31DeepSeek-V4-Flash vs. Kimi K2.6
- 32GPT-5.6 Terra vs. DeepSeek-V4-Flash
- 33DeepSeek-V4-Flash vs. Mistral Large 3
- 34GPT-5.4 mini vs. DeepSeek-V4-Flash
- 35GPT-6.1 Terra vs. GPT-5.4
- 36Gemini 3.7 Flash vs. DeepSeek-V4-Flash
- 37Gemini 3.5 Flash vs. DeepSeek-V4-Flash
- 38Gemini 3.1 Pro Preview vs. DeepSeek-V4-Flash
- 39GPT-5.6 Luna vs. GPT-5.4
- 40GPT-5.4 vs. GLM-5.3
- 41Claude Sonnet 5.5 vs. GPT-5.4
- 42GPT-6 Astra vs. GPT-5.4
- 43Claude Opus 5.5 vs. GPT-5.4
- 44GPT-5.6 Terra vs. GPT-5.4
- 45GPT-5.6 Sol vs. GPT-5.4
- 46Claude Opus 4.8 vs. DeepSeek-V4-Flash
- 47Claude Fable 5 vs. GPT-5.4
- 48Gemini 4 Argon vs. DeepSeek-V4-Flash