Claude Opus 4.8
Unavailable in this round
Head-to-head comparison
Compare published benchmark results from matching versions and cohorts, API pricing, and technical specifications. Any documented test setup differences remain visible.
Specifications
Release date, availability, context window, architecture, and published parameter counts at a glance. Undisclosed details remain marked as unavailable.
| Attribute | Claude Opus 4.8 | DeepSeek-V4-Flash |
|---|---|---|
| Provider | Anthropic | DeepSeek |
| Released | May 2026 | Apr 24, 2026 |
| Availability | Legacy | Limited access |
| Model type | Proprietary | Open Weights |
| Parameters | Not published | 284B, 13B active |
| Architecture | Not published | Mixture of Experts |
| Context window | 1,000,000 tokens | 1,000,000 tokens |
| Knowledge cutoff | January 2026 | Not published |
| Technical sources | Model, Knowledge cutoff | Model |
Pricing
The table compares official standard API rates per 1M tokens, including published cache pricing. Batch, fast, priority, regional surcharges, tool calls, and cloud platform pricing are excluded.
| Price type | Claude Opus 4.8 | DeepSeek-V4-Flash |
|---|---|---|
| API input | $5 | $0.14 |
| API output | $25 | $0.28 |
| Cache read | $0.5 | Not listed |
| Cache write (5 min.) | $6.25 | Not listed |
| Cache write (1 hr.) | $10 | Not listed |
| Price verified | 09/22/2026 Source | 10/26/2026 Source |
Key to the marks:better valuebetter, but not conclusivetie
Direct developer pricing and provider endpoint tariffs routed through OpenRouter are listed separately. Prices are in USD per 1M tokens. Context-dependent direct tiers plus regional, Flex, Priority, and other OpenRouter tariffs remain individually identifiable.
No provider tariff for Claude Opus 4.8 is available in the stored OpenRouter snapshot. The official direct price is still shown.
| Model | Provider | Purchase route and tariff | Input per 1M tokens | Output per 1M tokens | Source |
|---|---|---|---|---|---|
| Claude Opus 4.8 | Anthropic | Direct from developerStandard API | Lowest listed price: $5 | Lowest listed price: $25 | Source09/22/2026 |
| DeepSeek-V4-Flash | Alibaba | Via OpenRouteralibaba/us-east-1 | $0.374 | $1.122 | Source10/26/2026 |
| AtlasCloud | Via OpenRouteratlas-cloud/fp4 | $0.44 | $1.32 | Source10/26/2026 | |
| Baidu | Via OpenRouterbaidu/fp8 | $0.44 | $1.32 | Source10/26/2026 | |
| BaseTen | Via OpenRouterbaseten/fp32 | $0.13 | $0.26 | Source10/26/2026 | |
| BaseTen | Via OpenRouterbaseten/fp8 | $0.13 | $0.26 | Source10/26/2026 | |
| Cloudflare | Via OpenRoutercloudflare | $0.44 | $1.32 | Source10/26/2026 | |
| Cohere | Via OpenRoutercohere | $0.14 | $0.28 | Source10/26/2026 | |
| CoreWeave | Via OpenRoutercoreweave/fp8 | $0.13 | $0.28 | Source10/26/2026 | |
| DeepInfra | Via OpenRouterdeepinfra/fp8 | $0.06 | $0.18 | Source10/26/2026 | |
| DigitalOcean | Via OpenRouterdigitalocean | $0.119 | $0.238 | Source10/26/2026 | |
| GMICloud | Via OpenRoutergmicloud/fp8 | $0.286 | $0.858 | Source10/26/2026 | |
| Inceptron | Via OpenRouterinceptron/fp4 | $0.11 | $0.4125 | Source10/26/2026 | |
| Mancer 2 | Via OpenRoutermancer/fp8 | $0.2 | $0.6 | Source10/26/2026 | |
| Novita | Via OpenRouternovita/fp8 | $0.4092 | $1.2276 | Source10/26/2026 | |
| Parasail | Via OpenRouterparasail/fp8 | $0.14 | $0.28 | Source10/26/2026 | |
| Phala | Via OpenRouterphala | $0.308 | $0.924 | Source10/26/2026 | |
| Reka | Via OpenRouterreka | $0.05 | $0.28 | Source10/26/2026 | |
| Relace | Via OpenRouterrelace/fp4 | Lowest listed price: $0.0475 | $0.1568 | Source10/26/2026 | |
| Sail Research | Via OpenRoutersail-research/fp4 | $0.15 | Lowest listed price: $0.15 | Source10/26/2026 | |
| Sail Research | Via OpenRoutersail-research/us | $0.15 | Lowest listed price: $0.15 | Source10/26/2026 | |
| SiliconFlow | Via OpenRoutersiliconflow/fp8 | $0.22 | $0.66 | Source10/26/2026 | |
| StreamLake | Via OpenRouterstreamlake/fp8 | $0.132 | $0.396 | Source10/26/2026 | |
| Venice | Via OpenRoutervenice | $0.13 | $0.26 | Source10/26/2026 | |
| Wafer | Via OpenRouterwafer/fast | $0.14 | $0.23 | Source10/26/2026 |
Benchmark index
The index combines independent benchmarks on a scale from 0 to 100. A lead only counts when a model comes first in at least 95% of 200 recalculations with randomly redrawn test families. Otherwise both count as level.
Claude Opus 4.8 leads in 4 of 4 shared areas.
| Area | Claude Opus 4.8 | DeepSeek-V4-Flash |
|---|---|---|
| Coding | 55.3 | 19.7 |
| Reasoning | 46.2 | 24.9 |
| Knowledge | 65.6 | 10.2 |
| Agents | 56.7 | 38.4 |
Performance
Only published results with the same benchmark version, task, metric, and comparison cohort are paired. Different reasoning levels, agents, harnesses, or output limits appear directly in the table.
Each axis averages directly matched benchmark families. A value of 100 means the stronger value within this pair, not a universal quality score.
62 matched rows from 2 benchmark families were considered. The radar shows 8 of 8 comparable categories.
Key to the marks:better valuebetter, but not conclusivetie
| Benchmark and task | Claude Opus 4.8 | DeepSeek-V4-Flash | Source |
|---|---|---|---|
LMArena Code Arena WebDevOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Code Arena WebDev DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Code Arena WebDevClaude Opus 4.8: Arena rating from 17,454 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 10,152 published pairwise votes. | Higher measured value1,536.177 95% confidence interval: ±5.702The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,430.632 95% confidence interval: ±6.942The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlOverallTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 65,172 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 51,987 published pairwise votes. | Winner1,474.319 95% confidence interval: ±3.846The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,435.648 95% confidence interval: ±4.036The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Code Arena WebDevOverallTest detailsNo documented difference in the test setupVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Code Arena WebDev DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Code Arena WebDevClaude Opus 4.8: Arena rating from 18,540 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 10,152 published pairwise votes. | Winner1,555.99 95% confidence interval: ±5.768The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,430.632 95% confidence interval: ±6.942The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlOverallTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 64,100 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 51,809 published pairwise votes. | Winner1,481.495 95% confidence interval: ±3.868The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,438.671 95% confidence interval: ±4.106The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Code Arena WebDevWebdevTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Code Arena WebDev DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Code Arena WebDevClaude Opus 4.8: Arena rating from 17,454 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 10,152 published pairwise votes. | Higher measured value1,536.177 95% confidence interval: ±5.702The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,430.632 95% confidence interval: ±6.942The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlBusiness, management and financeTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 12,774 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 10,441 published pairwise votes. | Winner1,486.109 95% confidence interval: ±6.333The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,438.332 95% confidence interval: ±6.957The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Code Arena WebDevWebdevTest detailsNo documented difference in the test setupVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Code Arena WebDev DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Code Arena WebDevClaude Opus 4.8: Arena rating from 18,540 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 10,152 published pairwise votes. | Winner1,555.99 95% confidence interval: ±5.768The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,430.632 95% confidence interval: ±6.942The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlBusiness, management and financeTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 12,750 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 10,637 published pairwise votes. | Winner1,488.758 95% confidence interval: ±6.371The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,434.376 95% confidence interval: ±6.962The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Code Arena WebDevWebdev-htmlTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Code Arena WebDev DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Code Arena WebDevClaude Opus 4.8: Arena rating from 2,434 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 1,165 published pairwise votes. | Higher measured value1,524.579 95% confidence interval: ±12.803The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,416.219 95% confidence interval: ±18.033The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlChineseTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 4,397 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 3,009 published pairwise votes. | Winner1,524.914 95% confidence interval: ±9.61The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,468.963 95% confidence interval: ±11.369The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Code Arena WebDevWebdev-htmlTest detailsNo documented difference in the test setupVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Code Arena WebDev DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Code Arena WebDevClaude Opus 4.8: Arena rating from 2,269 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 1,165 published pairwise votes. | Winner1,543.179 95% confidence interval: ±13.758The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,416.219 95% confidence interval: ±18.033The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlChineseTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 4,372 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 2,983 published pairwise votes. | Winner1,525.992 95% confidence interval: ±9.609The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,480.151 95% confidence interval: ±11.391The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Code Arena WebDevWebdev-reactTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Code Arena WebDev DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Code Arena WebDevClaude Opus 4.8: Arena rating from 12,419 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 8,109 published pairwise votes. | Higher measured value1,537.451 95% confidence interval: ±6.53The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,421.593 95% confidence interval: ±7.665The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlCodingTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 18,069 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 15,288 published pairwise votes. | Winner1,529.229 95% confidence interval: ±5.786The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,484.162 95% confidence interval: ±6.212The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Code Arena WebDevWebdev-reactTest detailsNo documented difference in the test setupVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Code Arena WebDev DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Code Arena WebDevClaude Opus 4.8: Arena rating from 11,926 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 8,109 published pairwise votes. | Winner1,556.8 95% confidence interval: ±6.605The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,421.593 95% confidence interval: ±7.665The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlCodingTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 17,427 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 15,235 published pairwise votes. | Winner1,533.525 95% confidence interval: ±5.807The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,479.759 95% confidence interval: ±6.251The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlCreative writingTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 12,829 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 8,582 published pairwise votes. | Winner1,462.897 95% confidence interval: ±6.499The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,408.351 95% confidence interval: ±7.515The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlCreative writingTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 12,797 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 8,664 published pairwise votes. | Winner1,469.053 95% confidence interval: ±6.545The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,410.559 95% confidence interval: ±7.55The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlEnglishTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 28,731 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 23,129 published pairwise votes. | Winner1,481.645 95% confidence interval: ±4.981The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,445.146 95% confidence interval: ±5.272The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlEnglishTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 28,033 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 23,007 published pairwise votes. | Winner1,489.993 95% confidence interval: ±4.984The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,449.912 95% confidence interval: ±5.312The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlEntertainment, sports and mediaTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 16,015 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 11,211 published pairwise votes. | Winner1,453.64 95% confidence interval: ±6.041The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,404.427 95% confidence interval: ±6.919The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlEntertainment, sports and mediaTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 16,188 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 11,465 published pairwise votes. | Winner1,460.304 95% confidence interval: ±6.061The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,407.848 95% confidence interval: ±6.871The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlExcluding tiesTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 48,949 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 39,317 published pairwise votes. | Winner1,484.278 95% confidence interval: ±5.066The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,431.444 95% confidence interval: ±5.296The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlExcluding tiesTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 48,154 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 39,443 published pairwise votes. | Winner1,493.728 95% confidence interval: ±5.063The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,436.18 95% confidence interval: ±5.336The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlExpert promptsTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 7,406 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 5,404 published pairwise votes. | Winner1,515.083 95% confidence interval: ±7.746The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,456.998 95% confidence interval: ±8.731The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlExpert promptsTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 7,067 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 5,331 published pairwise votes. | Winner1,525.89 95% confidence interval: ±7.846The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,466.482 95% confidence interval: ±8.821The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlFrenchTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 2,235 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 2,004 published pairwise votes. | Winner1,506.537 95% confidence interval: ±14.304The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,449.133 95% confidence interval: ±14.893The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlFrenchTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 2,188 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 1,954 published pairwise votes. | Winner1,507.45 95% confidence interval: ±14.329The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,459.043 95% confidence interval: ±15.17The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlGermanTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 1,108 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 841 published pairwise votes. | Winner1,469.692 95% confidence interval: ±18.55The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,425.355 95% confidence interval: ±21.212The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlGermanTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 1,077 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 905 published pairwise votes. | Winner1,492.391 95% confidence interval: ±18.731The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,433.929 95% confidence interval: ±20.514The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlHard promptsTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 43,368 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 34,768 published pairwise votes. | Winner1,505.002 95% confidence interval: ±4.55The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,458.825 95% confidence interval: ±4.754The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlHard promptsTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 42,534 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 34,712 published pairwise votes. | Winner1,512.961 95% confidence interval: ±4.549The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,457.986 95% confidence interval: ±4.823The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlHard prompts, EnglishTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 19,493 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 16,226 published pairwise votes. | Winner1,506.085 95% confidence interval: ±5.664The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,463.797 95% confidence interval: ±6.041The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlHard prompts, EnglishTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 18,817 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 16,089 published pairwise votes. | Winner1,516.755 95% confidence interval: ±5.67The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,464.456 95% confidence interval: ±6.119The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlInstruction followingTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 23,258 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 17,963 published pairwise votes. | Winner1,478.167 95% confidence interval: ±5.333The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,427.905 95% confidence interval: ±5.794The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlInstruction followingTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 22,679 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 18,090 published pairwise votes. | Winner1,490.967 95% confidence interval: ±5.314The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,433.532 95% confidence interval: ±5.864The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlJapaneseTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 895 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 653 published pairwise votes. | Winner1,459.297 95% confidence interval: ±21.594The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,398.472 95% confidence interval: ±24.752The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlJapaneseTest detailsNo documented difference in the test setupNo clear leadVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 892 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 640 published pairwise votes. | No clear lead1,458.791 95% confidence interval: ±21.865The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,425.764 95% confidence interval: ±24.975The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlKoreanTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 1,081 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 899 published pairwise votes. | Winner1,438.453 95% confidence interval: ±19.142The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,392.931 95% confidence interval: ±20.881The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlKoreanTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 1,107 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 949 published pairwise votes. | Winner1,449.214 95% confidence interval: ±19.455The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,377.467 95% confidence interval: ±20.808The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlLegal and governmentTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 5,534 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 4,148 published pairwise votes. | Winner1,497.876 95% confidence interval: ±8.776The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,448.353 95% confidence interval: ±9.835The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlLegal and governmentTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 5,446 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 4,096 published pairwise votes. | Winner1,495.598 95% confidence interval: ±8.82The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,457.738 95% confidence interval: ±9.897The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlLife, physical and social scienceTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 10,711 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 8,412 published pairwise votes. | Winner1,499.851 95% confidence interval: ±6.614The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,456.376 95% confidence interval: ±7.368The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlLife, physical and social scienceTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 10,441 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 8,496 published pairwise votes. | Winner1,503.791 95% confidence interval: ±6.683The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,459.695 95% confidence interval: ±7.397The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlLonger queriesTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 30,856 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 23,356 published pairwise votes. | Winner1,499.266 95% confidence interval: ±5.142The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,447.355 95% confidence interval: ±5.559The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlLonger queriesTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 30,215 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 23,483 published pairwise votes. | Winner1,502.956 95% confidence interval: ±5.133The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,448.673 95% confidence interval: ±5.562The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlMathTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 3,088 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 2,697 published pairwise votes. | Winner1,476.342 95% confidence interval: ±10.946The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,424.768 95% confidence interval: ±11.736The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlMathTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 2,969 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 2,624 published pairwise votes. | Winner1,493.944 95% confidence interval: ±11.177The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,441.542 95% confidence interval: ±11.857The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlMathematical professionsTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 3,619 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 2,975 published pairwise votes. | Winner1,488.539 95% confidence interval: ±10.499The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,434.671 95% confidence interval: ±11.421The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlMathematical professionsTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 3,480 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 2,824 published pairwise votes. | Winner1,507.138 95% confidence interval: ±10.616The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,443.928 95% confidence interval: ±11.739The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlMedicine and healthcareTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 4,754 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 3,681 published pairwise votes. | Winner1,497.764 95% confidence interval: ±9.436The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,459.378 95% confidence interval: ±10.493The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlMedicine and healthcareTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 4,774 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 3,756 published pairwise votes. | Winner1,500.013 95% confidence interval: ±9.374The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,461.435 95% confidence interval: ±10.435The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlMulti-turnTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 11,385 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 9,346 published pairwise votes. | Winner1,494.492 95% confidence interval: ±6.7The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,452.779 95% confidence interval: ±7.275The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlMulti-turnTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 11,189 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 9,228 published pairwise votes. | Winner1,496.459 95% confidence interval: ±6.694The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,446.595 95% confidence interval: ±7.324The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlNon-EnglishTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 36,440 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 28,857 published pairwise votes. | Winner1,463.651 95% confidence interval: ±4.65The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,422.602 95% confidence interval: ±4.935The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlNon-EnglishTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 36,060 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 28,800 published pairwise votes. | Winner1,469.226 95% confidence interval: ±4.645The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,423.32 95% confidence interval: ±5.013The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlPolishTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 1,090 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 1,027 published pairwise votes. | Winner1,484.571 95% confidence interval: ±17.541The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,436.617 95% confidence interval: ±18.709The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlPolishTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 1,075 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 1,040 published pairwise votes. | Winner1,485.094 95% confidence interval: ±18.291The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,433.764 95% confidence interval: ±18.39The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlRussianTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 7,100 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 5,745 published pairwise votes. | Winner1,485.589 95% confidence interval: ±7.729The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,432.802 95% confidence interval: ±8.489The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlRussianTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 7,149 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 5,791 published pairwise votes. | Winner1,494.612 95% confidence interval: ±7.684The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,437.123 95% confidence interval: ±8.566The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlSoftware and IT servicesTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 25,722 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 21,378 published pairwise votes. | Winner1,517.219 95% confidence interval: ±5.18The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,471.006 95% confidence interval: ±5.497The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlSoftware and IT servicesTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 25,123 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 21,327 published pairwise votes. | Winner1,523.52 95% confidence interval: ±5.181The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,473.004 95% confidence interval: ±5.525The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlSpanishTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 1,942 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 1,578 published pairwise votes. | Winner1,467.726 95% confidence interval: ±14.48The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,431.922 95% confidence interval: ±16.067The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
LMArena Text, Style ControlSpanishTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.8: Snapshot: claude-opus-4-8-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.8: Arena rating from 1,865 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 1,475 published pairwise votes. | Winner1,480.153 95% confidence interval: ±14.717The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,429.606 95% confidence interval: ±16.458The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/15/2026 |
Key to the marks:better valuebetter, but not conclusivetie | |||
Our model tests
One SVG prompt and fixed output settings. Captures are shown only with 0 reported reasoning tokens or documented lack of reasoning controls. Identical test conditions do not make the models' internal compute identical.
Shared test round: 43b8c5c46830
Unavailable in this round
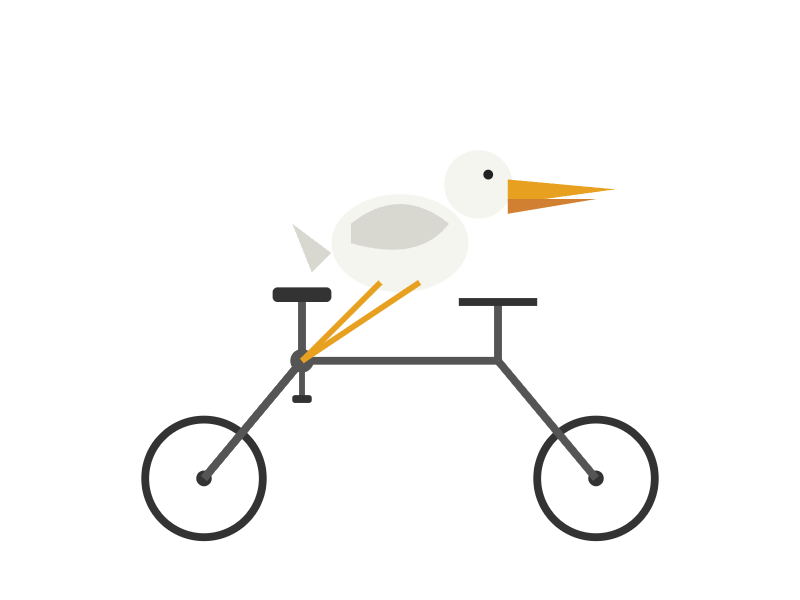
A community classic for free-form SVG drawing.
Claude Opus 4.8
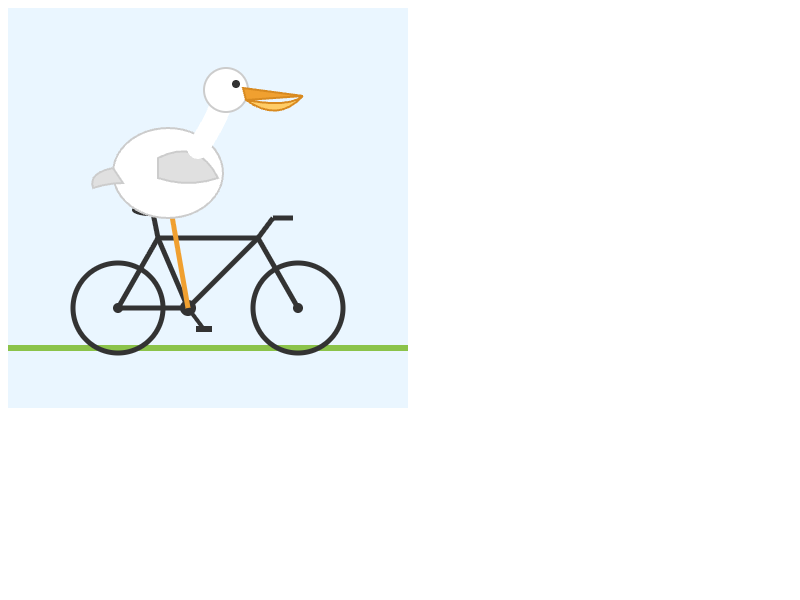
Reasoning (requested): high
Visually reviewed. This individual test does not establish overall model quality.
DeepSeek-V4-Flash
The response reached the token limit. No complete recording is available.
Reasoning (requested): high
Not yet visually reviewed. A successful recording does not confirm correct physics or full compliance with the prompt.
Generate an SVG of a pelican riding a bicycle
Token limit including reasoning: 8,192 tokens
Task origin (Simon Willison)How to read this comparison
Your workload, budget, and required context length matter most. A coding benchmark says little about visual understanding or agent performance.
The standard price table uses direct developer rates. The provider comparison labels OpenRouter endpoints, regions, and special tariffs separately.
Every result links to its measurement source and retrieval date. Labels distinguish vendor reports, official benchmark leaderboards, and independent evaluations. Disputed or archived results are excluded.
More matchups
Compare Claude Opus 4.8 and DeepSeek-V4-Flash with other leading models using the same data and benchmark logic.