Claude Fable 5.1
Unavailable in this round
Head-to-head comparison
Compare published benchmark results from matching versions and cohorts, API pricing, and technical specifications. Any documented test setup differences remain visible.
Specifications
Release date, availability, context window, architecture, and published parameter counts at a glance. Undisclosed details remain marked as unavailable.
| Attribute | Claude Fable 5.1 | DeepSeek-V4-Flash |
|---|---|---|
| Provider | Anthropic | DeepSeek |
| Released | Sep 1, 2026 | Apr 24, 2026 |
| Availability | Active | Limited access |
| Model type | Proprietary | Open Weights |
| Parameters | Not published | 284B, 13B active |
| Architecture | Not published | Mixture of Experts |
| Context window | 1,000,000 tokens | 1,000,000 tokens |
| Knowledge cutoff | June 2026 | Not published |
| Technical sources | Model | Model |
Pricing
The table compares official standard API rates per 1M tokens, including published cache pricing. Batch, fast, priority, regional surcharges, tool calls, and cloud platform pricing are excluded.
| Price type | Claude Fable 5.1 | DeepSeek-V4-Flash |
|---|---|---|
| API input | $10 | $0.14 |
| API output | $50 | $0.28 |
| Cache read | $0.25 | Not listed |
| Cache write (5 min.) | $12.5 | Not listed |
| Cache write (1 hr.) | $20 | Not listed |
| Price verified | 09/22/2026 Source | 10/17/2026 Source |
Key to the marks:better valuebetter, but not conclusivetie
Direct developer pricing and provider endpoint tariffs routed through OpenRouter are listed separately. Prices are in USD per 1M tokens. Context-dependent direct tiers plus regional, Flex, Priority, and other OpenRouter tariffs remain individually identifiable.
| Model | Provider | Purchase route and tariff | Input per 1M tokens | Output per 1M tokens | Source |
|---|---|---|---|---|---|
| Claude Fable 5.1 | Anthropic | Direct from developerStandard API | Lowest listed price: $10 | Lowest listed price: $50 | Source09/22/2026 |
| Amazon Bedrock | Via OpenRouteramazon-bedrock | Lowest listed price: $10 | Lowest listed price: $50 | Source10/17/2026 | |
| Anthropic | Via OpenRouteranthropic | Lowest listed price: $10 | Lowest listed price: $50 | Source10/17/2026 | |
| Azure | Via OpenRouterazure | Lowest listed price: $10 | Lowest listed price: $50 | Source10/17/2026 | |
| Via OpenRoutergoogle-vertex/global | Lowest listed price: $10 | Lowest listed price: $50 | Source10/17/2026 | ||
| DeepSeek-V4-Flash | Alibaba | Via OpenRouteralibaba | $0.352 | $1.056 | Source10/17/2026 |
| Alibaba | Via OpenRouteralibaba/us-east-1 | $0.374 | $1.122 | Source10/17/2026 | |
| AtlasCloud | Via OpenRouteratlas-cloud/fp4 | $0.44 | $1.32 | Source10/17/2026 | |
| Baidu | Via OpenRouterbaidu/fp8 | $0.0598 | Lowest listed price: $0.1795 | Source10/17/2026 | |
| BaseTen | Via OpenRouterbaseten/fp32 | $0.13 | $0.26 | Source10/17/2026 | |
| BaseTen | Via OpenRouterbaseten/fp8 | $0.13 | $0.26 | Source10/17/2026 | |
| Cloudflare | Via OpenRoutercloudflare | $0.44 | $1.32 | Source10/17/2026 | |
| Cohere | Via OpenRoutercohere | $0.14 | $0.28 | Source10/17/2026 | |
| CoreWeave | Via OpenRoutercoreweave/fp8 | $0.13 | $0.28 | Source10/17/2026 | |
| DeepInfra | Via OpenRouterdeepinfra/fp8 | $0.06 | $0.18 | Source10/17/2026 | |
| DigitalOcean | Via OpenRouterdigitalocean | $0.119 | $0.238 | Source10/17/2026 | |
| GMICloud | Via OpenRoutergmicloud/fp8 | $0.286 | $0.858 | Source10/17/2026 | |
| Inceptron | Via OpenRouterinceptron/fp4 | $0.13 | $0.5978 | Source10/17/2026 | |
| Mancer 2 | Via OpenRoutermancer/fp8 | $0.2 | $0.6 | Source10/17/2026 | |
| Novita | Via OpenRouternovita/fp8 | $0.4092 | $1.2276 | Source10/17/2026 | |
| Parasail | Via OpenRouterparasail/fp8 | $0.14 | $0.28 | Source10/17/2026 | |
| Phala | Via OpenRouterphala | $0.308 | $0.924 | Source10/17/2026 | |
| Reka | Via OpenRouterreka | $0.021 | $0.528 | Source10/17/2026 | |
| Relace | Via OpenRouterrelace/fp4 | Lowest listed price: $0.0067 | $1.28 | Source10/17/2026 | |
| Sail Research | Via OpenRoutersail-research/fp4 | $0.1 | $0.3 | Source10/17/2026 | |
| Sail Research | Via OpenRoutersail-research/us | $0.1 | $0.3 | Source10/17/2026 | |
| SiliconFlow | Via OpenRoutersiliconflow/fp8 | $0.22 | $0.66 | Source10/17/2026 | |
| StreamLake | Via OpenRouterstreamlake/fp8 | $0.088 | $0.264 | Source10/17/2026 | |
| Together | Via OpenRoutertogether | $0.14 | $0.28 | Source10/17/2026 | |
| Venice | Via OpenRoutervenice | $0.13 | $0.26 | Source10/17/2026 | |
| Wafer | Via OpenRouterwafer/fast | $0.13 | $0.23 | Source10/17/2026 |
Performance
Only published results with the same benchmark version, task, metric, and comparison cohort are paired. Different reasoning levels, agents, harnesses, or output limits appear directly in the table.
Each axis averages directly matched benchmark families. A value of 100 means the stronger value within this pair, not a universal quality score.
Not enough directly matched categories for a reliable radar
Only 0 of at least 5 categories have comparable, direct model measurements. The benchmark tables below show the available evidence without filling missing axes.
Key to the marks:better valuebetter, but not conclusivetie
| Benchmark and task | Claude Fable 5.1 | DeepSeek-V4-Flash | Source |
|---|---|---|---|
LMArena Code Arena WebDevOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Code Arena WebDev DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Code Arena WebDevClaude Fable 5.1: Arena rating from 7,230 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 10,152 published pairwise votes. | Higher measured value1,742.652 95% confidence interval: ±9.147The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,430.632 95% confidence interval: ±6.942The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 14,121 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 52,016 published pairwise votes. | Higher measured value1,500.568 95% confidence interval: ±6.106The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,435.976 95% confidence interval: ±4.036The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Code Arena WebDevWebdevTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Code Arena WebDev DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Code Arena WebDevClaude Fable 5.1: Arena rating from 7,230 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 10,152 published pairwise votes. | Higher measured value1,742.652 95% confidence interval: ±9.147The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,430.632 95% confidence interval: ±6.942The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 14,121 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 51,814 published pairwise votes. | Higher measured value1,500.568 95% confidence interval: ±6.106The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,438.654 95% confidence interval: ±4.106The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Code Arena WebDevWebdev-htmlTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Code Arena WebDev DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Code Arena WebDevClaude Fable 5.1: Arena rating from 855 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 1,165 published pairwise votes. | Higher measured value1,690.402 95% confidence interval: ±23.795The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,416.219 95% confidence interval: ±18.033The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlBusiness, management and financeTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 2,589 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 10,448 published pairwise votes. | Higher measured value1,485.231 95% confidence interval: ±11.847The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,438.829 95% confidence interval: ±6.961The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Code Arena WebDevWebdev-reactTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Code Arena WebDev DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Code Arena WebDevClaude Fable 5.1: Arena rating from 4,865 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 8,109 published pairwise votes. | Higher measured value1,791.006 95% confidence interval: ±11.348The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,421.593 95% confidence interval: ±7.665The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlBusiness, management and financeTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 2,589 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 10,643 published pairwise votes. | Higher measured value1,485.231 95% confidence interval: ±11.847The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,434.084 95% confidence interval: ±6.963The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlChineseTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 1,069 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 3,005 published pairwise votes. | Higher measured value1,567.304 95% confidence interval: ±18.995The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,470.018 95% confidence interval: ±11.382The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlChineseTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 1,069 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 2,975 published pairwise votes. | Higher measured value1,567.304 95% confidence interval: ±18.995The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,480.516 95% confidence interval: ±11.412The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlCodingTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 2,816 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 15,290 published pairwise votes. | Higher measured value1,535.255 95% confidence interval: ±11.537The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,484.301 95% confidence interval: ±6.214The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlCodingTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 2,816 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 15,245 published pairwise votes. | Higher measured value1,535.255 95% confidence interval: ±11.537The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,479.463 95% confidence interval: ±6.25The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlCreative writingTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 3,200 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 8,595 published pairwise votes. | Higher measured value1,483.901 95% confidence interval: ±11.553The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,408.246 95% confidence interval: ±7.512The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlCreative writingTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 3,200 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 8,668 published pairwise votes. | Higher measured value1,483.901 95% confidence interval: ±11.553The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,410.845 95% confidence interval: ±7.548The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlEnglishTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 5,753 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 23,136 published pairwise votes. | Higher measured value1,496.791 95% confidence interval: ±8.329The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,445.189 95% confidence interval: ±5.273The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlEnglishTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 5,753 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 23,022 published pairwise votes. | Higher measured value1,496.791 95% confidence interval: ±8.329The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,449.707 95% confidence interval: ±5.31The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlEntertainment, sports and mediaTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 3,559 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 11,221 published pairwise votes. | Higher measured value1,475.342 95% confidence interval: ±10.833The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,404.55 95% confidence interval: ±6.918The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlEntertainment, sports and mediaTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 3,559 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 11,460 published pairwise votes. | Higher measured value1,475.342 95% confidence interval: ±10.833The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,407.781 95% confidence interval: ±6.873The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlExcluding tiesTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 10,459 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 39,351 published pairwise votes. | Higher measured value1,518.19 95% confidence interval: ±8.066The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,431.858 95% confidence interval: ±5.294The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlExcluding tiesTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 10,459 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 39,449 published pairwise votes. | Higher measured value1,518.19 95% confidence interval: ±8.066The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,436.129 95% confidence interval: ±5.336The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlExpert promptsTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 1,222 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 5,416 published pairwise votes. | Higher measured value1,523.697 95% confidence interval: ±17.383The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,457.085 95% confidence interval: ±8.727The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlExpert promptsTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 1,222 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 5,338 published pairwise votes. | Higher measured value1,523.697 95% confidence interval: ±17.383The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,466.764 95% confidence interval: ±8.816The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlFrenchTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 476 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 2,004 published pairwise votes. | Higher measured value1,517.688 95% confidence interval: ±29.031The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,449.161 95% confidence interval: ±14.911The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlFrenchTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 476 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 1,957 published pairwise votes. | Higher measured value1,517.688 95% confidence interval: ±29.031The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,458.886 95% confidence interval: ±15.182The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlGermanTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 268 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 841 published pairwise votes. | Higher measured value1,484.511 95% confidence interval: ±35.581The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,425.17 95% confidence interval: ±21.221The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlGermanTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 268 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 904 published pairwise votes. | Higher measured value1,484.511 95% confidence interval: ±35.581The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,433.291 95% confidence interval: ±20.525The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlHard promptsTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 8,244 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 34,789 published pairwise votes. | Higher measured value1,520.197 95% confidence interval: ±7.328The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,459.087 95% confidence interval: ±4.755The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlHard promptsTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 8,244 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 34,719 published pairwise votes. | Higher measured value1,520.197 95% confidence interval: ±7.328The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,458.022 95% confidence interval: ±4.823The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlHard prompts, EnglishTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 3,345 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 16,226 published pairwise votes. | Higher measured value1,516.447 95% confidence interval: ±10.669The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,463.782 95% confidence interval: ±6.043The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlHard prompts, EnglishTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 3,345 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 16,101 published pairwise votes. | Higher measured value1,516.447 95% confidence interval: ±10.669The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,464.326 95% confidence interval: ±6.118The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlInstruction followingTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 4,222 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 17,984 published pairwise votes. | Higher measured value1,496.708 95% confidence interval: ±9.807The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,428.161 95% confidence interval: ±5.795The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlInstruction followingTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 4,222 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 18,097 published pairwise votes. | Higher measured value1,496.708 95% confidence interval: ±9.807The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,433.654 95% confidence interval: ±5.864The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlJapaneseTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 253 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 653 published pairwise votes. | Higher measured value1,547.14 95% confidence interval: ±40.875The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,398.855 95% confidence interval: ±24.754The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlJapaneseTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 253 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 640 published pairwise votes. | Higher measured value1,547.14 95% confidence interval: ±40.875The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,426.069 95% confidence interval: ±24.977The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlKoreanTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 229 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 900 published pairwise votes. | Higher measured value1,506.088 95% confidence interval: ±39.936The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,391.938 95% confidence interval: ±20.897The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlKoreanTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 229 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 949 published pairwise votes. | Higher measured value1,506.088 95% confidence interval: ±39.936The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,376.332 95% confidence interval: ±20.813The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlLegal and governmentTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 1,169 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 4,152 published pairwise votes. | Higher measured value1,491.952 95% confidence interval: ±18.043The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,448.281 95% confidence interval: ±9.836The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlLegal and governmentTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 1,169 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 4,099 published pairwise votes. | Higher measured value1,491.952 95% confidence interval: ±18.043The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,457.757 95% confidence interval: ±9.897The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlLife, physical and social scienceTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 2,348 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 8,416 published pairwise votes. | Higher measured value1,519.493 95% confidence interval: ±12.586The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,456.243 95% confidence interval: ±7.368The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlLife, physical and social scienceTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 2,348 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 8,489 published pairwise votes. | Higher measured value1,519.493 95% confidence interval: ±12.586The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,459.964 95% confidence interval: ±7.4The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlLonger queriesTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 5,840 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 23,382 published pairwise votes. | Higher measured value1,508.332 95% confidence interval: ±8.638The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,447.798 95% confidence interval: ±5.56The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlLonger queriesTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 5,840 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 23,493 published pairwise votes. | Higher measured value1,508.332 95% confidence interval: ±8.638The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,448.579 95% confidence interval: ±5.563The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlMathTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 662 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 2,699 published pairwise votes. | Higher measured value1,524.347 95% confidence interval: ±22.466The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,424.989 95% confidence interval: ±11.731The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlMathTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 662 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 2,625 published pairwise votes. | Higher measured value1,524.347 95% confidence interval: ±22.466The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,441.363 95% confidence interval: ±11.858The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlMathematical professionsTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 789 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 2,980 published pairwise votes. | Higher measured value1,526.92 95% confidence interval: ±21.312The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,434.613 95% confidence interval: ±11.415The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlMathematical professionsTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 789 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 2,825 published pairwise votes. | Higher measured value1,526.92 95% confidence interval: ±21.312The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,444.604 95% confidence interval: ±11.746The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlMedicine and healthcareTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 1,090 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 3,692 published pairwise votes. | Higher measured value1,524.465 95% confidence interval: ±18.711The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,459.398 95% confidence interval: ±10.484The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlMedicine and healthcareTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 1,090 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 3,760 published pairwise votes. | Higher measured value1,524.465 95% confidence interval: ±18.711The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,461.041 95% confidence interval: ±10.433The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlMulti-turnTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 1,864 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 9,349 published pairwise votes. | Higher measured value1,486.274 95% confidence interval: ±14.034The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,453.168 95% confidence interval: ±7.275The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlMulti-turnTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 1,864 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 9,223 published pairwise votes. | Higher measured value1,486.274 95% confidence interval: ±14.034The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,446.213 95% confidence interval: ±7.326The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlNon-EnglishTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 8,366 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 28,879 published pairwise votes. | Higher measured value1,494.6 95% confidence interval: ±7.219The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,422.96 95% confidence interval: ±4.937The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlNon-EnglishTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 8,366 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 28,790 published pairwise votes. | Higher measured value1,494.6 95% confidence interval: ±7.219The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,423.369 95% confidence interval: ±5.014The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlPolishTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 216 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 1,027 published pairwise votes. | Higher measured value1,510.948 95% confidence interval: ±38.576The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,436.594 95% confidence interval: ±18.719The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlPolishTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 216 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 1,040 published pairwise votes. | Higher measured value1,510.948 95% confidence interval: ±38.576The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,433.769 95% confidence interval: ±18.399The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlRussianTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 1,847 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 5,766 published pairwise votes. | Higher measured value1,510.806 95% confidence interval: ±14.384The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,432.997 95% confidence interval: ±8.479The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlRussianTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 1,847 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 5,793 published pairwise votes. | Higher measured value1,510.806 95% confidence interval: ±14.384The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,436.964 95% confidence interval: ±8.567The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlSoftware and IT servicesTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 4,662 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 21,384 published pairwise votes. | Higher measured value1,527.485 95% confidence interval: ±9.153The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,471.26 95% confidence interval: ±5.499The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlSoftware and IT servicesTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 4,662 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 21,349 published pairwise votes. | Higher measured value1,527.485 95% confidence interval: ±9.153The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,472.791 95% confidence interval: ±5.525The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlSpanishTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 454 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 1,580 published pairwise votes. | Higher measured value1,499.26 95% confidence interval: ±26.954The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,431.488 95% confidence interval: ±16.062The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlSpanishTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 454 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 1,476 published pairwise votes. | Higher measured value1,499.26 95% confidence interval: ±26.954The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,429.907 95% confidence interval: ±16.461The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlWriting, literature and languageTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 4,033 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 12,619 published pairwise votes. | Higher measured value1,491.637 95% confidence interval: ±10.188The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,415.784 95% confidence interval: ±6.537The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlWriting, literature and languageTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Fable 5.1: Snapshot: claude-fable-5.1-max, Reasoning: max, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Fable 5.1: Arena rating from 4,033 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 12,789 published pairwise votes. | Higher measured value1,491.637 95% confidence interval: ±10.188The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,422.178 95% confidence interval: ±6.53The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
Key to the marks:better valuebetter, but not conclusivetie | |||
Our model tests
One SVG prompt and fixed output settings. Captures are shown only with 0 reported reasoning tokens or documented lack of reasoning controls. Identical test conditions do not make the models' internal compute identical.
Shared test round: 4ae5d8eeb9a9
Unavailable in this round
API request failed. The model was not evaluated.
A community classic for free-form SVG drawing.
Claude Fable 5.1
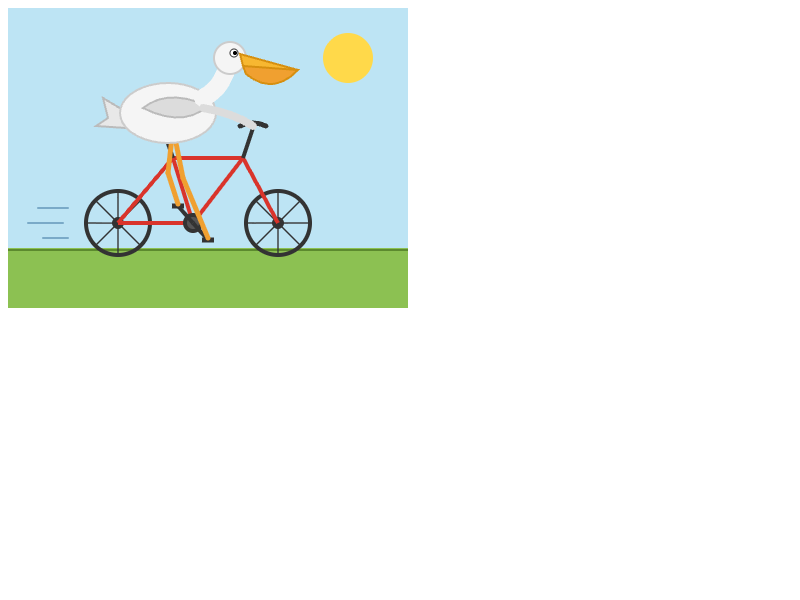
Reasoning (requested): high
Visually reviewed. This individual test does not establish overall model quality.
DeepSeek-V4-Flash
The response reached the token limit. No complete recording is available.
Reasoning (requested): high
Not yet visually reviewed. A successful recording does not confirm correct physics or full compliance with the prompt.
Generate an SVG of a pelican riding a bicycle
Token limit including reasoning: 8,192 tokens
Task origin (Simon Willison)How to read this comparison
Your workload, budget, and required context length matter most. A coding benchmark says little about visual understanding or agent performance.
The standard price table uses direct developer rates. The provider comparison labels OpenRouter endpoints, regions, and special tariffs separately.
Every result links to its measurement source and retrieval date. Labels distinguish vendor reports, official benchmark leaderboards, and independent evaluations. Disputed or archived results are excluded.
More matchups
Compare Claude Fable 5.1 and DeepSeek-V4-Flash with other leading models using the same data and benchmark logic.