AnthropicxAILLM matchup
Claude Haiku 5.5vs.Grok 4.6
Which one is better?
Claude Haiku 5.5 and Grok 4.6 perform about equally well, but Grok 4.6 costs 20 times (input) and 12 times (output) as much.
Claude Haiku 5.5
Rank 20
Grok 4.6
Rank 22
Claude Haiku 5.5
Grok 4.6
Claude Haiku 5.5
Grok 4.6
Claude Haiku 5.5
Rank 3 of 875
Grok 4.6
Rank 42 of 875
Above 100,000 tokens of context, Claude Haiku 5.5 costs more: $0.50 input and $2.50 output per 1M tokens. Above 200,000 tokens of context, Grok 4.6 costs more: $4 input and $12 output per 1M tokens.
Choose Claude Haiku 5.5 for
Choose Grok 4.6 for
Where is the difference?
Strengths at a glance
Haiku 5.5Grok 4.6
The median of all ranked models is below 100 in every area, so it sits in the centre of the net.
95 % range: Haiku 5.5 102.5 to 109.9, Grok 4.6 97.5 to 104.2.
The same values and verdicts as the bars below. In the top field the net starts at 100 points, the reference group average; values below sit as a hollow point in the centre. Not in the net because a model has no own value there or the data are too thin: Multimodal.
Haiku 5.5 is ahead in 2 of 10 areas, Grok 4.6 in 1.
Haiku 5.5 ahead: 2Haiku 5.5 slightly ahead: 3level: 2too little data: 1Grok 4.6 slightly ahead: 1Grok 4.6 ahead: 1
Bar length shows the gap in index points (full width 15 points, one standard deviation of the reference group). Solid means clearly ahead, hatched not certain yet, a thin grey bar level.
Show 3 more areas that do not count toward the overall index
Bar length shows the gap in index points (full width 15 points, one standard deviation of the reference group). Solid means clearly ahead, hatched not certain yet, a thin grey bar level.
Claude Haiku 5.5 vs. Grok 4.6 at the same effort
Both models measured at the same reasoning efforts. This shows whether a lead comes from the model or only from more compute.
| Effort | Haiku 5.5 | Grok 4.6 | Gap | Verdict | Test series |
|---|---|---|---|---|---|
| xhigh | 101.3 | n/a | 1.5 | tied | 10 |
| Overall index (max vs. high) | 103.4 | 102.4 | 1.0 | level |
Gap and verdict compare only the Artificial Analysis test series in which both models are measured at that effort. Tied below 3 points, ahead only beyond two standard errors. The single values rest on all test series of each model, so their difference can deviate from the gap.
Which model for which task?
Everyday tasks, translated from the area values above. Each row names the values it rests on.
See for yourself: same task, one attempt
The same prompt for both models. We show the latest attempt without fixes; it does not count toward the overall index.
Claude Haiku 5.5
Not tested yet
Grok 4.6
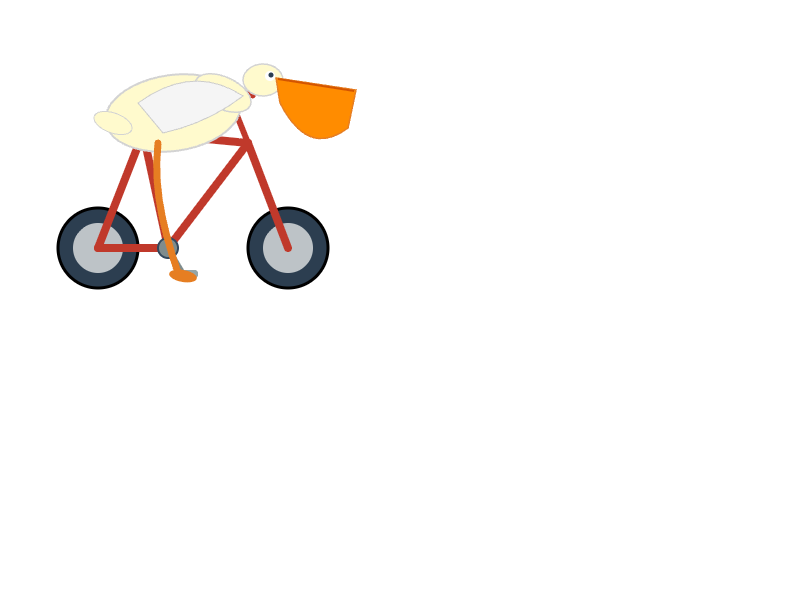
Oct 1, 2026 · 114 s · $0.05
Test details
- Run date
- Oct 1, 2026
- API provider
- openrouter
- Requested API model
- x-ai/grok-4.6
- Reasoning setting
- high
- Token limit including reasoning
- 8,192 tokens
- Output tokens
- 7,660 tokens
- Cost of the attempt
- $0.0462
- Response time
- 113.6 s
- API model reported in response
- x-ai/grok-4.6
- Pinned endpoint
- xAI | x-ai/grok-4.6-20260810
- Temperature
- Provider default
- Test protocol
- community-visual-tests-v1
- Technical checks
- Passed, not a quality rating
Visually reviewed. This individual test does not establish overall model quality.
Earlier attempts (1)
- Sep 7, 2026API request failedReasoning setting: high
SVG short test
SVG short test
One SVG task with the same fixed settings for every model, without hidden thinking.
Prompt
Return only one standalone SVG of a pelican riding a bicycle. Use viewBox="0 0 800 600", simple shapes, two clearly visible wheels and a recognizable pelican with a long beak. At most 30 SVG elements and 1800 characters. No Markdown, explanations, comments, scripts, animation, CSS or external resources.
Claude Haiku 5.5
Unavailable in this round
Grok 4.6
Unavailable in this round
Claude Haiku 5.5 and Grok 4.6 in the overall index
Every model with a place in the overall index, both models of this matchup highlighted. You can add or hide other models.
Overall index (Gradually Meta-Score v4)
20 of 91 models
5 models in this view are measured at a lower reasoning effort than max in the overall index. Dashed column: lower reasoning effort than the top.
Popularity compared
How often the models are searched for, used and mentioned, on a scale from 0 to 100.
Claude Haiku 5.5 is more popular than Grok 4.6: 77 to 59 out of 100.
Over time
Weekly values from October 18, 2026 to November 5, 2026
Claude Haiku 5.5Grok 4.6
All data side by side
The better value is bold. For the overall index only when the gap is clear.
| Metric | Claude Haiku 5.5 | Grok 4.6 |
|---|---|---|
| Intelligence | ||
| Overall indexpoints, 100 = reference group average, higher is better | 103.4 | 102.4 |
| Rank | Rank 20 of 91 | Rank 22 of 91 |
| Price per 1M tokens | ||
| Inputwhat you send | $0.10above 100,000 tokens: $0.50 | $2above 200,000 tokens: $4 |
| Outputwhat the model writes | $0.50above 100,000 tokens: $2.50 | $6above 200,000 tokens: $12 |
| Speed | ||
| Tokens per second | 236 | 72 |
| Popularity | ||
| Popularitysearch, usage and mentions, 0 to 100 | 77Rank 3 of 875 | 59Rank 42 of 875 |
| Technical | ||
| Context windowhow much text the model reads at once | 1 M tokens≈ 1,500 A4 pages | 500,000 tokens≈ 750 A4 pages |
| Knowledge cutoff | June 2026 | Feb 1, 2026 |
| Released | Oct 7, 2026 | Aug 12, 2026 |
| Availability | Active | Active |
| Open weights | no | no |
Prices without caching or batch discounts · Page count as a rule of thumb from Artificial Analysis
Is there a better choice?
Overall index 103.3, rank 21. $2 input and $6 output per 1M tokens.
Haiku 5.5 vs. Grok 4.7Overall index 126.1, rank 1. $4 input and $20 output per 1M tokens.
Haiku 5.5 vs. Claude Opus 5.5Shared benchmarks
Single results from the same benchmark version, task and metric. A value is bold only with the same test setup and a clear gap.
A: Claude Haiku 5.5B: Grok 4.6
Show 54 more benchmarks
More comparisons
Compare Claude Haiku 5.5 and Grok 4.6 with the models people compare them with most often.
Compare another matchup
Predecessor and successor
The most popular comparisons
- 1Claude Haiku 5.5 vs. GPT-6 Luna
- 2Claude Sonnet 5.5 vs. Claude Haiku 5.5
- 3Claude Haiku 5.5 vs. DeepSeek V4.1 Flash 1017
- 4Claude Haiku 5.5 vs. DeepSeek-V4-Flash
- 5Claude Haiku 5.5 vs. DeepSeek-V4.1-Flash
- 6Claude Opus 5.5 vs. Claude Haiku 5.5
- 7Claude Haiku 5.5 vs. GLM-5.3
- 8Claude Haiku 5.5 vs. Gemini 3.5 Flash-Lite
- 9Claude Haiku 5.5 vs. Gemini 3.8 Flash
Show all 41 comparisons
- 10Claude Opus 5.5 vs. Grok 4.6
- 11Claude Haiku 5.5 vs. Claude Sonnet 4.5
- 12Claude Haiku 5.5 vs. Claude Sonnet 5
- 13Claude Haiku 5.5 vs. Claude Opus 5
- 14Claude Haiku 5.5 vs. GPT-6 Astra
- 15Claude Haiku 5.5 vs. Gemini 3.5 Flash
- 16Claude Haiku 5.5 vs. Claude Opus 4.8
- 17Claude Haiku 5.5 vs. Gemini 4 Argon
- 18Claude Haiku 5.5 vs. Grok 4.7
- 19Claude Haiku 5.5 vs. GPT-5.6 Luna
- 20Claude Haiku 5.5 vs. Qwen 3.8 Max 0902
- 21Claude Opus 5 vs. Grok 4.6
- 22Claude Haiku 5.5 vs. Muse Spark 1.3
- 23Claude Haiku 5.5 vs. Claude Sonnet 4.6
- 24Claude Haiku 5.5 vs. Gemini 3.7 Flash
- 25Gemini 3.8 Flash vs. Grok 4.6
- 26Claude Haiku 5.5 vs. Mistral Large 4
- 27Claude Haiku 5.5 vs. GPT-6.1 Sol
- 28Claude Haiku 5.5 vs. Gemini 3.1 Pro Preview
- 29Claude Haiku 5.5 vs. GLM-5.3-Flash
- 30Claude Haiku 5.5 vs. DeepSeek-V4-Pro
- 31Claude Haiku 5.5 vs. GPT-5.6 Sol
- 32Claude Haiku 5.5 vs. Gemini 3.6 Flash
- 33Claude Haiku 5.5 vs. Claude Opus 4.6
- 34Claude Haiku 5.5 vs. Kimi K2.6
- 35GPT-6 Luna vs. Grok 4.6
- 36Grok 4.6 vs. GLM-5.3
- 37Grok 4.6 vs. DeepSeek-V4.1-Flash
- 38Claude Haiku 5.5 vs. Claude Opus 4.7
- 39Claude Haiku 5.5 vs. Mistral Large 3
- 40Claude Haiku 5.5 vs. GPT-5.5
- 41Claude Haiku 5.5 vs. GPT-6.1 Terra