AlibabaImage model

Qwen Image 3.0

Qwen Image 3.0 is rank 15 of 74 in our GraduallyBench test.

Arena ratingnot rated

n/aUser voteshigher is better

GraduallyBenchRank 15 of 74

65our own rating0 to 100

Priceno price

n/aper imagelower is better

Summary

Qwen Image 3.0 is an image model from Alibaba. The API lists Standard and Pro as separate model values, not request settings.

Image samples from our tests

These images come from documented single requests with an archived prompt. They complement measurements but do not replace a controlled laboratory test.

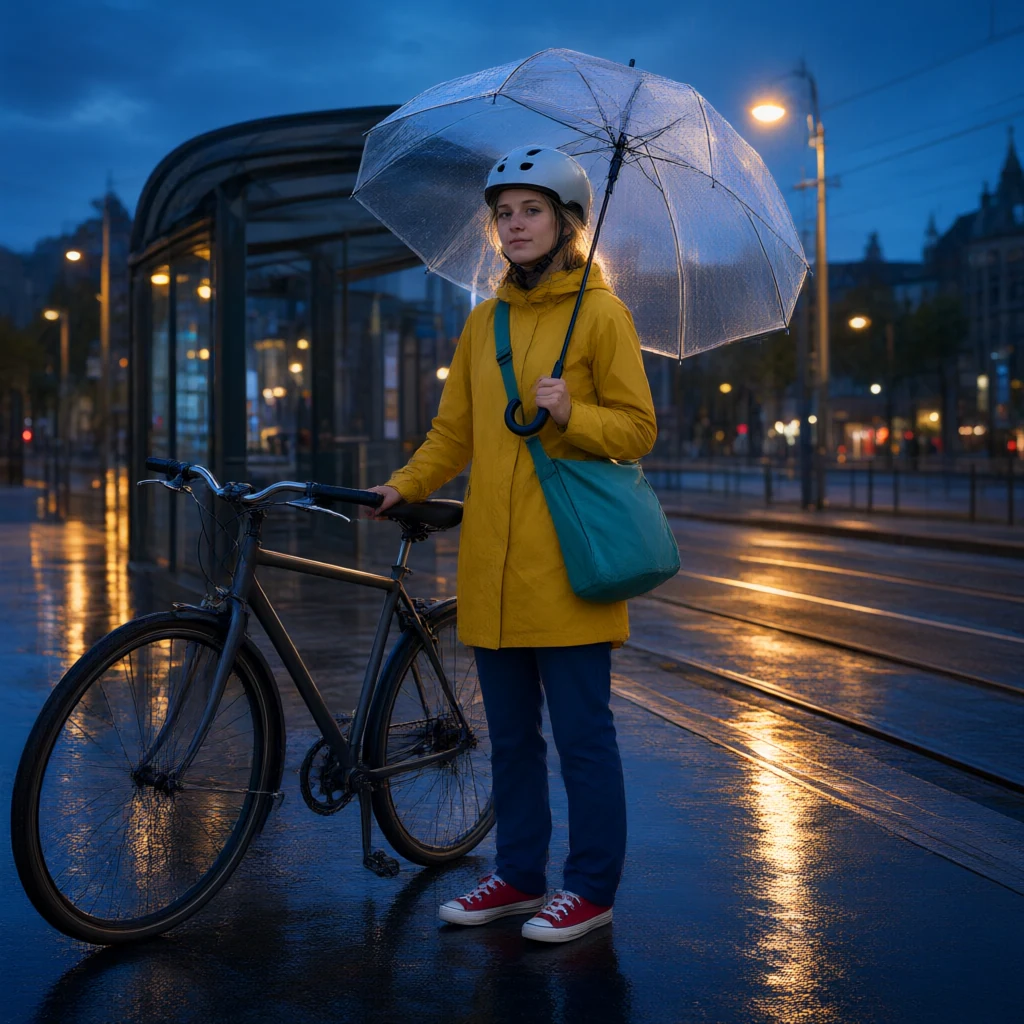
Character and detailOpen Character and detail at original size

Character and detail

This sample tests Anatomy, clothing, and spatial consistency.

Prompt and settings

Create a square cinematic full-body portrait of a fictional bicycle courier waiting under a transparent umbrella at a rainy tram stop in Hamburg at blue hour. She wears a mustard raincoat, navy trousers, red sneakers, a silver helmet, and carries a teal messenger bag. Keep both hands visible, render the bicycle correctly, use realistic wet-street reflections, and include no readable brand names.

Generated through openrouter with model ID qwen/qwen-image-3. Archived settings were aspect ratio 1:1, resolution 1K, n=1, seed=provider random, actual cost $0.030000.

Open source
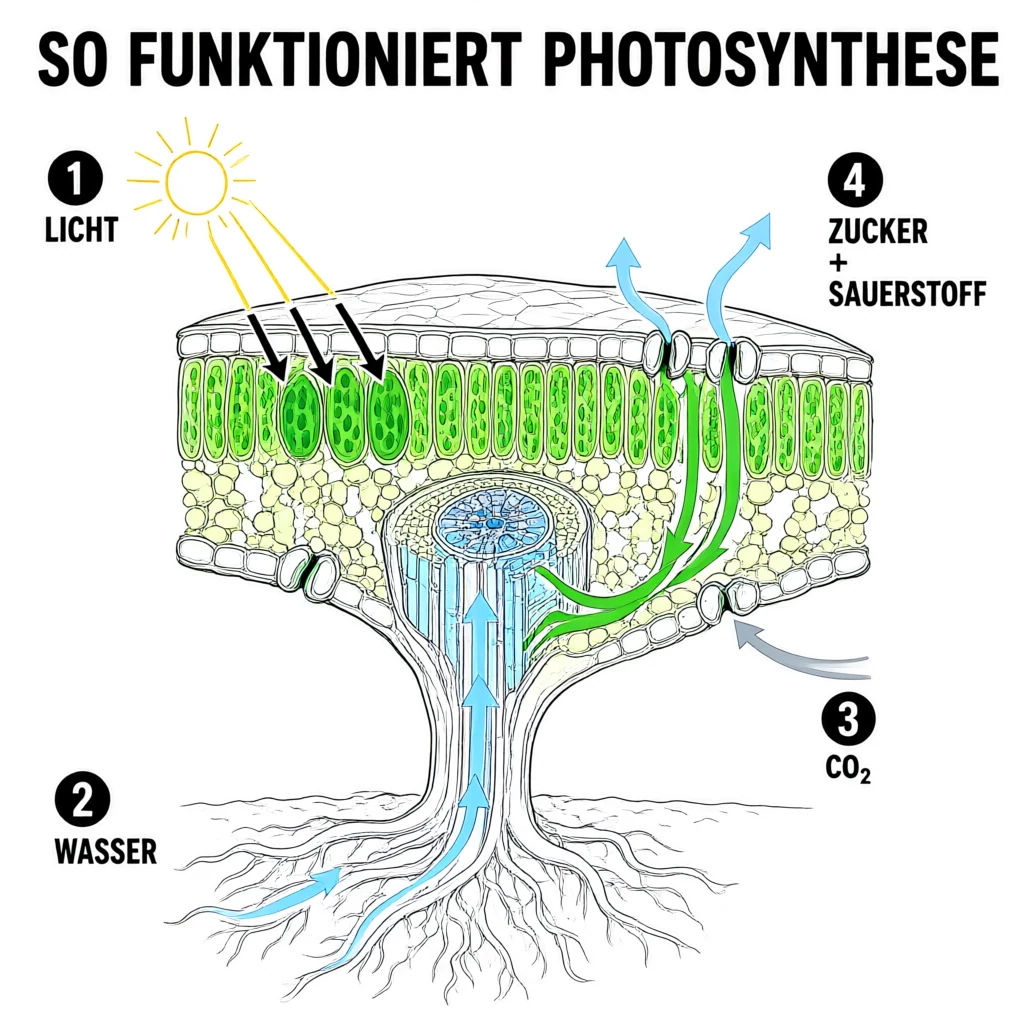
InfographicOpen Infographic at original size

Infographic

This sample tests Numbers, labels, and visual organization.

Prompt and settings

Create a square German infographic titled SO FUNKTIONIERT PHOTOSYNTHESE. Show exactly four numbered steps in this order: 1 LICHT, 2 WASSER, 3 CO₂, 4 ZUCKER + SAUERSTOFF. Use a clean editorial science style with one plant cross-section, simple arrows, high contrast, legible labels, and no other text.

Generated through openrouter with model ID qwen/qwen-image-3. Archived settings were aspect ratio 1:1, resolution 1K, n=1, seed=provider random, actual cost $0.030000.

Open source
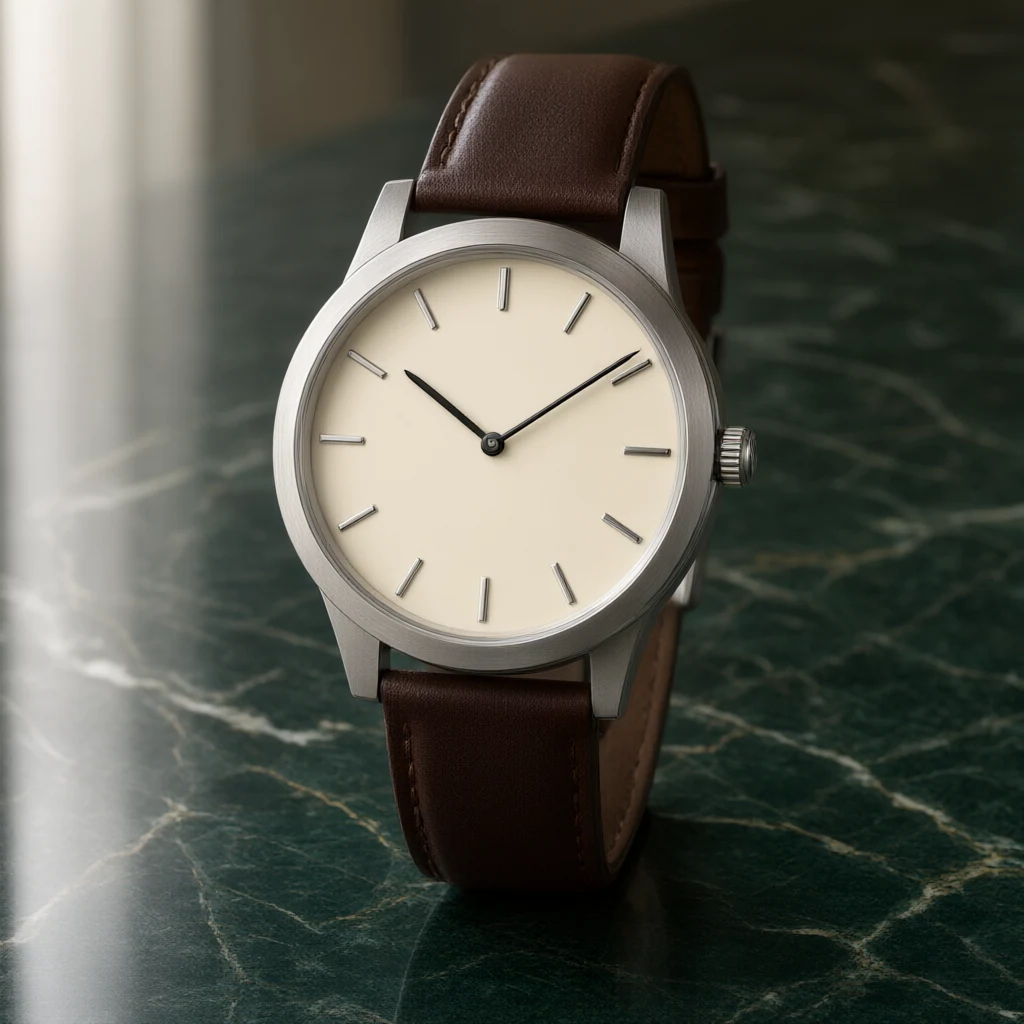
Product photographyOpen Product photography at original size

Product photography

This sample tests Materials, reflections, and fine details.

Prompt and settings

Create a square premium product photograph of a brushed titanium wristwatch standing upright on dark green marble. The watch has a cream dial, thin black hands set to 10:10, twelve distinct hour markers, a realistic crown, and a dark brown leather strap. Soft window light from the left, controlled reflections, shallow depth of field, no text, no logo, no extra objects.

Generated through openrouter with model ID qwen/qwen-image-3. Archived settings were aspect ratio 1:1, resolution 1K, n=1, seed=provider random, actual cost $0.030000.

Open source
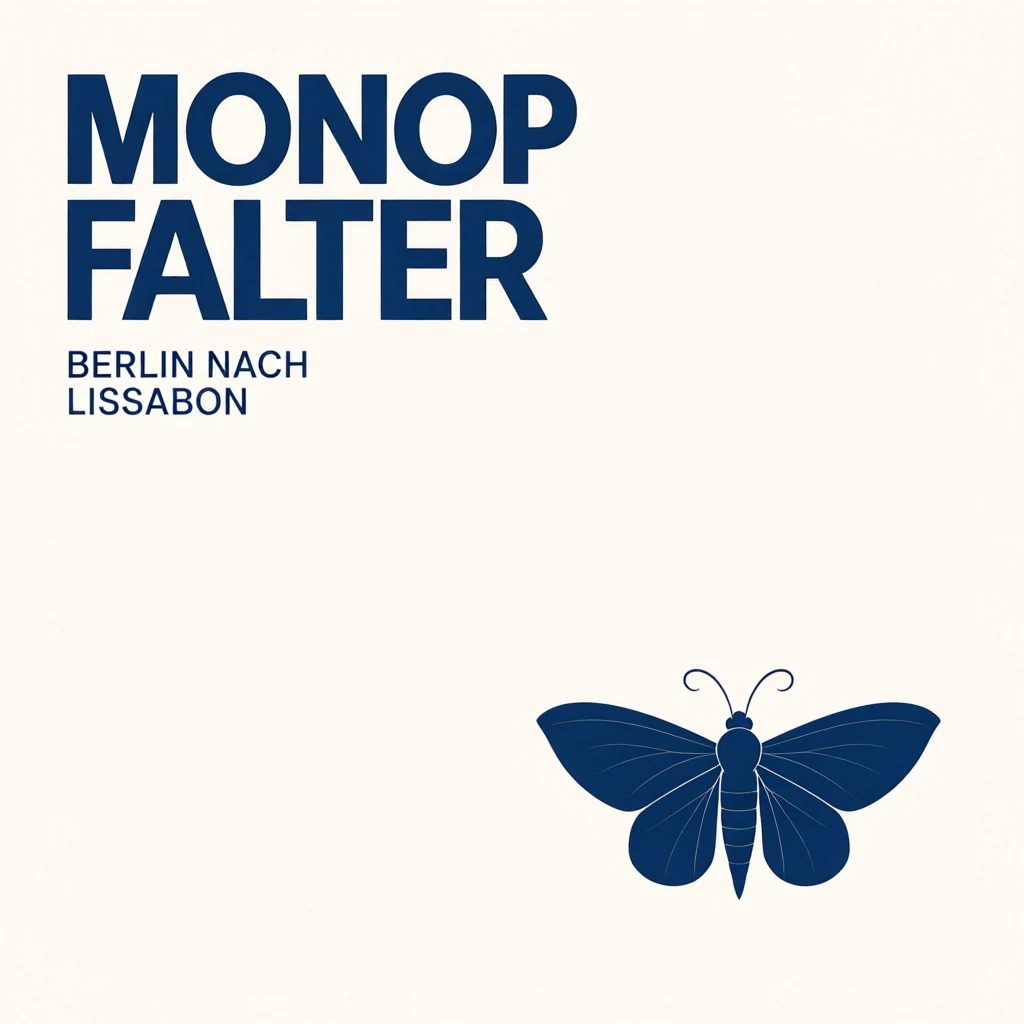
Typography and layoutOpen Typography and layout at original size

Typography and layout

This sample tests Legible text, hierarchy, and composition.

Prompt and settings

Create a square editorial poster for an imaginary night train called MONDFALTER. Show the exact German headline MONDFALTER and the exact subline BERLIN NACH LISSABON. Use a restrained midnight-blue and warm-cream palette, one stylized moth, strong Swiss-grid typography, generous negative space, and no additional words or logos.

Generated through openrouter with model ID qwen/qwen-image-3. Archived settings were aspect ratio 1:1, resolution 1K, n=1, seed=provider random, actual cost $0.030000.

Open source

All benchmark results

Every published result with its source, test setup and comparison models.

Show all 4 published benchmark results

Published benchmarks

Gradually sample test: Typography and layout

The 0-100 value normalizes the mean rank from model-blind comparison rounds. One archived first output contributes per model. This remains an n = 1 sample.

Krea 398.2 rank points
Recraft V4.1 Flash95.9 rank points
Recraft V4.1 Utility91.3 rank points
FLUX 3 Image Klein86.3 rank points
Grok Imagine Image 2.085.8 rank points
MAI-Image-2.583.6 rank points
Wan 2.7 Image Pro81.7 rank points
Ideogram 4.079 rank points
Nano Banana 277.6 rank points
Kling Image 3.0 Omni76.7 rank points
Muse Image76.3 rank points
Nano Banana Pro75.8 rank points
Recraft V4.1 Utility Pro75.8 rank points
Krea 2 Large75.3 rank points
Firefly Image Model 574.4 rank points
FLUX 3 Image74.4 rank points
Qwen Image 2.0 Pro73.5 rank points
Wan 2.7 Image73.5 rank points
Grok Imagine Image 1.073.1 rank points
FLUX.2 Flex71.2 rank points
FLUX.2 Pro70.8 rank points
Nano Banana 2 Lite70.3 rank points
Bria FIBO 268.9 rank points
Krea 2 Medium Turbo68.5 rank points
FLUX.2 Max68 rank points
Seedream 5.0 Pro67.1 rank points
MAI-Image-2.5 Flash65.8 rank points
Luma Uni-1.164.4 rank points
Luma Uni-1.1 Max63 rank points
FLUX.2 Dev61.2 rank points
Seedream 5.0 Flash60.7 rank points
Nano Banana 2.159.8 rank points
GPT Image 1.558 rank points
Recraft V4.156.6 rank points
HiDream-O1-Image-1.555.2 rank points
Z-Image Turbo53.9 rank points
Reve 2.153 rank points
Qwen-Image-2.150.2 rank points
GPT Image 249.3 rank points
GPT Image 2.5 Flare48.4 rank points
GPT Image 2.5 Sunburst47.5 rank points
GPT Image 1 Mini46.6 rank points
MAI-Image-2.6 Flash42.5 rank points
MAI-Image-2.638.8 rank points
Qwen Image 2.1 Turbo38.8 rank points
Seedream 4.035.6 rank points
Runway Gen-4 Image31.5 rank points
Wan 2.6 Text to Image30.1 rank points
Bria FIBO Lite29.7 rank points
Qwen Image 2.1 Pro29.2 rank points
Kling Image 3.026.5 rank points
FLUX.1 Kontext [max]25.1 rank points
Z-Image Base24.7 rank points
FLUX1.1 [pro]23.7 rank points
Qwen Image 3.022.8 rank points
FLUX.2 Klein 9B21.9 rank points
FLUX.2 Klein 4B21 rank points
MiniMax Image-0118.7 rank points
Ideogram 4.515.5 rank points
FLUX.1 Kontext [pro]13.7 rank points
MOSS-Image-SFT12.8 rank points
Adobe Firefly Image 410.5 rank points
HiDream-O1-Image8.2 rank points
Midjourney V8.18.2 rank points
FLUX.1 [dev]7.3 rank points
Lumina-Image 2.01.4 rank points
Adobe Firefly Image 30.5 rank points

higher is betterAs of November 1, 2026Scale: 0 rank points - 100 rank points

Source: Gradually-Bildtest
gradually.ai
Methodology and context
Metric
rank-score-100
Scale
0-100
Participants
74
Sample
1
Methodology and context
One archived, unfiltered first output per model. All 74 images are ranked in three model-blind orderings. The 0-100 value normalizes the mean rank. This remains an n = 1 sample, and an automated judge may have visual preferences of its own.
Source: Gradually-Bildtest

Gradually sample test: Product photography

The 0-100 value normalizes the mean rank from model-blind comparison rounds. One archived first output contributes per model. This remains an n = 1 sample.

GPT Image 2.5 Sunburst93.2 rank points
MAI-Image-2.5 Flash92.2 rank points
Muse Image89.5 rank points
Grok Imagine Image 1.088.6 rank points
GPT Image 287.2 rank points
Krea 2 Large87.2 rank points
Qwen Image 2.1 Pro86.8 rank points
Qwen Image 3.086.3 rank points
MAI-Image-2.6 Flash84 rank points
Krea 383.6 rank points
MAI-Image-2.683.6 rank points
Qwen Image 2.1 Turbo83.6 rank points
Wan 2.7 Image82.6 rank points
Seedream 5.0 Pro81.7 rank points
Nano Banana 2.179.9 rank points
Wan 2.7 Image Pro79.9 rank points
Grok Imagine Image 2.075.8 rank points
Nano Banana 2 Lite74 rank points
Recraft V4.173.1 rank points
Qwen-Image-2.172.2 rank points
FLUX.2 Klein 9B71.7 rank points
Nano Banana Pro71.7 rank points
Krea 2 Medium Turbo67.1 rank points
Reve 2.166.7 rank points
Bria FIBO 259.4 rank points
Ideogram 4.558.9 rank points
Luma Uni-1.158.9 rank points
MAI-Image-2.558.9 rank points
MOSS-Image-SFT57.5 rank points
FLUX.2 Flex56.2 rank points
Luma Uni-1.1 Max56.2 rank points
FLUX.2 Klein 4B54.3 rank points
FLUX.2 Max52.1 rank points
Bria FIBO Lite50.2 rank points
Seedream 5.0 Flash48.9 rank points
FLUX.2 Pro47 rank points
Recraft V4.1 Flash47 rank points
HiDream-O1-Image-1.543.8 rank points
GPT Image 1 Mini43.4 rank points
FLUX 3 Image42.9 rank points
FLUX 3 Image Klein42.9 rank points
FLUX.2 Dev40.2 rank points
FLUX.1 [dev]39.7 rank points
Kling Image 3.039.3 rank points
Qwen Image 2.0 Pro39.3 rank points
Nano Banana 238.8 rank points
GPT Image 1.537.9 rank points
GPT Image 2.5 Flare37.9 rank points
Wan 2.6 Text to Image37.9 rank points
Midjourney V8.136.5 rank points
Seedream 4.031.1 rank points
Recraft V4.1 Utility30.1 rank points
Z-Image Turbo28.3 rank points
Firefly Image Model 524.2 rank points
FLUX1.1 [pro]21.9 rank points
Kling Image 3.0 Omni21.5 rank points
FLUX.1 Kontext [pro]21 rank points
Runway Gen-4 Image19.6 rank points
HiDream-O1-Image19.2 rank points
Z-Image Base15.1 rank points
MiniMax Image-0111.9 rank points
FLUX.1 Kontext [max]9.1 rank points
Ideogram 4.08.2 rank points
Lumina-Image 2.03.7 rank points
Adobe Firefly Image 31.4 rank points

higher is betterAs of November 1, 2026Scale: 0 rank points - 100 rank points

Source: Gradually-Bildtest
gradually.ai
Methodology and context
Metric
rank-score-100
Scale
0-100
Participants
74
Sample
1
Methodology and context
One archived, unfiltered first output per model. All 74 images are ranked in three model-blind orderings. The 0-100 value normalizes the mean rank. This remains an n = 1 sample, and an automated judge may have visual preferences of its own.
Source: Gradually-Bildtest

Gradually sample test: Character and detail

The 0-100 value normalizes the mean rank from model-blind comparison rounds. One archived first output contributes per model. This remains an n = 1 sample.

Firefly Image Model 586.8 rank points
MAI-Image-2.5 Flash86.3 rank points
Qwen Image 2.0 Pro85.8 rank points
FLUX.2 Pro85.4 rank points
FLUX.2 Max84.5 rank points
HiDream-O1-Image-1.583.1 rank points
Seedream 5.0 Pro82.6 rank points
GPT Image 2.5 Flare82.2 rank points
FLUX 3 Image Klein81.7 rank points
Recraft V4.1 Utility78.5 rank points
Krea 378.1 rank points
GPT Image 2.5 Sunburst74.4 rank points
FLUX 3 Image72.6 rank points
Wan 2.6 Text to Image72.6 rank points
Ideogram 4.568 rank points
Wan 2.7 Image Pro68 rank points
Qwen Image 2.1 Pro67.1 rank points
Nano Banana 2.166.7 rank points
GPT Image 1.564.4 rank points
Luma Uni-1.1 Max64.4 rank points
Muse Image63.9 rank points
Ideogram 4.062.1 rank points
Nano Banana 262.1 rank points
GPT Image 260.7 rank points
FLUX.2 Dev60.3 rank points
FLUX.2 Klein 9B59.4 rank points
Qwen Image 3.059.4 rank points
FLUX.2 Flex58 rank points
Grok Imagine Image 2.057.1 rank points
Grok Imagine Image 1.056.6 rank points
MAI-Image-2.556.6 rank points
Bria FIBO Lite55.2 rank points
FLUX.1 Kontext [pro]54.8 rank points
Qwen Image 2.1 Turbo53 rank points
FLUX.2 Klein 4B52.5 rank points
Bria FIBO 249.3 rank points
Luma Uni-1.147.9 rank points
Nano Banana Pro46.6 rank points
Z-Image Base46.6 rank points
Adobe Firefly Image 446.1 rank points
Recraft V4.1 Utility Pro46.1 rank points
Z-Image Turbo46.1 rank points
Wan 2.7 Image45.7 rank points
MAI-Image-2.643.8 rank points
Reve 2.142 rank points
FLUX.1 [dev]39.7 rank points
Seedream 4.039.7 rank points
Krea 2 Medium Turbo37.9 rank points
Recraft V4.137 rank points
FLUX1.1 [pro]35.6 rank points
MAI-Image-2.6 Flash35.6 rank points
Kling Image 3.0 Omni35.2 rank points
Nano Banana 2 Lite35.2 rank points
Krea 2 Large34.2 rank points
Seedream 5.0 Flash34.2 rank points
HiDream-O1-Image26.9 rank points
MiniMax Image-0123.3 rank points
Runway Gen-4 Image22.4 rank points
Kling Image 3.021.9 rank points
Midjourney V8.121.9 rank points
Qwen-Image-2.121 rank points
Recraft V4.1 Flash21 rank points
Lumina-Image 2.017.4 rank points
MOSS-Image-SFT17.4 rank points
Adobe Firefly Image 38.7 rank points
FLUX.1 Kontext [max]8.7 rank points
GPT Image 1 Mini7.8 rank points

higher is betterAs of November 1, 2026Scale: 0 rank points - 100 rank points

Source: Gradually-Bildtest
gradually.ai
Methodology and context
Metric
rank-score-100
Scale
0-100
Participants
74
Sample
1
Methodology and context
One archived, unfiltered first output per model. All 74 images are ranked in three model-blind orderings. The 0-100 value normalizes the mean rank. This remains an n = 1 sample, and an automated judge may have visual preferences of its own.
Source: Gradually-Bildtest

Gradually sample test: Infographic

The 0-100 value normalizes the mean rank from model-blind comparison rounds. One archived first output contributes per model. This remains an n = 1 sample.

Luma Uni-1.195.4 rank points
Qwen Image 2.1 Turbo93.2 rank points
MAI-Image-2.5 Flash91.8 rank points
GPT Image 2.5 Sunburst91.3 rank points
Qwen Image 3.091.3 rank points
Reve 2.190.4 rank points
Seedream 5.0 Pro86.8 rank points
Grok Imagine Image 1.084.9 rank points
Ideogram 4.084.9 rank points
Krea 2 Large84.9 rank points
Krea 384.9 rank points
Qwen-Image-2.182.2 rank points
Ideogram 4.581.7 rank points
Seedream 5.0 Flash78.5 rank points
GPT Image 278.1 rank points
Grok Imagine Image 2.077.6 rank points
FLUX.2 Dev74.9 rank points
HiDream-O1-Image-1.574.9 rank points
MOSS-Image-SFT74.9 rank points
FLUX 3 Image Klein73.5 rank points
Krea 2 Medium Turbo73.1 rank points
Nano Banana 2.170.8 rank points
Bria FIBO 269.9 rank points
Luma Uni-1.1 Max69.4 rank points
Seedream 4.068.9 rank points
GPT Image 2.5 Flare65.8 rank points
Muse Image65.8 rank points
Recraft V4.1 Utility Pro62.1 rank points
Wan 2.7 Image Pro61.6 rank points
Recraft V4.161.2 rank points
Wan 2.6 Text to Image60.3 rank points
FLUX 3 Image58.9 rank points
MAI-Image-2.6 Flash58.9 rank points
Wan 2.7 Image56.2 rank points
GPT Image 1.555.7 rank points
Nano Banana 2 Lite55.2 rank points
Recraft V4.1 Flash55.2 rank points
MAI-Image-2.549.8 rank points
Recraft V4.1 Utility48.9 rank points
Qwen Image 2.0 Pro48.4 rank points
FLUX.2 Max47.9 rank points
Nano Banana Pro47.9 rank points
FLUX.1 Kontext [max]43.8 rank points
Nano Banana 243.4 rank points
FLUX.2 Flex40.6 rank points
MAI-Image-2.640.2 rank points
FLUX.2 Pro37.4 rank points
FLUX.1 Kontext [pro]32.9 rank points
FLUX.1 [dev]27.4 rank points
Runway Gen-4 Image26.9 rank points
Kling Image 3.026.5 rank points
FLUX.2 Klein 9B26 rank points
Qwen Image 2.1 Pro26 rank points
HiDream-O1-Image25.1 rank points
Midjourney V8.123.7 rank points
Z-Image Turbo20.5 rank points
FLUX.2 Klein 4B19.2 rank points
Kling Image 3.0 Omni17.8 rank points
FLUX1.1 [pro]17.4 rank points
Z-Image Base10 rank points
MiniMax Image-018.2 rank points
GPT Image 1 Mini7.8 rank points
Bria FIBO Lite7.3 rank points
Lumina-Image 2.06.4 rank points
Adobe Firefly Image 34.1 rank points

higher is betterAs of November 1, 2026Scale: 0 rank points - 100 rank points

Source: Gradually-Bildtest
gradually.ai
Methodology and context
Metric
rank-score-100
Scale
0-100
Participants
74
Sample
1
Methodology and context
One archived, unfiltered first output per model. All 74 images are ranked in three model-blind orderings. The 0-100 value normalizes the mean rank. This remains an n = 1 sample, and an automated judge may have visual preferences of its own.
Source: Gradually-Bildtest

Recorded measurement details

Gradually sample test: Typography and layout (Show measurement, test conditions, and source)
Source value
22.8
Score
22.8
Metric
rank-score-100
Unit
rank score
Direction
Higher is better
Source rank
58
Sample
1
Source type
gradually-sample-test
Evaluator
gemini-3.1-pro-preview
Retrieved at
2026-11-01
Methodology
One archived, unfiltered first output per model. All 74 images are ranked in three model-blind orderings. The 0-100 value normalizes the mean rank. This remains an n = 1 sample, and an automated judge may have visual preferences of its own.
Mean rank
57.33
Individual ranks
63, 52, 57
Criterion scores
headline 1, subline 1.67, text-control 1.33, visual-brief 1.67, layout 1.33
Source Gradually-Bildtest
Gradually sample test: Product photography (Show measurement, test conditions, and source)
Source value
86.3
Score
86.3
Metric
rank-score-100
Unit
rank score
Direction
Higher is better
Source rank
8
Sample
1
Source type
gradually-sample-test
Evaluator
gemini-3.1-pro-preview
Retrieved at
2026-11-01
Methodology
One archived, unfiltered first output per model. All 74 images are ranked in three model-blind orderings. The 0-100 value normalizes the mean rank. This remains an n = 1 sample, and an automated judge may have visual preferences of its own.
Mean rank
11
Individual ranks
5, 19, 9
Criterion scores
subject 1.33, time 1.33, watch-details 1.33, photography 1.33, exclusions 1.33
Source Gradually-Bildtest
Gradually sample test: Character and detail (Show measurement, test conditions, and source)
Source value
59.4
Score
59.4
Metric
rank-score-100
Unit
rank score
Direction
Higher is better
Source rank
27
Sample
1
Source type
gradually-sample-test
Evaluator
gemini-3.1-pro-preview
Retrieved at
2026-11-01
Methodology
One archived, unfiltered first output per model. All 74 images are ranked in three model-blind orderings. The 0-100 value normalizes the mean rank. This remains an n = 1 sample, and an automated judge may have visual preferences of its own.
Mean rank
30.67
Individual ranks
48, 2, 42
Criterion scores
scene 2, wardrobe 2, anatomy 1.33, props 1.33, environment 2
Source Gradually-Bildtest
Gradually sample test: Infographic (Show measurement, test conditions, and source)
Source value
91.3
Score
91.3
Metric
rank-score-100
Unit
rank score
Direction
Higher is better
Source rank
4
Sample
1
Source type
gradually-sample-test
Evaluator
gemini-3.1-pro-preview
Retrieved at
2026-11-01
Methodology
One archived, unfiltered first output per model. All 74 images are ranked in three model-blind orderings. The 0-100 value normalizes the mean rank. This remains an n = 1 sample, and an automated judge may have visual preferences of its own.
Mean rank
7.33
Individual ranks
2, 15, 5
Criterion scores
title 1.67, sequence 1.67, labels 1.67, diagram 1.67, clarity 1.67
Source Gradually-Bildtest

Head-to-head comparisons

Show all comparisons (139)

All specifications

Input and output

Maximum output
2K
Source: Maximum output

Licence and access

Access
API, Web
Source: Access

API

Native API model ID
qwen-image-3.0; separate standard ID alongside qwen-image-3.0-pro.
Source: Native API model ID

Further details

Distinction
The API lists Standard and Pro as separate model values, not request settings.
Source: Distinction

Prices

Choose a price view
OpenRouter (qwen/qwen-image-3)
$0.03 per image (estimated)Source
fal.ai (alibaba/qwen-image-3/text-to-image)
$0.04 per image (estimated)Source

No Alibaba subscription includes this model. Through other providers from €19.04 a month (Magnific Premium, with limited credits). 6 plans in Germany.

Filter plans
PlanMonthly priceNote
Magnific Premium€19.04with limited credit
Magnific Premium+€42.84with limited credit
Magnific Business€70.21with limited credit, for teams, per seat
Magnific Pro Starter€104.72with limited credit
Magnific Pro€273.70with limited credit
Magnific Enterprisen/afor enterprises

All plans in the AI subscription comparison

Frequently asked questions about Qwen Image 3.0

How good is Qwen Image 3.0?

Rank 15 of 74 in our own test.

GraduallyBench from Nov 1, 2026

GraduallyBenchour own rating, 0 to 100 · higher is better
GPT Image 269
Qwen Image 2.1 Turbo67
Luma Uni-1.167
Qwen Image 3.0Rank 15 of 7465
Wan 2.7 Image65
HiDream-O1-Image-1.564
HunyuanImage 3.0 Instruct64

What is Qwen Image 3.0 good at?

Best at Infographic (91 out of 100), weakest at Typography and layout (23).

GraduallyBench, one image per task

  1. Qwen Image 3.0: Typography and layoutTypography and layoutLegible text, hierarchy, and composition23out of 100Rank 58 of 74 in this task
  2. Qwen Image 3.0: Product photographyProduct photographyMaterials, reflections, and fine details86out of 100Rank 8 of 74 in this task
  3. Qwen Image 3.0: Character and detailCharacter and detailAnatomy, clothing, and spatial consistency59out of 100Rank 27 of 74 in this task
  4. Qwen Image 3.0: InfographicInfographicNumbers, labels, and visual organization91out of 100Rank 4 of 74 in this task

Where can I use Qwen Image 3.0?

Not in a Alibaba subscription. Including other providers that makes 6 plans in Germany.

Subscription comparison, prices in Germany incl. VAT

At Alibaba

No Alibaba subscription includes this model.

Through other providers

6 plans from 1 provider, from €19.04 a month (Magnific Premium), with limited credits.

Sources and data date

Benchmark sources at a glance

Which independent evaluators tested this model. This is coverage, not a quality ranking.

No active result from the reviewed external evaluators can currently be attributed to this model. Other source evidence remains available below.

Without vendor claims and historical or disputed results; those stay labelled in the single values.