AlibabaImage model

Wan 2.6 Text to Image

Wan 2.6 Text to Image is rank 44 of 108 in our GraduallyBench test.

Arena ratingnot rated

n/aUser voteshigher is better

GraduallyBenchRank 44 of 108

63our own rating0 to 100

PriceRank 6 of 28

$0.03per imagelower is better

PopularityRank 630 of 875

13out of 100same as last month

Summary

At $0.03 per image it is cheap; a typical image model costs $0.06.

Wan 2.6 Text to Image combines Alibaba’s proprietary text-based generation up to 2K with editing in the same API. In editing mode, you can provide one to four reference images, transfer a style, and keep a person or product consistent across variations.

The API defaults to 1K and offers 2K as a separate output option. Editing requires at least one reference image. Prompt extension can expand the positive prompt automatically, while the negative prompt stays unchanged. The weights are proprietary, and the cataloged access path is the API rather than a local installation.

Image samples from our tests

These images come from documented single requests with an archived prompt. They complement measurements but do not replace a controlled laboratory test.

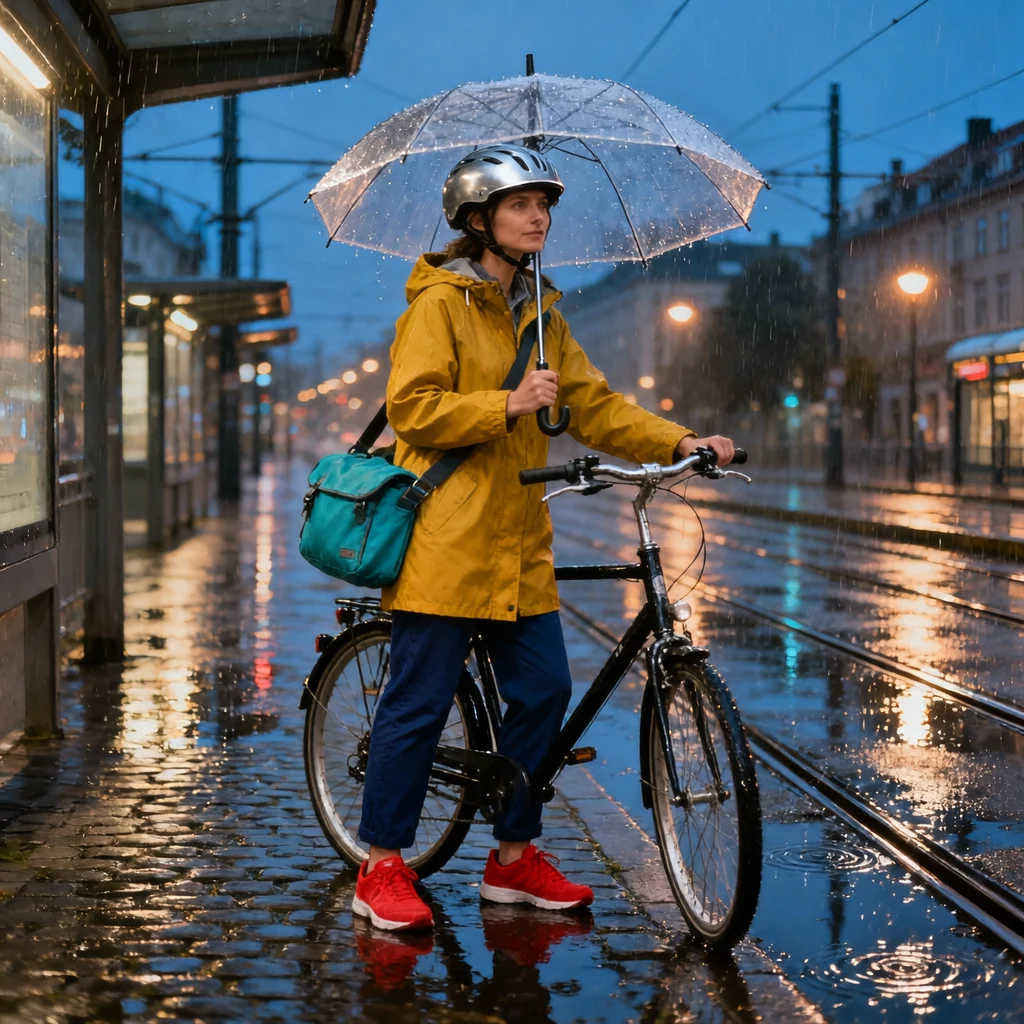
Character and detailOpen Character and detail at original size

Character and detail

This sample tests Anatomy, clothing, and spatial consistency.

Prompt and settings

Create a square cinematic full-body portrait of a fictional bicycle courier waiting under a transparent umbrella at a rainy tram stop in Hamburg at blue hour. She wears a mustard raincoat, navy trousers, red sneakers, a silver helmet, and carries a teal messenger bag. Keep both hands visible, render the bicycle correctly, use realistic wet-street reflections, and include no readable brand names.

Generated through together with model ID Wan-AI/Wan2.6-image. Archived settings were requested 1280x1280, stored 1024x1024 (Lanczos3 downscale), n=1, seed=provider random, provider default steps.

Open source
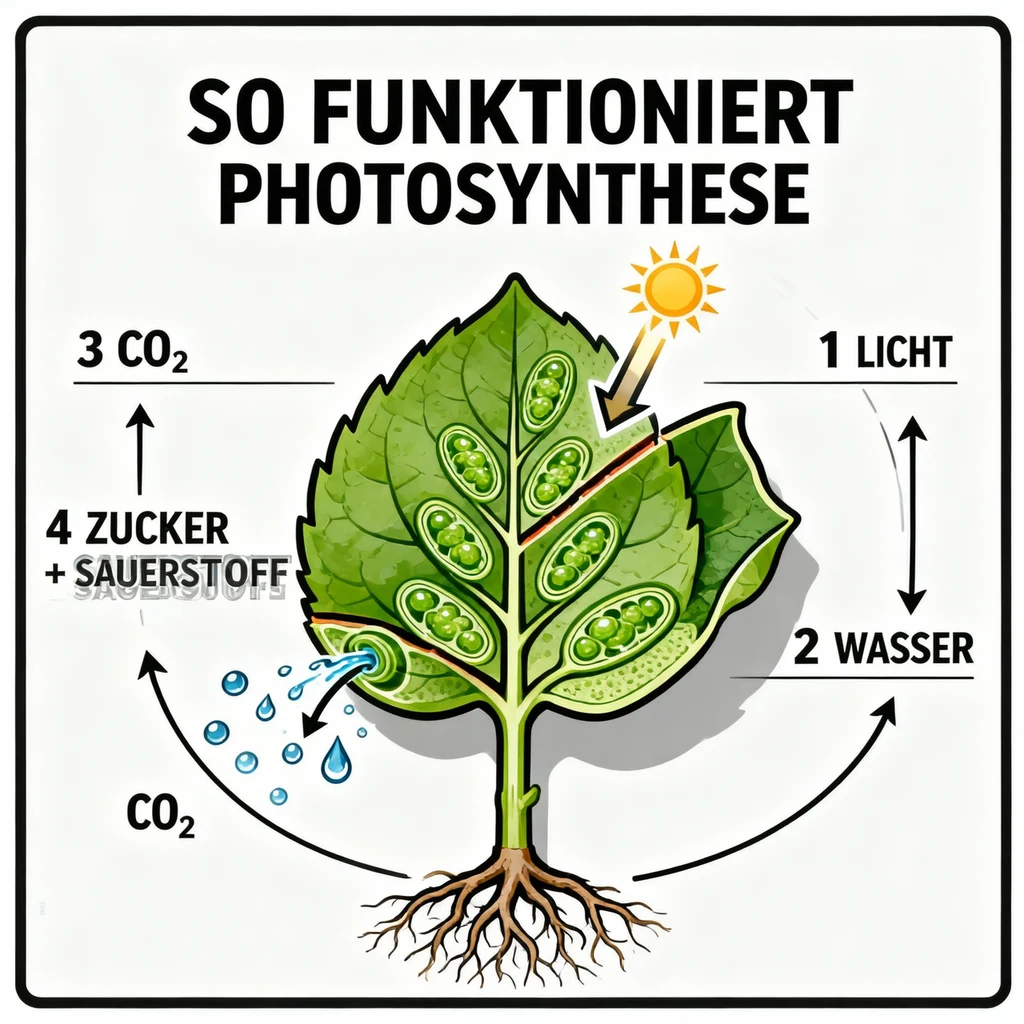
InfographicOpen Infographic at original size

Infographic

This sample tests Numbers, labels, and visual organization.

Prompt and settings

Create a square German infographic titled SO FUNKTIONIERT PHOTOSYNTHESE. Show exactly four numbered steps in this order: 1 LICHT, 2 WASSER, 3 CO₂, 4 ZUCKER + SAUERSTOFF. Use a clean editorial science style with one plant cross-section, simple arrows, high contrast, legible labels, and no other text.

Generated through together with model ID Wan-AI/Wan2.6-image. Archived settings were requested 1280x1280, stored 1024x1024 (Lanczos3 downscale), n=1, seed=provider random, provider default steps.

Open source
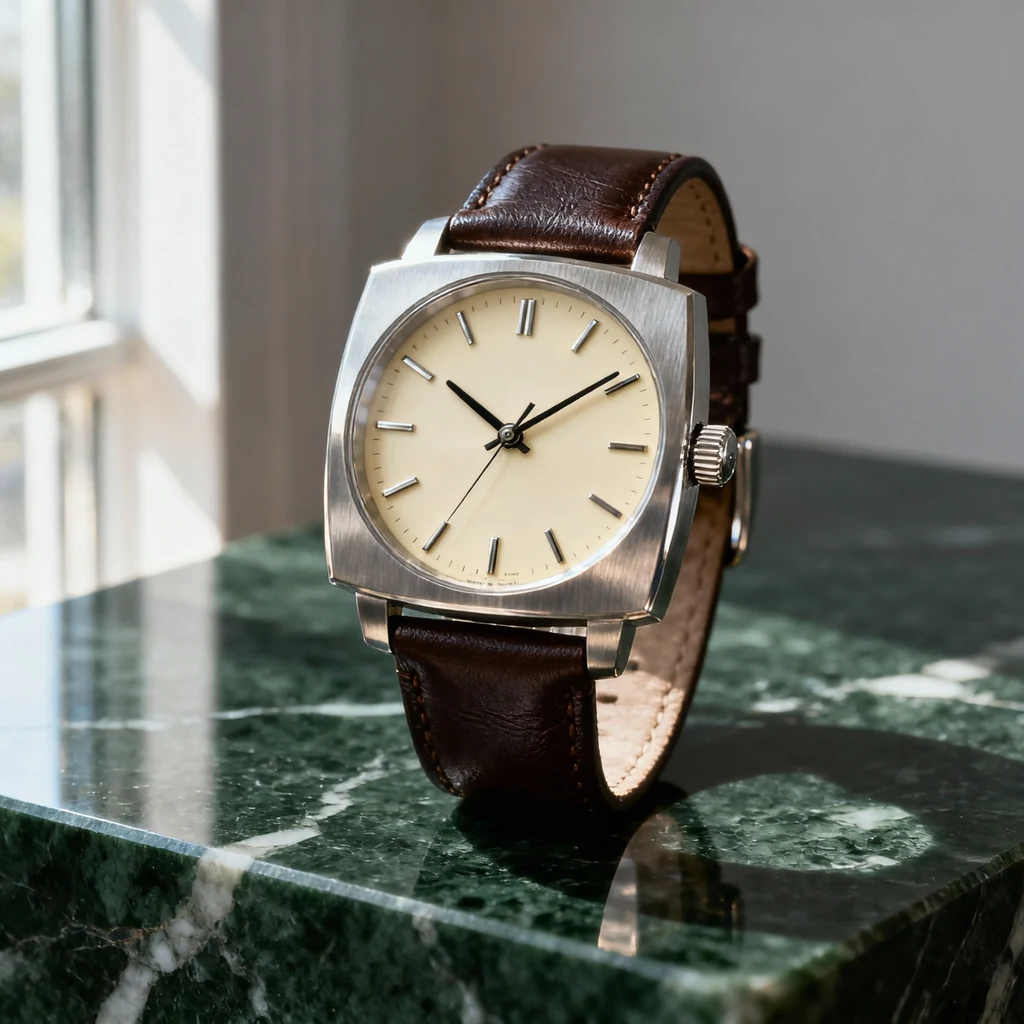
Product photographyOpen Product photography at original size

Product photography

This sample tests Materials, reflections, and fine details.

Prompt and settings

Create a square premium product photograph of a brushed titanium wristwatch standing upright on dark green marble. The watch has a cream dial, thin black hands set to 10:10, twelve distinct hour markers, a realistic crown, and a dark brown leather strap. Soft window light from the left, controlled reflections, shallow depth of field, no text, no logo, no extra objects.

Generated through together with model ID Wan-AI/Wan2.6-image. Archived settings were requested 1280x1280, stored 1024x1024 (Lanczos3 downscale), n=1, seed=provider random, provider default steps.

Open source
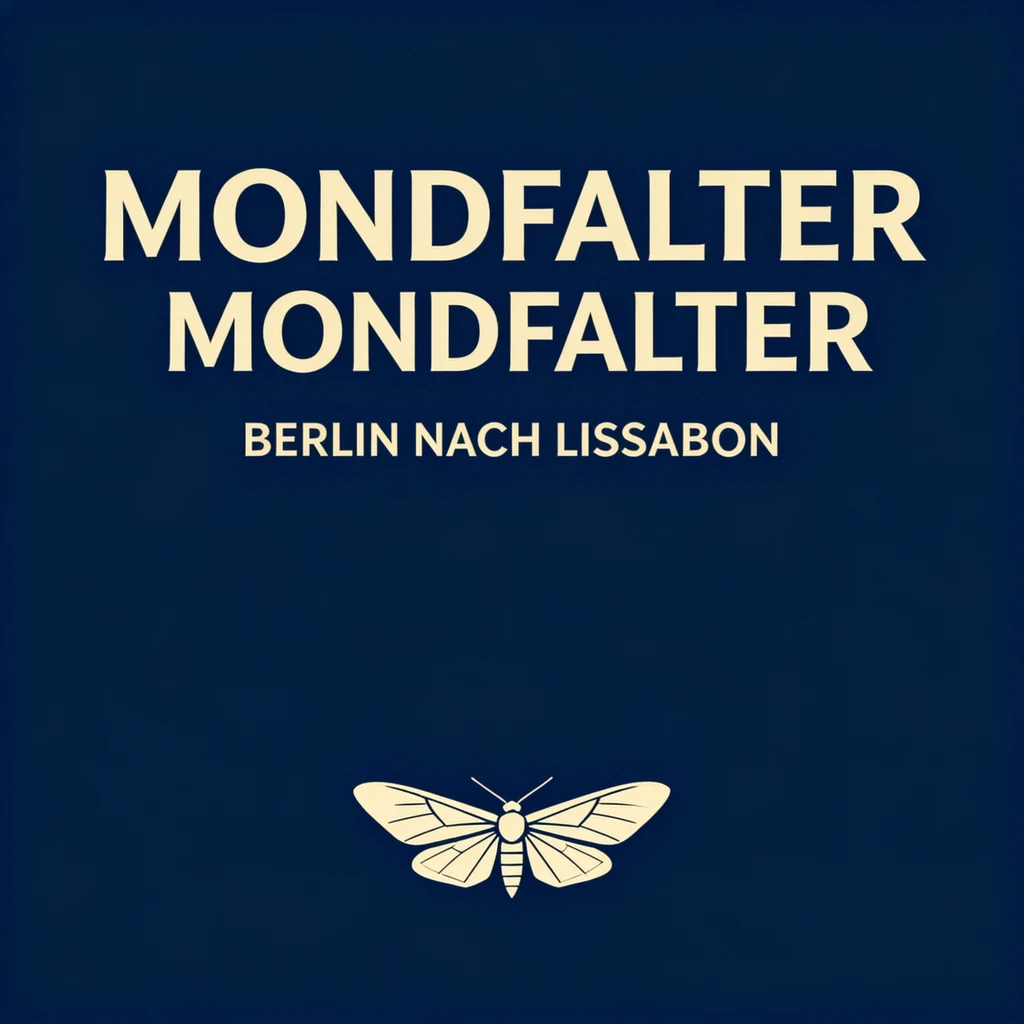
Typography and layoutOpen Typography and layout at original size

Typography and layout

This sample tests Legible text, hierarchy, and composition.

Prompt and settings

Create a square editorial poster for an imaginary night train called MONDFALTER. Show the exact German headline MONDFALTER and the exact subline BERLIN NACH LISSABON. Use a restrained midnight-blue and warm-cream palette, one stylized moth, strong Swiss-grid typography, generous negative space, and no additional words or logos.

Generated through together with model ID Wan-AI/Wan2.6-image. Archived settings were requested 1280x1280, stored 1024x1024 (Lanczos3 downscale), n=1, seed=provider random, provider default steps.

Open source

All benchmark results

Every published result with its source, test setup and comparison models.

Show all 23 published benchmark results

Page 1 of 2

Published benchmarks

Text to Image Arena

Elo ratings summarize pairwise comparisons within this leaderboard. They are not percentages. The scale does not express absolute quality or linear gaps between models.

GPT Image 21,187.61 Elo
MAI-Image-2.61,168.32 Elo
Nano Banana 21,141.6 Elo
Muse Image1,127.86 Elo
GPT Image 1.51,123.86 Elo
MAI-Image-2.51,120.06 Elo
Nano Banana Pro1,118.67 Elo
Nano Banana 2 Lite1,109.07 Elo
Seedream 5.0 Pro1,101.17 Elo
Qwen-Image-2.11,045.48 Elo
Krea 2 Large1,035.45 Elo
Qwen Image 2.0 Pro1,031.23 Elo
FLUX.2 Flex1,027.68 Elo
FLUX.2 Max1,020.57 Elo
Wan 2.6 Text to Image1,017.69 Elo
Ideogram 4.51,015.99 Elo
FLUX.2 Pro1,003.17 Elo
Ideogram 4.01,002.93 Elo
FLUX.2 Klein 9B932.08 Elo

higher is betterAs of November 6, 2026Scale: 0 Elo - 1,227.25 Elo

Source: Artificial Analysis
gradually.ai
Methodology and context
Metric
elo-rating
Scale
No upper bound is documented. The chart spans the recorded values and zero.
Participants
30
Methodology and context
AA appearances: 5817. This count does not establish an independent sample. Lower rank: 29. Upper rank: 44. Source model ID: caa670a4-e827-4a4b-84fb-2dd240205fe2. Evidence capture ID: aa-image-text-to-image-v2.1-2026-11-06-e430d57b5d0b. Source payload hash: e430d57b5d0bf260d6feb60bb7d8fa32da8d7961ec2bd9a9cae58fb015613cf0
Source: Artificial Analysis

GEBench

GEBench Chinese, single-step

Nano Banana Pro84.5 points
GPT Image 1.583.79 points
FLUX.2 Pro68.83 points
Wan 2.6 Text to Image64.2 points
Seedream 4.062.04 points

higher is betterAs of August 26, 2026Scale: 0 points - 100 points

Source: GEBench
gradually.ai
Methodology and context
Metric
points-100
Scale
0-100
Participants
5
Methodology and context
A bilingual graphical-user-interface benchmark. Chinese and English subsets and the single-step, multi-step, fictional-app, real-app, and grounding categories remain separate.
Source: GEBench

GEBench Chinese, multi-step

Nano Banana Pro68.65 points
GPT Image 1.556.97 points
FLUX.2 Pro55.07 points
Wan 2.6 Text to Image50.11 points
Seedream 4.048.64 points

higher is betterAs of August 26, 2026Scale: 0 points - 100 points

Source: GEBench
gradually.ai
Methodology and context
Metric
points-100
Scale
0-100
Participants
5
Methodology and context
A bilingual graphical-user-interface benchmark. Chinese and English subsets and the single-step, multi-step, fictional-app, real-app, and grounding categories remain separate.
Source: GEBench

GEBench Chinese, fictional app

Nano Banana Pro65.75 points
GPT Image 1.560.11 points
FLUX.2 Pro58.13 points
Wan 2.6 Text to Image52.72 points
Seedream 4.049.28 points

higher is betterAs of August 26, 2026Scale: 0 points - 100 points

Source: GEBench
gradually.ai
Methodology and context
Metric
points-100
Scale
0-100
Participants
5
Methodology and context
A bilingual graphical-user-interface benchmark. Chinese and English subsets and the single-step, multi-step, fictional-app, real-app, and grounding categories remain separate.
Source: GEBench

GEBench Chinese, real app

Nano Banana Pro64.35 points
GPT Image 1.555.65 points
FLUX.2 Pro55.41 points
Seedream 4.050.93 points
Wan 2.6 Text to Image50.4 points

higher is betterAs of August 26, 2026Scale: 0 points - 100 points

Source: GEBench
gradually.ai
Methodology and context
Metric
points-100
Scale
0-100
Participants
5
Methodology and context
A bilingual graphical-user-interface benchmark. Chinese and English subsets and the single-step, multi-step, fictional-app, real-app, and grounding categories remain separate.
Source: GEBench

GEBench Chinese, grounding

Nano Banana Pro64.83 points
Wan 2.6 Text to Image59.58 points
Seedream 4.053.53 points
GPT Image 1.553.33 points
FLUX.2 Pro50.24 points

higher is betterAs of August 26, 2026Scale: 0 points - 100 points

Source: GEBench
gradually.ai
Methodology and context
Metric
points-100
Scale
0-100
Participants
5
Methodology and context
A bilingual graphical-user-interface benchmark. Chinese and English subsets and the single-step, multi-step, fictional-app, real-app, and grounding categories remain separate.
Source: GEBench

GEBench Chinese, overall

Nano Banana Pro69.62 points
GPT Image 1.563.22 points
FLUX.2 Pro57.54 points
Wan 2.6 Text to Image55.4 points
Seedream 4.052.88 points

higher is betterAs of August 26, 2026Scale: 0 points - 100 points

Source: GEBench
gradually.ai
Methodology and context
Metric
points-100
Scale
0-100
Participants
5
Methodology and context
A bilingual graphical-user-interface benchmark. Chinese and English subsets and the single-step, multi-step, fictional-app, real-app, and grounding categories remain separate.
Source: GEBench

GEBench English, single-step

Nano Banana Pro84.32 points
GPT Image 1.580.8 points
FLUX.2 Pro61 points
Wan 2.6 Text to Image60.17 points
Seedream 4.053.28 points

higher is betterAs of August 26, 2026Scale: 0 points - 100 points

Source: GEBench
gradually.ai
Methodology and context
Metric
points-100
Scale
0-100
Participants
5
Methodology and context
A bilingual graphical-user-interface benchmark. Chinese and English subsets and the single-step, multi-step, fictional-app, real-app, and grounding categories remain separate.
Source: GEBench

GEBench English, multi-step

Nano Banana Pro69.51 points
GPT Image 1.558.87 points
FLUX.2 Pro52.17 points
Wan 2.6 Text to Image44.36 points
Seedream 4.037.57 points

higher is betterAs of August 26, 2026Scale: 0 points - 100 points

Source: GEBench
gradually.ai
Methodology and context
Metric
points-100
Scale
0-100
Participants
5
Methodology and context
A bilingual graphical-user-interface benchmark. Chinese and English subsets and the single-step, multi-step, fictional-app, real-app, and grounding categories remain separate.
Source: GEBench

GEBench English, fictional app

GPT Image 1.563.68 points
FLUX.2 Pro49.92 points
Wan 2.6 Text to Image49.55 points
Seedream 4.047.92 points
Nano Banana Pro46.33 points

higher is betterAs of August 26, 2026Scale: 0 points - 100 points

Source: GEBench
gradually.ai
Methodology and context
Metric
points-100
Scale
0-100
Participants
5
Methodology and context
A bilingual graphical-user-interface benchmark. Chinese and English subsets and the single-step, multi-step, fictional-app, real-app, and grounding categories remain separate.
Source: GEBench

GEBench English, real app

GPT Image 1.558.93 points
Seedream 4.049.36 points
Nano Banana Pro47.2 points
FLUX.2 Pro47.16 points
Wan 2.6 Text to Image44.8 points

higher is betterAs of August 26, 2026Scale: 0 points - 100 points

Source: GEBench
gradually.ai
Methodology and context
Metric
points-100
Scale
0-100
Participants
5
Methodology and context
A bilingual graphical-user-interface benchmark. Chinese and English subsets and the single-step, multi-step, fictional-app, real-app, and grounding categories remain separate.
Source: GEBench

GEBench English, grounding

Nano Banana Pro58.64 points
Wan 2.6 Text to Image53.36 points
GPT Image 1.549.23 points
FLUX.2 Pro45.67 points
Seedream 4.044.17 points

higher is betterAs of August 26, 2026Scale: 0 points - 100 points

Source: GEBench
gradually.ai
Methodology and context
Metric
points-100
Scale
0-100
Participants
5
Methodology and context
A bilingual graphical-user-interface benchmark. Chinese and English subsets and the single-step, multi-step, fictional-app, real-app, and grounding categories remain separate.
Source: GEBench

Recorded measurement details

Text to Image Arena (Show measurement, test conditions, and source)
Source value
1017.69
Score
1017.69
Metric
elo-rating
Unit
Elo
Benchmark version
v2.1
Direction
Higher is better
Source rank
39
Confidence interval
12
Lower confidence bound
1005.69
Upper confidence bound
1029.69
Source type
independent-evaluator
Evaluator
Artificial Analysis
Retrieved at
2026-11-06
Methodology
AA appearances: 5817. This count does not establish an independent sample. Lower rank: 29. Upper rank: 44. Source model ID: caa670a4-e827-4a4b-84fb-2dd240205fe2. Evidence capture ID: aa-image-text-to-image-v2.1-2026-11-06-e430d57b5d0b. Source payload hash: e430d57b5d0bf260d6feb60bb7d8fa32da8d7961ec2bd9a9cae58fb015613cf0
USD price per 1,000 tokens
30
Source Artificial Analysis
GEBench Chinese, single-step (Show measurement, test conditions, and source)
Source value
64.2
Score
64.2
Metric
points-100
Unit
points
Direction
Higher is better
Source rank
4
Source type
research-benchmark
Evaluator
GEBench evaluation pipeline
Retrieved at
2026-08-26
Methodology
A bilingual graphical-user-interface benchmark. Chinese and English subsets and the single-step, multi-step, fictional-app, real-app, and grounding categories remain separate.
Source GEBench
GEBench Chinese, multi-step (Show measurement, test conditions, and source)
Source value
50.11
Score
50.11
Metric
points-100
Unit
points
Direction
Higher is better
Source rank
4
Source type
research-benchmark
Evaluator
GEBench evaluation pipeline
Retrieved at
2026-08-26
Methodology
A bilingual graphical-user-interface benchmark. Chinese and English subsets and the single-step, multi-step, fictional-app, real-app, and grounding categories remain separate.
Source GEBench
GEBench Chinese, fictional app (Show measurement, test conditions, and source)
Source value
52.72
Score
52.72
Metric
points-100
Unit
points
Direction
Higher is better
Source rank
4
Source type
research-benchmark
Evaluator
GEBench evaluation pipeline
Retrieved at
2026-08-26
Methodology
A bilingual graphical-user-interface benchmark. Chinese and English subsets and the single-step, multi-step, fictional-app, real-app, and grounding categories remain separate.
Source GEBench
GEBench Chinese, real app (Show measurement, test conditions, and source)
Source value
50.4
Score
50.4
Metric
points-100
Unit
points
Direction
Higher is better
Source rank
5
Source type
research-benchmark
Evaluator
GEBench evaluation pipeline
Retrieved at
2026-08-26
Methodology
A bilingual graphical-user-interface benchmark. Chinese and English subsets and the single-step, multi-step, fictional-app, real-app, and grounding categories remain separate.
Source GEBench
GEBench Chinese, grounding (Show measurement, test conditions, and source)
Source value
59.58
Score
59.58
Metric
points-100
Unit
points
Direction
Higher is better
Source rank
2
Source type
research-benchmark
Evaluator
GEBench evaluation pipeline
Retrieved at
2026-08-26
Methodology
A bilingual graphical-user-interface benchmark. Chinese and English subsets and the single-step, multi-step, fictional-app, real-app, and grounding categories remain separate.
Source GEBench
GEBench Chinese, overall (Show measurement, test conditions, and source)
Source value
55.4
Score
55.4
Metric
points-100
Unit
points
Direction
Higher is better
Source rank
4
Source type
research-benchmark
Evaluator
GEBench evaluation pipeline
Retrieved at
2026-08-26
Methodology
A bilingual graphical-user-interface benchmark. Chinese and English subsets and the single-step, multi-step, fictional-app, real-app, and grounding categories remain separate.
Source GEBench
GEBench English, single-step (Show measurement, test conditions, and source)
Source value
60.17
Score
60.17
Metric
points-100
Unit
points
Direction
Higher is better
Source rank
4
Source type
research-benchmark
Evaluator
GEBench evaluation pipeline
Retrieved at
2026-08-26
Methodology
A bilingual graphical-user-interface benchmark. Chinese and English subsets and the single-step, multi-step, fictional-app, real-app, and grounding categories remain separate.
Source GEBench
GEBench English, multi-step (Show measurement, test conditions, and source)
Source value
44.36
Score
44.36
Metric
points-100
Unit
points
Direction
Higher is better
Source rank
4
Source type
research-benchmark
Evaluator
GEBench evaluation pipeline
Retrieved at
2026-08-26
Methodology
A bilingual graphical-user-interface benchmark. Chinese and English subsets and the single-step, multi-step, fictional-app, real-app, and grounding categories remain separate.
Source GEBench
GEBench English, fictional app (Show measurement, test conditions, and source)
Source value
49.55
Score
49.55
Metric
points-100
Unit
points
Direction
Higher is better
Source rank
3
Source type
research-benchmark
Evaluator
GEBench evaluation pipeline
Retrieved at
2026-08-26
Methodology
A bilingual graphical-user-interface benchmark. Chinese and English subsets and the single-step, multi-step, fictional-app, real-app, and grounding categories remain separate.
Source GEBench
GEBench English, real app (Show measurement, test conditions, and source)
Source value
44.8
Score
44.8
Metric
points-100
Unit
points
Direction
Higher is better
Source rank
5
Source type
research-benchmark
Evaluator
GEBench evaluation pipeline
Retrieved at
2026-08-26
Methodology
A bilingual graphical-user-interface benchmark. Chinese and English subsets and the single-step, multi-step, fictional-app, real-app, and grounding categories remain separate.
Source GEBench
GEBench English, grounding (Show measurement, test conditions, and source)
Source value
53.36
Score
53.36
Metric
points-100
Unit
points
Direction
Higher is better
Source rank
2
Source type
research-benchmark
Evaluator
GEBench evaluation pipeline
Retrieved at
2026-08-26
Methodology
A bilingual graphical-user-interface benchmark. Chinese and English subsets and the single-step, multi-step, fictional-app, real-app, and grounding categories remain separate.
Source GEBench

Page 1 of 2

Popularity compared

How often the model is searched for, used and mentioned, compared with every model of its category.

Popularity index

The 100 most popular models of this category, 0 to 100, higher is more popular

20 of 100 models

As of November 2026 · Source: gradually.ai popularity index

Over time

Weekly values from October 18, 2026 to November 5, 2026

Wan 2.6 Text to ImageFirefly Image Model 5Nano Banana 2.1Grok Imagine Image 2.0Recraft V4.1 Utility

Wan 2.6 Text to Image compared

Compare with another model

The most popular comparisons

  1. 1GPT Image 2.5 Sunburst vs. Wan 2.6 Text to Image
  2. 2GPT Image 2 vs. Wan 2.6 Text to Image
  3. 3Reve 2.1 vs. Wan 2.6 Text to Image
  4. 4Nano Banana 2 vs. Wan 2.6 Text to Image
  5. 5Midjourney V8.2 vs. Wan 2.6 Text to Image
  6. 6GPT Image 1.5 vs. Wan 2.6 Text to Image
  7. 7MAI-Image-2.5 vs. Wan 2.6 Text to Image
  8. 8Nano Banana Pro vs. Wan 2.6 Text to Image
  9. 9Nano Banana 2 Lite vs. Wan 2.6 Text to Image
Show all 108 comparisons
  1. 10Seedream 5.0 Pro vs. Wan 2.6 Text to Image
  2. 11Grok Imagine Image Quality vs. Wan 2.6 Text to Image
  3. 12FLUX.2 Max vs. Wan 2.6 Text to Image
  4. 13Qwen Image 2.0 Pro vs. Wan 2.6 Text to Image
  5. 14MAI-Image-2.5 Flash vs. Wan 2.6 Text to Image
  6. 15HiDream-O1-Image-1.5 vs. Wan 2.6 Text to Image
  7. 16Krea 2 Medium Turbo vs. Wan 2.6 Text to Image
  8. 17Seedream 4.0 vs. Wan 2.6 Text to Image
  9. 18Krea 2 Large vs. Wan 2.6 Text to Image
  10. 19Luma Uni-1.1 Max vs. Wan 2.6 Text to Image
  11. 20FLUX.2 Flex vs. Wan 2.6 Text to Image
  12. 21Recraft V4.1 Utility vs. Wan 2.6 Text to Image
  13. 22Ideogram 4.0 vs. Wan 2.6 Text to Image
  14. 23Wan 2.6 Text to Image vs. FLUX.2 Pro
  15. 24Wan 2.6 Text to Image vs. HunyuanImage 3.0 Instruct
  16. 25Wan 2.6 Text to Image vs. FLUX.2 Klein 9B
  17. 26Wan 2.6 Text to Image vs. HiDream-O1-Image
  18. 27Wan 2.6 Text to Image vs. Firefly Image Model 5
  19. 28Wan 2.6 Text to Image vs. Midjourney V8.1
  20. 29Wan 2.6 Text to Image vs. Stable Diffusion 3.5 Large
  21. 30Wan 2.6 Text to Image vs. GPT Image 2.5 Flare
  22. 31Wan 2.6 Text to Image vs. Qwen-Image-2.1
  23. 32Wan 2.6 Text to Image vs. MAI-Image-2.6
  24. 33Wan 2.6 Text to Image vs. MAI-Image-2.6 Flash
  25. 34Wan 2.6 Text to Image vs. Muse Image
  26. 35Wan 2.6 Text to Image vs. Grok Imagine Image 2.0
  27. 36Wan 2.6 Text to Image vs. FLUX 3 Image
  28. 37Wan 2.6 Text to Image vs. FLUX 3 Image Klein
  29. 38Wan 2.6 Text to Image vs. Nano Banana 2.1
  30. 39Wan 2.6 Text to Image vs. Ideogram 4.5
  31. 40Wan 2.6 Text to Image vs. Hy Image 3.5 Preview
  32. 41Wan 2.6 Text to Image vs. Recraft V4.1
  33. 42Wan 2.6 Text to Image vs. Recraft V4.1 Flash
  34. 43Wan 2.6 Text to Image vs. Bria FIBO 2
  35. 44Wan 2.6 Text to Image vs. Krea 3
  36. 45Wan 2.6 Text to Image vs. Qwen Image 3.0 Pro
  37. 46Wan 2.6 Text to Image vs. Qwen Image 3.0
  38. 47Wan 2.6 Text to Image vs. Qwen Image 2.1 Pro
  39. 48Wan 2.6 Text to Image vs. Qwen Image 2.1 Turbo
  40. 49Wan 2.6 Text to Image vs. Wan 2.7 Image Pro
  41. 50Wan 2.6 Text to Image vs. Wan 2.7 Image
  42. 51Wan 2.6 Text to Image vs. Seedream 5.0 Flash
  43. 52Wan 2.6 Text to Image vs. SenseNova U1.5 Lite
  44. 53Wan 2.6 Text to Image vs. Kling Image 3.0
  45. 54Wan 2.6 Text to Image vs. Kling Image 3.0 Omni
  46. 55Wan 2.6 Text to Image vs. Vidu Q2 Image
  47. 56Wan 2.6 Text to Image vs. GLM-Image
  48. 57Wan 2.6 Text to Image vs. MiniMax Image-01
  49. 58Wan 2.6 Text to Image vs. Z-Image Turbo
  50. 59Wan 2.6 Text to Image vs. Luma Uni-1.1
  51. 60Wan 2.6 Text to Image vs. Runway Gen-4 Image
  52. 61Wan 2.6 Text to Image vs. Adobe Firefly Image 3
  53. 62Wan 2.6 Text to Image vs. Adobe Firefly Image 4
  54. 63Wan 2.6 Text to Image vs. Adobe Firefly Image 4 Ultra
  55. 64Wan 2.6 Text to Image vs. Stable Diffusion 3.5 Medium
  56. 65Wan 2.6 Text to Image vs. Stable Diffusion 3.5 Large Turbo
  57. 66Wan 2.6 Text to Image vs. Bria FIBO Lite
  58. 67Wan 2.6 Text to Image vs. Recraft V4.1 Utility Pro
  59. 68Wan 2.6 Text to Image vs. Seedream 4.5
  60. 69Wan 2.6 Text to Image vs. Seedream 5.0 Lite
  61. 70Wan 2.6 Text to Image vs. FLUX.2 Klein 9B Preview
  62. 71Wan 2.6 Text to Image vs. GPT Image 1 Mini
  63. 72Wan 2.6 Text to Image vs. ChatGPT Image Latest (API-Alias)
  64. 73Wan 2.6 Text to Image vs. Nano Banana (Gemini 2.5 Flash Image)
  65. 74Wan 2.6 Text to Image vs. FLUX.2 Klein 4B
  66. 75Wan 2.6 Text to Image vs. FLUX.2 Dev
  67. 76Wan 2.6 Text to Image vs. FLUX1.1 [pro]
  68. 77Wan 2.6 Text to Image vs. FLUX1.1 [pro] Ultra
  69. 78Wan 2.6 Text to Image vs. FLUX.1 [dev]
  70. 79Wan 2.6 Text to Image vs. FLUX.1 Kontext [pro]
  71. 80Wan 2.6 Text to Image vs. FLUX.1 Kontext [max]
  72. 81Wan 2.6 Text to Image vs. Stable Diffusion XL 1.0
  73. 82Wan 2.6 Text to Image vs. Stable Diffusion 3 Medium
  74. 83Wan 2.6 Text to Image vs. SDXL Turbo
  75. 84Wan 2.6 Text to Image vs. Stable Diffusion Turbo
  76. 85Wan 2.6 Text to Image vs. Grok Imagine Image 1.0
  77. 86Wan 2.6 Text to Image vs. MOSS-Image-Base
  78. 87Wan 2.6 Text to Image vs. MOSS-Image-SFT
  79. 88Wan 2.6 Text to Image vs. LLaDA-Image
  80. 89Wan 2.6 Text to Image vs. LLaDA-Image-Turbo
  81. 90Wan 2.6 Text to Image vs. Nucleus-Image
  82. 91Wan 2.6 Text to Image vs. LongCat-Image
  83. 92Wan 2.6 Text to Image vs. BAGEL-7B-MoT
  84. 93Wan 2.6 Text to Image vs. OmniGen2
  85. 94Wan 2.6 Text to Image vs. Kandinsky-5.0-T2I-Lite-SFT
  86. 95Wan 2.6 Text to Image vs. Kandinsky-5.0-T2I-Lite-Pretrain
  87. 96Wan 2.6 Text to Image vs. Boogu-Image-0.1-Base
  88. 97Wan 2.6 Text to Image vs. Boogu-Image-0.1-Turbo
  89. 98Wan 2.6 Text to Image vs. SANA-1.5 1.6B 1024px
  90. 99Wan 2.6 Text to Image vs. SANA-1.5 4.8B 1024px
  91. 100Wan 2.6 Text to Image vs. Sana-Sprint 0.6B 1024px
  92. 101Wan 2.6 Text to Image vs. Sana-Sprint 1.6B 1024px
  93. 102Wan 2.6 Text to Image vs. Chroma1-HD
  94. 103Wan 2.6 Text to Image vs. Chroma1-Flash
  95. 104Wan 2.6 Text to Image vs. AuraFlow v0.3
  96. 105Wan 2.6 Text to Image vs. PixArt-Sigma-XL-2-1024-MS
  97. 106Wan 2.6 Text to Image vs. Lumina-Image 2.0
  98. 107Wan 2.6 Text to Image vs. HunyuanImage 3.0
  99. 108Wan 2.6 Text to Image vs. Z-Image Base

All specifications

Input and output

Maximum output
2K
Source: Maximum output

Watermarking and provenance

AI watermarking refers to invisible signals embedded in the output. Visible marks and provenance metadata are listed separately. Unknown means there is insufficient evidence for that particular field.

AI watermarking
Unknown
no source
Watermarking technique
Not known
no source

Licence and access

Weights
Proprietary
Source: Weights

Prices

Representative price
$0.03 per imageSource
Together AI (Wan-AI/Wan2.6-image)
$0.03 per megapixelSource

Frequently asked questions about Wan 2.6 Text to Image

How good is Wan 2.6 Text to Image?

Rank 44 of 108 in our own test.

GraduallyBench from Nov 3, 2026

GraduallyBenchour own rating, 0 to 100 · higher is better
Recraft V4.1 Utility65
FLUX.2 Pro65
MOSS-Image-SFT64
Wan 2.6 Text to ImageRank 44 of 10863
Ideogram 4.563
FLUX.2 Dev62
Seedream 4.062

What is Wan 2.6 Text to Image good at?

Best at Character and detail (79 out of 100), weakest at Typography and layout (41).

GraduallyBench, one image per task

  1. Wan 2.6 Text to Image: Typography and layoutTypography and layoutLegible text, hierarchy, and composition41out of 100Rank 63 of 108 in this task
  2. Wan 2.6 Text to Image: Product photographyProduct photographyMaterials, reflections, and fine details54out of 100Rank 52 of 108 in this task
  3. Wan 2.6 Text to Image: Character and detailCharacter and detailAnatomy, clothing, and spatial consistency79out of 100Rank 9 of 108 in this task
  4. Wan 2.6 Text to Image: InfographicInfographicNumbers, labels, and visual organization77out of 100Rank 20 of 108 in this task

How much does an image with Wan 2.6 Text to Image cost?

About $0.03 per image. That is cheap: a typical image model costs $0.06.

Configuration: Text to Image

Price per imageDollars per image · lower is better
FLUX.2 Klein 9B$0.015
MAI-Image-2.6 Flash$0.019
MAI-Image-2.5 Flash$0.02
Wan 2.6 Text to ImageRank 6 of 28$0.03
FLUX.2 Pro$0.03
Nano Banana 2 Lite$0.034
Recraft V4.1 Utility$0.035

Sources and data date

Show all 13 sources

Benchmark sources at a glance

Which independent evaluators tested this model. This is coverage, not a quality ranking.

No active result from the reviewed external evaluators can currently be attributed to this model. Other source evidence remains available below.

Without vendor claims and historical or disputed results; those stay labelled in the single values.