xAIMoonshot AILLM matchup

Grok 4.6vs.Kimi K3

Which one is better?

Grok 4.6 and Kimi K3 perform about equally well, but Kimi K3 costs 1.5 times (input) and 2.5 times (output) as much.

level
IntelligenceOverall index, 100 points = average
102.1

Grok 4.6

Rank 25

101.5

Kimi K3

Rank 26

Kimi K3 faster
SpeedTokens per second
38

Grok 4.6

59

Kimi K3

Grok 4.6 cheaper
Price$ per 1M tokens
$3

Grok 4.6

$6

Kimi K3

Popularity0 to 100
n/a

Grok 4.6

85

Kimi K3

Rank 5 of 511

Above 200,000 tokens of context, Grok 4.6 costs more: $4 input and $12 output per 1M tokens.

Choose Grok 4.6 for

AgentsKnowledge (not certain)Coding (not certain)Reasoning (not certain)

Choose Kimi K3 for

HealthFinance (not certain)Legal (not certain)

Where is the difference?

Strengths at a glance

Grok 4.6Kimi K3Median of all ranked models

10011012090Codingslightly Grok4.6Reasoningslightly Grok4.6MathematicslevelKnowledgeslightly Grok4.6AgentsGrok 4.6GenerallevelFinanceslightly KimiK3Legalslightly KimiK3HealthKimi K3
CodingGrok 4.6 slightly ahead
Grok 4.6101.0Rank 28
Kimi K397.3Rank 43
Median of ranked models87.5

95 % range: Grok 4.6 96.9 to 105.0, Kimi K3 89.9 to 104.6.

AreaGrok 4.6Kimi K3

The same values and verdicts as the bars below. In the close-up the net starts at 90 points, just below the weaker model's lowest value; the reference group average is 100. Not in the net because a model has no own value there or the data are too thin: Multimodal.

Grok 4.6 is ahead in 1 of 10 areas, Kimi K3 in 1.

Grok 4.6 ahead: 1Grok 4.6 slightly ahead: 3level: 2too little data: 1Kimi K3 slightly ahead: 2Kimi K3 ahead: 1

Areas in the overall index
AgentsGrok 4.6 +7104.6 to 97.4
Knowledgeleaning Grok 4.6not certain · 3 tests each
Codingleaning Grok 4.6not certain · 13 and 16 tests
Reasoningleaning Grok 4.6not certain · 5 tests each
Mathematicslevel101.2 to 101.5
Generallevel106.1 to 106.0
Multimodaltoo little data99.3 to 101.6
Specialist fields
HealthKimi K3 +699.3 to 105.0
Financeleaning Kimi K3not certain · 6 and 8 tests
Legalleaning Kimi K3not certain · 3 and 4 tests

Bar length shows the gap in index points (full width 15 points, one standard deviation of the reference group). Solid means clearly ahead, hatched not certain yet, a thin grey bar level.

Show 3 more areas that do not count toward the overall index
Cybersecuritytoo little data103.1 to 109.3
Productivitytoo little data105.4 to 107.2
Educationonly Kimi K3 has a score

Bar length shows the gap in index points (full width 15 points, one standard deviation of the reference group). Solid means clearly ahead, hatched not certain yet, a thin grey bar level.

Which model for which task?

Everyday tasks, translated from the area values above. Each row names the values it rests on.

Writing and debugging codeleaning Grok 4.6Coding 101.0 to 97.3
Maths and data analysisleaning Grok 4.6Mathematics 101.2 to 101.5, Reasoning 100.3 to 97.0
Facts and researchleaning Grok 4.6Knowledge 100.1 to 95.3
Agents and workflowsGrok 4.6Agents 104.6 to 97.4
Fast chat repliesKimi K338 to 59 tokens per second
Security analysisopenCybersecurity 103.1 to 109.3 (too little data)
Many requests on a small budgetGrok 4.6$3 to $6 per 1M tokens
Finance, legal and medical textsKimi K3Finance 100.9 to 105.3, Legal 105.7 to 109.8, Health 99.3 to 105.0
Images, screenshots and PDFsopenMultimodal 99.3 to 101.6 (too little data)

Grok 4.6 vs. Kimi K3 in our own test

The same prompt for both models. We show the latest attempt without fixes; it does not count toward the overall index.

Pelican on a bicycle

Prompt

Generate an SVG of a pelican riding a bicycle

Task origin: Simon Willison

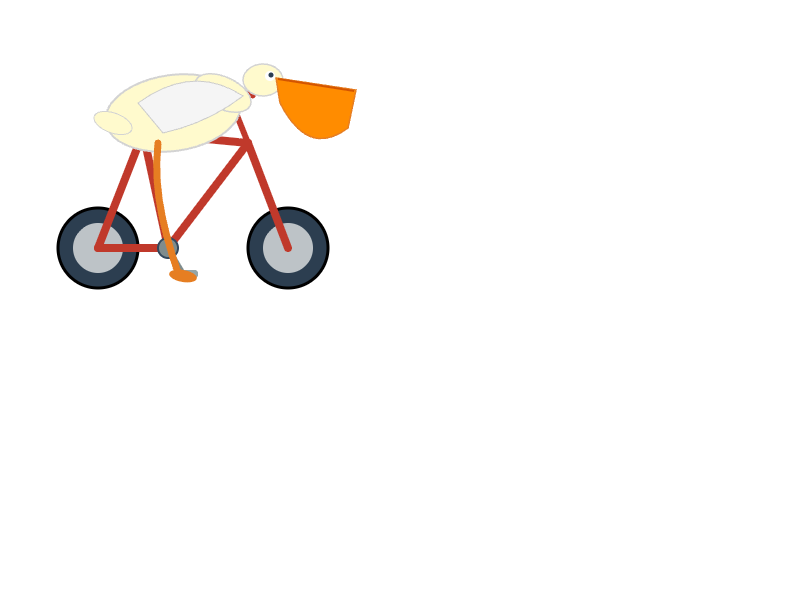
Grok 4.6

Grok 4.6: Pelican on a bicycle
A community classic for free-form SVG drawing.

Oct 1, 2026 · 114 s · $0.05

Test details
Run date
Oct 1, 2026
API provider
openrouter
Requested API model
x-ai/grok-4.6
Reasoning setting
high
Token limit including reasoning
8,192 tokens
Output tokens
7,660 tokens
Cost of the attempt
$0.0462
Response time
113.6 s
API model reported in response
x-ai/grok-4.6
Pinned endpoint
xAI | x-ai/grok-4.6-20260810
Temperature
Provider default
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating

Visually reviewed. This individual test does not establish overall model quality.

Earlier attempts (1)

  • Sep 7, 2026API request failedReasoning setting: high

Kimi K3
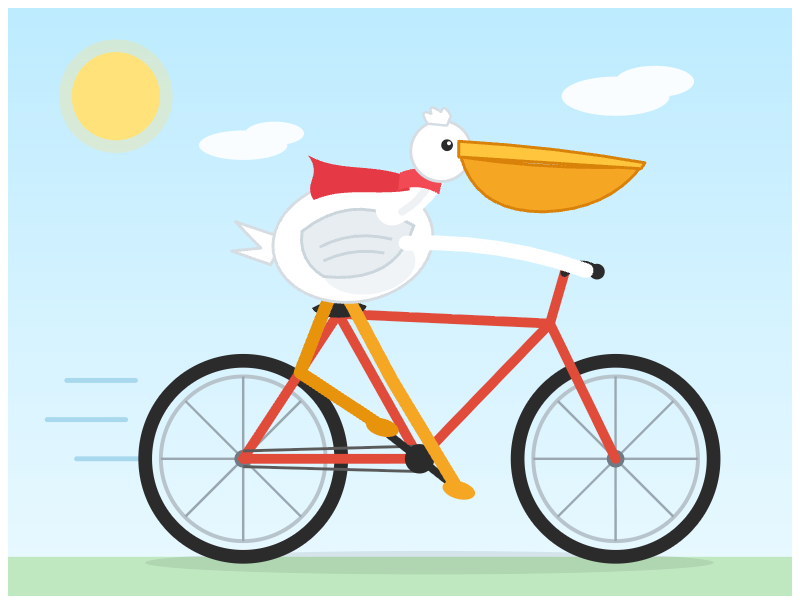
Kimi K3: Pelican on a bicycle
A community classic for free-form SVG drawing.

Oct 1, 2026 · 173 s · $0.08

Test details
Run date
Oct 1, 2026
API provider
openrouter
Requested API model
moonshotai/kimi-k3
Reasoning setting
high
Token limit including reasoning
8,192 tokens
Output tokens
5,145 tokens
Cost of the attempt
$0.0775
Response time
173.4 s
API model reported in response
moonshotai/kimi-k3
Pinned endpoint
Moonshot AI | moonshotai/kimi-k3-20260715
Temperature
Provider default
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating

Visually reviewed. This individual test does not establish overall model quality.

Earlier attempts (1)

  • Sep 7, 2026API request failedReasoning setting: high
SVG short test

SVG short test

One SVG task with the same fixed settings for every model, without hidden thinking.

Prompt

Return only one standalone SVG of a pelican riding a bicycle. Use viewBox="0 0 800 600", simple shapes, two clearly visible wheels and a recognizable pelican with a long beak. At most 30 SVG elements and 1800 characters. No Markdown, explanations, comments, scripts, animation, CSS or external resources.

Grok 4.6

Unavailable in this round

Kimi K3
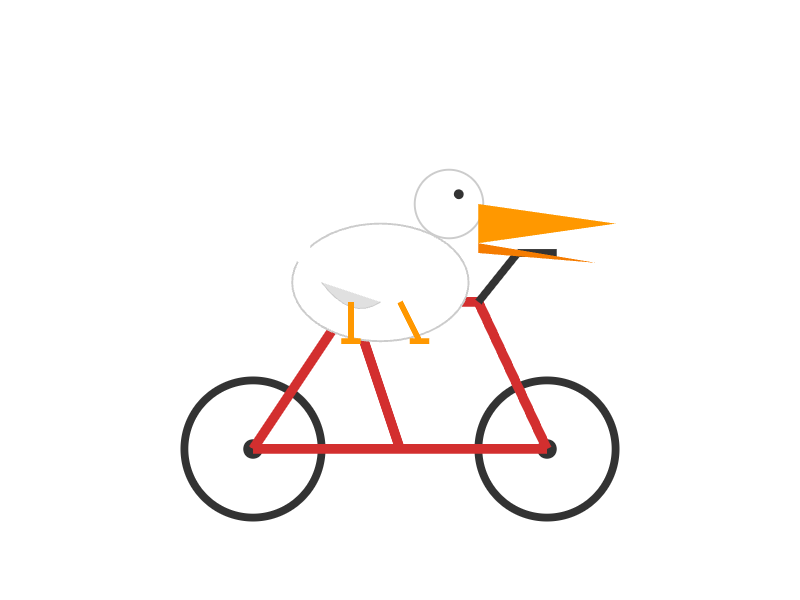
Kimi K3: SVG short test

Oct 14, 2026 · $0.0049

Test details
Test run
Oct 14, 2026
Provider
chutes/mxfp4
API model
moonshotai/kimi-k3
Output
495 tokens
Reasoning
API reports 0 reasoning tokens
Cost of the attempt
$0.0049
Test round
43b8c5c46830

Grok 4.6 and Kimi K3 in the overall index

Every model with a place in the overall index, both models of this matchup highlighted. You can add or hide other models.

Overall index (Gradually Meta-Score v6)

20 of 95 models

Claude Fable 5.2max130.9
Gemini 4 Carbonhigh127.0
Claude Opus 5.5max125.7
Claude Fable 5.1max124.1
Claude Sonnet 5.5max121.9
Gemini 4 Argonhigh121.2
GPT-6 Astramax119.6
Muse Wonder Fullmax118.4
GPT-6.1 Solmax117.5
Claude Opus 5max117.3
Muse Wondermax113.7
Claude Fable 5max112.8
Kimi K3.1 Promax112.6
Muse Ember 1.0max110.5
GPT-5.6 Solmax109.3
GPT-6 Solmax108.4
Gemini 3.7 Flashhigh107.7
DeepSeek V4.1 Flash 1017max107.1
Grok 4.6high102.1
Kimi K3max101.5

Popularity compared

How often the models are searched for, used and mentioned, on a scale from 0 to 100.

Grok 4.6 has no popularity score yet.

Over time

Weekly values from October 18, 2026 to November 17, 2026

Grok 4.6Kimi K3

All data side by side

The better value is bold. For the overall index only when the gap is clear.

MetricGrok 4.6Kimi K3
Intelligence
Overall indexpoints, 100 = reference group average, higher is better102.1101.5
RankRank 25 of 95Rank 26 of 95
Price per 1M tokens
Inputwhat you send$2above 200,000 tokens: $4$3
Outputwhat the model writes$6above 200,000 tokens: $12$15
Cost per task (own tests)average of 3 original-protocol tasks both models passed (SVG short test not included)$0.058$0.055
Speed
Tokens per second3859
Popularity
Popularitysearch, usage and mentions, 0 to 100n/a85Rank 5 of 511
Technical
Context windowhow much text the model reads at once500,000 tokens≈ 750 A4 pages1.05 M tokens≈ 1,570 A4 pages
Knowledge cutoffFeb 1, 2026n/a
ReleasedAug 12, 2026Jul 16, 2026
AvailabilityActiveActive
Open weightsnoyes

Prices without caching or batch discounts · Page count as a rule of thumb from Artificial Analysis

Is there a better choice?

Successor of Grok 4.6Grok 4.7

Overall index 103.6, rank 23$2 input and $6 output per 1M tokens

Kimi K3 vs. Grok 4.7
Successor of Kimi K3Kimi K3.1 Pro

Overall index 112.6, rank 13$2 input and $10 output per 1M tokens

Grok 4.6 vs. Kimi K3.1 Pro
Cheaper than Grok 4.6Muse Ember 1.0

Overall index 110.5, rank 14$0.10 input and $0.50 output per 1M tokens

View profile

Shared benchmarks

Single results from the same benchmark version, task and metric. A value is bold only with the same test setup and a clear gap.

A: Grok 4.6B: Kimi K3

Access to Justice BenchmarkOverall · higher is betterTest setup not documented as identicalGrok 4.6: 71.3%Kimi K3: 68.2%Vals AIAs of 11/10/2026
BioMysteryBenchOverall · higher is betterTest setup not documented as identicalGrok 4.6: 72.2%Kimi K3: 72.6%Vals AIAs of 11/05/2026
Code MigrationOverall · higher is betterTest setup not documented as identicalGrok 4.6: 44.6%Kimi K3: 16.1%Vals AIAs of 10/29/2026
CorpFin v2Overall · higher is betterTest setup not documented as identicalGrok 4.6: 66.2%Kimi K3: 71.6%Vals AIAs of 08/12/2026
CyberBench v1.1Overall · higher is betterTest setup not documented as identicalGrok 4.6: 67.7%Kimi K3: 75.2%Vals AIAs of 11/05/2026
EMBOverall · higher is betterTest setup not documented as identicalGrok 4.6: 62.7%Kimi K3: 66.7%Vals AIAs of 10/20/2026
Finance Agent (v2)Overall · higher is betterTest setup not documented as identicalGrok 4.6: 53.7%Kimi K3: 53.1%Vals AIAs of 10/29/2026
GDPval-AAOverall · higher is betterGrok 4.6: 1,417.9 eloKimi K3: 1,135.8 eloArtificial AnalysisAs of 11/07/2026
GPQA DiamondOverall · higher is betterTest setup not documented as identicalGrok 4.6: 94.7%Kimi K3: 92.9%Vals AIAs of 09/01/2026
ImmigrationOverall · higher is betterTest setup not documented as identicalGrok 4.6: 66.0%Kimi K3: 68.3%Vals AIAs of 10/28/2026
Show 54 more benchmarks
IOIOverall · higher is betterTest setup not documented as identicalGrok 4.6: 47.6%Kimi K3: 48.9%Vals AIAs of 10/29/2026
Legal Research BenchOverall · All-pass · higher is betterTest setup not documented as identicalGrok 4.6: 48.1%Kimi K3: 46.2%Vals AIAs of 11/05/2026
LegalBenchOverall · higher is betterTest setup not documented as identicalGrok 4.6: 86.3%Kimi K3: 86.2%Vals AIAs of 10/13/2026
LiveCodeBenchOverall · higher is betterTest setup not documented as identicalGrok 4.6: 88.2%Kimi K3: 87.2%Vals AIAs of 09/01/2026
LMArena Code Arena WebDevOverall · higher is betterTest setup not documented as identicalGrok 4.6: 1,618Kimi K3: 1,658LMArenaAs of 11/15/2026
LMArena Text, Style ControlOverall · higher is betterTest setup not documented as identicalGrok 4.6: 1,457Kimi K3: 1,487LMArenaAs of 11/11/2026
MedCodeOverall · higher is betterTest setup not documented as identicalGrok 4.6: 44.7%Kimi K3: 49.4%Vals AIAs of 10/29/2026
MedScribeOverall · higher is betterTest setup not documented as identicalGrok 4.6: 86.5%Kimi K3: 88.0%Vals AIAs of 10/29/2026
MMLU ProOverall · higher is betterTest setup not documented as identicalGrok 4.6: 89.4%Kimi K3: 88.0%Vals AIAs of 09/01/2026
MortgageTaxOverall · higher is betterTest setup not documented as identicalGrok 4.6: 64.2%Kimi K3: 66.3%Vals AIAs of 09/01/2026
ProgramBenchOverall · higher is betterTest setup not documented as identicalGrok 4.6: 1%Kimi K3: 2%Vals AIAs of 11/05/2026
ProofBench v1.1Overall · higher is betterTest setup not documented as identicalGrok 4.6: 51%Kimi K3: 87%Vals AIAs of 10/29/2026
Public Benefits Bench v1.1Overall · higher is betterTest setup not documented as identicalGrok 4.6: 66.8%Kimi K3: 68.2%Vals AIAs of 10/12/2026
SWE-bench VerifiedOverall · higher is betterTest setup not documented as identicalGrok 4.6: 95.6%Kimi K3: 93.4%Vals AIAs of 09/01/2026
Tax Agent BenchControversy & Precedence Analysis (weighted pass) · higher is betterTest setup not documented as identicalGrok 4.6: 71.7%Kimi K3: 71.7%Vals AIAs of 11/09/2026
TaxEval v2Overall · higher is betterTest setup not documented as identicalGrok 4.6: 71.1%Kimi K3: 75.7%Vals AIAs of 09/01/2026
Terminal-Bench 4.0Overall · higher is betterTest setup not documented as identicalGrok 4.6: 17.2%Kimi K3: 17.2%Vals AIAs of 11/05/2026
Terminal-Bench-ScienceOverall · higher is betterTest setup not documented as identicalGrok 4.6: 11.4%Kimi K3: 1.4%Vals AIAs of 11/05/2026
Time Horizon Index: KSPOverall · higher is betterTest setup not documented as identicalGrok 4.6: 5.8%Kimi K3: 10.5%Vals AIAs of 10/07/2026
Vibe Code Bench 1-100Overall · higher is betterTest setup not documented as identicalGrok 4.6: 14.8%Kimi K3: 18.2%Vals AIAs of 10/29/2026
Vibe Code Bench v1.1Overall · higher is betterTest setup not documented as identicalGrok 4.6: 76.2%Kimi K3: 85.0%Vals AIAs of 11/05/2026
BioMysteryBenchHard · higher is betterTest setup not documented as identicalGrok 4.6: 29.4%Kimi K3: 41.2%Vals AIAs of 11/05/2026
Code MigrationCLI · higher is betterTest setup not documented as identicalGrok 4.6: 39.4%Kimi K3: 1.5%Vals AIAs of 10/29/2026
CorpFin v2Exact Pages · higher is betterTest setup not documented as identicalGrok 4.6: 64.5%Kimi K3: 69.3%Vals AIAs of 08/12/2026
CyberBench v1.1Patch · higher is betterTest setup not documented as identicalGrok 4.6: 80.4%Kimi K3: 82.1%Vals AIAs of 11/05/2026
EMBComps · higher is betterTest setup not documented as identicalGrok 4.6: 59.9%Kimi K3: 70.8%Vals AIAs of 10/20/2026
Finance Agent (v2)Adjustments · higher is betterTest setup not documented as identicalGrok 4.6: 49.6%Kimi K3: 45.3%Vals AIAs of 10/29/2026
GPQA DiamondFew-Shot CoT · higher is betterTest setup not documented as identicalGrok 4.6: 93.9%Kimi K3: 93.4%Vals AIAs of 09/01/2026
ImmigrationAll-Pass · higher is betterTest setup not documented as identicalGrok 4.6: 17.6%Kimi K3: 21.4%Vals AIAs of 10/28/2026
IOIIOI 2024 · higher is betterTest setup not documented as identicalGrok 4.6: 50.3%Kimi K3: 59.7%Vals AIAs of 10/29/2026
Legal Research BenchAdministrative / Regulatory · All-pass · higher is betterTest setup not documented as identicalGrok 4.6: 62.1%Kimi K3: 63.6%Vals AIAs of 11/05/2026
LegalBenchConclusion Tasks · higher is betterTest setup not documented as identicalGrok 4.6: 90.4%Kimi K3: 90.1%Vals AIAs of 10/13/2026
LiveCodeBenchEasy · higher is betterTest setup not documented as identicalGrok 4.6: 99.1%Kimi K3: 98.8%Vals AIAs of 09/01/2026
LMArena Code Arena WebDevHTML development · higher is betterTest setup not documented as identicalGrok 4.6: 1,600Kimi K3: 1,640LMArenaAs of 11/15/2026
LMArena Text, Style ControlBusiness, management and finance · higher is betterTest setup not documented as identicalGrok 4.6: 1,446Kimi K3: 1,488LMArenaAs of 11/11/2026
MMLU ProBiology · higher is betterTest setup not documented as identicalGrok 4.6: 95.0%Kimi K3: 93.9%Vals AIAs of 09/01/2026
MortgageTaxNumerical Extraction · higher is betterTest setup not documented as identicalGrok 4.6: 68.3%Kimi K3: 78.9%Vals AIAs of 09/01/2026
ProgramBenchAlmost Resolved · higher is betterTest setup not documented as identicalGrok 4.6: 19.0%Kimi K3: 17.5%Vals AIAs of 11/05/2026
SWE-bench Verified<15 min fix · higher is betterTest setup not documented as identicalGrok 4.6: 95.9%Kimi K3: 92.3%Vals AIAs of 09/01/2026
Tax Agent BenchCurrent & Temporal Analysis · higher is betterTest setup not documented as identicalGrok 4.6: 46.7%Kimi K3: 42.3%Vals AIAs of 11/09/2026
TaxEval v2Correctness · higher is betterTest setup not documented as identicalGrok 4.6: 62.1%Kimi K3: 65.3%Vals AIAs of 09/01/2026
Terminal-Bench 4.0Hardware · higher is betterTest setup not documented as identicalGrok 4.6: 6.7%Kimi K3: 13.3%Vals AIAs of 11/05/2026
Terminal-Bench-ScienceEarth Sciences · higher is betterTest setup not documented as identicalGrok 4.6: 12.5%Kimi K3: 12.5%Vals AIAs of 11/05/2026
Time Horizon Index: KSPProgress efficiency · higher is betterTest setup not documented as identicalGrok 4.6: 4.9%Kimi K3: 9.3%Vals AIAs of 10/07/2026
BioMysteryBenchHuman-solvable · higher is betterTest setup not documented as identicalGrok 4.6: 82.2%Kimi K3: 79.9%Vals AIAs of 11/05/2026
Code MigrationCOBOL · higher is betterTest setup not documented as identicalGrok 4.6: 60%Kimi K3: 60%Vals AIAs of 10/29/2026
CorpFin v2Max Fitting Context · higher is betterTest setup not documented as identicalGrok 4.6: 66.2%Kimi K3: 72.7%Vals AIAs of 08/12/2026
CyberBench v1.1PoC · higher is betterTest setup not documented as identicalGrok 4.6: 55.0%Kimi K3: 68.3%Vals AIAs of 11/05/2026
EMBDataroom · higher is betterTest setup not documented as identicalGrok 4.6: 78.2%Kimi K3: 82.7%Vals AIAs of 10/20/2026
Finance Agent (v2)All-Pass · higher is betterTest setup not documented as identicalGrok 4.6: 42.9%Kimi K3: 41.8%Vals AIAs of 10/29/2026
GPQA DiamondZero-Shot CoT · higher is betterTest setup not documented as identicalGrok 4.6: 95.5%Kimi K3: 92.4%Vals AIAs of 09/01/2026
ImmigrationContent Checks · higher is betterTest setup not documented as identicalGrok 4.6: 63.3%Kimi K3: 65.6%Vals AIAs of 10/28/2026
IOIIOI 2025 · higher is betterTest setup not documented as identicalGrok 4.6: 49.0%Kimi K3: 29.3%Vals AIAs of 10/29/2026
Legal Research BenchAdministrative / Regulatory · Weighted partial credit (weighted pass) · higher is betterTest setup not documented as identicalGrok 4.6: 91.4%Kimi K3: 89.3%Vals AIAs of 11/05/2026

More comparisons

Compare Grok 4.6 and Kimi K3 with the models people compare them with most often.

Compare another matchup

The most popular comparisons

  1. 1Claude Fable 5.2 vs. Kimi K3
  2. 2Claude Opus 5.5 vs. Kimi K3
  3. 3Claude Opus 5.5 vs. Grok 4.6
  4. 4Claude Sonnet 5.5 vs. Kimi K3
  5. 5Claude Opus 5 vs. Kimi K3
  6. 6GPT-6 Astra vs. Kimi K3
  7. 7Grok 4.7 vs. Kimi K3
  8. 8DeepSeek V4.1 Flash 1017 vs. Kimi K3
  9. 9DeepSeek-V4-Pro vs. Kimi K3
Show all 35 comparisons
  1. 10Gemini 3.8 Flash vs. Grok 4.6
  2. 11DeepSeek-V4.1-Flash vs. Kimi K3
  3. 12DeepSeek-V4-Flash vs. Kimi K3
  4. 13Kimi K3 vs. GLM-5.3-Flash
  5. 14Kimi K3 vs. GLM-5.3
  6. 15Claude Opus 5 vs. Grok 4.6
  7. 16GPT-5.6 Luna vs. Kimi K3
  8. 17Claude Sonnet 5 vs. Kimi K3
  9. 18Kimi K3 vs. Qwen 3.8 27B
  10. 19GPT-6 Sol vs. Kimi K3
  11. 20Gemini 4 Carbon vs. Grok 4.6
  12. 21Claude Sonnet 5.5 vs. Grok 4.6
  13. 22Gemini 3.1 Pro Preview vs. Kimi K3
  14. 23Grok 4.6 vs. DeepSeek V4.1 Flash 1017
  15. 24Grok 4.6 vs. DeepSeek-V4-Flash
  16. 25GPT-6 Luna vs. Grok 4.6
  17. 26Grok 4.6 vs. DeepSeek-V4.1-Flash
  18. 27GPT-5.6 Sol vs. Grok 4.6
  19. 28Claude Haiku 5.5 vs. Grok 4.6
  20. 29Claude Fable 5.2 vs. Grok 4.6
  21. 30Kimi K3 vs. Mistral Large 4
  22. 31Muse Spark 1.3 vs. Kimi K3
  23. 32Claude Opus 4.8 vs. Kimi K3
  24. 33Grok 4.5 vs. Kimi K3
  25. 34Gemini 4 Argon vs. Kimi K3
  26. 35Muse Wonder vs. Kimi K3