Compare published benchmark results from matching versions and cohorts, API pricing, and technical specifications. Any documented test setup differences remain visible.
shared result series
194
distinct benchmarks
25
latest retrieval
2026-09-04
Change model selection
Specifications
General specifications
Release date, availability, context window, architecture, and published parameter counts at a glance. Undisclosed details remain marked as unavailable.
The table compares official standard API rates per 1M tokens, including published cache pricing. Batch, fast, priority, regional surcharges, tool calls, and cloud platform pricing are excluded.
Key to the marks:better valuebetter, but not conclusivetie
Pricing by provider
Direct developer pricing and provider endpoint tariffs routed through OpenRouter are listed separately. Prices are in USD per 1M tokens. Context-dependent direct tiers plus regional, Flex, Priority, and other OpenRouter tariffs remain individually identifiable.
Only published results with the same benchmark version, task, metric, and comparison cohort are paired. Different reasoning levels, agents, harnesses, or output limits appear directly in the table.
Capability profile from matched benchmarks
Each axis averages directly matched benchmark families. A value of 100 means the stronger value within this pair, not a universal quality score.
Claude Sonnet 5
Kimi K3
Coding: 75.1 / 87.3 (5 benchmark families)
Reasoning: 95.7 / 100 (1 benchmark family)
Mathematics: 88.5 / 100 (1 benchmark family)
Knowledge: 99.5 / 100 (1 benchmark family)
Finance: 98.5 / 98.9 (5 benchmark families)
Legal: 79.4 / 100 (3 benchmark families)
Agentic tasks: 92.1 / 100 (1 benchmark family)
Multimodal: 94.2 / 100 (1 benchmark family)
26 matched rows from 24 benchmark families were considered. The radar shows 8 of 12 comparable categories.
Claude Sonnet 5Kimi K3
Code MigrationOverall. Higher is better. No documented setup difference
Claude Sonnet 5Winner44.392 %
Kimi K316.099 %
CorpFin v2Overall. Higher is better. No documented setup difference
Claude Sonnet 566.977 %
Kimi K3Winner71.562 %
EMBOverall. Higher is better. No documented setup difference
Claude Sonnet 566.316 %
Kimi K3Winner66.399 %
Finance Agent (v2)Overall. Higher is better. No documented setup difference
Claude Sonnet 553.909 %
Kimi K3Winner54.36 %
GPQA DiamondOverall. Higher is better. No documented setup difference
Claude Sonnet 588.889 %
Kimi K3Winner92.929 %
Harvey's Legal Agent BenchmarkOverall · Task fully resolved. Higher is better. No documented setup difference
Claude Sonnet 55 %
Kimi K3Winner10.833 %
Legal Research BenchOverall · All-pass. Higher is better. No documented setup difference
Claude Sonnet 541.827 %
Kimi K3Winner44.231 %
LegalBenchOverall. Higher is better. No documented setup difference
Claude Sonnet 583.922 %
Kimi K3Winner86.016 %
LiveCodeBench v6Overall. Higher is better. No documented setup difference
Claude Sonnet 582.429 %
Kimi K3Winner87.185 %
LMArena Text, Style ControlOverall. Higher is better. Test setup not documented as identical
Claude Sonnet 51,462.16
Kimi K3Higher measured value1,489.017
MedCodeOverall. Higher is better. No documented setup difference
Claude Sonnet 547.54 %
Kimi K3Winner48.884 %
MedScribeOverall. Higher is better. No documented setup difference
Claude Sonnet 576.054 %
Kimi K3Winner87.958 %
Key to the marks:better valuebetter, but not conclusivetie
Benchmark scores for Claude Sonnet 5 and Kimi K3
Benchmark and task
Claude Sonnet 5
Kimi K3
Source
Code MigrationOverallTest details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is better
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Sonnet 5: Snapshot: claude-sonnet-5-high, Reasoning: high, Harness: Arena text, style control Kimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style controlClaude Sonnet 5: Style-controlled Arena rating from 31,096 anonymous pairwise votes.Kimi K3: Style-controlled Arena rating from 17,895 anonymous pairwise votes.
1,462.16
95% confidence interval: ±4.745The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Higher measured value1,489.017
95% confidence interval: ±5.47The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlBusiness, management and financeTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Sonnet 5: Snapshot: claude-sonnet-5-high, Reasoning: high, Harness: Arena text, style control Kimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style controlClaude Sonnet 5: Style-controlled Arena rating from 6,214 anonymous pairwise votes.Kimi K3: Style-controlled Arena rating from 3,520 anonymous pairwise votes.
1,462.981
95% confidence interval: ±8.229The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Higher measured value1,489.216
95% confidence interval: ±10.41The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Sonnet 5: Snapshot: claude-sonnet-5-high, Reasoning: high, Harness: Arena text, style control Kimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style controlClaude Sonnet 5: Style-controlled Arena rating from 2,074 anonymous pairwise votes.Kimi K3: Style-controlled Arena rating from 1,168 anonymous pairwise votes.
1,499.492
95% confidence interval: ±13.64The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Higher measured value1,528.536
95% confidence interval: ±17.657The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Key to the marks:better valuebetter, but not conclusivetie
Our model tests
Community tests you can inspect
Compare how the models respond to the same prompt. Each test shows the first attempt, with no subsequent fixes to the generated code. These results do not contribute to an overall score.
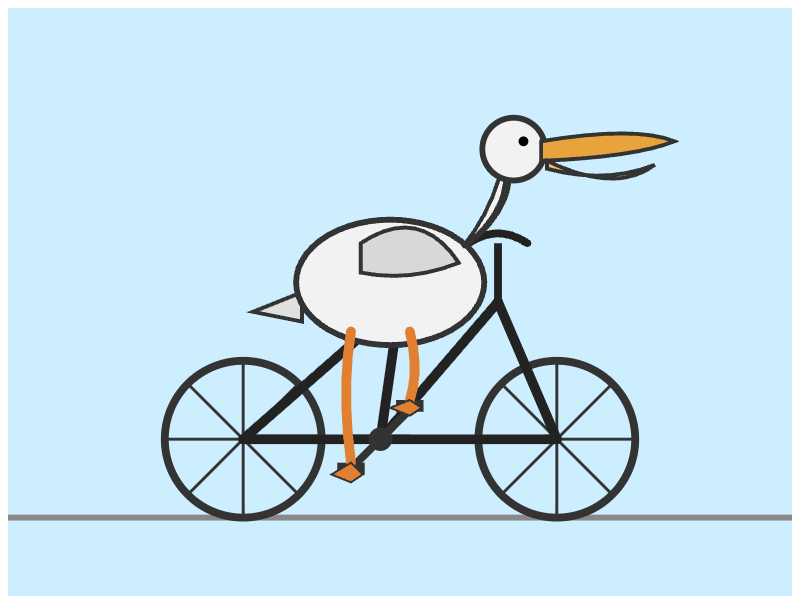
Pelican on a bicycle
A community classic for free-form SVG drawing.
Claude Sonnet 5
A community classic for free-form SVG drawing.First attempt
Run date
7 Sept 2026
API provider
openrouter
Requested API model
anthropic/claude-sonnet-5
API model reported in response
anthropic/claude-sonnet-5
Pinned endpoint
Anthropic | anthropic/claude-sonnet-5-20260630
Reasoning setting
high
Temperature
Provider default
Token limit including reasoning
8,192 tokens
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating
Response time
47.9 s
Visually reviewed. This individual test does not establish overall model quality.
Kimi K3
API access was unavailable for this run. The model was not evaluated.
First attempt
Run date
7 Sept 2026
API provider
openrouter
Requested API model
moonshotai/kimi-k3
Pinned endpoint
Moonshot AI | moonshotai/kimi-k3-20260715
Reasoning setting
high
Temperature
Provider default
Token limit including reasoning
8,192 tokens
Test protocol
community-visual-tests-v1
Technical checks
Not run
Not yet visually reviewed. A successful recording does not confirm correct physics or full compliance with the prompt.
Your workload, budget, and required context length matter most. A coding benchmark says little about visual understanding or agent performance.
The standard price table uses direct developer rates. The provider comparison labels OpenRouter endpoints, regions, and special tariffs separately.
Every result links to its measurement source and retrieval date. Labels distinguish vendor reports, official benchmark leaderboards, and independent evaluations. Disputed or archived results are excluded.
More matchups
Related LLM comparisons
Compare Claude Sonnet 5 and Kimi K3 with other leading models using the same data and benchmark logic.