Qwen 3 32B
Reasoning tokens were reported. The output is not shown as a comparable short-test result.
Alibaba
Qwen 3 32B brings the Qwen3 family into a dense 32.8-billion-parameter model with switchable Thinking. It can produce additional reasoning steps or answer directly without that visible trace.
The model has 64 layers with grouped-query attention, 64 Q heads, and 8 KV heads. Qwen lists 32,768 native context tokens and up to 131,072 tokens with YaRN.
| Specification | Value and source |
|---|---|
| Weights | Open weightsSource |
| Access | API, LocalSource |
| Parameters | 32.8BSource |
| Context window | 32,768 tokensSource |
| Weights repository | Qwen/Qwen3-32BSource |
| License | Apache-2.0Source |
| Architecture | Qwen3 causal language model; dense or sparse MoESource |
| Input | TextSource |
| Output | TextSource |
| Reasoning mode | base checkpoint; report evaluates pre-training onlySource |
| Tool calling | NoSource |
| Structured output | NoSource |
| Native context window | 32,768 tokensSource |
| Maximum context window | 131,072 tokensSource |
| Parameters | 32.8 BSource |
| Languages | 119 languages and dialectsSource |
| Repository created | 2025-04-27 (Repository creation date is a precise publication proxy, but may differ from the public announcement date or an individual checkpoint's first availability.)Source |
| Training tokens | 36 trillionSource |
Page 1 of 2
These measurements have no matching peer values under the same test conditions. Their original values and sources remain available here.
Page 1 of 2
One SVG prompt and fixed output settings. Captures are shown only with 0 reported reasoning tokens or documented lack of reasoning controls. Identical test conditions do not make the models' internal compute identical.
Reasoning tokens were reported. The output is not shown as a comparable short-test result.
A community classic for free-form SVG drawing.
Qwen 3 32B
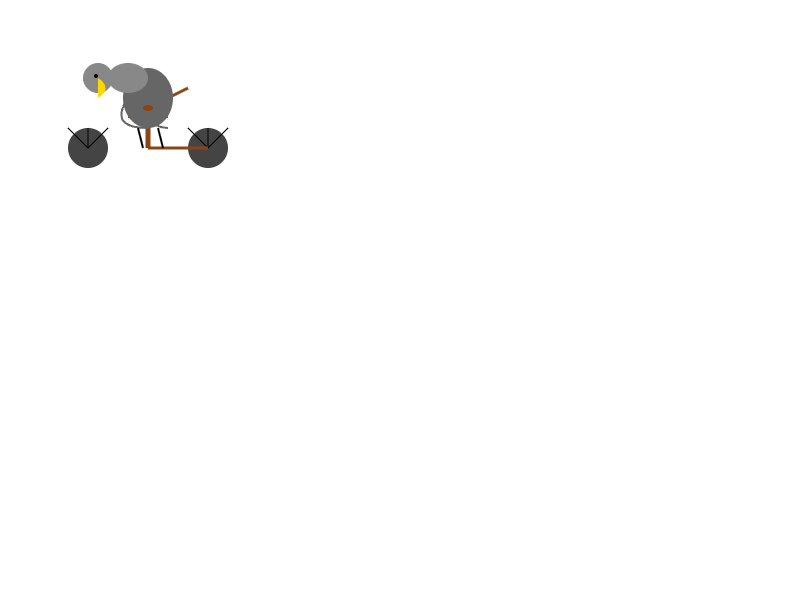
Reasoning (requested): high
Visually reviewed. This individual test does not establish overall model quality.
Generate an SVG of a pelican riding a bicycle
Token limit including reasoning: 8,192 tokens
Task origin (Simon Willison)44.3 / 100
| Type | Evidence and data date |
|---|---|
| Speed | Alibaba, Non-reasoning. Output speed after the first streaming chunk, not total response time. Classified as deprecated by Artificial Analysis. Artificial Analysis maintains only the default 10K-input workload there. Retrieved September 8, 2026. |
| Price | Base API prices without caching or batch discounts. Higher context tiers and other rates are listed under Costs. |
| Input | Documented modalities. Retrieved September 8, 2026. |
| Output | Documented modalities. Retrieved September 8, 2026. |
| Research status | Research date September 8, 2026. 4 source URLs checked. This documents the inspected sources, not an exhaustive inventory of every publication. |
| Not found in the inspected sources | active-parameters-billions Original wording Dense checkpoint; no separate activated-parameter count is applicable/published. |
| Additional source | Qwen3 Technical Report (retrieved September 8, 2026) · Qwen3 Technical Report · Editorial description reviewed October 2, 2026 |
| Additional source | Model metadata (retrieved September 8, 2026) |
| Additional source | OpenRouter: Popularity index (derived), CC BY 4.0 |
| Additional source | Vercel AI Gateway: Popularity index (derived), CC BY 4.0 |
| Additional source | Creative Commons Attribution 4.0 |
| Additional source | Qwen: "Qwen3: Think Deeper, Act Faster" (2026-09-19) |