Compare published benchmark results from matching versions and cohorts, API pricing, and technical specifications. Any documented test setup differences remain visible.
shared result series
39
distinct benchmarks
11
latest retrieval
2026-09-29
Change model selection
Specifications
General specifications
Release date, availability, context window, architecture, and published parameter counts at a glance. Undisclosed details remain marked as unavailable.
The table compares official standard API rates per 1M tokens, including published cache pricing. Batch, fast, priority, regional surcharges, tool calls, and cloud platform pricing are excluded.
Key to the marks:better valuebetter, but not conclusivetie
Pricing by provider
Direct developer pricing and provider endpoint tariffs routed through OpenRouter are listed separately. Prices are in USD per 1M tokens. Context-dependent direct tiers plus regional, Flex, Priority, and other OpenRouter tariffs remain individually identifiable.
Only published results with the same benchmark version, task, metric, and comparison cohort are paired. Different reasoning levels, agents, harnesses, or output limits appear directly in the table.
Capability profile from matched benchmarks
Each axis averages directly matched benchmark families. A value of 100 means the stronger value within this pair, not a universal quality score.
Kimi K3
Mistral Large 3
Coding: 100 / 53.9 (2 benchmark families)
Reasoning: 100 / 73.6 (1 benchmark family)
Knowledge: 100 / 90.7 (1 benchmark family)
Finance: 100 / 86.8 (3 benchmark families)
Legal: 100 / 92 (1 benchmark family)
Multimodal: 100 / 75.1 (1 benchmark family)
Education: 100 / 45.3 (1 benchmark family)
10 matched rows from 10 benchmark families were considered. The radar shows 7 of 7 comparable categories.
Kimi K3Mistral Large 3
CorpFin v2Overall. Higher is better. No documented setup difference
Kimi K3Winner71.562 %
Mistral Large 361.033 %
GPQA DiamondOverall. Higher is better. No documented setup difference
Kimi K3Winner92.929 %
Mistral Large 368.434 %
LegalBenchOverall. Higher is better. No documented setup difference
Kimi K3Winner86.016 %
Mistral Large 379.138 %
LiveCodeBench v6Overall. Higher is better. No documented setup difference
Kimi K3Winner87.185 %
Mistral Large 355.337 %
LMArena Text, Style ControlOverall. Higher is better. Test setup not documented as identical
Kimi K3Higher measured value1,487.964
Mistral Large 31,413.254
MMLU-ProOverall. Higher is better. No documented setup difference
Kimi K3Winner87.973 %
Mistral Large 379.823 %
MMMU-ProOverall. Higher is better. No documented setup difference
Kimi K3Winner88.15 %
Mistral Large 366.185 %
MortgageTaxOverall. Higher is better. No documented setup difference
Kimi K3Winner66.336 %
Mistral Large 352.106 %
SAGEOverall. Higher is better. No documented setup difference
Kimi K3Winner54.26 %
Mistral Large 324.595 %
SWE-bench VerifiedOverall. Higher is better. No documented setup difference
Kimi K3Winner93.4 %
Mistral Large 341.4 %
TaxEval v2Overall. Higher is better. No documented setup difference
Kimi K3Winner75.716 %
Mistral Large 373.058 %
LMArena Text, Style ControlBusiness, management and finance. Higher is better. Test setup not documented as identical
Kimi K3Higher measured value1,489.173
Mistral Large 31,409.446
Key to the marks:better valuebetter, but not conclusivetie
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 26,400 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 77,456 anonymous pairwise votes.
Higher measured value1,487.964
95% confidence interval: ±4.866The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,413.254
95% confidence interval: ±2.912The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlBusiness, management and financeTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 5,149 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 14,597 anonymous pairwise votes.
Higher measured value1,489.173
95% confidence interval: ±8.766The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,409.446
95% confidence interval: ±5.509The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 1,940 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 5,845 anonymous pairwise votes.
Higher measured value1,539.78
95% confidence interval: ±13.819The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,434.058
95% confidence interval: ±8.22The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 6,878 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 19,574 anonymous pairwise votes.
Higher measured value1,540.544
95% confidence interval: ±7.811The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,469.182
95% confidence interval: ±4.902The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 5,249 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 13,448 anonymous pairwise votes.
Higher measured value1,458.257
95% confidence interval: ±9.02The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,372.648
95% confidence interval: ±5.824The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 10,028 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 32,060 anonymous pairwise votes.
Higher measured value1,493.173
95% confidence interval: ±6.62The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,426.615
95% confidence interval: ±4.05The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlEntertainment, sports and mediaTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 6,417 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 16,716 anonymous pairwise votes.
Higher measured value1,459.187
95% confidence interval: ±8.256The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,371.316
95% confidence interval: ±5.299The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 19,504 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 56,501 anonymous pairwise votes.
Higher measured value1,501.41
95% confidence interval: ±6.35The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,400.18
95% confidence interval: ±4.058The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 2,457 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 7,295 anonymous pairwise votes.
Higher measured value1,532.809
95% confidence interval: ±12.276The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,427.543
95% confidence interval: ±7.482The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 944 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 2,181 anonymous pairwise votes.
Higher measured value1,506.507
95% confidence interval: ±20.255The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,432.389
95% confidence interval: ±14.389The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 508 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 1,257 anonymous pairwise votes.
Higher measured value1,487.756
95% confidence interval: ±26.837The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,409.467
95% confidence interval: ±17.833The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 17,130 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 47,316 anonymous pairwise votes.
Higher measured value1,516.598
95% confidence interval: ±5.615The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,431.274
95% confidence interval: ±3.63The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 6,516 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 19,638 anonymous pairwise votes.
Higher measured value1,514.741
95% confidence interval: ±7.894The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,439.274
95% confidence interval: ±4.91The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 8,851 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 24,861 anonymous pairwise votes.
Higher measured value1,486.2
95% confidence interval: ±7.06The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,400.115
95% confidence interval: ±4.491The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 465 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 830 anonymous pairwise votes.
Higher measured value1,505.193
95% confidence interval: ±29.212The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,382.659
95% confidence interval: ±22.106The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 567 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 1,318 anonymous pairwise votes.
Higher measured value1,476.936
95% confidence interval: ±24.854The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,356.821
95% confidence interval: ±17.794The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlLegal and governmentTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 2,120 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 5,879 anonymous pairwise votes.
Higher measured value1,513.54
95% confidence interval: ±13.409The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,421.357
95% confidence interval: ±8.211The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlLife, physical and social scienceTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 4,134 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 12,690 anonymous pairwise votes.
Higher measured value1,521.44
95% confidence interval: ±9.547The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,428.685
95% confidence interval: ±5.734The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 11,778 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 29,146 anonymous pairwise votes.
Higher measured value1,503.731
95% confidence interval: ±6.651The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,417.29
95% confidence interval: ±4.417The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 1,131 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 4,411 anonymous pairwise votes.
Higher measured value1,499.153
95% confidence interval: ±17.579The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,401.493
95% confidence interval: ±9.177The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 1,381 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 4,047 anonymous pairwise votes.
Higher measured value1,512.282
95% confidence interval: ±16.286The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,413.935
95% confidence interval: ±9.781The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlMedicine and healthcareTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 1,822 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 5,443 anonymous pairwise votes.
Higher measured value1,510.85
95% confidence interval: ±14.327The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,430.076
95% confidence interval: ±8.59The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 4,075 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 13,164 anonymous pairwise votes.
Higher measured value1,500.724
95% confidence interval: ±9.804The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,419.382
95% confidence interval: ±5.74The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 16,361 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 45,384 anonymous pairwise votes.
Higher measured value1,477.001
95% confidence interval: ±5.678The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,397.089
95% confidence interval: ±3.587The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 428 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 1,754 anonymous pairwise votes.
Higher measured value1,489.166
95% confidence interval: ±27.535The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,414.116
95% confidence interval: ±14.298The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 3,175 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 9,292 anonymous pairwise votes.
Higher measured value1,493.777
95% confidence interval: ±10.901The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,408.043
95% confidence interval: ±6.505The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlSoftware and IT servicesTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 10,253 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 29,068 anonymous pairwise votes.
Higher measured value1,526.074
95% confidence interval: ±6.653The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,455.584
95% confidence interval: ±4.237The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 810 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 2,328 anonymous pairwise votes.
Higher measured value1,484.797
95% confidence interval: ±20.864The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,405.285
95% confidence interval: ±13.338The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlWriting, literature and languageTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterKimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlKimi K3: Style-controlled Arena rating from 6,938 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 19,002 anonymous pairwise votes.
Higher measured value1,474.679
95% confidence interval: ±7.931The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,388.294
95% confidence interval: ±4.988The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Key to the marks:better valuebetter, but not conclusivetie
Our model tests
Our tests
Compare how the models respond to the same prompt. Each test shows the latest attempt, with no subsequent fixes to the generated code. Earlier runs remain available in the test details. These results do not contribute to an overall score.
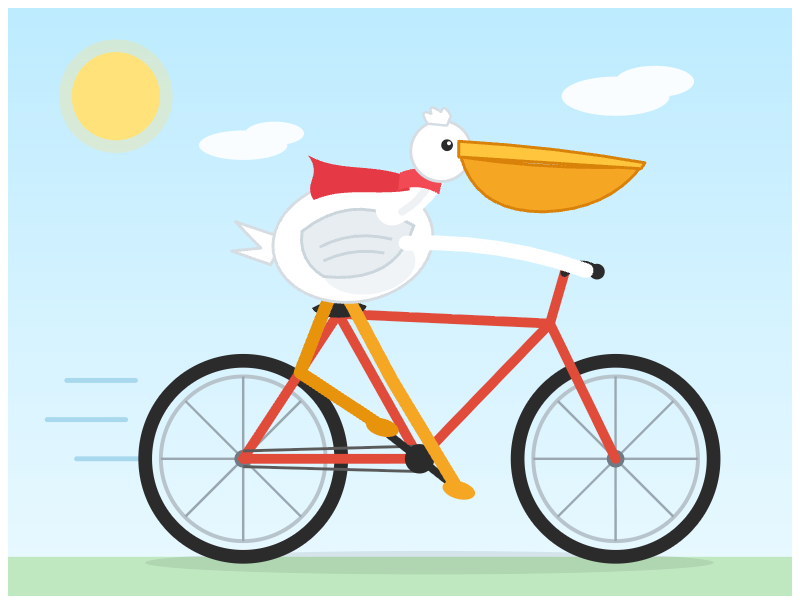
Pelican on a bicycle
A community classic for free-form SVG drawing.
Kimi K3
A community classic for free-form SVG drawing.
Reasoning (requested): high
Current attempt
Run date
1 Oct 2026
API provider
openrouter
Requested API model
moonshotai/kimi-k3
API model reported in response
moonshotai/kimi-k3
Reasoning setting
high
Pinned endpoint
Moonshot AI | moonshotai/kimi-k3-20260715
Temperature
Provider default
Token limit including reasoning
8,192 tokens
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating
Response time
173.4 s
Visually reviewed. This individual test does not establish overall model quality.
Earlier attempts (1)
7 Sept 2026API request failedReasoning setting: high
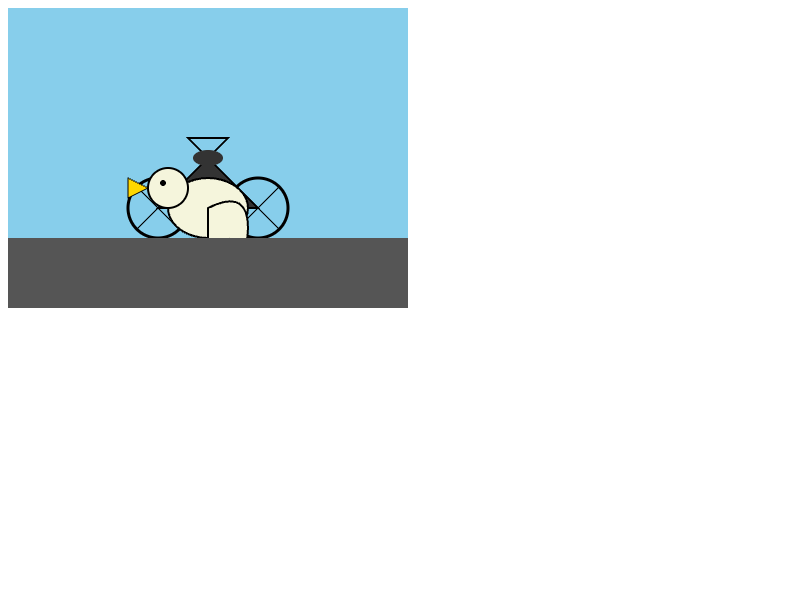
Mistral Large 3
A community classic for free-form SVG drawing.
Reasoning (model default): no reasoning mode Source
Current attempt
Run date
1 Oct 2026
API provider
openrouter
Requested API model
mistralai/mistral-large-2512
API model reported in response
mistralai/mistral-large-2512
Reasoning setting
not specified
Pinned endpoint
Mistral | mistralai/mistral-large-2512
Temperature
Provider default
Token limit including reasoning
8,192 tokens
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating
Response time
14.2 s
Visually reviewed. This individual test does not establish overall model quality.
Earlier attempts (1)
7 Sept 2026API request failedReasoning setting: not specified
Your workload, budget, and required context length matter most. A coding benchmark says little about visual understanding or agent performance.
The standard price table uses direct developer rates. The provider comparison labels OpenRouter endpoints, regions, and special tariffs separately.
Every result links to its measurement source and retrieval date. Labels distinguish vendor reports, official benchmark leaderboards, and independent evaluations. Disputed or archived results are excluded.
More matchups
Related LLM comparisons
Compare Kimi K3 and Mistral Large 3 with other leading models using the same data and benchmark logic.