Stability AIImage model

Stable Diffusion 3.5 Large

Stable Diffusion 3.5 Large is rank 21 of 21 in the arena rating and rank 87 of 108 in our GraduallyBench test.

Arena ratingRank 21 of 21

938User voteshigher is better

GraduallyBenchRank 87 of 108

27our own rating0 to 100

Priceno price

n/aper imagelower is better

PopularityRank 259 of 875

40out of 100same as last month

Summary

Stable Diffusion 3.5 Large uses 8.1B open-weight parameters and 1-megapixel output as a customizable foundation for professional images. Stability AI documents local use, APIs, and fine-tuning or LoRA workflows around the checkpoint.

Stability AI warns that different seeds can vary more and that vague prompts may produce less certain results and uneven aesthetics. The launch announcement also describes free commercial use up to $1 million in annual revenue and directs larger organizations to an enterprise license.

Image samples from our tests

These images come from documented single requests with an archived prompt. They complement measurements but do not replace a controlled laboratory test.

Character and detailOpen Character and detail at original size

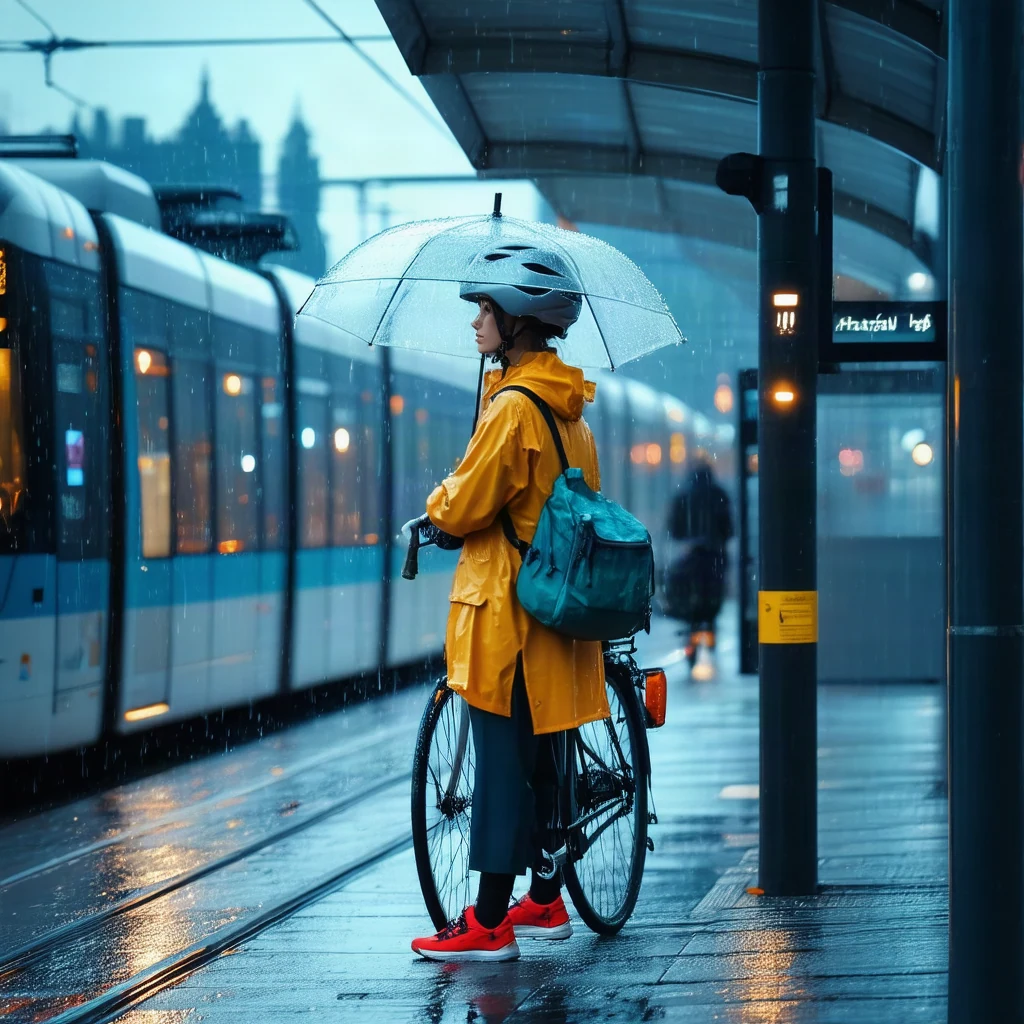
Character and detail

This sample tests Anatomy, clothing, and spatial consistency.

Prompt and settings

Create a square cinematic full-body portrait of a fictional bicycle courier waiting under a transparent umbrella at a rainy tram stop in Hamburg at blue hour. She wears a mustard raincoat, navy trousers, red sneakers, a silver helmet, and carries a teal messenger bag. Keep both hands visible, render the bicycle correctly, use realistic wet-street reflections, and include no readable brand names.

Generated through fal with model ID fal-ai/stable-diffusion-v35-large. Archived settings were requested 1024x1024, n=1, seed=7087247023770270000, estimated cost $0.068157.

Open source
InfographicOpen Infographic at original size

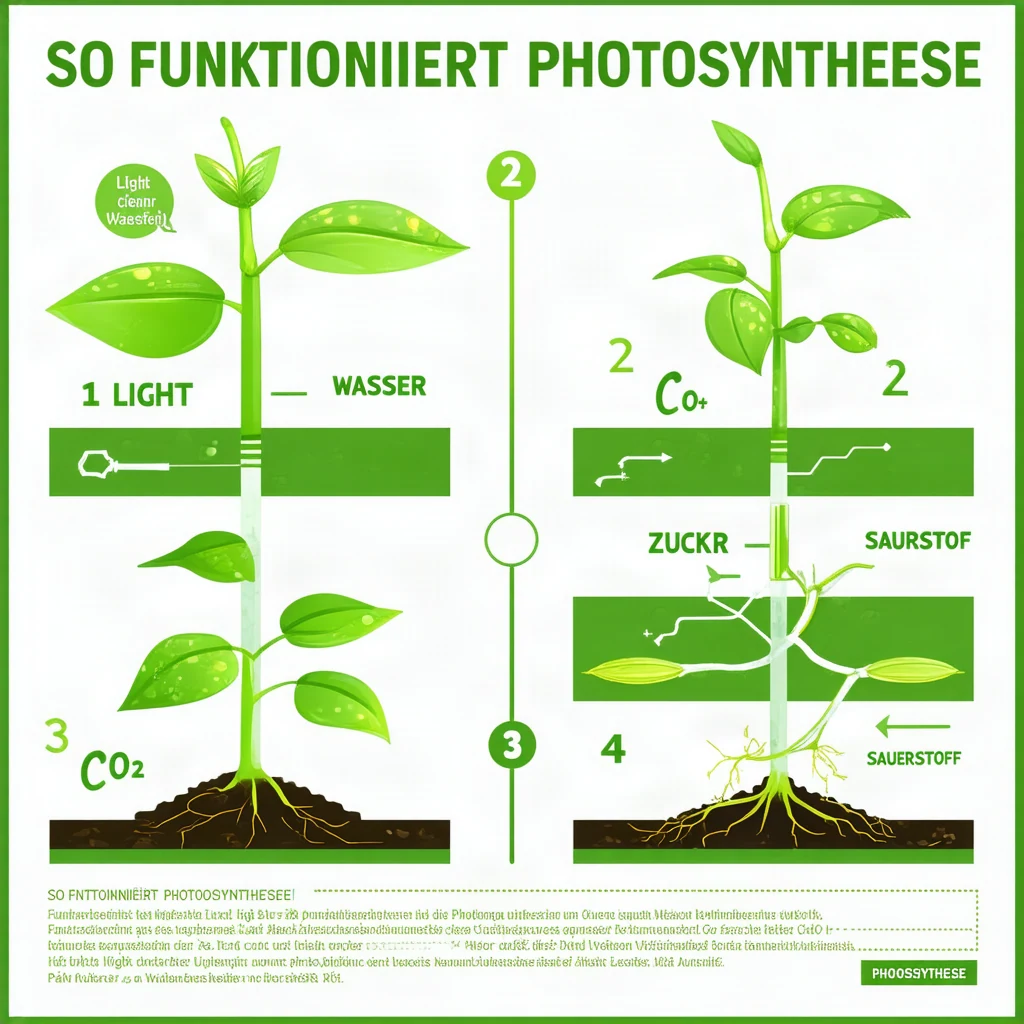
Infographic

This sample tests Numbers, labels, and visual organization.

Prompt and settings

Create a square German infographic titled SO FUNKTIONIERT PHOTOSYNTHESE. Show exactly four numbered steps in this order: 1 LICHT, 2 WASSER, 3 CO₂, 4 ZUCKER + SAUERSTOFF. Use a clean editorial science style with one plant cross-section, simple arrows, high contrast, legible labels, and no other text.

Generated through fal with model ID fal-ai/stable-diffusion-v35-large. Archived settings were requested 1024x1024, n=1, seed=12166653711354006000, estimated cost $0.068157.

Open source
Product photographyOpen Product photography at original size

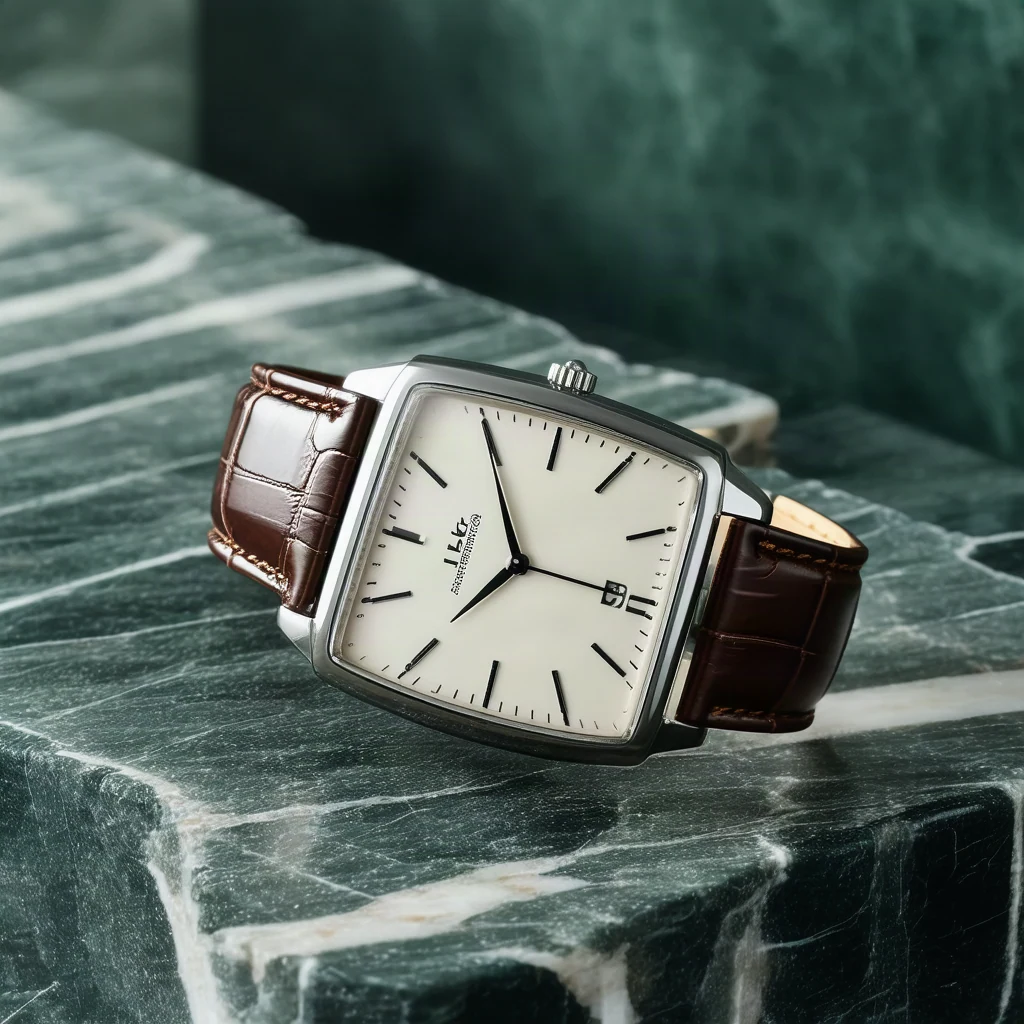
Product photography

This sample tests Materials, reflections, and fine details.

Prompt and settings

Create a square premium product photograph of a brushed titanium wristwatch standing upright on dark green marble. The watch has a cream dial, thin black hands set to 10:10, twelve distinct hour markers, a realistic crown, and a dark brown leather strap. Soft window light from the left, controlled reflections, shallow depth of field, no text, no logo, no extra objects.

Generated through fal with model ID fal-ai/stable-diffusion-v35-large. Archived settings were requested 1024x1024, n=1, seed=13346308312015933000, estimated cost $0.068157.

Open source
Typography and layoutOpen Typography and layout at original size

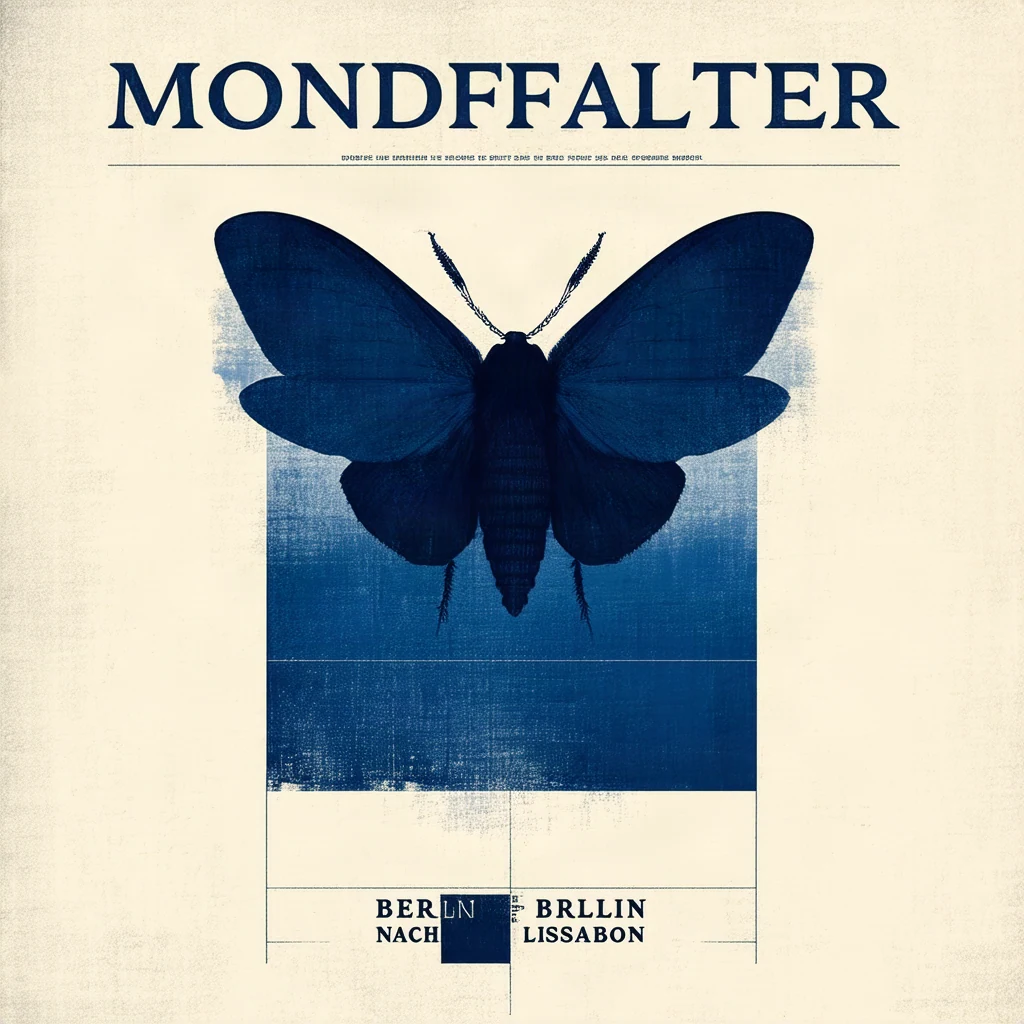
Typography and layout

This sample tests Legible text, hierarchy, and composition.

Prompt and settings

Create a square editorial poster for an imaginary night train called MONDFALTER. Show the exact German headline MONDFALTER and the exact subline BERLIN NACH LISSABON. Use a restrained midnight-blue and warm-cream palette, one stylized moth, strong Swiss-grid typography, generous negative space, and no additional words or logos.

Generated through fal with model ID fal-ai/stable-diffusion-v35-large. Archived settings were requested 1024x1024, n=1, seed=16632333557910893000, estimated cost $0.068157.

Open source

All benchmark results

Every published result with its source, test setup and comparison models.

Show all 74 published benchmark results

Page 1 of 7

Published benchmarks

Text to image

LMArena Text to Image: 3D modeling

GPT Image 2.5 Sunburst1,412.39 points
GPT Image 2.5 Flare1,381.8 points
GPT Image 21,365.33 points
MAI-Image-2.61,323.82 points
Grok Imagine Image 2.01,291.41 points
Reve 2.11,281.14 points
Nano Banana 21,255.68 points
MAI-Image-2.51,251.47 points
Seedream 5.0 Pro1,246.55 points
Muse Image1,238.45 points
Nano Banana Pro1,232.1 points
Nano Banana 2 Lite1,225.65 points
GPT Image 1.51,217.68 points
Qwen-Image-2.11,213.88 points
FLUX.2 Flex1,173.15 points
FLUX.2 Max1,160.58 points
FLUX.2 Pro1,145.47 points
HiDream-O1-Image1,120.68 points
Krea 2 Large1,115.65 points
FLUX.2 Klein 9B1,078.61 points
Stable Diffusion 3.5 Large963.03 points

higher is betterAs of November 6, 2026Scale: 0 points - 1,412.39 points

Source: LMArena
gradually.ai
Methodology and context
Metric
arena-score
Scale
No upper bound is documented. The chart spans the recorded values and zero.
Participants
21
Sample
1,629
Methodology and context
Evidence capture ID: lmarena-text_to_image-5a7e6bb84a93f55df56b198be8e56e53755a216a-43df833a690f. Source payload hash: 43df833a690f9454a344fb4d803c0c2ec845d592681e7f95e9ac50f1c0b25d4a
Source: LMArena

LMArena Text to Image: Art

GPT Image 2.5 Sunburst1,410.08 points
GPT Image 2.5 Flare1,387.35 points
GPT Image 21,370.68 points
MAI-Image-2.61,337.7 points
Grok Imagine Image 2.01,328.25 points
Reve 2.11,290.77 points
MAI-Image-2.51,276.76 points
Seedream 5.0 Pro1,258.85 points
Muse Image1,258.79 points
Nano Banana 2 Lite1,255.8 points
Nano Banana 21,239.62 points
Qwen-Image-2.11,234.74 points
GPT Image 1.51,224.81 points
Nano Banana Pro1,224.23 points
FLUX.2 Max1,168.74 points
FLUX.2 Pro1,159.34 points
FLUX.2 Flex1,155.3 points
Krea 2 Large1,122.19 points
HiDream-O1-Image1,116.78 points
FLUX.2 Klein 9B1,078.63 points
Stable Diffusion 3.5 Large997.29 points

higher is betterAs of November 6, 2026Scale: 0 points - 1,410.08 points

Source: LMArena
gradually.ai
Methodology and context
Metric
arena-score
Scale
No upper bound is documented. The chart spans the recorded values and zero.
Participants
21
Sample
5,340
Methodology and context
Evidence capture ID: lmarena-text_to_image-5a7e6bb84a93f55df56b198be8e56e53755a216a-43df833a690f. Source payload hash: 43df833a690f9454a344fb4d803c0c2ec845d592681e7f95e9ac50f1c0b25d4a
Source: LMArena

LMArena Text to Image: Cartoon

GPT Image 2.5 Sunburst1,456.88 points
GPT Image 2.5 Flare1,427.12 points
GPT Image 21,402.93 points
Grok Imagine Image 2.01,352.36 points
MAI-Image-2.61,348.71 points
Reve 2.11,309.78 points
Muse Image1,274.79 points
MAI-Image-2.51,268.65 points
Seedream 5.0 Pro1,263.52 points
Nano Banana 21,260.23 points
Nano Banana 2 Lite1,256.09 points
GPT Image 1.51,243.95 points
Nano Banana Pro1,243.91 points
Qwen-Image-2.11,234.48 points
FLUX.2 Max1,167.57 points
FLUX.2 Flex1,163.29 points
FLUX.2 Pro1,158.62 points
Krea 2 Large1,118.81 points
HiDream-O1-Image1,118.12 points
FLUX.2 Klein 9B1,063.58 points
Stable Diffusion 3.5 Large945.23 points

higher is betterAs of November 6, 2026Scale: 0 points - 1,456.88 points

Source: LMArena
gradually.ai
Methodology and context
Metric
arena-score
Scale
No upper bound is documented. The chart spans the recorded values and zero.
Participants
21
Sample
12,274
Methodology and context
Evidence capture ID: lmarena-text_to_image-5a7e6bb84a93f55df56b198be8e56e53755a216a-43df833a690f. Source payload hash: 43df833a690f9454a344fb4d803c0c2ec845d592681e7f95e9ac50f1c0b25d4a
Source: LMArena

LMArena Text to Image: Commercial design

GPT Image 2.5 Sunburst1,415.51 points
GPT Image 21,385.8 points
GPT Image 2.5 Flare1,384.8 points
MAI-Image-2.61,332.9 points
Grok Imagine Image 2.01,324.96 points
Reve 2.11,315.65 points
Nano Banana 21,267.93 points
MAI-Image-2.51,259.36 points
Muse Image1,258.15 points
Nano Banana 2 Lite1,248.4 points
Nano Banana Pro1,245.44 points
GPT Image 1.51,237.88 points
Qwen-Image-2.11,237.36 points
Seedream 5.0 Pro1,236.31 points
FLUX.2 Flex1,172.44 points
FLUX.2 Max1,163.75 points
FLUX.2 Pro1,154.5 points
HiDream-O1-Image1,129.54 points
Krea 2 Large1,110.71 points
FLUX.2 Klein 9B1,070.2 points
Stable Diffusion 3.5 Large936.77 points

higher is betterAs of November 6, 2026Scale: 0 points - 1,415.51 points

Source: LMArena
gradually.ai
Methodology and context
Metric
arena-score
Scale
No upper bound is documented. The chart spans the recorded values and zero.
Participants
21
Sample
3,051
Methodology and context
Evidence capture ID: lmarena-text_to_image-5a7e6bb84a93f55df56b198be8e56e53755a216a-43df833a690f. Source payload hash: 43df833a690f9454a344fb4d803c0c2ec845d592681e7f95e9ac50f1c0b25d4a
Source: LMArena

LMArena Text to Image: Overall

GPT Image 2.5 Sunburst1,427.13 points
GPT Image 2.5 Flare1,399.44 points
GPT Image 21,382.1 points
MAI-Image-2.61,330.58 points
Grok Imagine Image 2.01,317.31 points
Reve 2.11,300.4 points
Muse Image1,268.12 points
Nano Banana 21,257.49 points
MAI-Image-2.51,253 points
Seedream 5.0 Pro1,250.8 points
Nano Banana 2 Lite1,249.44 points
Nano Banana Pro1,246.31 points
GPT Image 1.51,236.39 points
Qwen-Image-2.11,226.55 points
FLUX.2 Max1,161.46 points
FLUX.2 Flex1,156.26 points
FLUX.2 Pro1,152.68 points
Krea 2 Large1,115.37 points
HiDream-O1-Image1,114.71 points
FLUX.2 Klein 9B1,069.84 points
Stable Diffusion 3.5 Large938.35 points

higher is betterAs of November 6, 2026Scale: 0 points - 1,427.13 points

Source: LMArena
gradually.ai
Methodology and context
Metric
arena-score
Scale
No upper bound is documented. The chart spans the recorded values and zero.
Participants
21
Sample
23,396
Methodology and context
Evidence capture ID: lmarena-text_to_image-5a7e6bb84a93f55df56b198be8e56e53755a216a-43df833a690f. Source payload hash: 43df833a690f9454a344fb4d803c0c2ec845d592681e7f95e9ac50f1c0b25d4a
Source: LMArena

LMArena Text to Image: Photorealism

GPT Image 2.5 Flare1,415.95 points
GPT Image 21,379.13 points
MAI-Image-2.61,330.88 points
Grok Imagine Image 2.01,312.19 points
Reve 2.11,302.1 points
Muse Image1,278.09 points
Seedream 5.0 Pro1,274.42 points
Nano Banana 21,261.31 points
Nano Banana Pro1,260.39 points
Nano Banana 2 Lite1,258.64 points
MAI-Image-2.51,250.67 points
GPT Image 1.51,246.79 points
Qwen-Image-2.11,229.66 points
FLUX.2 Max1,160.87 points
FLUX.2 Pro1,151.76 points
FLUX.2 Flex1,145.47 points
Krea 2 Large1,128.88 points
HiDream-O1-Image1,109.06 points
FLUX.2 Klein 9B1,091.05 points
Stable Diffusion 3.5 Large928.41 points

higher is betterAs of November 6, 2026Scale: 0 points - 1,434.4 points

Source: LMArena
gradually.ai
Methodology and context
Metric
arena-score
Scale
No upper bound is documented. The chart spans the recorded values and zero.
Participants
21
Sample
9,405
Methodology and context
Evidence capture ID: lmarena-text_to_image-5a7e6bb84a93f55df56b198be8e56e53755a216a-43df833a690f. Source payload hash: 43df833a690f9454a344fb4d803c0c2ec845d592681e7f95e9ac50f1c0b25d4a
Source: LMArena

LMArena Text to Image: Portraits

GPT Image 2.5 Sunburst1,461.22 points
GPT Image 2.5 Flare1,439.29 points
GPT Image 21,426.27 points
MAI-Image-2.61,341.91 points
Grok Imagine Image 2.01,332.04 points
Reve 2.11,316.59 points
Muse Image1,289.88 points
Seedream 5.0 Pro1,286.94 points
GPT Image 1.51,258.96 points
Qwen-Image-2.11,256.2 points
Nano Banana Pro1,255.64 points
Nano Banana 21,254.9 points
MAI-Image-2.51,254.78 points
Nano Banana 2 Lite1,244.1 points
FLUX.2 Max1,156.6 points
FLUX.2 Pro1,144.32 points
FLUX.2 Flex1,143.85 points
Krea 2 Large1,123.58 points
HiDream-O1-Image1,105.31 points
FLUX.2 Klein 9B1,091.81 points
Stable Diffusion 3.5 Large941.86 points

higher is betterAs of November 6, 2026Scale: 0 points - 1,461.22 points

Source: LMArena
gradually.ai
Methodology and context
Metric
arena-score
Scale
No upper bound is documented. The chart spans the recorded values and zero.
Participants
21
Sample
5,704
Methodology and context
Evidence capture ID: lmarena-text_to_image-5a7e6bb84a93f55df56b198be8e56e53755a216a-43df833a690f. Source payload hash: 43df833a690f9454a344fb4d803c0c2ec845d592681e7f95e9ac50f1c0b25d4a
Source: LMArena

LMArena Text to Image: Text rendering

GPT Image 2.5 Sunburst1,461.65 points
GPT Image 2.5 Flare1,431.87 points
GPT Image 21,424.21 points
MAI-Image-2.61,365.86 points
Grok Imagine Image 2.01,349.22 points
Reve 2.11,339.46 points
Nano Banana 21,294.44 points
Muse Image1,293.25 points
MAI-Image-2.51,280.73 points
Nano Banana 2 Lite1,273.63 points
Nano Banana Pro1,270.33 points
Seedream 5.0 Pro1,254.93 points
GPT Image 1.51,251.47 points
Qwen-Image-2.11,250.12 points
FLUX.2 Flex1,171.57 points
FLUX.2 Max1,165.6 points
FLUX.2 Pro1,154.35 points
HiDream-O1-Image1,134.31 points
Krea 2 Large1,116.42 points
FLUX.2 Klein 9B1,057.76 points
Stable Diffusion 3.5 Large921.07 points

higher is betterAs of November 6, 2026Scale: 0 points - 1,461.65 points

Source: LMArena
gradually.ai
Methodology and context
Metric
arena-score
Scale
No upper bound is documented. The chart spans the recorded values and zero.
Participants
21
Sample
3,222
Methodology and context
Evidence capture ID: lmarena-text_to_image-5a7e6bb84a93f55df56b198be8e56e53755a216a-43df833a690f. Source payload hash: 43df833a690f9454a344fb4d803c0c2ec845d592681e7f95e9ac50f1c0b25d4a
Source: LMArena

WISE Verified

WISE Verified overall

Stable Diffusion 3.5 Large40.4%

higher is betterAs of August 26, 2026Scale: 0% - 100%

Source: WISE Verified
gradually.ai
Methodology and context
Metric
percent
Scale
0-100
Participants
4
Sample
1,000
Methodology and context
1,000 knowledge and realism tasks. Binary item judgments are averaged by category, and the overall score follows the published weighting.
Source: WISE Verified

WISE culture

Stable Diffusion 3.5 Large49%

higher is betterAs of August 26, 2026Scale: 0% - 100%

Source: WISE Verified
gradually.ai
Methodology and context
Metric
percent
Scale
0-100
Participants
4
Methodology and context
1,000 knowledge and realism tasks. Binary item judgments are averaged by category, and the overall score follows the published weighting.
Source: WISE Verified

WISE time

Stable Diffusion 3.5 Large40.83%

higher is betterAs of August 26, 2026Scale: 0% - 100%

Source: WISE Verified
gradually.ai
Methodology and context
Metric
percent
Scale
0-100
Participants
4
Methodology and context
1,000 knowledge and realism tasks. Binary item judgments are averaged by category, and the overall score follows the published weighting.
Source: WISE Verified

WISE space

Stable Diffusion 3.5 Large44.17%

higher is betterAs of August 26, 2026Scale: 0% - 100%

Source: WISE Verified
gradually.ai
Methodology and context
Metric
percent
Scale
0-100
Participants
4
Methodology and context
1,000 knowledge and realism tasks. Binary item judgments are averaged by category, and the overall score follows the published weighting.
Source: WISE Verified

Recorded measurement details

LMArena Text to Image: 3D modeling (Show measurement, test conditions, and source)
Source value
963.031211018561
Score
963.031211018561
Metric
arena-score
Unit
score
Direction
Higher is better
Source rank
82
Sample
1629
Confidence interval
15.866167
Source type
official-leaderboard
Evaluator
LMArena
Retrieved at
2026-11-06
Methodology
Evidence capture ID: lmarena-text_to_image-5a7e6bb84a93f55df56b198be8e56e53755a216a-43df833a690f. Source payload hash: 43df833a690f9454a344fb4d803c0c2ec845d592681e7f95e9ac50f1c0b25d4a
Source LMArena
LMArena Text to Image: Art (Show measurement, test conditions, and source)
Source value
997.287526502457
Score
997.287526502457
Metric
arena-score
Unit
score
Direction
Higher is better
Source rank
79
Sample
5340
Confidence interval
9.43801
Source type
official-leaderboard
Evaluator
LMArena
Retrieved at
2026-11-06
Methodology
Evidence capture ID: lmarena-text_to_image-5a7e6bb84a93f55df56b198be8e56e53755a216a-43df833a690f. Source payload hash: 43df833a690f9454a344fb4d803c0c2ec845d592681e7f95e9ac50f1c0b25d4a
Source LMArena
LMArena Text to Image: Cartoon (Show measurement, test conditions, and source)
Source value
945.2276343193511
Score
945.2276343193511
Metric
arena-score
Unit
score
Direction
Higher is better
Source rank
82
Sample
12274
Confidence interval
6.30568
Source type
official-leaderboard
Evaluator
LMArena
Retrieved at
2026-11-06
Methodology
Evidence capture ID: lmarena-text_to_image-5a7e6bb84a93f55df56b198be8e56e53755a216a-43df833a690f. Source payload hash: 43df833a690f9454a344fb4d803c0c2ec845d592681e7f95e9ac50f1c0b25d4a
Source LMArena
LMArena Text to Image: Commercial design (Show measurement, test conditions, and source)
Source value
936.7720225800615
Score
936.7720225800615
Metric
arena-score
Unit
score
Direction
Higher is better
Source rank
83
Sample
3051
Confidence interval
10.982532
Source type
official-leaderboard
Evaluator
LMArena
Retrieved at
2026-11-06
Methodology
Evidence capture ID: lmarena-text_to_image-5a7e6bb84a93f55df56b198be8e56e53755a216a-43df833a690f. Source payload hash: 43df833a690f9454a344fb4d803c0c2ec845d592681e7f95e9ac50f1c0b25d4a
Source LMArena
LMArena Text to Image: Overall (Show measurement, test conditions, and source)
Source value
938.3505705225074
Score
938.3505705225074
Metric
arena-score
Unit
score
Direction
Higher is better
Source rank
83
Sample
23396
Confidence interval
4.477654
Source type
official-leaderboard
Evaluator
LMArena
Retrieved at
2026-11-06
Methodology
Evidence capture ID: lmarena-text_to_image-5a7e6bb84a93f55df56b198be8e56e53755a216a-43df833a690f. Source payload hash: 43df833a690f9454a344fb4d803c0c2ec845d592681e7f95e9ac50f1c0b25d4a
Source LMArena
LMArena Text to Image: Photorealism (Show measurement, test conditions, and source)
Source value
928.4134070367361
Score
928.4134070367361
Metric
arena-score
Unit
score
Direction
Higher is better
Source rank
83
Sample
9405
Confidence interval
7.027447
Source type
official-leaderboard
Evaluator
LMArena
Retrieved at
2026-11-06
Methodology
Evidence capture ID: lmarena-text_to_image-5a7e6bb84a93f55df56b198be8e56e53755a216a-43df833a690f. Source payload hash: 43df833a690f9454a344fb4d803c0c2ec845d592681e7f95e9ac50f1c0b25d4a
Source LMArena
LMArena Text to Image: Portraits (Show measurement, test conditions, and source)
Source value
941.860106062526
Score
941.860106062526
Metric
arena-score
Unit
score
Direction
Higher is better
Source rank
82
Sample
5704
Confidence interval
8.853952
Source type
official-leaderboard
Evaluator
LMArena
Retrieved at
2026-11-06
Methodology
Evidence capture ID: lmarena-text_to_image-5a7e6bb84a93f55df56b198be8e56e53755a216a-43df833a690f. Source payload hash: 43df833a690f9454a344fb4d803c0c2ec845d592681e7f95e9ac50f1c0b25d4a
Source LMArena
LMArena Text to Image: Text rendering (Show measurement, test conditions, and source)
Source value
921.0668654000264
Score
921.0668654000264
Metric
arena-score
Unit
score
Direction
Higher is better
Source rank
83
Sample
3222
Confidence interval
10.769655
Source type
official-leaderboard
Evaluator
LMArena
Retrieved at
2026-11-06
Methodology
Evidence capture ID: lmarena-text_to_image-5a7e6bb84a93f55df56b198be8e56e53755a216a-43df833a690f. Source payload hash: 43df833a690f9454a344fb4d803c0c2ec845d592681e7f95e9ac50f1c0b25d4a
Source LMArena
WISE Verified overall (Show measurement, test conditions, and source)
Source value
40.4
Score
40.4
Metric
percent
Unit
%
Direction
Higher is better
Source rank
4
Sample
1000
Source type
research-benchmark
Evaluator
Qwen3.5-35B-A3B
Retrieved at
2026-08-26
Methodology
1,000 knowledge and realism tasks. Binary item judgments are averaged by category, and the overall score follows the published weighting.
Source WISE Verified
WISE culture (Show measurement, test conditions, and source)
Source value
49
Score
49
Metric
percent
Unit
%
Direction
Higher is better
Source rank
3
Source type
research-benchmark
Evaluator
Qwen3.5-35B-A3B
Retrieved at
2026-08-26
Methodology
1,000 knowledge and realism tasks. Binary item judgments are averaged by category, and the overall score follows the published weighting.
Source WISE Verified
WISE time (Show measurement, test conditions, and source)
Source value
40.83
Score
40.83
Metric
percent
Unit
%
Direction
Higher is better
Source rank
3
Source type
research-benchmark
Evaluator
Qwen3.5-35B-A3B
Retrieved at
2026-08-26
Methodology
1,000 knowledge and realism tasks. Binary item judgments are averaged by category, and the overall score follows the published weighting.
Source WISE Verified
WISE space (Show measurement, test conditions, and source)
Source value
44.17
Score
44.17
Metric
percent
Unit
%
Direction
Higher is better
Source rank
4
Source type
research-benchmark
Evaluator
Qwen3.5-35B-A3B
Retrieved at
2026-08-26
Methodology
1,000 knowledge and realism tasks. Binary item judgments are averaged by category, and the overall score follows the published weighting.
Source WISE Verified

Page 1 of 7

Popularity compared

How often the model is searched for, used and mentioned, compared with every model of its category.

Popularity index

The 100 most popular models of this category, 0 to 100, higher is more popular

20 of 100 models

As of November 2026 · Source: gradually.ai popularity index

Over time

Weekly values from October 18, 2026 to November 5, 2026

Stable Diffusion 3.5 LargeMAI-Image-2.5GPT Image 2.5 FlareHiDream-O1-ImageHunyuanImage 3.0 Instruct

Stable Diffusion 3.5 Large compared

Compare with another model

The most popular comparisons

  1. 1Krea 2 Large vs. Stable Diffusion 3.5 Large
  2. 2FLUX.2 Max vs. Stable Diffusion 3.5 Large
  3. 3Stable Diffusion 3.5 Large vs. Qwen-Image-2.1
  4. 4Krea 2 Medium Turbo vs. Stable Diffusion 3.5 Large
  5. 5FLUX.2 Klein 9B vs. Stable Diffusion 3.5 Large
  6. 6GPT Image 2.5 Sunburst vs. Stable Diffusion 3.5 Large
  7. 7GPT Image 2 vs. Stable Diffusion 3.5 Large
  8. 8Reve 2.1 vs. Stable Diffusion 3.5 Large
  9. 9Nano Banana 2 vs. Stable Diffusion 3.5 Large
Show all 108 comparisons
  1. 10Midjourney V8.2 vs. Stable Diffusion 3.5 Large
  2. 11GPT Image 1.5 vs. Stable Diffusion 3.5 Large
  3. 12MAI-Image-2.5 vs. Stable Diffusion 3.5 Large
  4. 13Nano Banana Pro vs. Stable Diffusion 3.5 Large
  5. 14Nano Banana 2 Lite vs. Stable Diffusion 3.5 Large
  6. 15Seedream 5.0 Pro vs. Stable Diffusion 3.5 Large
  7. 16Grok Imagine Image Quality vs. Stable Diffusion 3.5 Large
  8. 17Qwen Image 2.0 Pro vs. Stable Diffusion 3.5 Large
  9. 18MAI-Image-2.5 Flash vs. Stable Diffusion 3.5 Large
  10. 19HiDream-O1-Image-1.5 vs. Stable Diffusion 3.5 Large
  11. 20Seedream 4.0 vs. Stable Diffusion 3.5 Large
  12. 21Luma Uni-1.1 Max vs. Stable Diffusion 3.5 Large
  13. 22FLUX.2 Flex vs. Stable Diffusion 3.5 Large
  14. 23Recraft V4.1 Utility vs. Stable Diffusion 3.5 Large
  15. 24Ideogram 4.0 vs. Stable Diffusion 3.5 Large
  16. 25Wan 2.6 Text to Image vs. Stable Diffusion 3.5 Large
  17. 26FLUX.2 Pro vs. Stable Diffusion 3.5 Large
  18. 27HunyuanImage 3.0 Instruct vs. Stable Diffusion 3.5 Large
  19. 28HiDream-O1-Image vs. Stable Diffusion 3.5 Large
  20. 29Firefly Image Model 5 vs. Stable Diffusion 3.5 Large
  21. 30Midjourney V8.1 vs. Stable Diffusion 3.5 Large
  22. 31Stable Diffusion 3.5 Large vs. GPT Image 2.5 Flare
  23. 32Stable Diffusion 3.5 Large vs. MAI-Image-2.6
  24. 33Stable Diffusion 3.5 Large vs. MAI-Image-2.6 Flash
  25. 34Stable Diffusion 3.5 Large vs. Muse Image
  26. 35Stable Diffusion 3.5 Large vs. Grok Imagine Image 2.0
  27. 36Stable Diffusion 3.5 Large vs. FLUX 3 Image
  28. 37Stable Diffusion 3.5 Large vs. FLUX 3 Image Klein
  29. 38Stable Diffusion 3.5 Large vs. Nano Banana 2.1
  30. 39Stable Diffusion 3.5 Large vs. Ideogram 4.5
  31. 40Stable Diffusion 3.5 Large vs. Hy Image 3.5 Preview
  32. 41Stable Diffusion 3.5 Large vs. Recraft V4.1
  33. 42Stable Diffusion 3.5 Large vs. Recraft V4.1 Flash
  34. 43Stable Diffusion 3.5 Large vs. Bria FIBO 2
  35. 44Stable Diffusion 3.5 Large vs. Krea 3
  36. 45Stable Diffusion 3.5 Large vs. Qwen Image 3.0 Pro
  37. 46Stable Diffusion 3.5 Large vs. Qwen Image 3.0
  38. 47Stable Diffusion 3.5 Large vs. Qwen Image 2.1 Pro
  39. 48Stable Diffusion 3.5 Large vs. Qwen Image 2.1 Turbo
  40. 49Stable Diffusion 3.5 Large vs. Wan 2.7 Image Pro
  41. 50Stable Diffusion 3.5 Large vs. Wan 2.7 Image
  42. 51Stable Diffusion 3.5 Large vs. Seedream 5.0 Flash
  43. 52Stable Diffusion 3.5 Large vs. SenseNova U1.5 Lite
  44. 53Stable Diffusion 3.5 Large vs. Kling Image 3.0
  45. 54Stable Diffusion 3.5 Large vs. Kling Image 3.0 Omni
  46. 55Stable Diffusion 3.5 Large vs. Vidu Q2 Image
  47. 56Stable Diffusion 3.5 Large vs. GLM-Image
  48. 57Stable Diffusion 3.5 Large vs. MiniMax Image-01
  49. 58Stable Diffusion 3.5 Large vs. Z-Image Turbo
  50. 59Stable Diffusion 3.5 Large vs. Luma Uni-1.1
  51. 60Stable Diffusion 3.5 Large vs. Runway Gen-4 Image
  52. 61Stable Diffusion 3.5 Large vs. Adobe Firefly Image 3
  53. 62Stable Diffusion 3.5 Large vs. Adobe Firefly Image 4
  54. 63Stable Diffusion 3.5 Large vs. Adobe Firefly Image 4 Ultra
  55. 64Stable Diffusion 3.5 Large vs. Stable Diffusion 3.5 Medium
  56. 65Stable Diffusion 3.5 Large vs. Stable Diffusion 3.5 Large Turbo
  57. 66Stable Diffusion 3.5 Large vs. Bria FIBO Lite
  58. 67Stable Diffusion 3.5 Large vs. Recraft V4.1 Utility Pro
  59. 68Stable Diffusion 3.5 Large vs. Seedream 4.5
  60. 69Stable Diffusion 3.5 Large vs. Seedream 5.0 Lite
  61. 70Stable Diffusion 3.5 Large vs. FLUX.2 Klein 9B Preview
  62. 71Stable Diffusion 3.5 Large vs. GPT Image 1 Mini
  63. 72Stable Diffusion 3.5 Large vs. ChatGPT Image Latest (API-Alias)
  64. 73Stable Diffusion 3.5 Large vs. Nano Banana (Gemini 2.5 Flash Image)
  65. 74Stable Diffusion 3.5 Large vs. FLUX.2 Klein 4B
  66. 75Stable Diffusion 3.5 Large vs. FLUX.2 Dev
  67. 76Stable Diffusion 3.5 Large vs. FLUX1.1 [pro]
  68. 77Stable Diffusion 3.5 Large vs. FLUX1.1 [pro] Ultra
  69. 78Stable Diffusion 3.5 Large vs. FLUX.1 [dev]
  70. 79Stable Diffusion 3.5 Large vs. FLUX.1 Kontext [pro]
  71. 80Stable Diffusion 3.5 Large vs. FLUX.1 Kontext [max]
  72. 81Stable Diffusion 3.5 Large vs. Stable Diffusion XL 1.0
  73. 82Stable Diffusion 3.5 Large vs. Stable Diffusion 3 Medium
  74. 83Stable Diffusion 3.5 Large vs. SDXL Turbo
  75. 84Stable Diffusion 3.5 Large vs. Stable Diffusion Turbo
  76. 85Stable Diffusion 3.5 Large vs. Grok Imagine Image 1.0
  77. 86Stable Diffusion 3.5 Large vs. MOSS-Image-Base
  78. 87Stable Diffusion 3.5 Large vs. MOSS-Image-SFT
  79. 88Stable Diffusion 3.5 Large vs. LLaDA-Image
  80. 89Stable Diffusion 3.5 Large vs. LLaDA-Image-Turbo
  81. 90Stable Diffusion 3.5 Large vs. Nucleus-Image
  82. 91Stable Diffusion 3.5 Large vs. LongCat-Image
  83. 92Stable Diffusion 3.5 Large vs. BAGEL-7B-MoT
  84. 93Stable Diffusion 3.5 Large vs. OmniGen2
  85. 94Stable Diffusion 3.5 Large vs. Kandinsky-5.0-T2I-Lite-SFT
  86. 95Stable Diffusion 3.5 Large vs. Kandinsky-5.0-T2I-Lite-Pretrain
  87. 96Stable Diffusion 3.5 Large vs. Boogu-Image-0.1-Base
  88. 97Stable Diffusion 3.5 Large vs. Boogu-Image-0.1-Turbo
  89. 98Stable Diffusion 3.5 Large vs. SANA-1.5 1.6B 1024px
  90. 99Stable Diffusion 3.5 Large vs. SANA-1.5 4.8B 1024px
  91. 100Stable Diffusion 3.5 Large vs. Sana-Sprint 0.6B 1024px
  92. 101Stable Diffusion 3.5 Large vs. Sana-Sprint 1.6B 1024px
  93. 102Stable Diffusion 3.5 Large vs. Chroma1-HD
  94. 103Stable Diffusion 3.5 Large vs. Chroma1-Flash
  95. 104Stable Diffusion 3.5 Large vs. AuraFlow v0.3
  96. 105Stable Diffusion 3.5 Large vs. PixArt-Sigma-XL-2-1024-MS
  97. 106Stable Diffusion 3.5 Large vs. Lumina-Image 2.0
  98. 107Stable Diffusion 3.5 Large vs. HunyuanImage 3.0
  99. 108Stable Diffusion 3.5 Large vs. Z-Image Base

All specifications

Architecture

Parameters
8.1B
Source: Parameters

Input and output

Maximum output
1 megapixels
Source: Maximum output

Watermarking and provenance

AI watermarking refers to invisible signals embedded in the output. Visible marks and provenance metadata are listed separately. Unknown means there is insufficient evidence for that particular field.

AI watermarking
Unknown. One Stability page describes imperceptible watermarks on its platform and watermarking by default in open image models. A report covering April 2024 to April 2025 describes technical challenges and does not confirm coverage of individual model versions. Coverage of a specific output remains unclear.
Source 1: AI watermarkingSource 2: AI watermarking
Provenance metadata
Stability AI documented C2PA signing for API outputs during its April 2024 to April 2025 reporting period. Current coverage and other output paths are not established by this report.
Source: Provenance metadata

Licence and access

Weights
Open weights
Source: Weights
Access
API, Local
Source: Access

Further details

Generator
sd3.5-large
Source: Generator

Prices

fal.ai (fal-ai/stable-diffusion-v35-large)
$0.13 per image (estimated)Source

Frequently asked questions about Stable Diffusion 3.5 Large

How good is Stable Diffusion 3.5 Large?

Rank 21 of 21 in the arena rating. Rank 87 of 108 in our own test.

Arena rating from Nov 6, 2026 · GraduallyBench from Nov 3, 2026

Arena ratingfrom user votes · higher is better
FLUX.2 Max1,161
FLUX.2 Flex1,156
FLUX.2 Pro1,153
Krea 2 Large1,115
HiDream-O1-Image1,115
FLUX.2 Klein 9B1,070
Stable Diffusion 3.5 LargeRank 21 of 21938
GraduallyBenchour own rating, 0 to 100 · higher is better
LLaDA-Image-Turbo31
Vidu Q2 Image31
Kandinsky-5.0-T2I-Lite-Pretrain28
Stable Diffusion 3.5 LargeRank 87 of 10827
Stable Diffusion 3.5 Large Turbo27
HunyuanImage 3.027
Stable Diffusion 3.5 Medium25

What is Stable Diffusion 3.5 Large good at?

Best at Infographic (39 out of 100), weakest at Product photography (17).

GraduallyBench, one image per task

  1. Stable Diffusion 3.5 Large: Typography and layoutTypography and layoutLegible text, hierarchy, and composition31out of 100Rank 75 of 108 in this task
  2. Stable Diffusion 3.5 Large: Product photographyProduct photographyMaterials, reflections, and fine details17out of 100Rank 89 of 108 in this task
  3. Stable Diffusion 3.5 Large: Character and detailCharacter and detailAnatomy, clothing, and spatial consistency23out of 100Rank 97 of 108 in this task
  4. Stable Diffusion 3.5 Large: InfographicInfographicNumbers, labels, and visual organization39out of 100Rank 63 of 108 in this task

Sources and data date

Show all 25 sources

Benchmark sources at a glance

Which independent evaluators tested this model. This is coverage, not a quality ranking.

No active result from the reviewed external evaluators can currently be attributed to this model. Other source evidence remains available below.

Without vendor claims and historical or disputed results; those stay labelled in the single values.

TypeEvidence and data date
Research statusResearch date October 17, 2026. 11 source URLs checked. This documents the inspected sources, not an exhaustive inventory of every publication.
Not published

exact-serving-configuration

Original wording

The evaluator does not publish the serving pipeline, checkpoint hash, sampler, output resolution, or generation controls.

Not published

model-specific-successful-image-denominator

Original wording

The paper and release documentation do not publish the per-model successful-image or prompt denominators for these means. The 432-prompt corpus and planned four samples per prompt are not used to infer N or confidence intervals.

Not published

exact-checkpoint-and-generation-configuration

Original wording

The paper's SD3.5 Large label is exact, but it does not publish a checkpoint hash, sampler, output resolution, seed or generation controls for the evaluated run.

Not published

model-specific-sample-count

Note

GenExam gives a suite-level count of 1,000 samples, not the evaluated denominator for this model.

Not published

confidence-interval

Note

No confidence interval is published for this leaderboard score.

Not published

exact-model-route

Note

The leaderboard does not disclose the API route or serving checkpoint revision.

Additional sourceStability AI · Stability AI Stable Diffusion 3.5 announcement · Editorial description reviewed October 2, 2026
Additional sourcefal.ai
Additional sourceLMArena (retrieved November 6, 2026)
Additional sourceWISE Verified (retrieved August 26, 2026)
Additional sourceGradually-Bildtest (retrieved November 3, 2026)
Additional sourceRapidata benchmark.ai (retrieved October 17, 2026; October 28, 2026)
Additional sourceUltraText Bench: Evaluating Dense Text Rendering in Generated Images (retrieved October 17, 2026)
Additional sourceGenExam, OpenGVLab (retrieved October 17, 2026)
Additional sourceAMVICC paper authors (arXiv:2601.17037v1) (retrieved October 18, 2026)
Additional sourceRapidata text-to-image human feedback benchmark (retrieved October 22, 2026)
Additional sourceBenchmark.ai Image Benchmark (built by Rapidata) (retrieved October 23, 2026)
Additional sourceDialectGen: Benchmarking and Improving Dialect Robustness in Multimodal Generation (arXiv:2510.14949v3) (retrieved October 23, 2026)
Additional sourceModel metadata (retrieved October 17, 2026)123
Additional sourceModel metadata (retrieved October 28, 2026)
Additional sourceStability AI: Content ecosystem (retrieved November 5, 2026)
Additional sourceStability AI: Integrity transparency report (retrieved November 5, 2026)
Additional sourceOpenRouter: Popularity index (derived), CC BY 4.0
Additional sourceVercel AI Gateway: Popularity index (derived), CC BY 4.0
Additional sourceOllama: cumulative downloads for the popularity index
Additional sourceReplicate: cumulative runs for the popularity index
Additional sourceGoogle Trending Now: limited feed selection for Germany and the US
Additional sourceCreative Commons Attribution 4.0
Additional sourceStability AI release notes (2026-09-09)