MicrosoftLanguage model

WizardLM-2 8x22B

WizardLM-2 8x22B has no overall index value yet because there are too few independent benchmark results.

PopularityRank 400 of 785

36out of 100-1 vs. last month

based on search, usage and attention

Summary

WizardLM-2 8x22B is Microsoft’s large sparse Mixture-of-Experts instruction model. The checkpoint has 141 billion total parameters, with roughly 39 billion activated per token. Microsoft positions it as the largest WizardLM-2 variant for complex conversation, multilingual work, reasoning, and agentic tasks. Its context window is 65,536 tokens.

The model card documents serving through Transformers, vLLM, and SGLang. Its model list also includes quantized versions for llama.cpp, Ollama, and LM Studio. The Apache-2.0 license applies to the published checkpoint.

See for yourself: one prompt, one attempt

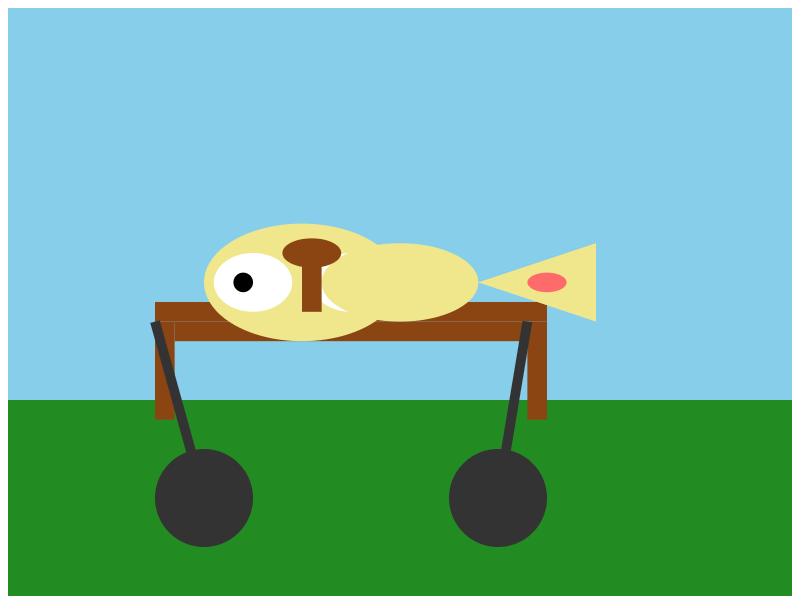
SVG short test

One SVG task with the same fixed settings for every model, without hidden thinking.

WizardLM-2 8x22B

WizardLM-2 8x22B: SVG short test

Prompt

Return only one standalone SVG of a pelican riding a bicycle. Use viewBox="0 0 800 600", simple shapes, two clearly visible wheels and a recognizable pelican with a long beak. At most 30 SVG elements and 1800 characters. No Markdown, explanations, comments, scripts, animation, CSS or external resources.

Oct 14, 2026 · $0.0004

Test details
Test run
Oct 14, 2026
Provider
novita/bf16
API model
microsoft/wizardlm-2-8x22b
Output
509 tokens
Reasoning
API reports 0 reasoning tokens
Cost of the attempt
$0.0004
Test round
43b8c5c46830

All benchmark results

Every published result with its source, test setup and comparison models.

Show all 62 published benchmark results

Page 1 of 6

Measurements without matching peer values

These measurements have no matching peer values under the same test conditions. Their original values and sources remain available here.

IFEval strict accuracy (Show measurement, test conditions, and source)
Source value
52.72
Score
52.72
Metric
0-shot strict accuracy
Unit
%
Benchmark version
Open LLM Leaderboard row; IFEval 0-shot
Category
general
Direction
Higher is better
Source type
official-leaderboard
Evaluator
WizardLM-2 8x22B model-card Open LLM Leaderboard evaluation table
Status
active
Retrieved at
2026-10-15
Methodology
Official benchmark leaderboard. Exact alpindale/WizardLM-2-8x22B model-index value; IFEval is 0-shot as specified in the model card.
Context
The model card embeds Open LLM Leaderboard values but does not pin the evaluated repository revision or complete decoding configuration.
Source WizardLM-2 8x22B model-card Open LLM Leaderboard evaluation table
BBH normalized accuracy (Show measurement, test conditions, and source)
Source value
48.58
Score
48.58
Metric
3-shot accuracy
Unit
%
Benchmark version
Open LLM Leaderboard row; BBH 3-shot
Category
general
Direction
Higher is better
Source type
official-leaderboard
Evaluator
WizardLM-2 8x22B model-card Open LLM Leaderboard evaluation table
Status
active
Retrieved at
2026-10-15
Methodology
Official benchmark leaderboard. Exact alpindale/WizardLM-2-8x22B model-index value; BBH is 3-shot as specified in the model card.
Context
The model card embeds Open LLM Leaderboard values but does not pin the evaluated repository revision or complete decoding configuration.
Source WizardLM-2 8x22B model-card Open LLM Leaderboard evaluation table
MATH Lvl 5 exact match (Show measurement, test conditions, and source)
Source value
22.28
Score
22.28
Metric
4-shot exact match
Unit
%
Benchmark version
Open LLM Leaderboard row; MATH Level 5 4-shot
Category
general
Direction
Higher is better
Source type
official-leaderboard
Evaluator
WizardLM-2 8x22B model-card Open LLM Leaderboard evaluation table
Status
active
Retrieved at
2026-10-15
Methodology
Official benchmark leaderboard. Exact alpindale/WizardLM-2-8x22B model-index value; MATH Level 5 is 4-shot as specified in the model card.
Context
The model card embeds Open LLM Leaderboard values but does not pin the evaluated repository revision or complete decoding configuration.
Source WizardLM-2 8x22B model-card Open LLM Leaderboard evaluation table
GPQA accuracy (Show measurement, test conditions, and source)
Source value
17.56
Score
17.56
Metric
0-shot accuracy
Unit
%
Benchmark version
Open LLM Leaderboard row; GPQA 0-shot
Category
general
Direction
Higher is better
Source type
official-leaderboard
Evaluator
WizardLM-2 8x22B model-card Open LLM Leaderboard evaluation table
Status
active
Retrieved at
2026-10-15
Methodology
Official benchmark leaderboard. Exact alpindale/WizardLM-2-8x22B model-index value; GPQA is 0-shot as specified in the model card.
Context
The model card embeds Open LLM Leaderboard values but does not pin the evaluated repository revision or complete decoding configuration.
Source WizardLM-2 8x22B model-card Open LLM Leaderboard evaluation table
MuSR accuracy (Show measurement, test conditions, and source)
Source value
14.54
Score
14.54
Metric
0-shot accuracy
Unit
%
Benchmark version
Open LLM Leaderboard row; MuSR 0-shot
Category
general
Direction
Higher is better
Source type
official-leaderboard
Evaluator
WizardLM-2 8x22B model-card Open LLM Leaderboard evaluation table
Status
active
Retrieved at
2026-10-15
Methodology
Official benchmark leaderboard. Exact alpindale/WizardLM-2-8x22B model-index value; MuSR is 0-shot as specified in the model card.
Context
The model card embeds Open LLM Leaderboard values but does not pin the evaluated repository revision or complete decoding configuration.
Source WizardLM-2 8x22B model-card Open LLM Leaderboard evaluation table
MMLU-Pro accuracy (Show measurement, test conditions, and source)
Source value
39.96
Score
39.96
Metric
5-shot accuracy
Unit
%
Benchmark version
Open LLM Leaderboard row; MMLU-Pro 5-shot
Category
general
Direction
Higher is better
Source type
official-leaderboard
Evaluator
WizardLM-2 8x22B model-card Open LLM Leaderboard evaluation table
Status
active
Retrieved at
2026-10-15
Methodology
Official benchmark leaderboard. Exact alpindale/WizardLM-2-8x22B model-index value; MMLU-Pro is 5-shot as specified in the model card.
Context
The model card embeds Open LLM Leaderboard values but does not pin the evaluated repository revision or complete decoding configuration.
Source WizardLM-2 8x22B model-card Open LLM Leaderboard evaluation table
AlpacaEval 2.0 length-controlled win rate (Show measurement, test conditions, and source)
Source value
51.3
Score
51.3
Metric
LC win rate
Unit
%
Benchmark version
AlpacaEval 2.0
Category
general
Direction
Higher is better
Source type
independent-evaluator
Evaluator
OSC: Cognitive Orchestration through Dynamic Knowledge Alignment in Multi-Agent LLM Collaboration, Table 1
Status
active
Retrieved at
2026-10-17
Methodology
Independent evaluation. OSC paper Table 1. The authors explicitly say the WizardLM-2-8x22B results are from prior work. AlpacaEval 2.0 uses 805 instructions compared with GPT-4 Preview and a GPT-4-based evaluator; MT-Bench uses published multi-turn dialogue scores.
Context
Prior-work result reproduced by the paper, not a new run by its authors. Scored N, confidence intervals, and complete generation configuration are not given.
Source OSC: Cognitive Orchestration through Dynamic Knowledge Alignment in Multi-Agent LLM Collaboration, Table 1
AlpacaEval 2.0 standard win rate (Show measurement, test conditions, and source)
Source value
62.3
Score
62.3
Metric
standard win rate
Unit
%
Benchmark version
AlpacaEval 2.0
Category
general
Direction
Higher is better
Source type
independent-evaluator
Evaluator
OSC: Cognitive Orchestration through Dynamic Knowledge Alignment in Multi-Agent LLM Collaboration, Table 1
Status
active
Retrieved at
2026-10-17
Methodology
Independent evaluation. OSC paper Table 1. The authors explicitly say the WizardLM-2-8x22B results are from prior work. AlpacaEval 2.0 uses 805 instructions compared with GPT-4 Preview and a GPT-4-based evaluator; MT-Bench uses published multi-turn dialogue scores.
Context
Prior-work result reproduced by the paper, not a new run by its authors. Scored N, confidence intervals, and complete generation configuration are not given.
Source OSC: Cognitive Orchestration through Dynamic Knowledge Alignment in Multi-Agent LLM Collaboration, Table 1
DynaCode (Show measurement, test conditions, and source)
Source value
35.4
Score
35.4
Metric
Pass@1; Unit 1
Unit
%
Benchmark version
Findings of ACL 2025 paper, Table 2; DynaCode
Direction
Higher is better
Source type
independent-evaluator
Evaluator
DynaCode paper, Findings of ACL 2025, ACL Anthology ID 2025.findings-acl.1133
Status
active
Retrieved at
2026-10-19
Methodology
Independent evaluation. Exact paper row WizardLM-2-8x22B (176B); Pass@1 means percentage of problems solved correctly on the first attempt, with temperature 0. The paper says results are averaged over three experiments using five random seeds. Row-level scored denominator, served checkpoint revision, and complete generation settings are not bound to this row.
Context
The paper prints parenthetical ± values for Table 2; their meaning is not mapped to a confidence interval here. The table's Average is retained as the publisher-labeled value, not recalculated.
Source DynaCode paper, Findings of ACL 2025, ACL Anthology ID 2025.findings-acl.1133
DynaCode (Show measurement, test conditions, and source)
Source value
27.5
Score
27.5
Metric
Pass@1; Unit 2
Unit
%
Benchmark version
Findings of ACL 2025 paper, Table 2; DynaCode
Direction
Higher is better
Source type
independent-evaluator
Evaluator
DynaCode paper, Findings of ACL 2025, ACL Anthology ID 2025.findings-acl.1133
Status
active
Retrieved at
2026-10-19
Methodology
Independent evaluation. Exact paper row WizardLM-2-8x22B (176B); Pass@1 means percentage of problems solved correctly on the first attempt, with temperature 0. The paper says results are averaged over three experiments using five random seeds. Row-level scored denominator, served checkpoint revision, and complete generation settings are not bound to this row.
Context
The paper prints parenthetical ± values for Table 2; their meaning is not mapped to a confidence interval here. The table's Average is retained as the publisher-labeled value, not recalculated.
Source DynaCode paper, Findings of ACL 2025, ACL Anthology ID 2025.findings-acl.1133
DynaCode (Show measurement, test conditions, and source)
Source value
25.1
Score
25.1
Metric
Pass@1; Unit 3
Unit
%
Benchmark version
Findings of ACL 2025 paper, Table 2; DynaCode
Direction
Higher is better
Source type
independent-evaluator
Evaluator
DynaCode paper, Findings of ACL 2025, ACL Anthology ID 2025.findings-acl.1133
Status
active
Retrieved at
2026-10-19
Methodology
Independent evaluation. Exact paper row WizardLM-2-8x22B (176B); Pass@1 means percentage of problems solved correctly on the first attempt, with temperature 0. The paper says results are averaged over three experiments using five random seeds. Row-level scored denominator, served checkpoint revision, and complete generation settings are not bound to this row.
Context
The paper prints parenthetical ± values for Table 2; their meaning is not mapped to a confidence interval here. The table's Average is retained as the publisher-labeled value, not recalculated.
Source DynaCode paper, Findings of ACL 2025, ACL Anthology ID 2025.findings-acl.1133
DynaCode (Show measurement, test conditions, and source)
Source value
12.8
Score
12.8
Metric
Pass@1; Unit 4
Unit
%
Benchmark version
Findings of ACL 2025 paper, Table 2; DynaCode
Direction
Higher is better
Source type
independent-evaluator
Evaluator
DynaCode paper, Findings of ACL 2025, ACL Anthology ID 2025.findings-acl.1133
Status
active
Retrieved at
2026-10-19
Methodology
Independent evaluation. Exact paper row WizardLM-2-8x22B (176B); Pass@1 means percentage of problems solved correctly on the first attempt, with temperature 0. The paper says results are averaged over three experiments using five random seeds. Row-level scored denominator, served checkpoint revision, and complete generation settings are not bound to this row.
Context
The paper prints parenthetical ± values for Table 2; their meaning is not mapped to a confidence interval here. The table's Average is retained as the publisher-labeled value, not recalculated.
Source DynaCode paper, Findings of ACL 2025, ACL Anthology ID 2025.findings-acl.1133

Page 1 of 6

Popularity compared

How often the model is searched for, used and mentioned, compared with every model of its category.

Popularity index

The 100 most popular models of this category, 0 to 100, higher is more popular

20 of 101 models

As of November 2026 · Source: gradually.ai popularity index

Over time

Weekly values from October 18, 2026 to November 7, 2026

WizardLM-2 8x22BAion 3.5 36Claude Opus 4.6 36ZDTaichu5.0-9B 36Apodex 1.1 Mini 36

Method changes in the timeline, a jump at these points is no market event:

  1. 1November 1, 2026: Value only with search or usage data, 30-day attention

What is gaining popularity right now, across models, vendors, harnesses and AI subscriptions, is collected in All AI trends.

All specifications

Architecture

Parameters
141 billion
Source: Parameters
Active parameters
39 billion
Source: Active parameters

Input and output

Context window
65,536 tokens
Source: Context window
Inputs
Text
Source: Inputs
Outputs
Text
Source: Outputs

Watermarking and provenance

AI watermarking refers to invisible signals embedded in the output. Visible marks and provenance metadata are listed separately. Unknown means there is insufficient evidence for that particular field.

AI watermarking
Unknown
no source
Watermarking technique
Not known
no source

Licence and access

Weights
Open weights
Source: Weights
License
Apache 2.0
Source: License

Frequently asked questions about WizardLM-2 8x22B

How large is the context window of WizardLM-2 8x22B?

65,536 tokens. That is how much text WizardLM-2 8x22B reads at once, about 100 A4 pages.

Page count as a rule of thumb from Artificial Analysis

Context windowTokens the model reads at once · higher is better
GLM-5.1200K
DeepSeek-V3 0324164K
GLM-4.5131K
GPT OSS 120B131K
DeepSeek-V3.2128K
DeepSeek-R1128K
WizardLM-2 8x22BRank 103 of 10366K

Can I run WizardLM-2 8x22B locally?

Yes, the weights are open. With 141B parameters it needs a lot of memory, more a server than a laptop.

Stated by Microsoft

Open weights
yes
License
Apache 2.0
Parameters
141B
active per token
39B

Sources and data date

Show all 18 sources

Benchmark sources at a glance

Which independent evaluators tested this model. This is coverage, not a quality ranking.

No active result from the reviewed external evaluators can currently be attributed to this model. Other source evidence remains available below.

Without vendor claims and historical or disputed results; those stay labelled in the single values.

TypeEvidence and data date
Input

Documented modalities.

Output

Documented modalities.

Research statusResearch date October 15, 2026. 10 source URLs checked. This documents the inspected sources, not an exhaustive inventory of every publication.
Not published

checkpoint-revision

Note

The embedded leaderboard table does not pin the exact weight revision and some task/date details.

Not published

scored-denominator-and-generation-settings

Note

The cited result tables omit task-level scored denominators and complete sampling/decoding details. The OSC paper marks the WizardLM results as prior work.

Not published

score-unit

Original wording

The inspected Table 3 excerpt presents numeric scores without an explicit unit label; no percent unit is inferred.

Not published

confidence-interval-95

Original wording

The paper does not report a 95% confidence interval for these cells.

Not published

immutable-api-served-revision

Original wording

The paper identifies Lepton AI API as the route but no immutable served revision.

Additional sourceWizardLM-2 8x22B model-card Open LLM Leaderboard evaluation table (retrieved October 15, 2026)
Additional sourceTIGER-Lab official MMLU-Pro leaderboard results.csv (retrieved October 15, 2026)
Additional sourceOSC: Cognitive Orchestration through Dynamic Knowledge Alignment in Multi-Agent LLM Collaboration, Table 1 (retrieved October 17, 2026)
Additional sourceArena Learning: Build Data Flywheel for LLMs, Table 8 (retrieved October 17, 2026)
Additional sourceDARG (NeurIPS 2024) (retrieved October 18, 2026)
Additional sourceFinance Language Model Evaluation (FLAME) (retrieved October 19, 2026)
Additional sourceDynaCode paper, Findings of ACL 2025, ACL Anthology ID 2025.findings-acl.1133 (retrieved October 19, 2026)
Additional sourceNeurIPS 2024 Datasets and Benchmarks Track paper publishing REPLIQA0 results (retrieved October 19, 2026)
Additional sourceModel metadata (retrieved October 15, 2026)
Additional sourceModel metadata (retrieved October 17, 2026)
Additional sourceWizardLM-2 official release post · Editorial description reviewed October 2, 2026
Additional sourceOpenRouter: Popularity index (derived), CC BY 4.0
Additional sourceVercel AI Gateway: Popularity index (derived), CC BY 4.0
Additional sourceOllama: cumulative downloads for the popularity index
Additional sourceReplicate: cumulative runs for the popularity index
Additional sourceGoogle Trending Now: limited feed selection for Germany and the US
Additional sourceCreative Commons Attribution 4.0