
DeepSeekLanguage model

DeepSeek V4 Pro 0423
DeepSeek V4 Pro 0423 has no overall index value yet because there are too few independent benchmark results.

PopularityRank 757 of 785

14out of 100same as last month

based on two data groups, mostly search

Summary

DeepSeek V4 Pro 0423 is the catalog entry dated April 23, 2026. DeepSeek dates the public V4 announcement to April 24, so 0423 identifies an initial snapshot rather than a separately confirmed weight release. The date distinguishes it from the later DeepSeek V4 Pro 0813.

On September 14, 2026, DeepSeek routed the deepseek-v4-pro alias to DeepSeek-V4.1-Flash; the 0423 snapshot comes from the original V4-Pro release.

See for yourself: one prompt, one attempt

SVG short test

One SVG task with the same fixed settings for every model, without hidden thinking.

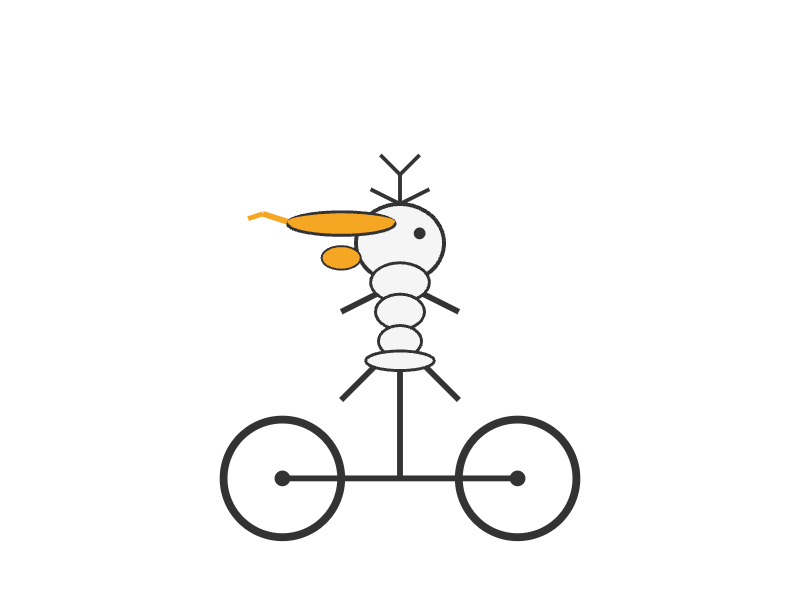
DeepSeek V4 Pro 0423

DeepSeek V4 Pro 0423: SVG short test

Prompt

Return only one standalone SVG of a pelican riding a bicycle. Use viewBox="0 0 800 600", simple shapes, two clearly visible wheels and a recognizable pelican with a long beak. At most 30 SVG elements and 1800 characters. No Markdown, explanations, comments, scripts, animation, CSS or external resources.

Oct 14, 2026 · $0.0018

Test details
Test run
Oct 14, 2026
Provider
streamlake/fp8
API model
deepseek/deepseek-v4-pro
Output
923 tokens
Reasoning
API reports 0 reasoning tokens
Cost of the attempt
$0.0018
Test round
43b8c5c46830
Earlier tests

The response reached the token limit. No complete recording is available.

Pelican on a bicycle

Prompt

Generate an SVG of a pelican riding a bicycle

Oct 5, 2026 · 161 s · $0.0034

Not yet visually reviewed. A successful recording does not confirm correct physics or full compliance with the prompt.

Test details
Run date
Oct 5, 2026
API provider
openrouter
Requested API model
deepseek/deepseek-v4-pro
Reasoning setting
high
Token limit including reasoning
8,192 tokens
Output tokens
8,192 tokens
Cost of the attempt
$0.0034
Response time
160.6 s
API model reported in response
deepseek/deepseek-v4-pro
Pinned endpoint
StreamLake | deepseek/deepseek-v4-pro-20260423
Temperature
Provider default
Test protocol
community-visual-tests-v1
Technical checks
Failed

Earlier attempts (2)

  • Oct 2, 2026API request failedReasoning setting: high
  • Oct 1, 2026API request failedReasoning setting: high
Task origin: Simon Willison

All benchmark results

Every published result with its source, test setup and comparison models.

Show all 12 published benchmark results

Measurements without matching peer values

These measurements have no matching peer values under the same test conditions. Their original values and sources remain available here.

Aider Polyglot (Show measurement, test conditions, and source)
Source value
20.6
Score
20.6
Metric
pass@1
Unit
%
Benchmark version
TrustedRouter replay 2026-06-17; Python Exercism subset
Category
coding
Direction
Higher is better
Sample
34
Source type
independent-evaluator
Evaluator
TrustedRouter Benchmarks
Status
active
Retrieved at
2026-10-16
Methodology
Independent evaluation. Single-model panel result through the TrustedRouter gateway; pass@1 on a 34-task Python Exercism subset. Seven tasks passed and one task had a transport error. The evaluator used real test execution rather than an LLM judge. The public record does not bind an immutable provider revision or disclose all historical decoding settings.
Context
This is one narrow code-repair task suite, not broad model quality. The exact 0423 name is the evaluator's dated attribution; the result artifact identifies only deepseek/deepseek-v4-pro and supplies no provider-immutable revision.
Source TrustedRouter Benchmarks
SimpleQA Verified (Show measurement, test conditions, and source)
Source value
55.1
Score
55.1
Metric
F-score
Unit
%
Benchmark version
TrustedRouter replay 2026-06-17; SimpleQA Verified
Category
knowledge
Direction
Higher is better
Source type
independent-evaluator
Evaluator
TrustedRouter Benchmarks
Status
active
Retrieved at
2026-10-16
Methodology
Independent evaluation. Single-model panel result through the TrustedRouter gateway; closed-book, no tools, and 250-target population. The table also reports Attempted% 91.3 as a neutral diagnostic. GPT-4.1 grades the reported F-score using the published modified Google SimpleQA grader prompt with direct-answer and numeric acceptable-range rules; response budget is 32768 tokens. The replay has nine transport errors and zero empty responses; the scorer excludes transport-error responses, but the public summary does not state the number of evaluated responses.
Context
The 250 items are the target population, not a published actual scored-response count. The evaluated-response count is not published, nine transport errors are excluded from scoring, and the reported F-score uses an LLM grader. The exact 0423 name is the evaluator's dated attribution, not provider-immutable proof.
Source TrustedRouter Benchmarks
SimpleQA Verified correct (Show measurement, test conditions, and source)
Source value
52.7
Score
52.7
Metric
Correct%
Unit
%
Benchmark version
TrustedRouter replay 2026-06-17; SimpleQA Verified
Category
knowledge
Direction
Higher is better
Source type
independent-evaluator
Evaluator
TrustedRouter Benchmarks
Status
active
Retrieved at
2026-10-16
Methodology
Independent evaluation. Single-model panel result through the TrustedRouter gateway. The pinned evaluator table reports Correct% as 52.7% and the neutral Attempted% diagnostic as 91.3% for its 250-target SimpleQA Verified population. The table does not define a per-model scored-response denominator for Correct%; the separate F-score scorer excludes transport errors.
Context
The table does not state the actual scored-response denominator for this column, and nine transport errors are reported separately. The exact 0423 name is the evaluator's dated attribution; the artifact provides no provider-immutable revision.
Source TrustedRouter Benchmarks
SimpleQA Verified accuracy among attempted (Show measurement, test conditions, and source)
Source value
57.7
Score
57.7
Metric
Acc|attempted
Unit
%
Benchmark version
TrustedRouter replay 2026-06-17; SimpleQA Verified
Category
knowledge
Direction
Higher is better
Source type
independent-evaluator
Evaluator
TrustedRouter Benchmarks
Status
active
Retrieved at
2026-10-16
Methodology
Independent evaluation. Single-model panel result through the TrustedRouter gateway. The pinned evaluator table reports Acc|attempted as 57.7% and the neutral Attempted% diagnostic as 91.3%. The target population is 250 items, but the public summary does not publish the exact number of attempted responses used as the accuracy column's denominator.
Context
The exact attempted-response denominator is not published, so its sample size remains unknown. This conditional accuracy column is distinct from the F-score and correct-share columns. The exact 0423 name is the evaluator's dated attribution; the artifact provides no provider-immutable revision.
Source TrustedRouter Benchmarks
IFEval (Show measurement, test conditions, and source)
Source value
36.2
Score
36.2
Metric
mean of prompt-strict, prompt-loose, instruction-strict, and instruction-loose accuracy
Unit
%
Benchmark version
TrustedRouter replay 2026-06-17; 100-prompt subset
Category
instruction-following
Direction
Higher is better
Sample
100
Source type
independent-evaluator
Evaluator
TrustedRouter Benchmarks
Status
active
Retrieved at
2026-10-16
Methodology
Independent evaluation. Zero-shot, no system prompt, 100 prompts; deterministic Google Python verifiers and no LLM judge. The four reported sub-scores are prompt-strict 24.0%, prompt-loose 30.0%, instruction-strict 42.3%, and instruction-loose 48.5%. The scorer counts two transport errors as failures in the 100-prompt denominator.
Context
This is a 100-prompt instruction-following evaluation, not a general quality score. Two transport errors count as failures. The exact 0423 name is the evaluator's dated attribution; the result artifact identifies only deepseek/deepseek-v4-pro and supplies no provider-immutable revision.
Source TrustedRouter Benchmarks
IFEval prompt-strict accuracy (Show measurement, test conditions, and source)
Source value
24
Score
24
Metric
Prompt-strict
Unit
%
Benchmark version
TrustedRouter replay 2026-06-17; 100-prompt subset
Category
instruction-following
Direction
Higher is better
Sample
100
Source type
independent-evaluator
Evaluator
TrustedRouter Benchmarks
Status
active
Retrieved at
2026-10-16
Methodology
Independent evaluation. Prompt-level strict IFEval score on the 100-prompt subset; deterministic Google Python verification and no LLM judge. The scorer counts two transport errors as failures in the prompt denominator.
Context
This is the strict prompt-level IFEval component, not the composite mean or broad model quality. The exact 0423 name is the evaluator's dated attribution, not provider-immutable proof.
Source TrustedRouter Benchmarks
IFEval prompt-loose accuracy (Show measurement, test conditions, and source)
Source value
30
Score
30
Metric
Prompt-loose
Unit
%
Benchmark version
TrustedRouter replay 2026-06-17; 100-prompt subset
Category
instruction-following
Direction
Higher is better
Sample
100
Source type
independent-evaluator
Evaluator
TrustedRouter Benchmarks
Status
active
Retrieved at
2026-10-16
Methodology
Independent evaluation. Prompt-level loose IFEval score on the 100-prompt subset; deterministic Google Python verification and no LLM judge. The scorer counts two transport errors as failures in the prompt denominator.
Context
This is the loose prompt-level IFEval component, not the composite mean or broad model quality. The exact 0423 name is the evaluator's dated attribution, not provider-immutable proof.
Source TrustedRouter Benchmarks
IFEval instruction-strict accuracy (Show measurement, test conditions, and source)
Source value
42.3
Score
42.3
Metric
Inst-strict
Unit
%
Benchmark version
TrustedRouter replay 2026-06-17; 100-prompt subset
Category
instruction-following
Direction
Higher is better
Source type
independent-evaluator
Evaluator
TrustedRouter Benchmarks
Status
active
Retrieved at
2026-10-16
Methodology
Independent evaluation. Instruction-level strict IFEval component generated from the 100-prompt subset; deterministic Google Python verification and no LLM judge. The public summary does not publish the number of individual instructions used as this component's denominator.
Context
This is the strict instruction-level IFEval component. The evaluator's 100 prompts do not establish the denominator of individual instruction constraints, so its sample size remains unknown. The exact 0423 name is the evaluator's dated attribution, not provider-immutable proof.
Source TrustedRouter Benchmarks
IFEval instruction-loose accuracy (Show measurement, test conditions, and source)
Source value
48.5
Score
48.5
Metric
Inst-loose
Unit
%
Benchmark version
TrustedRouter replay 2026-06-17; 100-prompt subset
Category
instruction-following
Direction
Higher is better
Source type
independent-evaluator
Evaluator
TrustedRouter Benchmarks
Status
active
Retrieved at
2026-10-16
Methodology
Independent evaluation. Instruction-level loose IFEval component generated from the 100-prompt subset; deterministic Google Python verification and no LLM judge. The public summary does not publish the number of individual instructions used as this component's denominator.
Context
This is the loose instruction-level IFEval component. The evaluator's 100 prompts do not establish the denominator of individual instruction constraints, so its sample size remains unknown. The exact 0423 name is the evaluator's dated attribution, not provider-immutable proof.
Source TrustedRouter Benchmarks
MMLU-Pro (Show measurement, test conditions, and source)
Source value
83.3
Score
83.3
Metric
accuracy
Unit
%
Benchmark version
TrustedRouter replay 2026-06-19; MMLU-Pro subset
Category
knowledge
Direction
Higher is better
Sample
150
Source type
independent-evaluator
Evaluator
TrustedRouter Benchmarks
Status
active
Retrieved at
2026-10-16
Methodology
Independent evaluation. Archived replay contains 150 MMLU-Pro items; zero-shot chain-of-thought, ten choices, deterministic exact letter matching, no LLM judge. It records 125/150 correct, two no-answer items, and zero transport errors. The evaluator webpage instead labels the row a 200-question subset.
Context
The archived replay and score correspond to N=150; the evaluator webpage says N=200, so the source conflict remains visible. This is one multiple-choice benchmark, not a general model ranking. The exact 0423 name is the evaluator's dated attribution, not provider-immutable proof.
Source TrustedRouter Benchmarks
GSM8K (Show measurement, test conditions, and source)
Source value
100
Score
100
Metric
exact-match accuracy
Unit
%
Benchmark version
TrustedRouter replay 2026-06-17; 30-item subset
Category
reasoning
Direction
Higher is better
Sample
30
Source type
independent-evaluator
Evaluator
TrustedRouter Benchmarks
Status
active
Retrieved at
2026-10-16
Methodology
Independent evaluation. 30-item GSM8K subset. The prompt requests a final answer in #### format; the scorer applies deterministic numeric exact match and no LLM judge. The evaluator describes this small run as a saturation sanity check.
Context
N=30 is small, and the evaluator calls this a saturated sanity check, not a broad quality discriminator. The exact 0423 name is the evaluator's dated attribution; the result artifact identifies only deepseek/deepseek-v4-pro and supplies no provider-immutable revision.
Source TrustedRouter Benchmarks
ObviousBench answer pass³ (Show measurement, test conditions, and source)
Source value
79.9
Score
79.9
Metric
Answer pass³, percentage of item/model/config cells where all three sampled answers are correct
Unit
%
Benchmark version
0.2.0
Direction
Higher is better
Sample
144
Source type
independent-evaluator
Evaluator
ObviousBench
Status
active
Retrieved at
2026-10-21
Methodology
Independent evaluation. ObviousBench v0.2.0, public release dated 2026-08-13; DeepSeek V4 Pro 0423, setting “Reasoning”; 144 private held-out items with three answers per item. The source does not identify the API route, immutable serving revision, or exact reasoning level.
Context
This measures only simple, objectively scored tasks under the pass³ rule, not general model quality. Raw responses and item-level outcomes are absent from the public-local release bundle, whose README labels its status local-prep.
Source ObviousBench

Popularity compared

How often the model is searched for, used and mentioned, compared with every model of its category.

Popularity index

The 100 most popular models of this category, 0 to 100, higher is more popular

20 of 101 models

As of November 2026 · Source: gradually.ai popularity index

Over time

Weekly values from October 18, 2026 to November 7, 2026

DeepSeek V4 Pro 0423Sonar Reasoning Pro 14Seed 2.0 Mini 14Seed 2.0 Pro 14Seed 2.0 Lite 13

Method changes in the timeline, a jump at these points is no market event:

  1. 1November 1, 2026: Value only with search or usage data, 30-day attention

What is gaining popularity right now, across models, vendors, harnesses and AI subscriptions, is collected in All AI trends.

All specifications

Architecture

Parameters
1,600 billion
Source: Parameters
Active parameters
49 billion
Source: Active parameters
Knowledge cutoff
May 2025
Source: Knowledge cutoff

Input and output

Context window
1,000,000 tokens
Source: Context window
Maximum output
384,000 tokens
Source: Maximum output
Inputs
Text
Source: Inputs
Outputs
Text
Source: Outputs
Reasoning
Yes
Source: Reasoning
Tool calling
Yes
Source: Tool calling

Watermarking and provenance

AI watermarking refers to invisible signals embedded in the output. Visible marks and provenance metadata are listed separately. Unknown means there is insufficient evidence for that particular field.

AI watermarking
Unknown
no source
Watermarking technique
Not known
no source

Licence and access

Weights
Open weights
Source: Weights
License
MIT
Source: License

Prices

Not included in any subscription in Germany.

All plans in the AI subscription comparison

Frequently asked questions about DeepSeek V4 Pro 0423

What is the knowledge cutoff of DeepSeek V4 Pro 0423?

May 2025, according to DeepSeek. That is 11 months before release.

Stated by DeepSeek

How large is the context window of DeepSeek V4 Pro 0423?

1 M tokens. That is how much text DeepSeek V4 Pro 0423 reads at once, about 1,500 A4 pages.

Page count as a rule of thumb from Artificial Analysis

Context windowTokens the model reads at once · higher is better
DeepSeek V4 Pro 0423Rank 31 of 1031M
Claude Opus 5.51M
Gemini 4 Carbon1M
Claude Fable 5.11M
Claude Sonnet 5.51M
Muse Wonder Full1M
Claude Opus 51M

Can I run DeepSeek V4 Pro 0423 locally?

Yes, the weights are open. With 1.6T parameters it needs a lot of memory, more a server than a laptop.

Stated by DeepSeek

Open weights
yes
License
MIT
Parameters
1.6T
active per token
49B

Sources and data date

Show all 24 sources

Benchmark sources at a glance

Which independent evaluators tested this model. This is coverage, not a quality ranking.

No active result from the reviewed external evaluators can currently be attributed to this model. Other source evidence remains available below.

Without vendor claims and historical or disputed results; those stay labelled in the single values.

TypeEvidence and data date
Input

Documented modalities. Retrieved October 27, 2026.

Output

Documented modalities. Retrieved October 27, 2026.

Research statusResearch date October 15, 2026. 15 source URLs checked. This documents the inspected sources, not an exhaustive inventory of every publication.
Unresolved

exact-release-source-and-benchmarks

Note

No readable official author page for a DeepSeek-V4-Pro-0423 release was located; direct candidate URL was unavailable. The verified Pro-0813 card is a distinct official release and explicitly supersedes preview, so its scores are not assigned to 0423.

Unresolved

provider-checkpoint-identity

Note

The evaluator's 2026-06-18 page explicitly attributes these rows to DeepSeek V4 Pro 0423 and claims exact-checkpoint scope. The pinned run artifacts themselves identify only deepseek/deepseek-v4-pro, and no provider-immutable revision was found. Treat the name bridge as the evaluator's dated attribution, not provider proof.

Not published

simpleqa-verified-scored-response-count

Note

The public table gives a target population of 250 and an Errors count of nine, while the pinned scorer excludes transport-error responses. It does not publish the actual per-model number of responses included in the F-score, so the scored-response count remains unknown.

Unresolved

mmlu-pro-population-conflict

Note

The evaluator webpage calls this a 200-question subset, but the pinned README and archived replay file report 150 items and 125/150 correct. The recorded sample size uses the inspectable replay population of 150; the conflict is retained.

Additional sourceTrustedRouter Benchmarks (retrieved October 16, 2026)
Additional sourceObviousBench (retrieved October 21, 2026)
Additional sourceModel metadata (retrieved October 15, 2026; October 16, 2026)
Additional sourceModel metadata (retrieved October 16, 2026)123456789101112
Additional sourceDeepSeek V4 announcement · Editorial description reviewed October 2, 2026
Additional sourceDeepSeek V4.1 lifecycle notice · Editorial description reviewed October 2, 2026
Additional sourceOpenRouter: Popularity index (derived), CC BY 4.0
Additional sourceVercel AI Gateway: Popularity index (derived), CC BY 4.0
Additional sourceOllama: cumulative downloads for the popularity index
Additional sourceReplicate: cumulative runs for the popularity index
Additional sourceGoogle Trending Now: limited feed selection for Germany and the US
Additional sourceCreative Commons Attribution 4.0