Compare published benchmark results from matching versions and cohorts, API pricing, and technical specifications. Any documented test setup differences remain visible.
shared result series
29
distinct benchmarks
1
latest retrieval
2026-09-04
Change model selection
Specifications
General specifications
Release date, availability, context window, architecture, and published parameter counts at a glance. Undisclosed details remain marked as unavailable.
Specifications for GPT-5.6 Luna and Mistral Large 3
The table compares official standard API rates per 1M tokens, including published cache pricing. Batch, fast, priority, regional surcharges, tool calls, and cloud platform pricing are excluded.
Key to the marks:better valuebetter, but not conclusivetie
Pricing by provider
Direct developer pricing and provider endpoint tariffs routed through OpenRouter are listed separately. Prices are in USD per 1M tokens. Context-dependent direct tiers plus regional, Flex, Priority, and other OpenRouter tariffs remain individually identifiable.
Provider pricing for GPT-5.6 Luna and Mistral Large 3
Only published results with the same benchmark version, task, metric, and comparison cohort are paired. Different reasoning levels, agents, harnesses, or output limits appear directly in the table.
Capability profile from matched benchmarks
Each axis averages directly matched benchmark families. A value of 100 means the stronger value within this pair, not a universal quality score.
Not enough directly matched categories for a reliable radar
Only 0 of at least 5 categories have comparable, direct model measurements. The benchmark tables below show the available evidence without filling missing axes.
GPT-5.6 LunaMistral Large 3
LMArena Text, Style ControlOverall. Higher is better. Test setup not documented as identical
GPT-5.6 LunaHigher measured value1,452.364
Mistral Large 31,413.556
LMArena Text, Style ControlBusiness, management and finance. Higher is better. Test setup not documented as identical
GPT-5.6 LunaHigher measured value1,461.709
Mistral Large 31,412.721
LMArena Text, Style ControlChinese. Higher is better. Test setup not documented as identical
GPT-5.6 LunaHigher measured value1,474.185
Mistral Large 31,431.759
LMArena Text, Style ControlCoding. Higher is better. Test setup not documented as identical
GPT-5.6 LunaHigher measured value1,497.069
Mistral Large 31,468.587
LMArena Text, Style ControlCreative writing. Higher is better. Test setup not documented as identical
GPT-5.6 LunaHigher measured value1,408.317
Mistral Large 31,375.017
LMArena Text, Style ControlEnglish. Higher is better. Test setup not documented as identical
GPT-5.6 LunaHigher measured value1,465.717
Mistral Large 31,426.818
LMArena Text, Style ControlEntertainment, sports and media. Higher is better. Test setup not documented as identical
GPT-5.6 LunaHigher measured value1,421.389
Mistral Large 31,373.228
LMArena Text, Style ControlExcluding ties. Higher is better. Test setup not documented as identical
GPT-5.6 LunaHigher measured value1,454.697
Mistral Large 31,400.876
LMArena Text, Style ControlExpert prompts. Higher is better. Test setup not documented as identical
GPT-5.6 LunaHigher measured value1,487.391
Mistral Large 31,423.349
LMArena Text, Style ControlFrench. Higher is better. Test setup not documented as identical
GPT-5.6 LunaHigher measured value1,476.247
Mistral Large 31,434.923
LMArena Text, Style ControlGerman. Higher is better. Test setup not documented as identical
GPT-5.6 LunaHigher measured value1,486.451
Mistral Large 31,404.512
LMArena Text, Style ControlHard prompts. Higher is better. Test setup not documented as identical
GPT-5.6 LunaHigher measured value1,472.892
Mistral Large 31,431.026
Key to the marks:better valuebetter, but not conclusivetie
Benchmark scores for GPT-5.6 Luna and Mistral Large 3
Benchmark and task
GPT-5.6 Luna
Mistral Large 3
Source
LMArena Text, Style ControlOverallTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 24,433 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 65,336 anonymous pairwise votes.
Higher measured value1,452.364
95% confidence interval: ±5.03The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,413.556
95% confidence interval: ±3.08The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlBusiness, management and financeTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 4,691 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 12,392 anonymous pairwise votes.
Higher measured value1,461.709
95% confidence interval: ±9.371The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,412.721
95% confidence interval: ±5.917The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 1,691 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 4,483 anonymous pairwise votes.
Higher measured value1,474.185
95% confidence interval: ±15.484The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,431.759
95% confidence interval: ±9.282The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 6,843 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 16,301 anonymous pairwise votes.
Higher measured value1,497.069
95% confidence interval: ±7.965The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,468.587
95% confidence interval: ±5.241The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 4,866 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 10,954 anonymous pairwise votes.
Higher measured value1,408.317
95% confidence interval: ±9.528The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,375.017
95% confidence interval: ±6.318The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 10,147 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 27,473 anonymous pairwise votes.
Higher measured value1,465.717
95% confidence interval: ±6.77The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,426.818
95% confidence interval: ±4.282The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlEntertainment, sports and mediaTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 6,255 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 13,723 anonymous pairwise votes.
Higher measured value1,421.389
95% confidence interval: ±8.549The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,373.228
95% confidence interval: ±5.71The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 18,424 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 47,430 anonymous pairwise votes.
Higher measured value1,454.697
95% confidence interval: ±6.557The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,400.876
95% confidence interval: ±4.294The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 2,703 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 5,705 anonymous pairwise votes.
Higher measured value1,487.391
95% confidence interval: ±11.906The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,423.349
95% confidence interval: ±8.346The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 835 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 1,858 anonymous pairwise votes.
Higher measured value1,476.247
95% confidence interval: ±21.942The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,434.923
95% confidence interval: ±15.523The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 424 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 1,080 anonymous pairwise votes.
Higher measured value1,486.451
95% confidence interval: ±29.435The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,404.512
95% confidence interval: ±19.03The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 16,256 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 39,237 anonymous pairwise votes.
Higher measured value1,472.892
95% confidence interval: ±5.879The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,431.026
95% confidence interval: ±3.848The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 6,739 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 16,526 anonymous pairwise votes.
Higher measured value1,482.99
95% confidence interval: ±7.984The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,438.338
95% confidence interval: ±5.247The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 8,687 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 20,253 anonymous pairwise votes.
Higher measured value1,442.672
95% confidence interval: ±7.285The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,399.916
95% confidence interval: ±4.811The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 339 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 661 anonymous pairwise votes.
Higher measured value1,448.32
95% confidence interval: ±34.335The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,382.813
95% confidence interval: ±24.568The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 481 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 1,118 anonymous pairwise votes.
Higher measured value1,398.575
95% confidence interval: ±27.208The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,355.204
95% confidence interval: ±19.178The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlLegal and governmentTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 2,064 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 4,880 anonymous pairwise votes.
Higher measured value1,462.472
95% confidence interval: ±13.711The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,420.347
95% confidence interval: ±8.946The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlLife, physical and social scienceTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 3,971 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 10,595 anonymous pairwise votes.
Higher measured value1,455.82
95% confidence interval: ±9.876The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,427.433
95% confidence interval: ±6.173The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 11,564 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 23,193 anonymous pairwise votes.
Higher measured value1,451.975
95% confidence interval: ±6.845The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,416.784
95% confidence interval: ±4.746The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 1,078 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 3,755 anonymous pairwise votes.
Higher measured value1,477.348
95% confidence interval: ±17.909The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,402.864
95% confidence interval: ±9.902The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 1,258 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 3,175 anonymous pairwise votes.
Higher measured value1,477.124
95% confidence interval: ±17.262The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,417.813
95% confidence interval: ±10.98The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlMedicine and healthcareTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 1,853 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 4,505 anonymous pairwise votes.
Higher measured value1,436.426
95% confidence interval: ±14.729The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,431.127
95% confidence interval: ±9.388The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 4,094 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 11,201 anonymous pairwise votes.
Higher measured value1,458.732
95% confidence interval: ±9.928The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,420.712
95% confidence interval: ±6.145The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 14,283 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 37,859 anonymous pairwise votes.
Higher measured value1,435.463
95% confidence interval: ±6.095The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,397.941
95% confidence interval: ±3.805The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 382 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 1,582 anonymous pairwise votes.
Higher measured value1,429.959
95% confidence interval: ±29.891The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,415.726
95% confidence interval: ±15.021The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 2,470 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 7,429 anonymous pairwise votes.
Higher measured value1,445.524
95% confidence interval: ±12.278The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,409.803
95% confidence interval: ±7.118The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlSoftware and IT servicesTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 9,767 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 24,350 anonymous pairwise votes.
Higher measured value1,491.879
95% confidence interval: ±6.977The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,456.163
95% confidence interval: ±4.498The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 666 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 1,998 anonymous pairwise votes.
Higher measured value1,462.579
95% confidence interval: ±24.039The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,406.852
95% confidence interval: ±14.343The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
LMArena Text, Style ControlWriting, literature and languageTest details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Luna: Snapshot: gpt-5.6-luna-xhigh, Reasoning: xhigh, Harness: Arena text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena text, style controlGPT-5.6 Luna: Style-controlled Arena rating from 6,482 anonymous pairwise votes.Mistral Large 3: Style-controlled Arena rating from 15,693 anonymous pairwise votes.
Higher measured value1,434.128
95% confidence interval: ±8.276The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
1,390.534
95% confidence interval: ±5.355The Arena score measures human preference rather than a fixed capability test. The confidence interval and model configuration are part of the result.
Key to the marks:better valuebetter, but not conclusivetie
Our model tests
Community tests you can inspect
Compare how the models respond to the same prompt. Each test shows the first attempt, with no subsequent fixes to the generated code. These results do not contribute to an overall score.
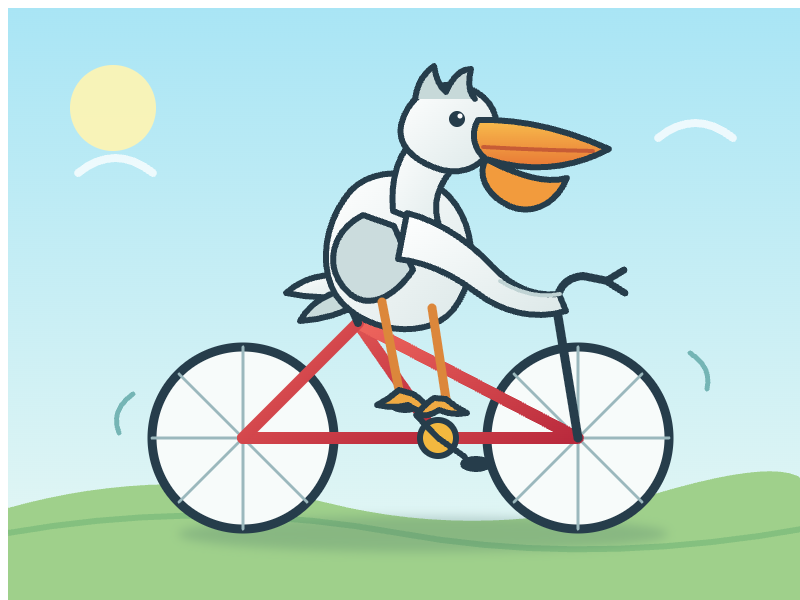
Pelican on a bicycle
A community classic for free-form SVG drawing.
GPT-5.6 Luna
A community classic for free-form SVG drawing.First attempt
Run date
7 Sept 2026
API provider
openrouter
Requested API model
openai/gpt-5.6-luna
API model reported in response
openai/gpt-5.6-luna
Pinned endpoint
OpenAI | openai/gpt-5.6-luna-20260709
Reasoning setting
high
Temperature
Provider default
Token limit including reasoning
8,192 tokens
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating
Response time
49.9 s
Visually reviewed. This individual test does not establish overall model quality.
Mistral Large 3
API access was unavailable for this run. The model was not evaluated.
First attempt
Run date
7 Sept 2026
API provider
openrouter
Requested API model
mistralai/mistral-large-2512
Pinned endpoint
Mistral | mistralai/mistral-large-2512
Reasoning setting
none
Temperature
Provider default
Token limit including reasoning
8,192 tokens
Test protocol
community-visual-tests-v1
Technical checks
Not run
Not yet visually reviewed. A successful recording does not confirm correct physics or full compliance with the prompt.
Your workload, budget, and required context length matter most. A coding benchmark says little about visual understanding or agent performance.
The standard price table uses direct developer rates. The provider comparison labels OpenRouter endpoints, regions, and special tariffs separately.
Every result links to its measurement source and retrieval date. Labels distinguish vendor reports, official benchmark leaderboards, and independent evaluations. Disputed or archived results are excluded.
More matchups
Related LLM comparisons
Compare GPT-5.6 Luna and Mistral Large 3 with other leading models using the same data and benchmark logic.