Gemini 3.8 Flash
Unavailable in this round
Head-to-head comparison
Compare published benchmark results from matching versions and cohorts, API pricing, and technical specifications. Any documented test setup differences remain visible.
Specifications
Release date, availability, context window, architecture, and published parameter counts at a glance. Undisclosed details remain marked as unavailable.
| Attribute | Gemini 3.8 Flash | Gemini 3.5 Flash-Lite |
|---|---|---|
| Provider | ||
| Released | Sep 2, 2026 | Jul 21, 2026 |
| Availability | Active | Active |
| Model type | Proprietary | Proprietary |
| Parameters | Not published | Not published |
| Architecture | Not published | Not published |
| Context window | 1,048,576 tokens | 1,048,576 tokens |
| Knowledge cutoff | March 2026 | Not published |
| Technical sources | Model, Knowledge cutoff | Model |
Pricing
The table compares official standard API rates per 1M tokens, including published cache pricing. Batch, fast, priority, regional surcharges, tool calls, and cloud platform pricing are excluded.
| Price type | Gemini 3.8 Flash | Gemini 3.5 Flash-Lite |
|---|---|---|
| API input | $0.75 | $0.3 |
| API output | $3.75 | $2.5 |
| Cache read | $0.075 | $0.03 |
| Cache write (5 min.) | Not listed | Not listed |
| Cache write (1 hr.) | Not listed | Not listed |
| Price verified | 09/22/2026 Source | 09/22/2026 Source |
Key to the marks:better valuebetter, but not conclusivetie
Direct developer pricing and provider endpoint tariffs routed through OpenRouter are listed separately. Prices are in USD per 1M tokens. Context-dependent direct tiers plus regional, Flex, Priority, and other OpenRouter tariffs remain individually identifiable.
| Model | Provider | Purchase route and tariff | Input per 1M tokens | Output per 1M tokens | Source |
|---|---|---|---|---|---|
| Gemini 3.8 Flash | Direct from developerStandard API | $0.75 | $3.75 | Source09/22/2026 | |
| Via OpenRoutergoogle-vertex/us | $0.825 | $4.125 | Source10/17/2026 | ||
| Google AI Studio | Via OpenRoutergoogle-ai-studio | $0.75 | $3.75 | Source10/17/2026 | |
| Google AI Studio | Via OpenRoutergoogle-ai-studio/flex | Lowest listed price: $0.375 | Lowest listed price: $1.875 | Source10/17/2026 | |
| Google AI Studio | Via OpenRoutergoogle-ai-studio/priority | $1.35 | $6.75 | Source10/17/2026 | |
| Gemini 3.5 Flash-Lite | Direct from developerStandard API | $0.3 | $2.5 | Source09/22/2026 | |
| Via OpenRoutergoogle-vertex/eu | $0.33 | $2.75 | Source10/17/2026 | ||
| Via OpenRoutergoogle-vertex/global | $0.3 | $2.5 | Source10/17/2026 | ||
| Via OpenRoutergoogle-vertex/global/priority | $0.54 | $4.5 | Source10/17/2026 | ||
| Via OpenRoutergoogle-vertex/us | $0.33 | $2.75 | Source10/17/2026 | ||
| Google AI Studio | Via OpenRoutergoogle-ai-studio | $0.3 | $2.5 | Source10/17/2026 | |
| Google AI Studio | Via OpenRoutergoogle-ai-studio/flex | Lowest listed price: $0.15 | Lowest listed price: $1.25 | Source10/17/2026 | |
| Google AI Studio | Via OpenRoutergoogle-ai-studio/priority | $0.54 | $4.5 | Source10/17/2026 |
Performance
Only published results with the same benchmark version, task, metric, and comparison cohort are paired. Different reasoning levels, agents, harnesses, or output limits appear directly in the table.
Each axis averages directly matched benchmark families. A value of 100 means the stronger value within this pair, not a universal quality score.
165 matched rows from 20 benchmark families were considered. The radar shows 8 of 10 comparable categories.
Key to the marks:better valuebetter, but not conclusivetie
| Benchmark and task | Gemini 3.8 Flash | Gemini 3.5 Flash-Lite | Source |
|---|---|---|---|
Code MigrationOverallTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner36.546 % | 6.148 % | Vals AISource detailsData as of: 10/12/2026 |
CyberBench v1.1OverallTest detailsNo documented difference in the test setupVersion: 1.1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | 43.75 % | Winner59.107 % | Vals AISource detailsData as of: 10/12/2026 |
EMBOverallTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner72.196 % | 43.231 % | Vals AISource detailsData as of: 10/12/2026 |
Finance Agent (v2)OverallTest detailsNo documented difference in the test setupVersion: 2Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner61.435 % | 47.442 % | Vals AISource detailsData as of: 10/12/2026 |
GPQA DiamondOverallTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner94.444 % | 83.838 % | Vals AISource detailsData as of: 09/01/2026 |
Harvey's Legal Agent BenchmarkOverall · Task fully resolvedTest detailsNo documented difference in the test setupVersion: 1Metric: task resolution rateScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner10 % | 0 % | Vals AISource detailsData as of: 10/12/2026 |
Legal Research BenchOverall · All-passTest detailsNo documented difference in the test setupVersion: 1Metric: all-pass rateScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner38.942 % | 13.942 % | Vals AISource detailsData as of: 10/12/2026 |
LegalBenchOverallTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner86.993 % | 84.073 % | Vals AISource detailsData as of: 10/13/2026 |
LiveCodeBench v6OverallTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner89.484 % | 79.014 % | Vals AISource detailsData as of: 09/01/2026 |
LMArena Code Arena WebDevOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterGemini 3.8 Flash: Snapshot: gemini-3.8-flash-high, Reasoning: high, Harness: Arena Code Arena WebDev Gemini 3.5 Flash-Lite: Snapshot: gemini-3.5-flash-lite, Harness: Arena Code Arena WebDevGemini 3.8 Flash: Arena rating from 10,077 published pairwise votes.Gemini 3.5 Flash-Lite: Arena rating from 242 published pairwise votes. | Higher measured value1,584.77 95% confidence interval: ±7.59The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,440.401 95% confidence interval: ±40.572The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGemini 3.8 Flash: Snapshot: gemini-3.8-flash-high, Reasoning: high, Harness: Arena Text, style control Gemini 3.5 Flash-Lite: Snapshot: gemini-3.5-flash-lite, Harness: Arena Text, style controlGemini 3.8 Flash: Arena rating from 35,670 published pairwise votes.Gemini 3.5 Flash-Lite: Arena rating from 35,845 published pairwise votes. | Higher measured value1,496.319 95% confidence interval: ±4.654The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,454.971 95% confidence interval: ±4.474The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Vision, Style ControlOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGemini 3.8 Flash: Snapshot: gemini-3.8-flash-high, Reasoning: high, Harness: Arena Vision, style control Gemini 3.5 Flash-Lite: Snapshot: gemini-3.5-flash-lite, Harness: Arena Vision, style controlGemini 3.8 Flash: Arena rating from 3,792 published pairwise votes.Gemini 3.5 Flash-Lite: Arena rating from 8,381 published pairwise votes. | Higher measured value1,289.129 95% confidence interval: ±10.62The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,265.999 95% confidence interval: ±8.109The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/09/2026 |
MedCodeOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGemini 3.8 Flash: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens Gemini 3.5 Flash-Lite: Reasoning: high, Temperature: 1, Output limit: 30,000 tokens | Higher measured value48.135 % | 43.489 % | Vals AISource detailsData as of: 10/13/2026 |
MedScribeOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGemini 3.8 Flash: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens Gemini 3.5 Flash-Lite: Reasoning: high, Temperature: 1, Output limit: 30,000 tokens | Higher measured value84.496 % | 70.886 % | Vals AISource detailsData as of: 10/13/2026 |
MMLU-ProOverallTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner90.221 % | 85.836 % | Vals AISource detailsData as of: 09/01/2026 |
MMMU-ProOverallTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner89.075 % | 83.584 % | Vals AISource detailsData as of: 09/01/2026 |
MortgageTaxOverallTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | 65.342 % | Winner68.68 % | Vals AISource detailsData as of: 09/01/2026 |
ProgramBenchOverallTest detailsNo documented difference in the test setupVersion: 1Metric: fully resolved rateScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner1 % | 0 % | Vals AISource detailsData as of: 10/12/2026 |
Public Benefits Bench v1.1OverallTest detailsNo documented difference in the test setupVersion: 1.1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner65.291 % | 51.827 % | Vals AISource detailsData as of: 10/12/2026 |
SAGEOverallTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 30,000 tokens | 35.064 % | Winner47.303 % | Vals AISource detailsData as of: 10/08/2026 |
SWE-bench VerifiedOverallTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner80 % | 75 % | Vals AISource detailsData as of: 09/01/2026 |
Tax Agent BenchOverallTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner32.124 % | 7.254 % | Vals AISource detailsData as of: 10/12/2026 |
TaxEval v2OverallTest detailsNo documented difference in the test setupVersion: 2Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner74.448 % | 72.608 % | Vals AISource detailsData as of: 09/01/2026 |
Terminal-Bench 2.1OverallTest detailsNo documented difference in the test setupVersion: 2.1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner81.273 % | 50.187 % | Vals AISource detailsData as of: 09/28/2026 |
Vibe Code Bench v1.1OverallTest detailsNo documented difference in the test setupVersion: 1.1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Harness: OpenHands, Temperature: 1, Output limit: 65,536 tokens | Winner78.651 % | 37.161 % | Vals AISource detailsData as of: 10/12/2026 |
Code MigrationCLITest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner25.871 % | 5.875 % | Vals AISource detailsData as of: 10/12/2026 |
CyberBench v1.1PatchTest detailsNo documented difference in the test setupVersion: 1.1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner87.5 % | 73.214 % | Vals AISource detailsData as of: 10/12/2026 |
EMBCompsTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner76.435 % | 46.417 % | Vals AISource detailsData as of: 10/12/2026 |
Finance Agent (v2)AdjustmentsTest detailsNo documented difference in the test setupVersion: 2Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner54.828 % | 41.741 % | Vals AISource detailsData as of: 10/12/2026 |
GPQA DiamondFew-Shot CoTTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner94.949 % | 81.818 % | Vals AISource detailsData as of: 09/01/2026 |
Harvey's Legal Agent BenchmarkAntitrust Competition · Criteria passedTest detailsNo documented difference in the test setupVersion: 1Metric: criteria pass rateScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner87.681 % | 76.449 % | Vals AISource detailsData as of: 10/12/2026 |
Legal Research BenchAdministrative / Regulatory · All-passTest detailsNo documented difference in the test setupVersion: 1Metric: all-pass rateScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner46.97 % | 19.697 % | Vals AISource detailsData as of: 10/12/2026 |
LegalBenchConclusion TasksTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner90.691 % | 88.404 % | Vals AISource detailsData as of: 10/13/2026 |
LiveCodeBench v6EasyTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner99.068 % | 98.758 % | Vals AISource detailsData as of: 09/01/2026 |
LMArena Code Arena WebDevImage to webdevTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterGemini 3.8 Flash: Snapshot: gemini-3.8-flash-high, Reasoning: high, Harness: Arena Code Arena WebDev Gemini 3.5 Flash-Lite: Snapshot: gemini-3.5-flash-lite, Harness: Arena Code Arena WebDevGemini 3.8 Flash: Arena rating from 2,015 published pairwise votes.Gemini 3.5 Flash-Lite: Arena rating from 1,600 published pairwise votes. | Higher measured value1,593.067 95% confidence interval: ±13.862The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,447.43 95% confidence interval: ±15.334The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/09/2026 |
LMArena Text, Style ControlBusiness, management and financeTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGemini 3.8 Flash: Snapshot: gemini-3.8-flash-high, Reasoning: high, Harness: Arena Text, style control Gemini 3.5 Flash-Lite: Snapshot: gemini-3.5-flash-lite, Harness: Arena Text, style controlGemini 3.8 Flash: Arena rating from 6,520 published pairwise votes.Gemini 3.5 Flash-Lite: Arena rating from 6,603 published pairwise votes. | Higher measured value1,479.887 95% confidence interval: ±8.136The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,452.709 95% confidence interval: ±7.982The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Vision, Style ControlChineseTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGemini 3.8 Flash: Snapshot: gemini-3.8-flash-high, Reasoning: high, Harness: Arena Vision, style control Gemini 3.5 Flash-Lite: Snapshot: gemini-3.5-flash-lite, Harness: Arena Vision, style controlGemini 3.8 Flash: Arena rating from 182 published pairwise votes.Gemini 3.5 Flash-Lite: Arena rating from 471 published pairwise votes. | Higher measured value1,379.729 95% confidence interval: ±43.521The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,301.978 95% confidence interval: ±28.157The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/09/2026 |
MMLU-ProBiologyTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner94.979 % | 91.911 % | Vals AISource detailsData as of: 09/01/2026 |
MortgageTaxNumerical ExtractionTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | 70.588 % | Winner75.835 % | Vals AISource detailsData as of: 09/01/2026 |
ProgramBenchAlmost ResolvedTest detailsNo documented difference in the test setupVersion: 1Metric: almost-resolved rateScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner14 % | 0 % | Vals AISource detailsData as of: 10/12/2026 |
SAGEAutomataTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 30,000 tokens | Winner33.334 % | 28.968 % | Vals AISource detailsData as of: 10/08/2026 |
SWE-bench Verified<15 min fixTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner89.691 % | 85.567 % | Vals AISource detailsData as of: 09/01/2026 |
Tax Agent BenchControversy & Precedence AnalysisTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner6.667 % | 3.333 % | Vals AISource detailsData as of: 10/12/2026 |
TaxEval v2CorrectnessTest detailsNo documented difference in the test setupVersion: 2Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner62.469 % | 61.733 % | Vals AISource detailsData as of: 09/01/2026 |
Terminal-Bench 2.1EasyTest detailsNo documented difference in the test setupVersion: 2.1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner100 % | 66.667 % | Vals AISource detailsData as of: 09/28/2026 |
Code MigrationCOBOLTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner68.571 % | 6.964 % | Vals AISource detailsData as of: 10/12/2026 |
CyberBench v1.1PoCTest detailsNo documented difference in the test setupVersion: 1.1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | 0 % | Winner45 % | Vals AISource detailsData as of: 10/12/2026 |
EMBDataroomTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner86.218 % | 57.687 % | Vals AISource detailsData as of: 10/12/2026 |
Finance Agent (v2)All-PassTest detailsNo documented difference in the test setupVersion: 2Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner49.694 % | 35.265 % | Vals AISource detailsData as of: 10/12/2026 |
GPQA DiamondZero-Shot CoTTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner93.939 % | 85.859 % | Vals AISource detailsData as of: 09/01/2026 |
Harvey's Legal Agent BenchmarkAntitrust Competition · Task fully resolvedTest detailsNo documented difference in the test setupVersion: 1Metric: task resolution rateScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Tie0 % | Tie0 % | Vals AISource detailsData as of: 10/12/2026 |
Legal Research BenchAdministrative / Regulatory · Weighted partial creditTest detailsNo documented difference in the test setupVersion: 1Metric: weighted partial-credit scoreScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner87.613 % | 71.96 % | Vals AISource detailsData as of: 10/12/2026 |
LegalBenchInterpretation TasksTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner84.589 % | 80.332 % | Vals AISource detailsData as of: 10/13/2026 |
LiveCodeBench v6HardTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner78 % | 53.429 % | Vals AISource detailsData as of: 09/01/2026 |
LMArena Code Arena WebDevWebdevTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterGemini 3.8 Flash: Snapshot: gemini-3.8-flash-high, Reasoning: high, Harness: Arena Code Arena WebDev Gemini 3.5 Flash-Lite: Snapshot: gemini-3.5-flash-lite, Harness: Arena Code Arena WebDevGemini 3.8 Flash: Arena rating from 10,077 published pairwise votes.Gemini 3.5 Flash-Lite: Arena rating from 242 published pairwise votes. | Higher measured value1,584.77 95% confidence interval: ±7.59The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,440.401 95% confidence interval: ±40.572The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlChineseTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGemini 3.8 Flash: Snapshot: gemini-3.8-flash-high, Reasoning: high, Harness: Arena Text, style control Gemini 3.5 Flash-Lite: Snapshot: gemini-3.5-flash-lite, Harness: Arena Text, style controlGemini 3.8 Flash: Arena rating from 2,903 published pairwise votes.Gemini 3.5 Flash-Lite: Arena rating from 2,746 published pairwise votes. | Higher measured value1,532.833 95% confidence interval: ±11.757The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,483.866 95% confidence interval: ±12.01The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Vision, Style ControlCreative writing visionTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGemini 3.8 Flash: Snapshot: gemini-3.8-flash-high, Reasoning: high, Harness: Arena Vision, style control Gemini 3.5 Flash-Lite: Snapshot: gemini-3.5-flash-lite, Harness: Arena Vision, style controlGemini 3.8 Flash: Arena rating from 363 published pairwise votes.Gemini 3.5 Flash-Lite: Arena rating from 787 published pairwise votes. | Higher measured value1,263.378 95% confidence interval: ±32.508The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,256.499 95% confidence interval: ±22.214The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/09/2026 |
MMLU-ProBusinessTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner93.79 % | 90.621 % | Vals AISource detailsData as of: 09/01/2026 |
MortgageTaxSemantic ExtractionTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | 60.095 % | Winner61.526 % | Vals AISource detailsData as of: 09/01/2026 |
ProgramBenchFully ResolvedTest detailsNo documented difference in the test setupVersion: 1Metric: fully resolved rateScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner1 % | 0 % | Vals AISource detailsData as of: 10/12/2026 |
SAGECalculusTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 30,000 tokens | Winner79.63 % | 60.494 % | Vals AISource detailsData as of: 10/08/2026 |
SWE-bench Verified>4 hoursTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Tie33.333 % | Tie33.333 % | Vals AISource detailsData as of: 09/01/2026 |
Tax Agent BenchControversy & Precedence AnalysisTest detailsNo documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner59.001 % | 34.598 % | Vals AISource detailsData as of: 10/12/2026 |
TaxEval v2Stepwise ReasoningTest detailsNo documented difference in the test setupVersion: 2Metric: accuracyScoring: Higher is betterSettings: Reasoning: high, Temperature: 1, Output limit: 65,536 tokens | Winner86.427 % | 83.483 % | Vals AISource detailsData as of: 09/01/2026 |
Key to the marks:better valuebetter, but not conclusivetie | |||
Our model tests
One SVG prompt and fixed output settings. Captures are shown only with 0 reported reasoning tokens or documented lack of reasoning controls. Identical test conditions do not make the models' internal compute identical.
Shared test round: 4ae5d8eeb9a9
Unavailable in this round
Unavailable in this round
A community classic for free-form SVG drawing.
Gemini 3.8 Flash
The response reached the token limit. No complete recording is available.
Reasoning (requested): high
Not yet visually reviewed. A successful recording does not confirm correct physics or full compliance with the prompt.
Gemini 3.5 Flash-Lite
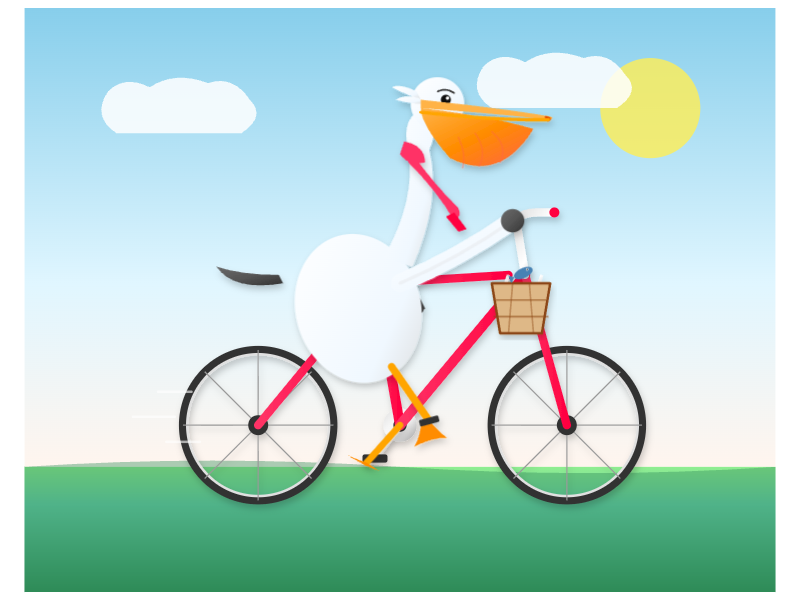
Reasoning (requested): high
Visually reviewed. This individual test does not establish overall model quality.
Generate an SVG of a pelican riding a bicycle
Token limit including reasoning: 8,192 tokens
Task origin (Simon Willison)How to read this comparison
Your workload, budget, and required context length matter most. A coding benchmark says little about visual understanding or agent performance.
The standard price table uses direct developer rates. The provider comparison labels OpenRouter endpoints, regions, and special tariffs separately.
Every result links to its measurement source and retrieval date. Labels distinguish vendor reports, official benchmark leaderboards, and independent evaluations. Disputed or archived results are excluded.
More matchups
Compare Gemini 3.8 Flash and Gemini 3.5 Flash-Lite with other leading models using the same data and benchmark logic.