
XiaomiLanguage modelActive

MiMo V2.6 Pro UltraSpeed
MiMo V2.6 Pro UltraSpeed has no overall index value yet because there are too few independent benchmark results.

Intelligencenot ranked yet

n/aOverall indexhigher is better

Speednot measured

n/ano measurement yet

PriceRank 79 of 95

Input $4.35 · Output $8.70

$5.44per 1M tokenslower is better

Contextn/a

n/atokens at once

PopularityRank 673 of 876

0out of 100same as last month

Summary

It is expensive: $5.44 per 1M tokens (input and output blended); a typical model costs $1.56.

MiMo V2.6 Pro UltraSpeed is Xiaomi’s accelerated API and desktop mode for MiMo V2.6 Pro. Xiaomi refers to the regular Pro checkpoint for the released weights. The name describes lower-latency serving within the V2.6 family.

Xiaomi reports acceleration of up to 20 times for UltraSpeed. That is a vendor figure and depends on the platform and workflow.

See for yourself: one prompt, one attempt

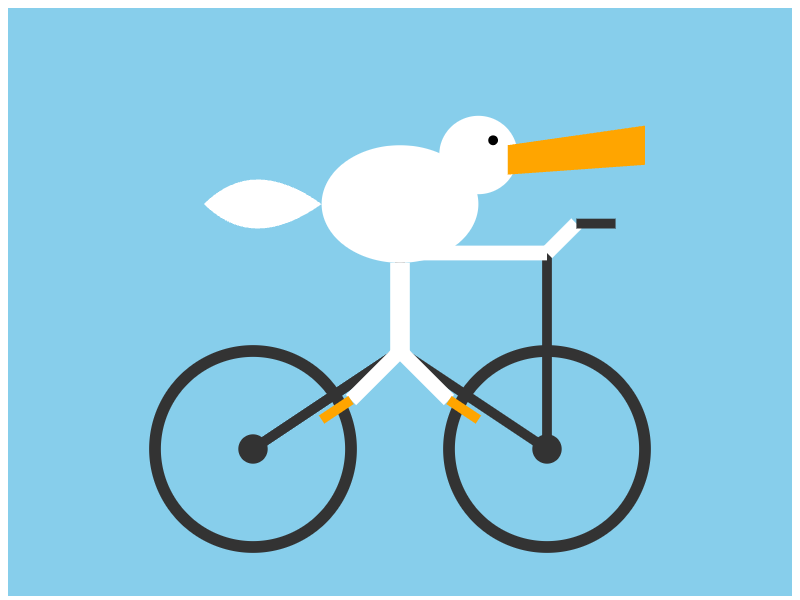
SVG short test

One SVG task with the same fixed settings for every model, without hidden thinking.

MiMo V2.6 Pro UltraSpeed

MiMo V2.6 Pro UltraSpeed: SVG short test

Prompt

Return only one standalone SVG of a pelican riding a bicycle. Use viewBox="0 0 800 600", simple shapes, two clearly visible wheels and a recognizable pelican with a long beak. At most 30 SVG elements and 1800 characters. No Markdown, explanations, comments, scripts, animation, CSS or external resources.

Oct 14, 2026 · $0.0087

Test details
Test run
Oct 14, 2026
Provider
xiaomi/fp8
API model
xiaomi/mimo-v2.6-pro-ultraspeed
Output
953 tokens
Reasoning
API reports 0 reasoning tokens
Cost of the attempt
$0.0087
Test round
43b8c5c46830
Earlier tests

The response reached the token limit. No complete recording is available.

Pelican on a bicycle

Prompt

Generate an SVG of a pelican riding a bicycle

Oct 6, 2026 · 16 s · $0.07

Not yet visually reviewed. A successful recording does not confirm correct physics or full compliance with the prompt.

Test details
Run date
Oct 6, 2026
API provider
openrouter
Requested API model
xiaomi/mimo-v2.6-pro-ultraspeed
Reasoning setting
high
Token limit including reasoning
8,192 tokens
Output tokens
8,192 tokens
Cost of the attempt
$0.0713
Response time
15.9 s
API model reported in response
xiaomi/mimo-v2.6-pro-ultraspeed
Pinned endpoint
Xiaomi | xiaomi/mimo-v2.6-pro-ultraspeed-20260921
Temperature
Provider default
Test protocol
community-visual-tests-v1
Technical checks
Failed

Earlier attempts (2)

  • Oct 2, 2026API request failedReasoning setting: high
  • Oct 1, 2026API request failedReasoning setting: high
Task origin: Simon Willison

All benchmark results

Every published result with its source, test setup and comparison models.

Show all 29 published benchmark results

Page 1 of 3

Measurements without matching peer values

These measurements have no matching peer values under the same test conditions. Their original values and sources remain available here.

DataLLM Lab Python function suite hidden-assert tasks passed (Show measurement, test conditions, and source)
Source value
9
Score
9
Metric
tasks passed
Unit
count
Benchmark version
DataLLM Lab nine-task Python function suite, run 2026-10-02
Category
coding
Direction
Higher is better
Sample
9
Source type
independent-evaluator
Evaluator
DataLLM Lab executed API benchmark
Status
active
Retrieved at
2026-10-16
Methodology
Independent evaluation. Exact endpoint xiaomi/mimo-v2.6-pro-ultraspeed through OpenRouter. Nine self-contained Python function tasks; generated code executed against hidden asserts in isolated python3 -I with a 12-second timeout. Temperature 0, max_tokens 4000, one scored attempt per task. All nine passed.
Context
A tiny, single-attempt micro-suite at ceiling performance. It does not distinguish model quality, measure multimodal or agentic work, or support generalized coding comparisons.
Source DataLLM Lab executed API benchmark
DataLLM Lab Python function suite mean per-call latency (Show measurement, test conditions, and source)
Source value
2.5
Score
2.5
Metric
arithmetic mean latency per call
Unit
seconds
Benchmark version
DataLLM Lab nine-task Python function suite, run 2026-10-02
Category
coding
Direction
Lower is better
Sample
9
Source type
independent-evaluator
Evaluator
DataLLM Lab executed API benchmark
Status
active
Retrieved at
2026-10-16
Methodology
Independent evaluation. Exact endpoint xiaomi/mimo-v2.6-pro-ultraspeed through OpenRouter. Nine calls in the same nine-task Python function suite; reported mean call latency 2.5 seconds. This is wall-clock latency, not token throughput.
Context
Single sweep and only nine calls; the value is not a stable service-level or general throughput estimate.
Source DataLLM Lab executed API benchmark
ToneBench Writing Score (Show measurement, test conditions, and source)
Source value
80.6
Score
80.6
Metric
composite score out of 100
Unit
points
Benchmark version
ToneBench October 2026 board, generated 2026-10-13T20:08:00Z
Category
English long-form writing
Direction
Higher is better
Sample
50
Source type
independent-evaluator
Evaluator
Towards AI ToneBench
Status
superseded
Retrieved at
2026-10-17
Methodology
Independent evaluation. Via OpenRouter, exact route xiaomi/mimo-v2.6-pro-ultraspeed; provider-default sampling, the provider applies thinking on; five independent drafts for each of ten English script briefs (50 drafts), run date 2026-10-08; four blind judges; closed-book with no tools.
Context
Specialized English long-form YouTube script writing in one creator's voice, not a general capability measure. Four blind judges score drafts; Length Adherence is computed and half of Slop Score is computed. The exact rubric is private. Published ± values for metrics are draft-to-draft standard deviations, not confidence intervals.
Source Towards AI ToneBench
ToneBench Writing Elo (Show measurement, test conditions, and source)
Source value
1990
Score
1990
Metric
board-relative pairwise writing rating
Unit
elo
Benchmark version
ToneBench October 2026 board, generated 2026-10-13T20:08:00Z
Category
English long-form writing
Direction
Higher is better
Lower confidence bound
1947
Upper confidence bound
2037
Source type
independent-evaluator
Evaluator
Towards AI ToneBench
Status
superseded
Retrieved at
2026-10-17
Methodology
Independent evaluation. Via OpenRouter, exact route xiaomi/mimo-v2.6-pro-ultraspeed; provider-default sampling, the provider applies thinking on; five independent drafts for each of ten English script briefs (50 drafts), run date 2026-10-08; four blind judges; closed-book with no tools.
Context
Specialized English long-form YouTube script writing in one creator's voice, not a general capability measure. Four blind judges score drafts; Length Adherence is computed and half of Slop Score is computed. The exact rubric is private. Published ± values for metrics are draft-to-draft standard deviations, not confidence intervals.
Source Towards AI ToneBench
ToneBench Tone & Voice Match (Show measurement, test conditions, and source)
Source value
78.2
Score
78.2
Metric
Tone & Voice Match
Unit
points
Benchmark version
ToneBench October 2026 board, generated 2026-10-13T20:08:00Z
Category
English long-form writing
Direction
Higher is better
Sample
50
Source type
independent-evaluator
Evaluator
Towards AI ToneBench
Status
superseded
Retrieved at
2026-10-17
Methodology
Independent evaluation. Via OpenRouter, exact route xiaomi/mimo-v2.6-pro-ultraspeed; provider-default sampling, the provider applies thinking on; five independent drafts for each of ten English script briefs (50 drafts), run date 2026-10-08; four blind judges; closed-book with no tools.
Context
Specialized English long-form YouTube script writing in one creator's voice, not a general capability measure. Four blind judges score drafts; Length Adherence is computed and half of Slop Score is computed. The exact rubric is private. Published ± values for metrics are draft-to-draft standard deviations, not confidence intervals.
Source Towards AI ToneBench
ToneBench Writing Craft & Clarity (Show measurement, test conditions, and source)
Source value
78
Score
78
Metric
Writing Craft & Clarity
Unit
points
Benchmark version
ToneBench October 2026 board, generated 2026-10-13T20:08:00Z
Category
English long-form writing
Direction
Higher is better
Sample
50
Source type
independent-evaluator
Evaluator
Towards AI ToneBench
Status
superseded
Retrieved at
2026-10-17
Methodology
Independent evaluation. Via OpenRouter, exact route xiaomi/mimo-v2.6-pro-ultraspeed; provider-default sampling, the provider applies thinking on; five independent drafts for each of ten English script briefs (50 drafts), run date 2026-10-08; four blind judges; closed-book with no tools.
Context
Specialized English long-form YouTube script writing in one creator's voice, not a general capability measure. Four blind judges score drafts; Length Adherence is computed and half of Slop Score is computed. The exact rubric is private. Published ± values for metrics are draft-to-draft standard deviations, not confidence intervals.
Source Towards AI ToneBench
ToneBench Substance, Accuracy & Value (Show measurement, test conditions, and source)
Source value
82.7
Score
82.7
Metric
Substance, Accuracy & Value
Unit
points
Benchmark version
ToneBench October 2026 board, generated 2026-10-13T20:08:00Z
Category
English long-form writing
Direction
Higher is better
Sample
50
Source type
independent-evaluator
Evaluator
Towards AI ToneBench
Status
superseded
Retrieved at
2026-10-17
Methodology
Independent evaluation. Via OpenRouter, exact route xiaomi/mimo-v2.6-pro-ultraspeed; provider-default sampling, the provider applies thinking on; five independent drafts for each of ten English script briefs (50 drafts), run date 2026-10-08; four blind judges; closed-book with no tools.
Context
Specialized English long-form YouTube script writing in one creator's voice, not a general capability measure. Four blind judges score drafts; Length Adherence is computed and half of Slop Score is computed. The exact rubric is private. Published ± values for metrics are draft-to-draft standard deviations, not confidence intervals.
Source Towards AI ToneBench
ToneBench Continuity & Emotion (Show measurement, test conditions, and source)
Source value
80
Score
80
Metric
Continuity & Emotion
Unit
points
Benchmark version
ToneBench October 2026 board, generated 2026-10-13T20:08:00Z
Category
English long-form writing
Direction
Higher is better
Sample
50
Source type
independent-evaluator
Evaluator
Towards AI ToneBench
Status
superseded
Retrieved at
2026-10-17
Methodology
Independent evaluation. Via OpenRouter, exact route xiaomi/mimo-v2.6-pro-ultraspeed; provider-default sampling, the provider applies thinking on; five independent drafts for each of ten English script briefs (50 drafts), run date 2026-10-08; four blind judges; closed-book with no tools.
Context
Specialized English long-form YouTube script writing in one creator's voice, not a general capability measure. Four blind judges score drafts; Length Adherence is computed and half of Slop Score is computed. The exact rubric is private. Published ± values for metrics are draft-to-draft standard deviations, not confidence intervals.
Source Towards AI ToneBench
ToneBench YouTube Best Practices (Show measurement, test conditions, and source)
Source value
78.6
Score
78.6
Metric
YouTube Best Practices
Unit
points
Benchmark version
ToneBench October 2026 board, generated 2026-10-13T20:08:00Z
Category
English long-form writing
Direction
Higher is better
Sample
50
Source type
independent-evaluator
Evaluator
Towards AI ToneBench
Status
superseded
Retrieved at
2026-10-17
Methodology
Independent evaluation. Via OpenRouter, exact route xiaomi/mimo-v2.6-pro-ultraspeed; provider-default sampling, the provider applies thinking on; five independent drafts for each of ten English script briefs (50 drafts), run date 2026-10-08; four blind judges; closed-book with no tools.
Context
Specialized English long-form YouTube script writing in one creator's voice, not a general capability measure. Four blind judges score drafts; Length Adherence is computed and half of Slop Score is computed. The exact rubric is private. Published ± values for metrics are draft-to-draft standard deviations, not confidence intervals.
Source Towards AI ToneBench
ToneBench Hook Strength (Show measurement, test conditions, and source)
Source value
80.6
Score
80.6
Metric
Hook Strength
Unit
points
Benchmark version
ToneBench October 2026 board, generated 2026-10-13T20:08:00Z
Category
English long-form writing
Direction
Higher is better
Sample
50
Source type
independent-evaluator
Evaluator
Towards AI ToneBench
Status
superseded
Retrieved at
2026-10-17
Methodology
Independent evaluation. Via OpenRouter, exact route xiaomi/mimo-v2.6-pro-ultraspeed; provider-default sampling, the provider applies thinking on; five independent drafts for each of ten English script briefs (50 drafts), run date 2026-10-08; four blind judges; closed-book with no tools.
Context
Specialized English long-form YouTube script writing in one creator's voice, not a general capability measure. Four blind judges score drafts; Length Adherence is computed and half of Slop Score is computed. The exact rubric is private. Published ± values for metrics are draft-to-draft standard deviations, not confidence intervals.
Source Towards AI ToneBench
ToneBench Length Adherence (Show measurement, test conditions, and source)
Source value
89.4
Score
89.4
Metric
Length Adherence
Unit
points
Benchmark version
ToneBench October 2026 board, generated 2026-10-13T20:08:00Z
Category
English long-form writing
Direction
Higher is better
Sample
50
Source type
independent-evaluator
Evaluator
Towards AI ToneBench
Status
superseded
Retrieved at
2026-10-17
Methodology
Independent evaluation. Via OpenRouter, exact route xiaomi/mimo-v2.6-pro-ultraspeed; provider-default sampling, the provider applies thinking on; five independent drafts for each of ten English script briefs (50 drafts), run date 2026-10-08; four blind judges; closed-book with no tools.
Context
Specialized English long-form YouTube script writing in one creator's voice, not a general capability measure. Four blind judges score drafts; Length Adherence is computed and half of Slop Score is computed. The exact rubric is private. Published ± values for metrics are draft-to-draft standard deviations, not confidence intervals.
Source Towards AI ToneBench
ToneBench Slop Score (Show measurement, test conditions, and source)
Source value
83.8
Score
83.8
Metric
Slop Score
Unit
points
Benchmark version
ToneBench October 2026 board, generated 2026-10-13T20:08:00Z
Category
English long-form writing
Direction
Higher is better
Sample
50
Source type
independent-evaluator
Evaluator
Towards AI ToneBench
Status
superseded
Retrieved at
2026-10-17
Methodology
Independent evaluation. Via OpenRouter, exact route xiaomi/mimo-v2.6-pro-ultraspeed; provider-default sampling, the provider applies thinking on; five independent drafts for each of ten English script briefs (50 drafts), run date 2026-10-08; four blind judges; closed-book with no tools.
Context
Specialized English long-form YouTube script writing in one creator's voice, not a general capability measure. Four blind judges score drafts; Length Adherence is computed and half of Slop Score is computed. The exact rubric is private. Published ± values for metrics are draft-to-draft standard deviations, not confidence intervals.
Source Towards AI ToneBench

Page 1 of 3

Popularity compared

How often the model is searched for, used and mentioned, compared with every model of its category.

Popularity index

The 100 most popular models of this category, 0 to 100, higher is more popular

20 of 101 models

As of November 2026 · Source: gradually.ai popularity index

Over time

Weekly values from October 18, 2026 to November 6, 2026

MiMo V2.6 Pro UltraSpeedAgnes 3.0 FlashAion 3.5Aion 3.5 MiniEmber-1

What is gaining popularity right now, across models, vendors, harnesses and AI subscriptions, is collected in All AI trends.

All specifications

Architecture

Model class
High-speed mode for MiMo V2.6 Pro
Source: Model class

Input and output

Speed
Up to 20× faster inference according to Xiaomi
Source: Speed

Watermarking and provenance

AI watermarking refers to invisible signals embedded in the output. Visible marks and provenance metadata are listed separately. Unknown means there is insufficient evidence for that particular field.

AI watermarking
Unknown
no source
Watermarking technique
Not known
no source

Licence and access

Access
MiMo API and MiMo Desktop
Source: Access
Weights
No separate weights published
Source: Weights

API

API model ID
mimo-v2.6-pro-ultraspeed
Source: API model ID

Further details

Batch API
Not available
Source: Batch API

Prices

Choose a price view

1 offer, prices in US dollars per 1M tokens, blended from 3 parts input and 1 part output.

ProviderInputOutputCache readBlended
Xiaomidirect$4.35$8.70$0.036$5.44

Direct price according to the developer, checked Oct 25, 2026. Open the LLM price index

More price tiers and rules
Cache price
US$0.036 / 1M tokens, overseas real-time API, cache hitSource
Input price
US$4.35 / 1M tokens, overseas real-time API, cache missSource
Output price
US$8.70 / 1M tokens, overseas real-time APISource

No Xiaomi subscription includes this model. Through other providers from $10 a month (Command Code GOAT, with limited credits). 4 plans in Germany.

PlanMonthly list priceNote
Command Code GOAT$10with limited credit
Command Code Pro$20with limited credit
Command Code Max 10×$100with limited credit
Command Code Max 20×$200with limited credit

All plans in the AI subscription comparison

Frequently asked questions about MiMo V2.6 Pro UltraSpeed

How much does MiMo V2.6 Pro UltraSpeed cost?

Through the API $4.35 per 1M input tokens and $8.70 output. That is expensive.

PriceDollars per 1M tokens, input and output blended · lower is better
GPT-5.6 Terra$4.50
Gemini 3.1 Pro Preview$4.50
MiMo V2.6 Pro UltraSpeedRank 79 of 95$5.44
GPT-5.4$5.63
Kimi K3$6
Claude Sonnet 4.6$6
Claude Sonnet 4.5$6

Where can I use MiMo V2.6 Pro UltraSpeed?

Not in a Xiaomi subscription. Including other providers that makes 4 plans in Germany, plus the API.

Subscription comparison, prices in Germany incl. VAT

At Xiaomi

No Xiaomi subscription includes this model.

Through other providers

4 plans from 1 provider, from $10 a month (Command Code GOAT), with limited credits.

Through the API

$4.35 input, $8.70 output per 1M tokens.

Sources and data date

Show all 12 sources

Benchmark sources at a glance

Which independent evaluators tested this model. This is coverage, not a quality ranking.

No active result from the reviewed external evaluators can currently be attributed to this model. Other source evidence remains available below.

Without vendor claims and historical or disputed results; those stay labelled in the single values.

TypeEvidence and data date
Price

Base API prices without caching or batch discounts. Higher context tiers and other rates are listed under Costs.

Research statusResearch date October 15, 2026. 5 source URLs checked. This documents the inspected sources, not an exhaustive inventory of every publication.
Unresolved

broader-independent-quality-benchmarks

Note

The exact UltraSpeed API route has separate Python micro-suite and ToneBench English long-form writing results. These specialized evaluations do not establish broader general-purpose capability or an immutable serving revision. A same-checkpoint statement alone does not transfer sibling-model results.

Additional sourceXiaomi MiMo model release (retrieved September 22, 2026; October 15, 2026) · Xiaomi MiMo V2.6 model release · Editorial description reviewed October 2, 2026
Additional sourceXiaomi MiMo V2.6 announcement (retrieved September 22, 2026; October 15, 2026) · Xiaomi MiMo V2.6 announcement · Editorial description reviewed October 2, 2026
Additional sourceDataLLM Lab executed API benchmark (retrieved October 16, 2026; October 23, 2026)
Additional sourceTowards AI ToneBench (retrieved October 17, 2026; October 28, 2026; October 30, 2026)
Additional sourceModel metadata (retrieved October 16, 2026)
Additional sourceOpenRouter: Popularity index (derived), CC BY 4.0
Additional sourceVercel AI Gateway: Popularity index (derived), CC BY 4.0
Additional sourceOllama: cumulative downloads for the popularity index
Additional sourceReplicate: cumulative runs for the popularity index
Additional sourceGoogle Trending Now: limited feed selection for Germany and the US
Additional sourceCreative Commons Attribution 4.0