MetaLanguage model

Llama 4 Maverick 17B Instruct

Llama 4 Maverick 17B Instruct has no overall index value yet because there are too few independent benchmark results. From the vendor-reported results we estimate about 52.5 points (95% range 32.6 to 72.3). This is not an independent measurement.

PopularityRank 448 of 785

33out of 100+1 vs. last month

based on search, usage and attention

Summary

Llama 4 Maverick 17B Instruct is the cataloged Instruct identity for Meta’s open Maverick weights. The 17B in the name describes active parameters, not the full size of the MoE model. It accepts text and images and provides about one million tokens of context.

The weights use the Llama 4 Community License. Llama 4 Maverick leads to the family checkpoint. Llama 4 Scout 17B Instruct is the parallel Scout variant with a larger context window. The model card lists Transformers, vLLM, and SGLang, plus quantizations for llama.cpp, Ollama, and LM Studio.

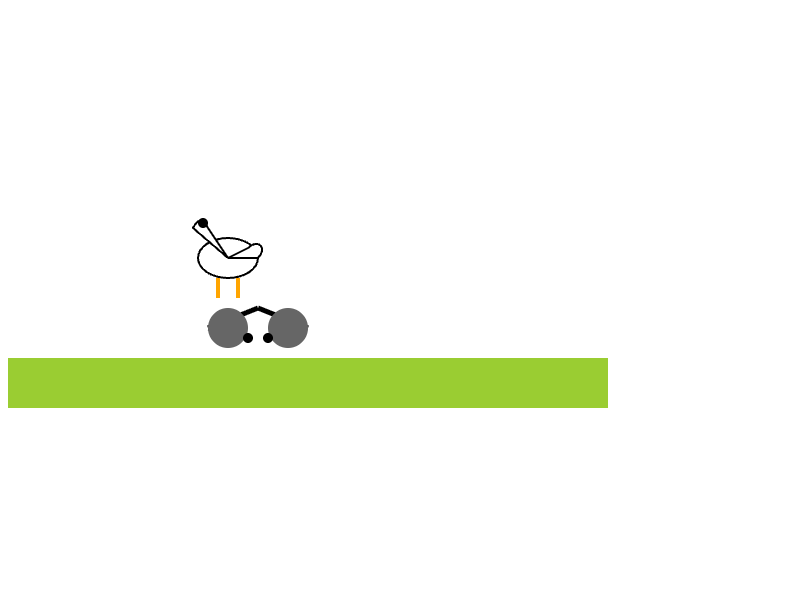
See for yourself: one prompt, one attempt

We show the latest attempt without fixes; it does not count toward the overall index.

Llama 4 Maverick 17B Instruct: Pelican on a bicycle
A community classic for free-form SVG drawing.

Pelican on a bicycle

Prompt

Generate an SVG of a pelican riding a bicycle

Oct 2, 2026 · 33 s · $0.0005

Test details
Run date
Oct 2, 2026
API provider
openrouter
Requested API model
meta-llama/llama-4-maverick
Reasoning setting
not specified
Token limit including reasoning
8,192 tokens
Output tokens
785 tokens
Cost of the attempt
$0.0005
Response time
33.3 s
API model reported in response
meta-llama/llama-4-maverick
Pinned endpoint
DigitalOcean | meta-llama/llama-4-maverick-17b-128e-instruct
Temperature
Provider default
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating

Visually reviewed. This individual test does not establish overall model quality.

Task origin: Simon Willison
SVG short test

SVG short test

One SVG task with the same fixed settings for every model, without hidden thinking.

Llama 4 Maverick 17B Instruct

No independent test. This API route aliases llama-4-maverick.

All benchmark results

Every published result with its source, test setup and comparison models.

Show all 111 published benchmark results

Page 1 of 10

Measurements without matching peer values

These measurements have no matching peer values under the same test conditions. Their original values and sources remain available here.

SWE-bench Verified (official mini-SWE-agent) (Show measurement, test conditions, and source)
Source value
21.04
Score
21.04
Metric
resolved issue rate
Unit
%
Benchmark version
SWE-bench Verified; mini-SWE-agent 0.0.0; submission 20250720_mini-v0.0.0-Llama-4-Maverick-17B-Instruct
Category
coding
Direction
Higher is better
Source type
official-leaderboard
Evaluator
SWE-bench
Status
active
Retrieved at
2026-10-16
Methodology
Official benchmark leaderboard. Official SWE-bench Verified (500 benchmark tasks); mini-SWE-agent 0.0.0; source submission 20250720_mini-v0.0.0-Llama-4-Maverick-17B-Instruct; source date 2025-07-20; model label Llama 4 Maverick Instruct; reasoning_effort=not specified. Source logs: s3://swe-bench-submissions/bash-only/20250720_mini-v0.0.0-Llama-4-Maverick-17B-Instruct/logs. The leaderboard marks this submission as independently checked: yes.
Context
Historical official leaderboard submission, not a fresh model run or a Vals evaluation. mini-SWE-agent 1.x and 2.x use different action interfaces and are not necessarily comparable. Undisclosed sampling, repetition counts and backend revisions remain unknown.
Source SWE-bench
MMMU (Show measurement, test conditions, and source)
Source value
73.4
Score
73.4
Metric
percent
Unit
%
Direction
Higher is better
Source type
vendor-reported
Evaluator
Meta Llama 4 model card
Status
active
Retrieved at
2026-09-08
Methodology
Vendor-reported result. Instruction-tuned table; BF16
Source Meta Llama 4 model card
MMMU Pro (Show measurement, test conditions, and source)
Source value
59.6
Score
59.6
Metric
percent
Unit
%
Direction
Higher is better
Source type
vendor-reported
Evaluator
Meta Llama 4 model card
Status
active
Retrieved at
2026-09-08
Methodology
Vendor-reported result. Instruction-tuned table; BF16
Source Meta Llama 4 model card
MathVista (Show measurement, test conditions, and source)
Source value
73.7
Score
73.7
Metric
percent
Unit
%
Direction
Higher is better
Source type
vendor-reported
Evaluator
Meta Llama 4 model card
Status
active
Retrieved at
2026-09-08
Methodology
Vendor-reported result. Instruction-tuned table; BF16
Source Meta Llama 4 model card
ChartQA (Show measurement, test conditions, and source)
Source value
90
Score
90
Metric
percent
Unit
%
Direction
Higher is better
Source type
vendor-reported
Evaluator
Meta Llama 4 model card
Status
active
Retrieved at
2026-09-08
Methodology
Vendor-reported result. Instruction-tuned table; BF16
Source Meta Llama 4 model card
DocVQA (Show measurement, test conditions, and source)
Source value
94.4
Score
94.4
Metric
percent
Unit
%
Direction
Higher is better
Source type
vendor-reported
Evaluator
Meta Llama 4 model card
Status
active
Retrieved at
2026-09-08
Methodology
Vendor-reported result. Instruction-tuned table; BF16
Source Meta Llama 4 model card
LiveCodeBench (Show measurement, test conditions, and source)
Source value
43.4
Score
43.4
Metric
percent
Unit
%
Direction
Higher is better
Source type
vendor-reported
Evaluator
Meta Llama 4 model card
Status
active
Retrieved at
2026-09-08
Methodology
Vendor-reported result. Instruction-tuned table; BF16
Source Meta Llama 4 model card
MMLU Pro instruct (Show measurement, test conditions, and source)
Source value
80.5
Score
80.5
Metric
percent
Unit
%
Direction
Higher is better
Source type
vendor-reported
Evaluator
Meta Llama 4 model card
Status
active
Retrieved at
2026-09-08
Methodology
Vendor-reported result. Instruction-tuned table; BF16
Source Meta Llama 4 model card
GPQA (Show measurement, test conditions, and source)
Source value
69.8
Score
69.8
Metric
percent
Unit
%
Direction
Higher is better
Source type
vendor-reported
Evaluator
Meta Llama 4 model card
Status
active
Retrieved at
2026-09-08
Methodology
Vendor-reported result. Instruction-tuned table; BF16
Source Meta Llama 4 model card
MGSM (Show measurement, test conditions, and source)
Source value
92.3
Score
92.3
Metric
percent
Unit
%
Direction
Higher is better
Source type
vendor-reported
Evaluator
Meta Llama 4 model card
Status
active
Retrieved at
2026-09-08
Methodology
Vendor-reported result. Instruction-tuned table; BF16
Source Meta Llama 4 model card
MTOB half (Show measurement, test conditions, and source)
Source value
46.4
Score
46.4
Metric
percent
Unit
%
Direction
Higher is better
Source type
vendor-reported
Evaluator
Meta Llama 4 model card
Status
superseded
Retrieved at
2026-09-08
Methodology
Vendor-reported result. Instruction-tuned tool-use table; BF16
Source Meta Llama 4 model card
MTOB full (Show measurement, test conditions, and source)
Source value
46.7
Score
46.7
Metric
percent
Unit
%
Direction
Higher is better
Source type
vendor-reported
Evaluator
Meta Llama 4 model card
Status
superseded
Retrieved at
2026-09-08
Methodology
Vendor-reported result. Instruction-tuned tool-use table; BF16
Source Meta Llama 4 model card

Page 1 of 10

Popularity compared

How often the model is searched for, used and mentioned, compared with every model of its category.

Popularity index

The 100 most popular models of this category, 0 to 100, higher is more popular

20 of 101 models

As of November 2026 · Source: gradually.ai popularity index

Over time

Weekly values from October 18, 2026 to November 7, 2026

Llama 4 Maverick 17B InstructMixtral 8x22B 33Amazon Nova Pro 33Aya Expanse 32B 33MiMo V2.6 Pro UltraSpeed 33

Method changes in the timeline, a jump at these points is no market event:

  1. 1November 1, 2026: Value only with search or usage data, 30-day attention

What is gaining popularity right now, across models, vendors, harnesses and AI subscriptions, is collected in All AI trends.

All specifications

Architecture

Parameters
400 billion
Source: Parameters
Active parameters
17 billion
Source: Active parameters
Knowledge cutoff
August 2024
Source: Knowledge cutoff

Input and output

Context window
1,000,000 tokens
Source: Context window
Maximum output
16,384 tokens
Source: Maximum output
Inputs
Text, Image
Source: Inputs
Outputs
Text
Source: Outputs
Tool calling
Yes
Source: Tool calling

Watermarking and provenance

AI watermarking refers to invisible signals embedded in the output. Visible marks and provenance metadata are listed separately. Unknown means there is insufficient evidence for that particular field.

AI watermarking
Unknown
no source
Watermarking technique
Not known
no source

Licence and access

Weights
Open weights
Source: Weights
License
Llama 4 Community
Source: License

Prices

Not included in any subscription in Germany.

All plans in the AI subscription comparison

Frequently asked questions about Llama 4 Maverick 17B Instruct

How good is Llama 4 Maverick 17B Instruct in benchmarks?

Independent results are not yet enough for the overall index. An estimate from 3 vendor-reported results (MMLU-Pro 80.5%, MMMU-Pro 59.6%, MMMU (val) 73.4%) gives about 52.5 points, with a 95% range of 32.6 to 72.3. The estimate is calibrated on models with both vendor-reported and independent results. Vendor numbers run clearly above independent measurements on some tests; the calibration offsets that on average.

Vendor estimate, not an overall index value

What is the knowledge cutoff of Llama 4 Maverick 17B Instruct?

August 2024, according to Meta. That is 8 months before release.

Stated by Meta

How large is the context window of Llama 4 Maverick 17B Instruct?

1 M tokens. That is how much text Llama 4 Maverick 17B Instruct reads at once, about 1,500 A4 pages.

Page count as a rule of thumb from Artificial Analysis

Context windowTokens the model reads at once · higher is better
Llama 4 Maverick 17B InstructRank 31 of 1031M
Claude Opus 5.51M
Gemini 4 Carbon1M
Claude Fable 5.11M
Claude Sonnet 5.51M
Muse Wonder Full1M
Claude Opus 51M

Can I run Llama 4 Maverick 17B Instruct locally?

Yes, the weights are open. With 400B parameters it needs a lot of memory, more a server than a laptop.

Stated by Meta

Open weights
yes
License
Llama 4 Community
Parameters
400B
active per token
17B

Sources and data date

Show all 35 sources

Benchmark sources at a glance

Which independent evaluators tested this model. This is coverage, not a quality ranking.

EvaluatorTest seriesComposite indicesRecorded active measurements
LMArena001
SWE-bench001
Scale AI Evals001

Without vendor claims and historical or disputed results; those stay labelled in the single values. 3 measurements are not yet assigned to a test series.

TypeEvidence and data date
Input

Documented modalities. Retrieved October 27, 2026.

Output

Documented modalities. Retrieved October 27, 2026.

Research statusResearch date September 8, 2026. 28 source URLs checked. This documents the inspected sources, not an exhaustive inventory of every publication.
Not published

per-row evaluation N and confidence interval

Note

The paper describes dataset sizes but reports no model-row sample size or confidence interval.

Unresolved

row-specific prompt, route, and checkpoint revision

Note

Study-level protocol is described, but no prompt variant, serving route, or checkpoint revision is bound to this row.

Not published

evaluated N

Original wording

The leaderboard reports preference-vote totals but no fixed task-case N; Votes are not copied to sampleCount.

Unresolved

confidence interval

Original wording

The Score cell displays ±, but the official policy does not define that notation as a confidence interval; no CI field is populated.

Unresolved

score direction

Original wording

The captured source does not explicitly state higher-is-better or lower-is-better; higherIsBetter remains null.

Not published

per-model prompts and generation settings

Original wording

No exact prompt, decoding settings, or serving configuration is published in the captured row.

Additional sourceHugging Face (retrieved October 15, 2026; October 20, 2026; October 28, 2026) · Hugging Face, Llama 4 Maverick 17B Instruct · Editorial description reviewed October 2, 2026
Additional sourceSWE-bench (retrieved October 16, 2026)
Additional sourceMeta Llama 4 model card (retrieved September 8, 2026; October 28, 2026)
Additional sourceMeta Llama-verifications benchmark report, pinned commit 9a53f29 (retrieved October 17, 2026)
Additional sourceRobustness as an Emergent Property of Task Performance (retrieved October 17, 2026; October 24, 2026)
Additional sourceEFFIBENCH-X: A Multi-Language Benchmark for Measuring Efficiency of LLM-Generated Code (retrieved October 17, 2026)
Additional sourceAssessing Large Language Models for Medical QA: Zero-Shot and LLM-as-a-Judge Evaluation (arXiv:2602.14564v1) (retrieved October 17, 2026)
Additional sourceSpatialViz-Bench, anonymous ICLR 2026 submission (retrieved October 18, 2026)
Additional sourceMM-BrowseComp: A Comprehensive Benchmark for Multimodal Browsing Agents (retrieved October 18, 2026)
Additional sourceACL Anthology, Findings of EMNLP 2025, From KMMLU-Redux to Pro (retrieved October 18, 2026)
Additional sourceArena leaderboard (retrieved October 18, 2026)
Additional sourceFinCon Bench (retrieved October 19, 2026)
Additional sourceMeta Llama Verifications Benchmark Evaluation Report (retrieved October 19, 2026)
Additional sourceMERA Text (retrieved October 23, 2026)
Additional sourceBigCodeBench official leaderboard (retrieved October 28, 2026)12
Additional sourceScale SWE-Bench Pro public leaderboard (retrieved October 28, 2026)
Additional sourceModel metadata (retrieved October 16, 2026)12
Additional sourceModel metadata (retrieved September 8, 2026)
Additional sourceModel metadata (retrieved October 17, 2026)
Additional sourceModel metadata (retrieved October 18, 2026)
Additional sourceModel metadata (retrieved October 19, 2026)
Additional sourceModel metadata (retrieved October 28, 2026)12345
Additional sourceOpenRouter: Popularity index (derived), CC BY 4.0
Additional sourceVercel AI Gateway: Popularity index (derived), CC BY 4.0
Additional sourceOllama: cumulative downloads for the popularity index
Additional sourceReplicate: cumulative runs for the popularity index
Additional sourceGoogle Trending Now: limited feed selection for Germany and the US
Additional sourceCreative Commons Attribution 4.0