AlibabaLanguage modelActive

Qwen3.8-Omni-Flash

Qwen3.8-Omni-Flash has no overall index value yet because there are too few independent benchmark results.

Intelligencenot ranked yet

n/aOverall indexhigher is better

Speednot measured

n/ano measurement yet

PriceRank 8 of 95

Input $0.113 · Output $0.382

$0.18per 1M tokenslower is better

ContextRank 31 of 102

1Mtokens at once≈ 1,500 A4 pages

PopularityRank 645 of 875

2out of 100same as last month

Summary

It is cheap: $0.18 per 1M tokens (input and output blended); a typical model costs $1.56.

Qwen3.8-Omni-Flash is a proprietary API model for audio and video analysis with text output. It accepts text, images, audio, and video in a shared context of up to 1,000,000 tokens. The documentation names long recordings, meeting summaries, speaker alignment, and video understanding.

The endpoint returns text, not audio. Current documentation describes Chat Completions and Responses for non-real-time requests. For speech dialogs with audio output, Alibaba points to Qwen3.5-Omni. These docs do not name a separate realtime endpoint.

See for yourself: one prompt, one attempt

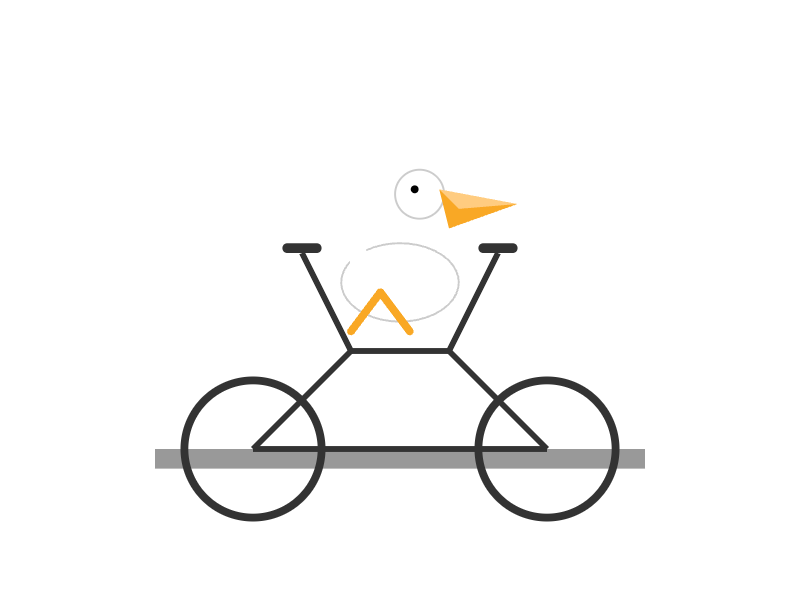
SVG short test

One SVG task with the same fixed settings for every model, without hidden thinking.

Qwen3.8-Omni-Flash

Qwen3.8-Omni-Flash: SVG short test

Prompt

Return only one standalone SVG of a pelican riding a bicycle. Use viewBox="0 0 800 600", simple shapes, two clearly visible wheels and a recognizable pelican with a long beak. At most 30 SVG elements and 1800 characters. No Markdown, explanations, comments, scripts, animation, CSS or external resources.

Oct 14, 2026 · $0.0004

Test details
Test run
Oct 14, 2026
Provider
alibaba
API model
qwen/qwen3.8-omni-flash
Output
726 tokens
Reasoning
API reports 0 reasoning tokens
Cost of the attempt
$0.0004
Test round
43b8c5c46830
Earlier tests

API request failed

Pelican on a bicycle

Prompt

Generate an SVG of a pelican riding a bicycle

Oct 5, 2026

Not yet visually reviewed. A successful recording does not confirm correct physics or full compliance with the prompt.

Test details
Run date
Oct 5, 2026
API provider
openrouter
Requested API model
qwen/qwen3.8-omni-flash
Reasoning setting
high
Token limit including reasoning
8,192 tokens
Pinned endpoint
Alibaba | qwen/qwen3.8-omni-flash-20260918
Temperature
Provider default
Test protocol
community-visual-tests-v1
Technical checks
Failed

Earlier attempts (2)

  • Oct 2, 2026API request failedReasoning setting: high
  • Oct 1, 2026API request failedReasoning setting: high
Task origin: Simon Willison

All benchmark results

Every published result with its source, test setup and comparison models.

Show all 88 published benchmark results

Page 1 of 8

Measurements without matching peer values

These measurements have no matching peer values under the same test conditions. Their original values and sources remain available here.

ClawEval-MM (Show measurement, test conditions, and source)
Source value
60.4
Score
60.4
Metric
Pass@3, at least one successful trial
Unit
%
Benchmark version
Qwen3.8-Omni technical report v1, Table 3
Category
agents
Direction
Higher is better
Source type
vendor-reported
Evaluator
Qwen3.8-Omni: Towards Native Omni-Modal Agents, Qwen Team
Status
active
Retrieved at
2026-10-15
Methodology
Vendor-reported result. Exact Qwen3.8-Omni-Flash row. Pass@3 is the percentage of tasks passed in at least one of three trials. Task date, prompt/harness details, sampling, serving snapshot, and quantization are not stated.
Context
The report was published 2026-09-22; this is not a benchmark task date.
Source Qwen3.8-Omni: Towards Native Omni-Modal Agents, Qwen Team
AliMeeting Test (Show measurement, test conditions, and source)
Source value
17.2
Score
17.2
Metric
cpWER
Unit
%
Category
audio
Direction
Lower is better
Source type
vendor-reported
Evaluator
Qwen3.8-Omni paper
Status
active
Retrieved at
2026-10-17
Methodology
Vendor-reported result. Qwen3.8-Omni-Flash column in Table 4. Metric is identified by the table row or table description; the paper gives no per-row denominator. Lower error rate is better.
Context
The cited table does not publish a per-result denominator or numeric confidence interval; the numerical scale is left as reported.
Source Qwen3.8-Omni paper
AISHELL-4 (Show measurement, test conditions, and source)
Source value
11.2
Score
11.2
Metric
cpWER
Unit
%
Category
audio
Direction
Lower is better
Source type
vendor-reported
Evaluator
Qwen3.8-Omni paper
Status
active
Retrieved at
2026-10-17
Methodology
Vendor-reported result. Qwen3.8-Omni-Flash column in Table 4. Metric is identified by the table row or table description; the paper gives no per-row denominator. Lower error rate is better.
Context
The cited table does not publish a per-result denominator or numeric confidence interval; the numerical scale is left as reported.
Source Qwen3.8-Omni paper
MagicData-RAMC (Show measurement, test conditions, and source)
Source value
14.1
Score
14.1
Metric
cpWER
Unit
%
Category
audio
Direction
Lower is better
Source type
vendor-reported
Evaluator
Qwen3.8-Omni paper
Status
active
Retrieved at
2026-10-17
Methodology
Vendor-reported result. Qwen3.8-Omni-Flash column in Table 4. Metric is identified by the table row or table description; the paper gives no per-row denominator. Lower error rate is better.
Context
The cited table does not publish a per-result denominator or numeric confidence interval; the numerical scale is left as reported.
Source Qwen3.8-Omni paper
MLC-SLM (en) (Show measurement, test conditions, and source)
Source value
14.2
Score
14.2
Metric
cpWER
Unit
%
Category
audio
Direction
Lower is better
Source type
vendor-reported
Evaluator
Qwen3.8-Omni paper
Status
active
Retrieved at
2026-10-17
Methodology
Vendor-reported result. Qwen3.8-Omni-Flash column in Table 4. Metric is identified by the table row or table description; the paper gives no per-row denominator. Lower error rate is better.
Context
The cited table does not publish a per-result denominator or numeric confidence interval; the numerical scale is left as reported.
Source Qwen3.8-Omni paper
OmniLingua-LongAudioASR (Show measurement, test conditions, and source)
Source value
95.56
Score
95.56
Metric
Success rate
Unit
%
Category
audio
Direction
Higher is better
Source type
vendor-reported
Evaluator
Qwen3.8-Omni paper
Status
active
Retrieved at
2026-10-17
Methodology
Vendor-reported result. Qwen3.8-Omni-Flash column in Table 4. Metric is identified by the table row or table description; the paper gives no per-row denominator. OmniLingua-LongAudioASR reports success rate and WER as separate metrics.
Context
The cited table does not publish a per-result denominator or numeric confidence interval; the numerical scale is left as reported.
Source Qwen3.8-Omni paper
OmniLingua-MultiSpeaker (Show measurement, test conditions, and source)
Source value
100
Score
100
Metric
Success rate
Unit
%
Category
audio
Direction
Higher is better
Source type
vendor-reported
Evaluator
Qwen3.8-Omni paper
Status
active
Retrieved at
2026-10-17
Methodology
Vendor-reported result. Qwen3.8-Omni-Flash column in Table 4. Metric is identified by the table row or table description; the paper gives no per-row denominator. The table reports success rate, tcpWER, cpWER, and DER separately.
Context
The cited table does not publish a per-result denominator or numeric confidence interval; the numerical scale is left as reported.
Source Qwen3.8-Omni paper
OmniLingua-MultiSpeaker (Show measurement, test conditions, and source)
Source value
43.25
Score
43.25
Metric
tcpWER
Unit
%
Category
audio
Direction
Lower is better
Source type
vendor-reported
Evaluator
Qwen3.8-Omni paper
Status
active
Retrieved at
2026-10-17
Methodology
Vendor-reported result. Qwen3.8-Omni-Flash column in Table 4. Metric is identified by the table row or table description; the paper gives no per-row denominator. Lower error rate is better.
Context
The cited table does not publish a per-result denominator or numeric confidence interval; the numerical scale is left as reported.
Source Qwen3.8-Omni paper
OmniLingua-MultiSpeaker (Show measurement, test conditions, and source)
Source value
34.97
Score
34.97
Metric
cpWER
Unit
%
Category
audio
Direction
Lower is better
Source type
vendor-reported
Evaluator
Qwen3.8-Omni paper
Status
active
Retrieved at
2026-10-17
Methodology
Vendor-reported result. Qwen3.8-Omni-Flash column in Table 4. Metric is identified by the table row or table description; the paper gives no per-row denominator. Lower error rate is better.
Context
The cited table does not publish a per-result denominator or numeric confidence interval; the numerical scale is left as reported.
Source Qwen3.8-Omni paper
OmniCompass-AV (Show measurement, test conditions, and source)
Source value
48.6
Score
48.6
Metric
CS^{Avg}
Unit
%
Direction
Higher is better
Source type
independent-evaluator
Evaluator
OmniCompass: A Holistic Benchmark for Omni-Modal Video Grounding and Understanding (arXiv:2610.18829v1)
Status
active
Retrieved at
2026-10-22
Methodology
Independent evaluation. OmniCompass-AV; the model row lists 64 frames, and the caption specifies uniformly sampled, timestamped frames with synchronized audio.
Context
The inspected result table gives no model-specific N, confidence interval, measurement date, or exact checkpoint revision. CSAvg is a benchmark-specific consistency measure.
Source OmniCompass: A Holistic Benchmark for Omni-Modal Video Grounding and Understanding (arXiv:2610.18829v1)
DeepSWE 1.1 (Show measurement, test conditions, and source)
Source value
57.8
Score
57.8
Metric
reported score
Unit
No unit provided
Benchmark version
Qwen3.8-Omni technical report v1, Table 2
Category
code-agent
Direction
Higher is better
Source type
vendor-reported
Evaluator
Qwen3.8-Omni: Towards Native Omni-Modal Agents, Qwen Team
Status
active
Retrieved at
2026-10-15
Methodology
Vendor-reported result. Exact Qwen3.8-Omni-Flash row. The report says DeepSWE uses Claude Code and mini-SWE-agent, temperature 1, top_p 0.95, and 256K context; it reports the best score across both harnesses without identifying the harness for this row. Task date, serving snapshot, and quantization are not stated.
Context
The report was published 2026-09-22; this is not a benchmark task date. The table does not state a score unit or scale.
Source Qwen3.8-Omni: Towards Native Omni-Modal Agents, Qwen Team
SWE-bench Pro (Show measurement, test conditions, and source)
Source value
63.3
Score
63.3
Metric
reported score
Unit
No unit provided
Benchmark version
Qwen3.8-Omni technical report v1, Table 2
Category
code-agent
Direction
Higher is better
Source type
vendor-reported
Evaluator
Qwen3.8-Omni: Towards Native Omni-Modal Agents, Qwen Team
Status
active
Retrieved at
2026-10-15
Methodology
Vendor-reported result. Exact Qwen3.8-Omni-Flash row. The report states Claude Code, temperature 1, top_p 0.95, 256K context, and refined SWE-bench Pro tasks. Task date, serving snapshot, quantization, and further harness details are not stated.
Context
The report was published 2026-09-22; this is not a benchmark task date. The table does not state a score unit or scale.
Source Qwen3.8-Omni: Towards Native Omni-Modal Agents, Qwen Team

Page 1 of 8

Popularity compared

How often the model is searched for, used and mentioned, compared with every model of its category.

Popularity index

The 100 most popular models of this category, 0 to 100, higher is more popular

20 of 101 models

As of November 2026 · Source: gradually.ai popularity index

Over time

Weekly values from October 18, 2026 to November 5, 2026

Qwen3.8-Omni-FlashStep 5 PreviewMAI-Code-1.1-FlashMistral NemotronMuse Wonder

All specifications

Architecture

Model class
Omnimodal language model
Source: Model class

Input and output

Input
Text, image, audio, video
Source: Input
Output
Text
Source: Output
Context window
1,000,000 tokens
Source: Context window
Maximum output
131,072 tokens
Source: Maximum output
Reasoning mode
Default: xhigh. Adjustable from none to max.
Source: Reasoning mode

Watermarking and provenance

AI watermarking refers to invisible signals embedded in the output. Visible marks and provenance metadata are listed separately. Unknown means there is insufficient evidence for that particular field.

AI watermarking
Unknown
no source
Watermarking technique
Not known
no source

Licence and access

Weights
Proprietary
Source: Weights

API

API model ID
qwen3.8-omni-flash
Source: API model ID

Further details

Tools
Function calling and web search
Source: Tools

Prices

Choose a price view

1 offer, prices in US dollars per 1M tokens, blended from 3 parts input and 1 part output.

ProviderInputOutputCache readBlended
Alibabadirect$0.113$0.382$0.014$0.18

Direct price according to the developer, checked Sep 22, 2026. Open the LLM price index

More price tiers and rules
Input price
US$0.113 / 1M tokens, FrankfurtSource
Output price
US$0.382 / 1M tokens, FrankfurtSource
Cache price
US$0.014 / 1M tokens for cache hits, FrankfurtSource

No Alibaba subscription includes this model. Through other providers from ≈ €1.06 a month (Command Code Go, with limited credits). 5 plans in Germany.

PlanMonthly priceNote
Command Code Go≈ €1.06with limited credit
Command Code GOAT≈ €10.60with limited credit
Command Code Pro≈ €21.20with limited credit
Command Code Max 10×≈ €106.02with limited credit
Command Code Max 20×≈ €212.05with limited credit

All plans in the AI subscription comparison

Frequently asked questions about Qwen3.8-Omni-Flash

How much does Qwen3.8-Omni-Flash cost?

Through the API $0.113 per 1M input tokens and $0.382 output. That is cheap.

PriceDollars per 1M tokens, input and output blended · lower is better
MiMo V2.6 Flash$0.18
MiMo-V2.5$0.18
Qwen3.8-Omni-FlashRank 8 of 95$0.18
Claude Haiku 5.5$0.20
GPT-6 Luna$0.20
GPT OSS 120B$0.20
GLM-5.3-Flash$0.24

How large is the context window of Qwen3.8-Omni-Flash?

1 M tokens. That is how much text Qwen3.8-Omni-Flash reads at once, about 1,500 A4 pages.

Page count as a rule of thumb from Artificial Analysis

Context windowTokens the model reads at once · higher is better
Qwen3.8-Omni-FlashRank 31 of 1021M
Claude Opus 5.51M
Gemini 4 Carbon1M
Claude Fable 5.11M
Claude Sonnet 5.51M
Muse Wonder Full1M
Claude Opus 51M

Can I run Qwen3.8-Omni-Flash locally?

No. Alibaba does not publish the weights.

Stated by Alibaba

Open weights
no
License
n/a
Parameters
n/a
active per token
n/a

Where can I use Qwen3.8-Omni-Flash?

Not in a Alibaba subscription. Including other providers that makes 5 plans in Germany, plus the API.

Subscription comparison, prices in Germany incl. VAT

At Alibaba

No Alibaba subscription includes this model.

Through other providers

5 plans from 1 provider, from ≈ €1.06 a month (Command Code Go), with limited credits.

Through the API

$0.113 input, $0.382 output per 1M tokens.

Sources and data date

Show all 13 sources

Benchmark sources at a glance

Which independent evaluators tested this model. This is coverage, not a quality ranking.

No active result from the reviewed external evaluators can currently be attributed to this model. Other source evidence remains available below.

Without vendor claims and historical or disputed results; those stay labelled in the single values.

TypeEvidence and data date
Price

Base API prices without caching or batch discounts. Higher context tiers and other rates are listed under Costs.

Research statusResearch date October 15, 2026. 4 source URLs checked. This documents the inspected sources, not an exhaustive inventory of every publication.
Not published

per-row sample counts and confidence intervals

Note

The result tables do not provide exact per-row denominators or numerical confidence intervals. Repeated runs are recorded only where stated.

Unresolved

OmniEchoBench single score

Note

Table 5 reports 43.9 while the later discussion paragraph reports 41.7 for Qwen3.8-Omni-Flash; both claims remain visible in the disputed row.

Additional sourceAlibaba Cloud Model Studio (retrieved September 22, 2026; October 15, 2026) · Alibaba Cloud Qwen3.8-Omni-Flash · Editorial description reviewed October 2, 2026
Additional sourceAlibaba Cloud newly released models (retrieved September 22, 2026; October 15, 2026)
Additional sourceQwen3.8-Omni: Towards Native Omni-Modal Agents, Qwen Team (retrieved October 15, 2026; October 17, 2026)
Additional sourceOmniCompass: A Holistic Benchmark for Omni-Modal Video Grounding and Understanding (arXiv:2610.18829v1) (retrieved October 22, 2026)
Additional sourceQwen3.8-Omni-Flash official release · Editorial description reviewed October 2, 2026
Additional sourceAlibaba Cloud Qwen-Omni documentation · Editorial description reviewed October 2, 2026
Additional sourceOpenRouter: Popularity index (derived), CC BY 4.0
Additional sourceVercel AI Gateway: Popularity index (derived), CC BY 4.0
Additional sourceOllama: cumulative downloads for the popularity index
Additional sourceReplicate: cumulative runs for the popularity index
Additional sourceGoogle Trending Now: limited feed selection for Germany and the US
Additional sourceCreative Commons Attribution 4.0