
o3-pro
No independent attempt was planned for this model.
OpenAI
| Specification | Value and source |
|---|---|
| Weights | ProprietarySource |
| Access | APISource |
| Context window | 200,000 tokensSource |
| Knowledge cutoff | June 1, 2024Source |
| Notes | Reasoning model, parameter count not disclosedSource |
| API model ID | o3-proSource |
| Maximum output | 100,000 tokensSource |
| Input | Text, ImageSource |
| Output | TextSource |
| Reasoning mode | medium, high, xhighSource |
| API interfaces | Responses APISource |
| Tool calling | YesSource |
| Structured output | YesSource |
| Release | 2025-06-10Source |
Page 1 of 2
Overall
225 code-editing tasks from Exercism across C++, Go, Java, JavaScript, Python, and Rust. Aider, the edit format, reasoning budget, and two attempts are part of the result.
higher is betterAs of September 2, 2026Scale: 0% - 100%
Overall
Multi-turn conversations test memory, instruction retention, versioned editing, and self-coherence. Tasks were selected from shared failures of six older frontier models and may disadvantage those systems.
higher is betterAs of August 26, 2026Scale: 0% - 100%
Overall
Native reasoning tasks in French, Spanish, and Chinese that were not translated from English templates. Three languages counter English-only evaluation, but they do not represent global language coverage.
higher is betterAs of August 26, 2026Scale: 0% - 100%
Overall
600 realistic finance questions with weighted criteria, including a 300-question hard subset. An o4-mini judge scores the responses, so domain correctness and operational reliability remain separate questions.
higher is betterAs of August 26, 2026Scale: 0% - 100%
Overall
500 realistic legal questions with weighted criteria across jurisdictions and practice areas. The benchmark measures professional response quality but cannot replace legal review or human accountability.
higher is betterAs of August 26, 2026Scale: 0% - 100%
Overall
1,490 tasks test adaptive explanations, feedback, and hints across six STEM subjects. A Claude 4 Sonnet judge scores weighted rubrics, so strong results do not prove safe tutoring of real learners.
higher is betterAs of August 26, 2026Scale: 0% - 100%
Overall
758 image-text tasks combine OCR, spatial understanding, object recognition, and open-ended visual reasoning. The dataset is private and uses task-specific rubrics, making independent reproduction difficult.
higher is betterAs of August 26, 2026Scale: 0% - 100%
These measurements have no matching peer values under the same test conditions. Their original values and sources remain available here.
Page 1 of 2
One SVG prompt and fixed output settings. Captures are shown only with 0 reported reasoning tokens or documented lack of reasoning controls. Identical test conditions do not make the models' internal compute identical.
No independent attempt was planned for this model.
A community classic for free-form SVG drawing.
o3-pro
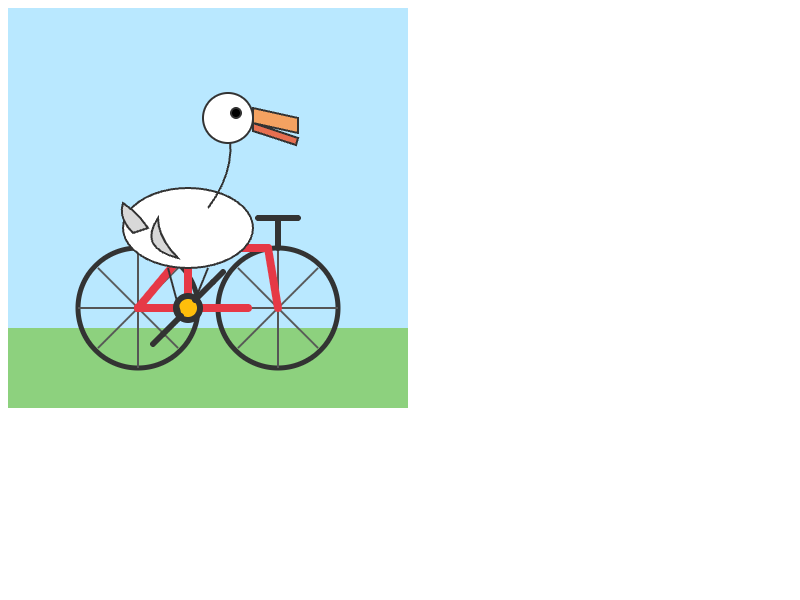
Reasoning (requested): high
Visually reviewed. This individual test does not establish overall model quality.
Generate an SVG of a pelican riding a bicycle
Token limit including reasoning: 8,192 tokens
Task origin (Simon Willison)25.5 / 100
| Type | Evidence and data date |
|---|---|
| Price | Base API prices without caching or batch discounts. Higher context tiers and other rates are listed under Costs. |
| Input | Documented modalities. Retrieved September 8, 2026. |
| Output | Documented modalities. Retrieved September 8, 2026. |
| Research status | Research date September 8, 2026. 7 source URLs checked. This documents the inspected sources, not an exhaustive inventory of every publication. |
| Not found in the inspected sources | independent-benchmarks Original wording The recorded o3-pro benchmark rows are official vendor evaluations; no independent evaluator row was merged. |
| Not found in the inspected sources | parameters-billions Original wording OpenAI does not publish parameter counts. |
| Not found in the inspected sources | AA benchmark rows Original wording No exact-model row in the selected public JSON-LD datasets (some pages only expose N/A or unknown metric summaries). |
| Additional source | Aider (retrieved September 2, 2026) |
| Additional source | Scale AI (retrieved August 26, 2026) |
| Additional source | Scale AI (retrieved August 26, 2026) |
| Additional source | Scale AI (retrieved August 26, 2026) |
| Additional source | Scale AI (retrieved August 26, 2026) |
| Additional source | Scale AI (retrieved August 26, 2026) |
| Additional source | Scale AI (retrieved August 26, 2026) |
| Additional source | OpenAI (retrieved September 8, 2026) |
| Additional source | OpenAI (retrieved September 8, 2026) |
| Additional source | OpenAI (retrieved September 8, 2026) |
| Additional source | Model metadata (retrieved September 8, 2026) |
| Additional source | Introducing OpenAI o3 and o4-mini · Editorial description reviewed October 2, 2026 |
| Additional source | OpenRouter: Popularity index (derived), CC BY 4.0 |
| Additional source | Vercel AI Gateway: Popularity index (derived), CC BY 4.0 |
| Additional source | Creative Commons Attribution 4.0 |
| Additional source | OpenAI o3-pro rollout announcement (2026-09-19) |
| Additional source | OpenAI, "Introducing GPT-5" (2026-09-22) |