
InclusionAILanguage modelActive

Ling 3.1 Flash

Ling 3.1 Flash has no overall index value yet because there are too few independent benchmark results.

Intelligencenot ranked yet

n/aOverall indexhigher is better

SpeedRank 15 of 101

174Tokens per secondhigher is better

Priceno API price

n/aper 1M tokenslower is better

ContextRank 31 of 102

1Mtokens at once≈ 1,500 A4 pages

PopularityRank 236 of 875

42out of 100+1 vs. last month

Summary

At 174 tokens per second it writes faster than a typical model (87).

Ling 3.1 Flash activates 25 billion of its 560 billion parameters per token. InclusionAI’s hybrid reasoning model handles 262K context tokens on Vercel AI Gateway.

The model card lists MIT for the weights and a 1M-token context for the checkpoint. Vercel AI Gateway offers the model through a separate API route with 262K context tokens.

See for yourself: one prompt, one attempt

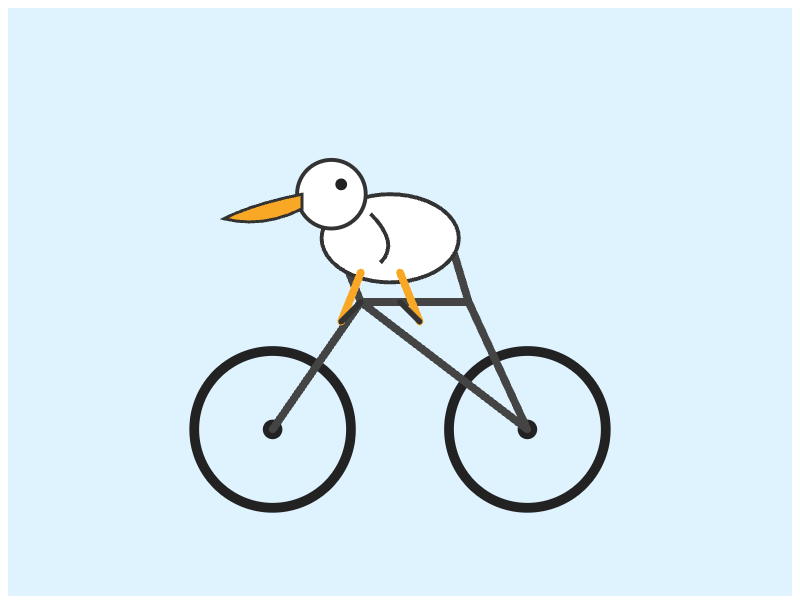
SVG short test

One SVG task with the same fixed settings for every model, without hidden thinking.

Ling 3.1 Flash

Ling 3.1 Flash: SVG short test

Prompt

Return only one standalone SVG of a pelican riding a bicycle. Use viewBox="0 0 800 600", simple shapes, two clearly visible wheels and a recognizable pelican with a long beak. At most 30 SVG elements and 1800 characters. No Markdown, explanations, comments, scripts, animation, CSS or external resources.

Oct 14, 2026 · $0.0002

Test details
Test run
Oct 14, 2026
Provider
novita
API model
inclusionai/ling-3.1-flash
Output
667 tokens
Reasoning
API reports 0 reasoning tokens
Cost of the attempt
$0.0002
Test round
43b8c5c46830
Earlier tests

API access was unavailable for this run. The model was not evaluated.

Pelican on a bicycle

Prompt

Generate an SVG of a pelican riding a bicycle

Oct 5, 2026

Not yet visually reviewed. A successful recording does not confirm correct physics or full compliance with the prompt.

Test details
Run date
Oct 5, 2026
API provider
openrouter
Requested API model
inclusionai/ling-3.1-flash
Reasoning setting
high
Token limit including reasoning
8,192 tokens
Pinned endpoint
Novita | inclusionai/ling-3.1-flash-20261002
Temperature
Provider default
Test protocol
community-visual-tests-v1
Technical checks
Not run
Task origin: Simon Willison

All benchmark results

Every published result with its source, test setup and comparison models.

Show all 75 published benchmark results

Page 1 of 7

Measurements without matching peer values

These measurements have no matching peer values under the same test conditions. Their original values and sources remain available here.

CritPt v2: Overall (Show measurement, test conditions, and source)
Source value
18
Score
18
Metric
pass@1 accuracy
Unit
%
Benchmark version
v2
Category
reasoning
Task
overall
Task label
Overall
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Artificial Analysis
Status
disputed
Retrieved at
2026-11-02
Methodology
Exact AA configuration: Ling 3.1 Flash (release ling-3-1-flash, row ling-3-1-flash, UUID a6043b9b-628a-4a76-a021-2834e0627d05, reasoning=true, effort=not specified, suffix=not specified). AA source value for average reasoning tokens before the answer: 2000. Its methodology averages 60 varied prompts and assumes 2,000 when no average is available. This is not a token cap. The full CritPt v2 run covers 70 questions with five repeats. The official grading server reports pass@1.. Source model ID: artificial-analysis/a6043b9b-628a-4a76-a021-2834e0627d05/ling-3-1-flash/ling-3-1-flash. Source model name: Ling 3.1 Flash. Provider reported by source: InclusionAI. Model snapshot: Ling 3.1 Flash. Evaluator: Artificial Analysis. Dataset type: artificial-analysis-evaluation. Tool policy: Python functions, symbolic expressions, and numerical answers; official grading server. Attempts: 70 questions, five repeats per question, pass@1. Reasoning: reasoning enabled. Score display: 18.0%. Source ID: artificial-analysis. Evidence capture ID: aa-model-page-2026-11-02-67d46be20a5b. Source payload hash: 67d46be20a5b412db6cfb60ad190441fcaa5513500b8fd47d033168d0e97b6b2. Parser version: artificial-analysis-rsc-models-v3. Imported at: 2026-11-02. Source cohort: artificial-analysis-critpt-v2:v2:standalone:reasoning:effort=unspecified:suffix=unspecified
Comparison methodology
Exact AA configuration: Ling 3.1 Flash (release ling-3-1-flash, row ling-3-1-flash, UUID a6043b9b-628a-4a76-a021-2834e0627d05, reasoning=true, effort=not specified, suffix=not specified). AA source value for average reasoning tokens before the answer: 2000. Its methodology averages 60 varied prompts and assumes 2,000 when no average is available. This is not a token cap. The full CritPt v2 run covers 70 questions with five repeats. The official grading server reports pass@1.. Tool policy: Python functions, symbolic expressions, and numerical answers; official grading server. Attempts: 70 questions, five repeats per question, pass@1. Reasoning: reasoning enabled
Context
This AA source field contains the original CritPt score. The earlier CritPt v2 attribution was incorrect; the value and former label remain as disputed historical evidence.. The source dataset marks this result as disputed. It remains visible as documented evidence, but is not reliable comparative proof.
Source Artificial Analysis
GSM8K completion stop rate (Show measurement, test conditions, and source)
Source value
99.77
Score
99.77
Metric
completion stop rate, H200 NEXTN Low-Latency
Unit
%
Direction
No direction published
Source type
independent-evaluator
Evaluator
SGLang Documentation, Ling-3.1-flash cookbook
Status
active
Retrieved at
2026-10-19
Methodology
Independent evaluation. SGLang GSM8K completion stop-rate figure for the H200 NEXTN Low-Latency recipe. The same section instructs evaluating all 1,319 questions, but the published stop-rate line does not state the completed-run denominator, repeats, or CI.
Context
This is a generation stop/completion-rate check, not GSM8K answer accuracy. The source does not report the completed-run denominator, repeats, or CI for the displayed stop-rate figure.
Source SGLang Documentation, Ling-3.1-flash cookbook
GSM8K completion stop rate (Show measurement, test conditions, and source)
Source value
99.92
Score
99.92
Metric
completion stop rate, H200 NEXTN High-Throughput
Unit
%
Direction
No direction published
Source type
independent-evaluator
Evaluator
SGLang Documentation, Ling-3.1-flash cookbook
Status
active
Retrieved at
2026-10-19
Methodology
Independent evaluation. SGLang GSM8K completion stop-rate figure for the H200 NEXTN High-Throughput recipe. The same section instructs evaluating all 1,319 questions, but the published stop-rate line does not state the completed-run denominator, repeats, or CI.
Context
This is a generation stop/completion-rate check, not GSM8K answer accuracy. The source does not report the completed-run denominator, repeats, or CI for the displayed stop-rate figure.
Source SGLang Documentation, Ling-3.1-flash cookbook
GDPval-AA: Overall (Show measurement, test conditions, and source)
Source value
1626.38
Score
1626.38
Metric
GDPval-AA Elo
Unit
Elo
Benchmark version
v2.1
Category
agentic
Task
overall
Task label
Overall
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Artificial Analysis
Status
superseded
Retrieved at
2026-11-02
Methodology
Exact AA configuration: Ling 3.1 Flash (release ling-3-1-flash, row ling-3-1-flash, UUID a6043b9b-628a-4a76-a021-2834e0627d05, reasoning=true, effort=not specified, suffix=not specified). AA source value for average reasoning tokens before the answer: 2000. Its methodology averages 60 varied prompts and assumes 2,000 when no average is available. This is not a token cap. 220 tasks with one run each. AA scores outcomes through pairwise panel comparisons and anchors the Elo scale at DeepSeek V4.1 Flash (Max) at 1,600.. Source model ID: artificial-analysis/a6043b9b-628a-4a76-a021-2834e0627d05/ling-3-1-flash/ling-3-1-flash. Source model name: Ling 3.1 Flash. Provider reported by source: InclusionAI. Model snapshot: Ling 3.1 Flash. Evaluator: Artificial Analysis. Dataset type: artificial-analysis-evaluation. Harness: Artificial Analysis Stirrup. Agent: Stirrup agent. Tool policy: Agentic task completion with file outputs. Attempts: 220 tasks, one run per task; panel pairwise judgments. Reasoning: reasoning enabled. Source ID: artificial-analysis. Evidence capture ID: aa-model-page-2026-11-02-67d46be20a5b. Source payload hash: 67d46be20a5b412db6cfb60ad190441fcaa5513500b8fd47d033168d0e97b6b2. Parser version: artificial-analysis-rsc-models-v3. Imported at: 2026-11-02. Source cohort: artificial-analysis-gdpval-aa:v2.1:standalone:reasoning:effort=unspecified:suffix=unspecified
Comparison methodology
Exact AA configuration: Ling 3.1 Flash (release ling-3-1-flash, row ling-3-1-flash, UUID a6043b9b-628a-4a76-a021-2834e0627d05, reasoning=true, effort=not specified, suffix=not specified). AA source value for average reasoning tokens before the answer: 2000. Its methodology averages 60 varied prompts and assumes 2,000 when no average is available. This is not a token cap. 220 tasks with one run each. AA scores outcomes through pairwise panel comparisons and anchors the Elo scale at DeepSeek V4.1 Flash (Max) at 1,600.. Harness: Artificial Analysis Stirrup. Agent: Stirrup agent. Tool policy: Agentic task completion with file outputs. Attempts: 220 tasks, one run per task; panel pairwise judgments. Reasoning: reasoning enabled
Context
This result is retained as historical evidence and is not interchangeable with current results.
Source Artificial Analysis
GDPval-AA: Overall (Show measurement, test conditions, and source)
Source value
1626.56
Score
1626.56
Metric
GDPval-AA Elo
Unit
Elo
Benchmark version
v2.1
Category
agentic
Task
overall
Task label
Overall
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Artificial Analysis
Status
superseded
Retrieved at
2026-10-29
Methodology
Exact AA configuration: Ling 3.1 Flash (release ling-3-1-flash, row ling-3-1-flash, UUID a6043b9b-628a-4a76-a021-2834e0627d05, reasoning=true, effort=not specified, suffix=not specified). AA source value for average reasoning tokens before the answer: 2000. Its methodology averages 60 varied prompts and assumes 2,000 when no average is available. This is not a token cap. 220 tasks with one run each. AA scores outcomes through pairwise panel comparisons and anchors the Elo scale at DeepSeek V4.1 Flash (Max) at 1,600.. Source model ID: artificial-analysis/a6043b9b-628a-4a76-a021-2834e0627d05/ling-3-1-flash/ling-3-1-flash. Source model name: Ling 3.1 Flash. Provider reported by source: InclusionAI. Model snapshot: Ling 3.1 Flash. Evaluator: Artificial Analysis. Dataset type: artificial-analysis-evaluation. Harness: Artificial Analysis Stirrup. Agent: Stirrup agent. Tool policy: Agentic task completion with file outputs. Attempts: 220 tasks, one run per task; panel pairwise judgments. Reasoning: reasoning enabled. Source ID: artificial-analysis. Evidence capture ID: aa-model-page-2026-10-29-5a1b1cf41cd1. Source payload hash: 5a1b1cf41cd14d4fa7e1b5c737732505ff7f014395c8a19ff9385c13df09b106. Parser version: artificial-analysis-rsc-models-v3. Imported at: 2026-10-29. Source cohort: artificial-analysis-gdpval-aa:v2.1:standalone:reasoning:effort=unspecified:suffix=unspecified
Comparison methodology
Exact AA configuration: Ling 3.1 Flash (release ling-3-1-flash, row ling-3-1-flash, UUID a6043b9b-628a-4a76-a021-2834e0627d05, reasoning=true, effort=not specified, suffix=not specified). AA source value for average reasoning tokens before the answer: 2000. Its methodology averages 60 varied prompts and assumes 2,000 when no average is available. This is not a token cap. 220 tasks with one run each. AA scores outcomes through pairwise panel comparisons and anchors the Elo scale at DeepSeek V4.1 Flash (Max) at 1,600.. Harness: Artificial Analysis Stirrup. Agent: Stirrup agent. Tool policy: Agentic task completion with file outputs. Attempts: 220 tasks, one run per task; panel pairwise judgments. Reasoning: reasoning enabled
Context
This result is retained as historical evidence and is not interchangeable with current results.
Source Artificial Analysis
GDPval-AA: Overall (Show measurement, test conditions, and source)
Source value
1626.38
Score
1626.38
Metric
GDPval-AA Elo
Unit
Elo
Benchmark version
v2.1
Category
agentic
Task
overall
Task label
Overall
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Artificial Analysis
Status
active
Retrieved at
2026-11-06
Methodology
Exact AA configuration: Ling 3.1 Flash (release ling-3-1-flash, row ling-3-1-flash, UUID a6043b9b-628a-4a76-a021-2834e0627d05, reasoning=true, effort=not specified, suffix=not specified). This source capture does not provide an average reasoning-token count. 220 tasks with one run each. AA scores outcomes through pairwise panel comparisons and anchors the Elo scale at DeepSeek V4.1 Flash (Max) at 1,600.. Source model ID: artificial-analysis/a6043b9b-628a-4a76-a021-2834e0627d05/ling-3-1-flash/ling-3-1-flash. Source model name: Ling 3.1 Flash. Provider reported by source: InclusionAI. Model snapshot: Ling 3.1 Flash. Evaluator: Artificial Analysis. Dataset type: artificial-analysis-evaluation. Harness: Artificial Analysis Stirrup. Agent: Stirrup agent. Tool policy: Agentic task completion with file outputs. Attempts: 220 tasks, one run per task; panel pairwise judgments. Reasoning: reasoning enabled. Source ID: artificial-analysis. Evidence capture ID: aa-model-page-2026-11-06-ec1194e008b3. Source payload hash: ec1194e008b3638ef60dbf5249daf9e6047364e22905e745a4af64c5f3f080fe. Parser version: artificial-analysis-rsc-models-v4. Imported at: 2026-11-06. Source cohort: artificial-analysis-gdpval-aa:v2.1:standalone:reasoning:effort=unspecified:suffix=unspecified
Comparison methodology
Exact AA configuration: Ling 3.1 Flash (release ling-3-1-flash, row ling-3-1-flash, UUID a6043b9b-628a-4a76-a021-2834e0627d05, reasoning=true, effort=not specified, suffix=not specified). This source capture does not provide an average reasoning-token count. 220 tasks with one run each. AA scores outcomes through pairwise panel comparisons and anchors the Elo scale at DeepSeek V4.1 Flash (Max) at 1,600.. Harness: Artificial Analysis Stirrup. Agent: Stirrup agent. Tool policy: Agentic task completion with file outputs. Attempts: 220 tasks, one run per task; panel pairwise judgments. Reasoning: reasoning enabled
Source Artificial Analysis
Artificial Analysis Intelligence Index (Show measurement, test conditions, and source)
Source value
41.0906200397391
Score
41.0906200397391
Metric
Artificial Analysis Intelligence Index
Unit
points
Benchmark version
Artificial Analysis Intelligence Index v4.3.2
Category
source-specific
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Artificial Analysis
Status
active
Retrieved at
2026-10-04
Methodology
Independent evaluation. Artificial Analysis independent evaluation on dedicated hardware; the exact page identifies Ling 3.1 Flash as reasoning-enabled with 2,000 reasoning tokens.
Context
Source-specific observation; it is not a shared comparison cohort.
Source Artificial Analysis
AA-Briefcase (Show measurement, test conditions, and source)
Source value
1400.35
Score
1400.35
Metric
AA-Briefcase
Unit
elo
Benchmark version
AA-Briefcase v1.1
Category
source-specific
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Artificial Analysis
Status
active
Retrieved at
2026-10-04
Methodology
Independent evaluation. 91-task agentic knowledge-work evaluation; the AA page describes a combined Elo over rubric pass rate, analytical-quality Elo and presentation Elo.
Context
Source-specific observation; it is not a shared comparison cohort.
Source Artificial Analysis
GDPval-AA (Show measurement, test conditions, and source)
Source value
1621.75
Score
1621.75
Metric
GDPval-AA
Unit
elo
Benchmark version
GDPval-AA v2.1
Category
source-specific
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Artificial Analysis
Status
active
Retrieved at
2026-10-04
Methodology
Independent evaluation. 220 real-world work tasks, agent loop with shell/web access via Stirrup, blind pairwise comparisons; AA evaluator result for the exact Ling 3.1 Flash slug.
Context
Source-specific observation; it is not a shared comparison cohort.
Source Artificial Analysis
AutomationBench-AA (Show measurement, test conditions, and source)
Source value
0.6174373352506193
Score
0.6174373352506193
Metric
AutomationBench-AA
Unit
ratio
Benchmark version
AutomationBench-AA (dataset version 1.0.6 noted on evaluator page)
Category
source-specific
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Artificial Analysis
Status
active
Retrieved at
2026-10-04
Methodology
Independent evaluation. 657 simulated SaaS workflow tasks across six business domains; exact model result from AA's dedicated-hardware evaluator.
Context
Source-specific observation; it is not a shared comparison cohort.
Source Artificial Analysis
Terminal-Bench (Show measurement, test conditions, and source)
Source value
0.333333333333333
Score
0.333333333333333
Metric
Terminal-Bench
Unit
ratio
Benchmark version
Terminal-Bench 4.0
Category
source-specific
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Artificial Analysis
Status
active
Retrieved at
2026-10-04
Methodology
Independent evaluation. AA page states pass@1 averaged over three repeats per task with the mini-swe-agent harness; exact Ling result.
Context
Source-specific observation; it is not a shared comparison cohort.
Source Artificial Analysis
SciCode (Show measurement, test conditions, and source)
Source value
0.540509259259259
Score
0.540509259259259
Metric
SciCode
Unit
ratio
Benchmark version
SciCode current AA implementation
Category
source-specific
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Artificial Analysis
Status
disputed
Retrieved at
2026-10-04
Methodology
Independent evaluation. 288 test-set subproblems from scientist-curated laboratory problems; independent AA evaluation of the exact checkpoint.
Context
Source-specific observation; it is not a shared comparison cohort. The evaluator currently labels this result Under review.
Source Artificial Analysis

Page 1 of 7

Popularity compared

How often the model is searched for, used and mentioned, compared with every model of its category.

Popularity index

The 100 most popular models of this category, 0 to 100, higher is more popular

20 of 101 models

As of November 2026 · Source: gradually.ai popularity index

Over time

Weekly values from October 18, 2026 to November 5, 2026

Ling 3.1 FlashDevstral SmallK2 Horizon 32BNaive-N0.5-FlashGLM-4.6V

All specifications

Architecture

Model class
Hybrid reasoning language model
Source: Model class
Parameters
560 billion total, 25 billion active
Source: Parameters

Input and output

Context window
1,000,000 tokens according to the model card
Source: Context window

Watermarking and provenance

AI watermarking refers to invisible signals embedded in the output. Visible marks and provenance metadata are listed separately. Unknown means there is insufficient evidence for that particular field.

AI watermarking
Unknown
no source
Watermarking technique
Not known
no source

Licence and access

Access
Vercel AI Gateway API
Source: Access
License
MIT
Source: License

API

Model ID
inclusionai/ling-3.1-flash
Source: Model ID

Further details

API context window
262K tokens according to Vercel AI Gateway
Source: API context window
Local inference
Model card documents inference with SGLang and vLLM
Source: Local inference

Prices

No InclusionAI subscription includes this model. Through other providers from ≈ €1.06 a month (Command Code Go, with limited credits). 5 plans in Germany.

PlanMonthly priceNote
Command Code Go≈ €1.06with limited credit
Command Code GOAT≈ €10.60with limited credit
Command Code Pro≈ €21.20with limited credit
Command Code Max 10×≈ €106.02with limited credit
Command Code Max 20×≈ €212.05with limited credit

All plans in the AI subscription comparison

Frequently asked questions about Ling 3.1 Flash

How large is the context window of Ling 3.1 Flash?

1 M tokens. That is how much text Ling 3.1 Flash reads at once, about 1,500 A4 pages.

Page count as a rule of thumb from Artificial Analysis

Context windowTokens the model reads at once · higher is better
Ling 3.1 FlashRank 31 of 1021M
Claude Opus 5.51M
Gemini 4 Carbon1M
Claude Fable 5.11M
Claude Sonnet 5.51M
Muse Wonder Full1M
Claude Opus 51M

How fast is Ling 3.1 Flash?

174 tokens per second. That is faster than a typical model at 87.

Measured by Artificial Analysis on Nov 6, 2026. AA 3.0.0, including time to first token, averaged across available workloads and five days.

SpeedTokens per second · higher is better
Gemini 3 Flash Preview191
Gemini 3.5 Flash184
Gemini 3.6 Flash182
DeepSeek-V4.1-Flash176
Ling 3.1 FlashRank 15 of 101174
DeepSeek V4.1 Flash 1017172
Qwen 3.7 Max165

Can I run Ling 3.1 Flash locally?

Yes, the weights are open. With 560B parameters it needs a lot of memory, more a server than a laptop.

Stated by InclusionAI

Open weights
yes
License
MIT
Parameters
560B
active per token
25B

Where can I use Ling 3.1 Flash?

Not in a InclusionAI subscription. Including other providers that makes 5 plans in Germany.

Subscription comparison, prices in Germany incl. VAT

At InclusionAI

No InclusionAI subscription includes this model.

Through other providers

5 plans from 1 provider, from ≈ €1.06 a month (Command Code Go), with limited credits.

Sources and data date

Show all 28 sources

Benchmark sources at a glance

Which independent evaluators tested this model. This is coverage, not a quality ranking.

EvaluatorTest seriesComposite indicesRecorded active measurements
Artificial Analysis8110

Without vendor claims and historical or disputed results; those stay labelled in the single values.

TypeEvidence and data date
Speed

InclusionAI, Reasoning enabled; effort unspecified. AA 3.0.0, including time to first token, averaged across available workloads and five days. Retrieved November 6, 2026.

Research statusResearch date October 4, 2026. 21 source URLs checked. This documents the inspected sources, not an exhaustive inventory of every publication.
Unresolved

scicode-and-critpt-evaluation-status

Original wording

Artificial Analysis labels the SciCode and CritPt observations Under review. They are retained as disputed observations and do not establish confirmed benchmark coverage.

Not published

score scale, denominator, serving revision and confidence interval

Note

The card does not define chart scales or per-cell sample sizes for these results; no N or CI is inferred.

Not published

GameBench 2 Intensive group

Note

The source reports: Not supported by this model.

Not published

GameBench 2 Balanced group

Note

The source reports: No published result.

Additional sourceVercel AI Gateway Ling 3.1 Flash (retrieved October 3, 2026; October 4, 2026) · Vercel AI Gateway Ling 3.1 Flash · Editorial description reviewed October 25, 2026
Additional sourceInclusionAI Ling 3.1 Flash model card (retrieved October 17, 2026; October 25, 2026) · InclusionAI Ling 3.1 Flash model card · Editorial description reviewed October 25, 2026
Additional sourceArtificial Analysis (retrieved October 4, 2026; November 2, 2026)
Additional sourceArtificial Analysis (retrieved October 4, 2026; October 29, 2026; November 2, 2026; November 6, 2026)
Additional sourceArtificial Analysis (retrieved October 4, 2026)12345678
Additional sourceDataLLM Lab (retrieved October 17, 2026)
Additional sourceMathBench AI, Ling-3.1-flash results (retrieved October 17, 2026)
Additional sourceSGLang Documentation, Ling-3.1-flash cookbook (retrieved October 19, 2026)
Additional sourceDataLLM Lab (retrieved October 17, 2026; October 19, 2026)
Additional sourceDuelLab GameBench 2 model results (retrieved October 28, 2026; November 2, 2026; November 5, 2026)
Additional sourceModel metadata (retrieved October 4, 2026)
Additional sourceModel metadata (retrieved October 17, 2026)12
Additional sourceOpenRouter: Popularity index (derived), CC BY 4.0
Additional sourceVercel AI Gateway: Popularity index (derived), CC BY 4.0
Additional sourceOllama: cumulative downloads for the popularity index
Additional sourceReplicate: cumulative runs for the popularity index
Additional sourceGoogle Trending Now: limited feed selection for Germany and the US
Additional sourceCreative Commons Attribution 4.0