AlibabaLanguage model

Qwen2.5-VL 72B Instruct

Qwen2.5-VL 72B Instruct has no overall index value yet because there are too few independent benchmark results.

PopularityRank 497 of 875

28out of 100same as last month

Summary

Qwen2.5-VL 72B Instruct was released on January 26, 2025. The specific instruct checkpoint is in the Qwen/Qwen2.5-VL-72B-Instruct repository. It analyzes visual documents, recognizes text and layouts, and finds relevant moments in video. Localized image regions can be returned as bounding boxes, points, and structured JSON.

The open model accepts text, images, and video and returns text. The catalog lists 72 billion parameters, 131,072 context tokens, and up to 8,192 output tokens. Instruct fine-tuning targets direct chat and extraction tasks and distinguishes the checkpoint from the base model.

See for yourself: one prompt, one attempt

We show the latest attempt without fixes; it does not count toward the overall index.

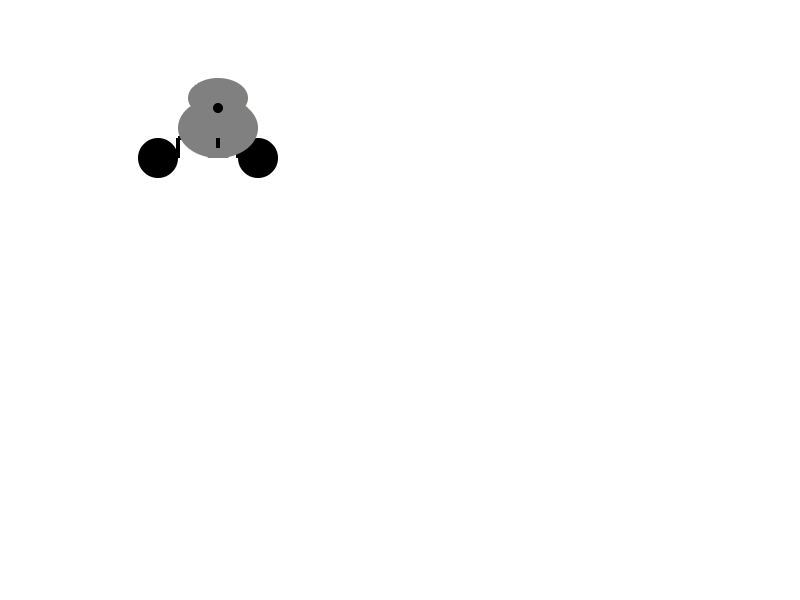
Qwen2.5-VL 72B Instruct: Pelican on a bicycle
A community classic for free-form SVG drawing.

Pelican on a bicycle

Prompt

Generate an SVG of a pelican riding a bicycle

Oct 1, 2026 · 9.2 s · $0.0006

Test details
Run date
Oct 1, 2026
API provider
openrouter
Requested API model
qwen/qwen2.5-vl-72b-instruct
Reasoning setting
not specified
Token limit including reasoning
8,192 tokens
Output tokens
604 tokens
Cost of the attempt
$0.0006
Response time
9.2 s
API model reported in response
qwen/qwen2.5-vl-72b-instruct
Pinned endpoint
Parasail | qwen/qwen2.5-vl-72b-instruct
Temperature
Provider default
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating

Visually reviewed. This individual test does not establish overall model quality.

Task origin: Simon Willison
SVG short test

SVG short test

One SVG task with the same fixed settings for every model, without hidden thinking.

Qwen2.5-VL 72B Instruct

No independent test. This API route aliases qwen-2.5-vl-72b.

All benchmark results

Every published result with its source, test setup and comparison models.

Show all 118 published benchmark results

Page 1 of 10

Measurements without matching peer values

These measurements have no matching peer values under the same test conditions. Their original values and sources remain available here.

AndroidWorld success rate (Show measurement, test conditions, and source)
Source value
35
Score
35
Metric
success rate
Unit
%
Benchmark version
AndroidWorld_SR
Category
agent
Direction
Higher is better
Source type
vendor-reported
Evaluator
Qwen Team Qwen2.5-VL-72B-Instruct model card
Status
active
Retrieved at
2026-10-15
Methodology
Vendor-reported result. Exact Qwen2.5-VL-72B-Instruct model row/widget in Qwen Team Qwen2.5-VL-72B-Instruct model card. Benchmark prompt, sampling/decoding settings, reasoning effort, quantization, and task run date are not stated in the cited result; none are inferred.
Source Qwen Team Qwen2.5-VL-72B-Instruct model card
AEGIS FSD accuracy (Show measurement, test conditions, and source)
Source value
37.63
Score
37.63
Metric
Forgery Scope Discrimination single-choice accuracy (ACC), percent of evaluated cases correct
Unit
%
Benchmark version
AEGIS Table 2; ACL 2026 Long Papers, July 2026
Category
multimodal
Direction
Higher is better
Source type
independent-evaluator
Evaluator
AEGIS, ACL 2026, Table 2
Status
active
Retrieved at
2026-10-16
Methodology
Independent evaluation. AEGIS primary Table 2 result for the exact row “Qwen2.5-VL-72B”. Appendix B.2 lists its access route as https://bailian.console.aliyun.com/cn-beijing?tab=model#/model-market/detail/qwen2.5-vl-72b-instruct?serviceSite=asia-pacific-china. The paper reports high-resolution PNG inputs. Its 8,210-item dataset size is not this metric's N; the per-task denominator, request date, temperature, other decoding settings, and immutable served revision are not published.
Context
This is an AEGIS academic-image-forensics task result, not a general model-quality score. The paper names a model label and access route but does not identify the immutable served revision or request date.
Source AEGIS, ACL 2026, Table 2
AEGIS FSD macro-F1 (Show measurement, test conditions, and source)
Source value
33.16
Score
33.16
Metric
Forgery Scope Discrimination macro-averaged F1, reported as percent
Unit
%
Benchmark version
AEGIS Table 2; ACL 2026 Long Papers, July 2026
Category
multimodal
Direction
Higher is better
Source type
independent-evaluator
Evaluator
AEGIS, ACL 2026, Table 2
Status
active
Retrieved at
2026-10-16
Methodology
Independent evaluation. AEGIS primary Table 2 result for the exact row “Qwen2.5-VL-72B”. Appendix B.2 lists its access route as https://bailian.console.aliyun.com/cn-beijing?tab=model#/model-market/detail/qwen2.5-vl-72b-instruct?serviceSite=asia-pacific-china. The paper reports high-resolution PNG inputs. Its 8,210-item dataset size is not this metric's N; the per-task denominator, request date, temperature, other decoding settings, and immutable served revision are not published.
Context
This is an AEGIS academic-image-forensics task result, not a general model-quality score. The paper names a model label and access route but does not identify the immutable served revision or request date.
Source AEGIS, ACL 2026, Table 2
AEGIS TAR accuracy (Show measurement, test conditions, and source)
Source value
70.81
Score
70.81
Metric
Textual Artifact Recognition accuracy (ACC), percent of evaluated cases correct
Unit
%
Benchmark version
AEGIS Table 2; ACL 2026 Long Papers, July 2026
Category
multimodal
Direction
Higher is better
Source type
independent-evaluator
Evaluator
AEGIS, ACL 2026, Table 2
Status
active
Retrieved at
2026-10-16
Methodology
Independent evaluation. AEGIS primary Table 2 result for the exact row “Qwen2.5-VL-72B”. Appendix B.2 lists its access route as https://bailian.console.aliyun.com/cn-beijing?tab=model#/model-market/detail/qwen2.5-vl-72b-instruct?serviceSite=asia-pacific-china. The paper reports high-resolution PNG inputs. Its 8,210-item dataset size is not this metric's N; the per-task denominator, request date, temperature, other decoding settings, and immutable served revision are not published.
Context
This is an AEGIS academic-image-forensics task result, not a general model-quality score. The paper names a model label and access route but does not identify the immutable served revision or request date.
Source AEGIS, ACL 2026, Table 2
AEGIS TAR macro-F1 (Show measurement, test conditions, and source)
Source value
70.76
Score
70.76
Metric
Textual Artifact Recognition macro-averaged F1, reported as percent
Unit
%
Benchmark version
AEGIS Table 2; ACL 2026 Long Papers, July 2026
Category
multimodal
Direction
Higher is better
Source type
independent-evaluator
Evaluator
AEGIS, ACL 2026, Table 2
Status
active
Retrieved at
2026-10-16
Methodology
Independent evaluation. AEGIS primary Table 2 result for the exact row “Qwen2.5-VL-72B”. Appendix B.2 lists its access route as https://bailian.console.aliyun.com/cn-beijing?tab=model#/model-market/detail/qwen2.5-vl-72b-instruct?serviceSite=asia-pacific-china. The paper reports high-resolution PNG inputs. Its 8,210-item dataset size is not this metric's N; the per-task denominator, request date, temperature, other decoding settings, and immutable served revision are not published.
Context
This is an AEGIS academic-image-forensics task result, not a general model-quality score. The paper names a model label and access route but does not identify the immutable served revision or request date.
Source AEGIS, ACL 2026, Table 2
AEGIS MC accuracy (Show measurement, test conditions, and source)
Source value
51.76
Score
51.76
Metric
Manipulation Classification accuracy (ACC), percent of evaluated cases correct
Unit
%
Benchmark version
AEGIS Table 2; ACL 2026 Long Papers, July 2026
Category
multimodal
Direction
Higher is better
Source type
independent-evaluator
Evaluator
AEGIS, ACL 2026, Table 2
Status
active
Retrieved at
2026-10-16
Methodology
Independent evaluation. AEGIS primary Table 2 result for the exact row “Qwen2.5-VL-72B”. Appendix B.2 lists its access route as https://bailian.console.aliyun.com/cn-beijing?tab=model#/model-market/detail/qwen2.5-vl-72b-instruct?serviceSite=asia-pacific-china. The paper reports high-resolution PNG inputs. Its 8,210-item dataset size is not this metric's N; the per-task denominator, request date, temperature, other decoding settings, and immutable served revision are not published.
Context
This is an AEGIS academic-image-forensics task result, not a general model-quality score. The paper names a model label and access route but does not identify the immutable served revision or request date.
Source AEGIS, ACL 2026, Table 2
AEGIS MC macro-F1 (Show measurement, test conditions, and source)
Source value
35.96
Score
35.96
Metric
Manipulation Classification macro-averaged F1, reported as percent
Unit
%
Benchmark version
AEGIS Table 2; ACL 2026 Long Papers, July 2026
Category
multimodal
Direction
Higher is better
Source type
independent-evaluator
Evaluator
AEGIS, ACL 2026, Table 2
Status
active
Retrieved at
2026-10-16
Methodology
Independent evaluation. AEGIS primary Table 2 result for the exact row “Qwen2.5-VL-72B”. Appendix B.2 lists its access route as https://bailian.console.aliyun.com/cn-beijing?tab=model#/model-market/detail/qwen2.5-vl-72b-instruct?serviceSite=asia-pacific-china. The paper reports high-resolution PNG inputs. Its 8,210-item dataset size is not this metric's N; the per-task denominator, request date, temperature, other decoding settings, and immutable served revision are not published.
Context
This is an AEGIS academic-image-forensics task result, not a general model-quality score. The paper names a model label and access route but does not identify the immutable served revision or request date.
Source AEGIS, ACL 2026, Table 2
AEGIS TP region-level Correct Localization Accuracy (Show measurement, test conditions, and source)
Source value
32.29
Score
32.29
Metric
Tampering Pinpointing region-level Correct Localization Accuracy (CLA), percent of evaluated cases meeting the paper's localization rule
Unit
%
Benchmark version
AEGIS Table 2; ACL 2026 Long Papers, July 2026
Category
multimodal
Direction
Higher is better
Source type
independent-evaluator
Evaluator
AEGIS, ACL 2026, Table 2
Status
active
Retrieved at
2026-10-16
Methodology
Independent evaluation. AEGIS primary Table 2 result for the exact row “Qwen2.5-VL-72B”. Appendix B.2 lists its access route as https://bailian.console.aliyun.com/cn-beijing?tab=model#/model-market/detail/qwen2.5-vl-72b-instruct?serviceSite=asia-pacific-china. The paper reports high-resolution PNG inputs. Its 8,210-item dataset size is not this metric's N; the per-task denominator, request date, temperature, other decoding settings, and immutable served revision are not published.
Context
This is an AEGIS academic-image-forensics task result, not a general model-quality score. The paper names a model label and access route but does not identify the immutable served revision or request date.
Source AEGIS, ACL 2026, Table 2
AEGIS TP Over Localization Rate (Show measurement, test conditions, and source)
Source value
0.53
Score
0.53
Metric
Tampering Pinpointing Over Localization Rate (OLR), percent of cases with excessive predicted regions; lower is better
Unit
%
Benchmark version
AEGIS Table 2; ACL 2026 Long Papers, July 2026
Category
multimodal
Direction
Lower is better
Source type
independent-evaluator
Evaluator
AEGIS, ACL 2026, Table 2
Status
active
Retrieved at
2026-10-16
Methodology
Independent evaluation. AEGIS primary Table 2 result for the exact row “Qwen2.5-VL-72B”. Appendix B.2 lists its access route as https://bailian.console.aliyun.com/cn-beijing?tab=model#/model-market/detail/qwen2.5-vl-72b-instruct?serviceSite=asia-pacific-china. The paper reports high-resolution PNG inputs. Its 8,210-item dataset size is not this metric's N; the per-task denominator, request date, temperature, other decoding settings, and immutable served revision are not published.
Context
This is an AEGIS academic-image-forensics task result, not a general model-quality score. The paper names a model label and access route but does not identify the immutable served revision or request date.
Source AEGIS, ACL 2026, Table 2
MobileMiniWob++ success rate (Show measurement, test conditions, and source)
Source value
68
Score
68
Metric
success rate
Unit
%
Benchmark version
Qwen2.5-VL model card revision 89c86200743eec961a297729e7990e8f2ddbc4c5
Category
agent
Direction
Higher is better
Source type
vendor-reported
Evaluator
Qwen2.5-VL-72B-Instruct model card, Qwen Team
Status
active
Retrieved at
2026-10-17
Methodology
Vendor-reported result. Exact Qwen2.5VL-72B column in the pinned model card agent benchmark table. The card does not report task run date, prompts, decoding settings, quantization, or per-task scored denominator.
Source Qwen2.5-VL-72B-Instruct model card, Qwen Team
Creation-MMBench (Show measurement, test conditions, and source)
Source value
13.2
Score
13.2
Metric
Pairwise win rate versus GPT-4o-1120 baseline
Unit
%
Benchmark version
ICCV 2025 supplement, Table 5
Category
Overall
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Creation-MMBench authors, ICCV 2025 supplement
Status
active
Retrieved at
2026-10-17
Methodology
Independent evaluation. Exact Table 5 row: Qwen2.5-VL-72B-Instruct. Win rate is reported for dual GPT-4o pairwise comparisons against GPT-4o-1120, with response positions swapped. The same table reports six much-better, 196 better, 984 tie, 302 worse, 42 much-worse, and zero failed outcomes.
Context
The reported outcome counts sum to 1,530 judge outcomes from dual evaluations, not independent benchmark cases. No sampleCount is inferred from those counts. The paper does not identify an immutable checkpoint revision, inference route, or model-specific run date.
Source Creation-MMBench authors, ICCV 2025 supplement
GitChameleon 2.0 Qwen 2.5-VL Instruct 72B Greedy decoding hidden success rate (Show measurement, test conditions, and source)
Source value
48.2
Score
48.2
Metric
Greedy decoding hidden success rate
Unit
%
Benchmark version
GitChameleon 2.0, ACL 2026
Category
code-agent
Direction
Higher is better
Sample
328
Source type
independent-evaluator
Evaluator
GitChameleon 2.0, ACL 2026 paper
Status
active
Retrieved at
2026-10-17
Methodology
Independent evaluation. GitChameleon 2.0, exact publicly named model variant. The paper evaluates 328 manually authored version-conditioned Python API-change problems with hidden tests. Model serving revision and complete decoding parameters are not specified. Qwen 2.5-VL Instruct 72B; Table 1 reports greedy decoding, greedy with self-debug, and zero-shot chain-of-thought settings. Hidden/visible test variants are retained separately.
Context
The table prints ± values but does not identify their statistical meaning or confidence level; no CI field is set. The evaluated serving revision is not pinned.
Source GitChameleon 2.0, ACL 2026 paper

Page 1 of 10

Popularity compared

How often the model is searched for, used and mentioned, compared with every model of its category.

Popularity index

The 100 most popular models of this category, 0 to 100, higher is more popular

20 of 101 models

As of November 2026 · Source: gradually.ai popularity index

Over time

Weekly values from October 18, 2026 to November 5, 2026

Qwen2.5-VL 72B InstructGLM-4.7-FlashXMiniMax-M2.7-highspeedOLMo 2 13BQwen3 VL 235B A22B Instruct

All specifications

Architecture

Parameters
72 billion
Source: Parameters
Knowledge Cutoff
April 2024
Source: Knowledge Cutoff

Input and output

Context window
131,072 tokens
Source: Context window
Maximum output
8,192 tokens
Source: Maximum output
Inputs
Text, Image, Video
Source: Inputs
Outputs
Text
Source: Outputs
Tool calling
Yes
Source: Tool calling

Watermarking and provenance

AI watermarking refers to invisible signals embedded in the output. Visible marks and provenance metadata are listed separately. Unknown means there is insufficient evidence for that particular field.

AI watermarking
Unknown
no source
Watermarking technique
Not known
no source

Licence and access

Weights
Open weights
Source: Weights
License
Qwen License
Source: License

Prices

Not included in any subscription in Germany.

All plans in the AI subscription comparison

Frequently asked questions about Qwen2.5-VL 72B Instruct

What is the knowledge cutoff of Qwen2.5-VL 72B Instruct?

April 2024, according to Alibaba. That is 9 months before release.

Stated by Alibaba

How large is the context window of Qwen2.5-VL 72B Instruct?

131,072 tokens. That is how much text Qwen2.5-VL 72B Instruct reads at once, about 200 A4 pages.

Page count as a rule of thumb from Artificial Analysis

Context windowTokens the model reads at once · higher is better
GLM-5.1200K
DeepSeek-V3 0324164K
Qwen2.5-VL 72B InstructRank 93 of 102131K
GLM-4.5131K
GPT OSS 120B131K
DeepSeek-V3.2128K
DeepSeek-R1128K

Can I run Qwen2.5-VL 72B Instruct locally?

Yes, the weights are open.

Stated by Alibaba

Open weights
yes
License
Qwen License
Parameters
72B
active per token
n/a

Sources and data date

Show all 21 sources

Benchmark sources at a glance

Which independent evaluators tested this model. This is coverage, not a quality ranking.

No active result from the reviewed external evaluators can currently be attributed to this model. Other source evidence remains available below.

Without vendor claims and historical or disputed results; those stay labelled in the single values.

TypeEvidence and data date
Input

Documented modalities. Retrieved October 2, 2026.

Output

Documented modalities. Retrieved October 27, 2026.

Research statusResearch date October 15, 2026. 13 source URLs checked. This documents the inspected sources, not an exhaustive inventory of every publication.
Not published

evaluation-protocol

Note

The card publishes benchmark tables but does not provide exact inference prompts, quantization, effort, or run dates for these rows.

Not published

evaluation-denominator

Note

AEGIS reports 8,210 dataset samples overall but does not publish the valid or evaluated denominator for each Table 2 metric.

Unresolved

serving-snapshot

Note

The paper lists a model label and access route but not the evaluation request date or an immutable provider serving revision.

Not published

evaluation-protocol-and-units

Note

The pinned card omits benchmark run dates, task-specific denominators, prompts, and decoding settings. Score units remain unknown except for the explicitly percent-labeled MobileMiniWob++ success rate.

Not published

Creation-MMBench category sample counts and exact model revision

Note

The paper reports 765 overall questions but does not publish category-specific sample counts, a model-specific run date, or an immutable checkpoint revision and inference route.

Additional sourceqwenlm.github.io (retrieved October 2, 2026) · Qwen2.5-VL official release · Editorial description reviewed October 2, 2026
Additional sourceAEGIS, ACL 2026, Table 2 (retrieved October 16, 2026)
Additional sourceQwen2.5-VL-72B-Instruct model card, Qwen Team (retrieved October 17, 2026)
Additional sourceCreation-MMBench authors, ICCV 2025 (retrieved October 17, 2026)
Additional sourceCreation-MMBench authors, ICCV 2025 supplement (retrieved October 17, 2026)
Additional sourceGitChameleon 2.0, ACL 2026 paper (retrieved October 17, 2026)
Additional sourceBenchmarking large multimodal models for ophthalmic visual question answering with OphthalWeChat (retrieved October 17, 2026)
Additional sourceGeoLaux: A Benchmark for Evaluating MLLMs’ Geometry Performance on Long-Step Problems Requiring Auxiliary Lines (retrieved October 17, 2026)
Additional sourceBeyond Screenshots: Evaluating VLMs’ Understanding of UI Animations (retrieved October 18, 2026)
Additional sourceSciVideoBench authors (retrieved October 19, 2026)
Additional sourceReasonMap project page (retrieved October 23, 2026)
Additional sourceModel metadata (retrieved October 17, 2026)
Additional sourceModel metadata (retrieved October 19, 2026)
Additional sourceOpenRouter: Popularity index (derived), CC BY 4.0
Additional sourceVercel AI Gateway: Popularity index (derived), CC BY 4.0
Additional sourceOllama: cumulative downloads for the popularity index
Additional sourceReplicate: cumulative runs for the popularity index
Additional sourceGoogle Trending Now: limited feed selection for Germany and the US
Additional sourceCreative Commons Attribution 4.0