OpenAIMistral AILLM matchup

GPT-5.4vs.Mistral Large 3

Which one is better?

GPT-5.4 performs better than Mistral Large 3, but costs 5 times (input) and 10 times (output) as much.

GPT-5.4 ahead
IntelligenceOverall index, 100 points = average
86.4

GPT-5.4

Rank 50

32.7

Mistral Large 3

Rank 95

about as fast
SpeedTokens per second
64

GPT-5.4

60

Mistral Large 3

Mistral Large 3 cheaper
Price$ per 1M tokens
$5.63

GPT-5.4

$0.75

Mistral Large 3

Popularity0 to 100
n/a

GPT-5.4

48

Mistral Large 3

Rank 145 of 508

Above 272,000 tokens of context, GPT-5.4 costs more: $5 input and $22.50 output per 1M tokens.

Choose GPT-5.4 for

MultimodalCodingFinance

No clear advantage for Mistral Large 3.

Where is the difference?

GPT-5.4 is ahead in 3 of 10 areas, Mistral Large 3 in none.

GPT-5.4 ahead: 3too little data: 7

Areas in the overall index
MultimodalGPT-5.4 +5688.8 to 32.8
CodingGPT-5.4 +5385.0 to 31.9
Agentstoo little data90.5 to 34.3
Reasoningtoo little data87.9 to 34.3
Generaltoo little data86.1 to 33.4
Knowledgetoo little data87.0 to 38.4
Mathematicsonly Mistral Large 3 has a score
Specialist fields
FinanceGPT-5.4 +4585.9 to 41.3
Healthtoo little data80.4 to 30.9
Legaltoo little data83.9 to 39.7

Bar length shows the gap in index points (full width 15 points, one standard deviation of the reference group). Solid means clearly ahead, hatched not certain yet, a thin grey bar level.

Which model for which task?

Everyday tasks, translated from the area values above. Each row names the values it rests on.

Writing and debugging codeGPT-5.4Coding 85.0 to 31.9
Maths and data analysisopenMathematics without a score for GPT-5.4, Reasoning 87.9 to 34.3 (too little data)
Facts and researchopenKnowledge 87.0 to 38.4 (too little data)
Agents and workflowsopenAgents 90.5 to 34.3 (too little data)
Fast chat repliesabout the same64 to 60 tokens per second
Many requests on a small budgetMistral Large 3$5.63 to $0.75 per 1M tokens
Finance, legal and medical textsGPT-5.4Finance 85.9 to 41.3, Legal 83.9 to 39.7 (too little data), Health 80.4 to 30.9 (too little data)
Images, screenshots and PDFsGPT-5.4Multimodal 88.8 to 32.8

GPT-5.4 vs. Mistral Large 3 in our own test

The same prompt for both models. We show the latest attempt without fixes; it does not count toward the overall index.

Pelican on a bicycle

Prompt

Generate an SVG of a pelican riding a bicycle

Task origin: Simon Willison

GPT-5.4

GPT-5.4: Pelican on a bicycle
A community classic for free-form SVG drawing.

Oct 1, 2026 · 117 s · $0.11

Test details
Run date
Oct 1, 2026
API provider
openrouter
Requested API model
openai/gpt-5.4
Reasoning setting
high
Token limit including reasoning
8,192 tokens
Output tokens
7,339 tokens
Cost of the attempt
$0.1101
Response time
116.8 s
API model reported in response
openai/gpt-5.4
Pinned endpoint
OpenAI | openai/gpt-5.4-20260305
Temperature
Provider default
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating

Visually reviewed. This individual test does not establish overall model quality.

Earlier attempts (1)

  • Sep 7, 2026API request failedReasoning setting: high

Mistral Large 3
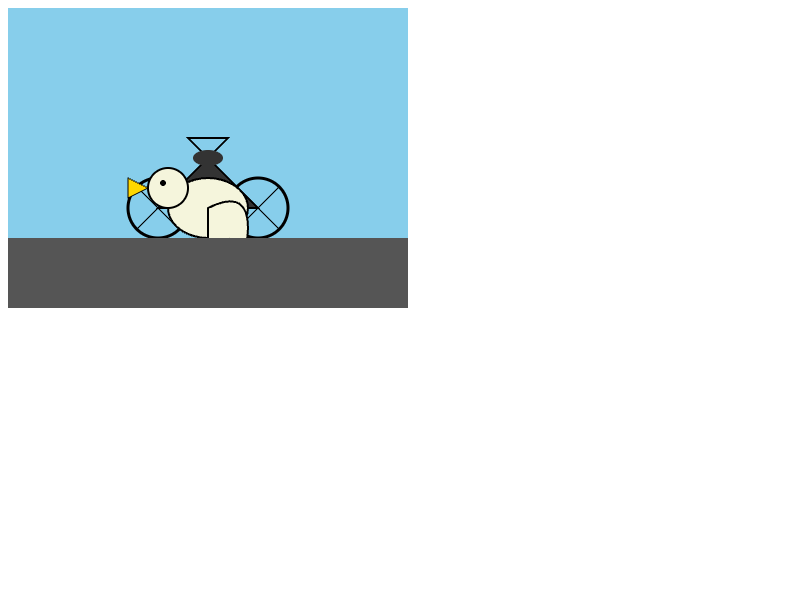
Mistral Large 3: Pelican on a bicycle
A community classic for free-form SVG drawing.

Oct 1, 2026 · 14 s · $0.0022

Test details
Run date
Oct 1, 2026
API provider
openrouter
Requested API model
mistralai/mistral-large-2512
Reasoning setting
not specified
Token limit including reasoning
8,192 tokens
Output tokens
1,451 tokens
Cost of the attempt
$0.0022
Response time
14.2 s
API model reported in response
mistralai/mistral-large-2512
Pinned endpoint
Mistral | mistralai/mistral-large-2512
Temperature
Provider default
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating
Reasoning (model default)
no reasoning mode Source

Visually reviewed. This individual test does not establish overall model quality.

Earlier attempts (1)

  • Sep 7, 2026API request failedReasoning setting: not specified
SVG short test

SVG short test

One SVG task with the same fixed settings for every model, without hidden thinking.

Prompt

Return only one standalone SVG of a pelican riding a bicycle. Use viewBox="0 0 800 600", simple shapes, two clearly visible wheels and a recognizable pelican with a long beak. At most 30 SVG elements and 1800 characters. No Markdown, explanations, comments, scripts, animation, CSS or external resources.

GPT-5.4

Unavailable in this round

Mistral Large 3

API request failed. The model was not evaluated.

GPT-5.4 and Mistral Large 3 in the overall index

Every model with a place in the overall index, both models of this matchup highlighted. You can add or hide other models.

Overall index (Gradually Meta-Score v6)

20 of 95 models

Claude Fable 5.2max130.9
Gemini 4 Carbonhigh127.0
Claude Opus 5.5max125.7
Claude Fable 5.1max124.1
Claude Sonnet 5.5max121.9
Gemini 4 Argonhigh121.2
GPT-6 Astramax119.6
Muse Wonder Fullmax118.4
GPT-6.1 Solmax117.5
Claude Opus 5max117.3
Muse Wondermax113.7
Claude Fable 5max112.8
Kimi K3.1 Promax112.6
Muse Ember 1.0max110.5
GPT-5.6 Solmax109.3
GPT-6 Solmax108.4
Gemini 3.7 Flashhigh107.7
DeepSeek V4.1 Flash 1017max107.1
GPT-5.4xhigh86.4
Mistral Large 3none32.7

Popularity compared

How often the models are searched for, used and mentioned, on a scale from 0 to 100.

GPT-5.4 has no popularity score yet.

Over time

Weekly values from October 18, 2026 to November 16, 2026

GPT-5.4Mistral Large 3

All data side by side

The better value is bold. For the overall index only when the gap is clear.

MetricGPT-5.4Mistral Large 3
Intelligence
Overall indexpoints, 100 = reference group average, higher is better86.432.7
RankRank 50 of 95Rank 95 of 95
Price per 1M tokens
Inputwhat you send$2.50above 272,000 tokens: $5$0.50
Outputwhat the model writes$15above 272,000 tokens: $22.50$1.50
Cost per task (own tests)average of 1 original-protocol task both models passed (SVG short test not included)$0.11$0.002
Speed
Tokens per second6460
Popularity
Popularitysearch, usage and mentions, 0 to 100n/a48Rank 145 of 508
Technical
Context windowhow much text the model reads at once1.05 M tokens≈ 1,580 A4 pages262,144 tokens≈ 390 A4 pages
Knowledge cutoffAug 31, 2025n/a
ReleasedMar 5, 2026Dec 2, 2025
AvailabilityActiveActive
Open weightsnoyes

Prices without caching or batch discounts · Page count as a rule of thumb from Artificial Analysis

Is there a better choice?

Successor of GPT-5.4GPT-5.5

Overall index 101.4, rank 27$5 input and $30 output per 1M tokens

Mistral Large 3 vs. GPT-5.5
Cheaper than Mistral Large 3Muse Ember 1.0

Overall index 110.5, rank 14$0.10 input and $0.50 output per 1M tokens

View profile
Best model in the overall indexClaude Fable 5.2

Overall index 130.9, rank 1$8 input and $40 output per 1M tokens

Shared benchmarks

Single results from the same benchmark version, task and metric. A value is bold only with the same test setup and a clear gap.

A: GPT-5.4B: Mistral Large 3

CorpFin v2Overall · higher is betterTest setup not documented as identicalGPT-5.4: 65.3%Mistral Large 3: 61.0%Vals AIAs of 08/12/2026
GPQA DiamondOverall · higher is betterTest setup not documented as identicalGPT-5.4: 91.7%Mistral Large 3: 68.4%Vals AIAs of 09/01/2026
LegalBenchOverall · higher is betterTest setup not documented as identicalGPT-5.4: 86.0%Mistral Large 3: 79.1%Vals AIAs of 10/13/2026
LiveCodeBenchOverall · higher is betterTest setup not documented as identicalGPT-5.4: 84.1%Mistral Large 3: 55.3%Vals AIAs of 09/01/2026
LMArena Code Arena WebDevOverall · higher is betterGPT-5.4: 1,400Mistral Large 3: 1,231LMArenaAs of 11/15/2026
LMArena Text, Style ControlOverall · higher is betterTest setup not documented as identicalGPT-5.4: 1,475Mistral Large 3: 1,415LMArenaAs of 11/11/2026
LMArena Vision, Style ControlOverall · higher is betterTest setup not documented as identicalGPT-5.4: 1,282Mistral Large 3: 1,200LMArenaAs of 11/09/2026
MedQAOverall · higher is betterTest setup not documented as identicalGPT-5.4: 96.1%Mistral Large 3: 82.2%Vals AIAs of 04/16/2026
MMLU ProOverall · higher is betterTest setup not documented as identicalGPT-5.4: 87.5%Mistral Large 3: 79.8%Vals AIAs of 09/01/2026
MMMU ProOverall · higher is betterTest setup not documented as identicalGPT-5.4: 87.5%Mistral Large 3: 66.2%Vals AIAs of 09/01/2026
Show 54 more benchmarks
MortgageTaxOverall · higher is betterTest setup not documented as identicalGPT-5.4: 68.3%Mistral Large 3: 52.1%Vals AIAs of 09/01/2026
SWE-bench VerifiedOverall · higher is betterTest setup not documented as identicalGPT-5.4: 78.2%Mistral Large 3: 41.4%Vals AIAs of 09/01/2026
TaxEval v2Overall · higher is betterTest setup not documented as identicalGPT-5.4: 74.0%Mistral Large 3: 73.1%Vals AIAs of 09/01/2026
CorpFin v2Exact Pages · higher is betterTest setup not documented as identicalGPT-5.4: 64.1%Mistral Large 3: 59.8%Vals AIAs of 08/12/2026
GPQA DiamondFew-Shot CoT · higher is betterTest setup not documented as identicalGPT-5.4: 91.4%Mistral Large 3: 64.1%Vals AIAs of 09/01/2026
LegalBenchConclusion Tasks · higher is betterTest setup not documented as identicalGPT-5.4: 88.9%Mistral Large 3: 81.0%Vals AIAs of 10/13/2026
LiveCodeBenchEasy · higher is betterTest setup not documented as identicalGPT-5.4: 99.1%Mistral Large 3: 95.3%Vals AIAs of 09/01/2026
LMArena Code Arena WebDevHTML development · higher is betterGPT-5.4: 1,423Mistral Large 3: 1,239LMArenaAs of 11/15/2026
LMArena Text, Style ControlBusiness, management and finance · higher is betterTest setup not documented as identicalGPT-5.4: 1,482Mistral Large 3: 1,411LMArenaAs of 11/11/2026
LMArena Vision, Style ControlChinese · higher is betterTest setup not documented as identicalGPT-5.4: 1,317Mistral Large 3: 1,219LMArenaAs of 11/09/2026
MedQAAsian · higher is betterTest setup not documented as identicalGPT-5.4: 96.2%Mistral Large 3: 82.1%Vals AIAs of 04/16/2026
MMLU ProBiology · higher is betterTest setup not documented as identicalGPT-5.4: 92.9%Mistral Large 3: 88.6%Vals AIAs of 09/01/2026
MortgageTaxNumerical Extraction · higher is betterTest setup not documented as identicalGPT-5.4: 76%Mistral Large 3: 50%Vals AIAs of 09/01/2026
SWE-bench Verified<15 min fix · higher is betterTest setup not documented as identicalGPT-5.4: 88.1%Mistral Large 3: 56.2%Vals AIAs of 09/01/2026
TaxEval v2Correctness · higher is betterTest setup not documented as identicalGPT-5.4: 64.9%Mistral Large 3: 61.6%Vals AIAs of 09/01/2026
CorpFin v2Max Fitting Context · higher is betterTest setup not documented as identicalGPT-5.4: 64.9%Mistral Large 3: 63.8%Vals AIAs of 08/12/2026
GPQA DiamondZero-Shot CoT · higher is betterTest setup not documented as identicalGPT-5.4: 91.9%Mistral Large 3: 72.7%Vals AIAs of 09/01/2026
LegalBenchInterpretation Tasks · higher is betterTest setup not documented as identicalGPT-5.4: 83.9%Mistral Large 3: 76.6%Vals AIAs of 10/13/2026
LiveCodeBenchHard · higher is betterTest setup not documented as identicalGPT-5.4: 67.7%Mistral Large 3: 17.1%Vals AIAs of 09/01/2026
LMArena Code Arena WebDevImage to WebDev · higher is betterGPT-5.4: 1,441Mistral Large 3: 1,362LMArenaAs of 11/15/2026
LMArena Text, Style ControlChinese · higher is betterTest setup not documented as identicalGPT-5.4: 1,505Mistral Large 3: 1,431LMArenaAs of 11/11/2026
LMArena Vision, Style ControlCreative writing with images · higher is betterTest setup not documented as identicalGPT-5.4: 1,264Mistral Large 3: 1,198LMArenaAs of 11/09/2026
MedQABlack · higher is betterTest setup not documented as identicalGPT-5.4: 96.5%Mistral Large 3: 81.9%Vals AIAs of 04/16/2026
MMLU ProBusiness · higher is betterTest setup not documented as identicalGPT-5.4: 91.8%Mistral Large 3: 84.7%Vals AIAs of 09/01/2026
MortgageTaxSemantic Extraction · higher is betterTest setup not documented as identicalGPT-5.4: 60.7%Mistral Large 3: 54.2%Vals AIAs of 09/01/2026
SWE-bench Verified>4 hours · higher is betterTest setup not documented as identicalGPT-5.4: 0.0%Mistral Large 3: 33.3%Vals AIAs of 09/01/2026
TaxEval v2Stepwise Reasoning · higher is betterTest setup not documented as identicalGPT-5.4: 83.0%Mistral Large 3: 84.5%Vals AIAs of 09/01/2026
CorpFin v2Shared Max Context · higher is betterTest setup not documented as identicalGPT-5.4: 66.8%Mistral Large 3: 59.6%Vals AIAs of 08/12/2026
LegalBenchIssue Tasks · higher is betterTest setup not documented as identicalGPT-5.4: 90.5%Mistral Large 3: 81.0%Vals AIAs of 10/13/2026
LiveCodeBenchMedium · higher is betterTest setup not documented as identicalGPT-5.4: 85.6%Mistral Large 3: 53.5%Vals AIAs of 09/01/2026
LMArena Code Arena WebDevWeb development · higher is betterGPT-5.4: 1,400Mistral Large 3: 1,231LMArenaAs of 11/15/2026
LMArena Text, Style ControlCoding · higher is betterTest setup not documented as identicalGPT-5.4: 1,521Mistral Large 3: 1,471LMArenaAs of 11/11/2026
LMArena Vision, Style ControlDiagram understanding · higher is betterTest setup not documented as identicalGPT-5.4: 1,319Mistral Large 3: 1,233LMArenaAs of 11/09/2026
MedQAHispanic · higher is betterTest setup not documented as identicalGPT-5.4: 95.7%Mistral Large 3: 82.8%Vals AIAs of 04/16/2026
MMLU ProChemistry · higher is betterTest setup not documented as identicalGPT-5.4: 91.1%Mistral Large 3: 85.0%Vals AIAs of 09/01/2026
SWE-bench Verified1-4 hours · higher is betterTest setup not documented as identicalGPT-5.4: 50.0%Mistral Large 3: 4.8%Vals AIAs of 09/01/2026
LegalBenchRhetoric Tasks · higher is betterTest setup not documented as identicalGPT-5.4: 82.8%Mistral Large 3: 77.9%Vals AIAs of 10/13/2026
LMArena Text, Style ControlCreative writing · higher is betterTest setup not documented as identicalGPT-5.4: 1,440Mistral Large 3: 1,375LMArenaAs of 11/11/2026
LMArena Vision, Style ControlEnglish · higher is betterTest setup not documented as identicalGPT-5.4: 1,279Mistral Large 3: 1,208LMArenaAs of 11/09/2026
MedQAIndigenous · higher is betterTest setup not documented as identicalGPT-5.4: 95.9%Mistral Large 3: 81.8%Vals AIAs of 04/16/2026
MMLU ProComputer Science · higher is betterTest setup not documented as identicalGPT-5.4: 89.8%Mistral Large 3: 83.2%Vals AIAs of 09/01/2026
SWE-bench Verified15 min - 1 hour · higher is betterTest setup not documented as identicalGPT-5.4: 76.2%Mistral Large 3: 36.4%Vals AIAs of 09/01/2026
LegalBenchRule Tasks · higher is betterTest setup not documented as identicalGPT-5.4: 84.0%Mistral Large 3: 79.1%Vals AIAs of 10/13/2026
LMArena Text, Style ControlEnglish · higher is betterTest setup not documented as identicalGPT-5.4: 1,476Mistral Large 3: 1,427LMArenaAs of 11/11/2026
LMArena Vision, Style ControlHomework · higher is betterTest setup not documented as identicalGPT-5.4: 1,330Mistral Large 3: 1,203LMArenaAs of 11/09/2026
MedQAUnbiased · higher is betterTest setup not documented as identicalGPT-5.4: 96.3%Mistral Large 3: 82.2%Vals AIAs of 04/16/2026
MMLU ProEconomics · higher is betterTest setup not documented as identicalGPT-5.4: 89.7%Mistral Large 3: 85.8%Vals AIAs of 09/01/2026
LMArena Text, Style ControlEntertainment, sports and media · higher is betterTest setup not documented as identicalGPT-5.4: 1,441Mistral Large 3: 1,373LMArenaAs of 11/11/2026
LMArena Vision, Style ControlHumor · higher is betterTest setup not documented as identicalGPT-5.4: 1,267Mistral Large 3: 1,186LMArenaAs of 11/09/2026
MedQAWhite · higher is betterTest setup not documented as identicalGPT-5.4: 96.1%Mistral Large 3: 82.8%Vals AIAs of 04/16/2026
MMLU ProEngineering · higher is betterTest setup not documented as identicalGPT-5.4: 85.2%Mistral Large 3: 74.9%Vals AIAs of 09/01/2026
LMArena Text, Style ControlExcluding ties · higher is betterTest setup not documented as identicalGPT-5.4: 1,484Mistral Large 3: 1,402LMArenaAs of 11/11/2026
LMArena Vision, Style ControlOptical character recognition · higher is betterTest setup not documented as identicalGPT-5.4: 1,297Mistral Large 3: 1,214LMArenaAs of 11/09/2026
MMLU ProHealth · higher is betterTest setup not documented as identicalGPT-5.4: 82.4%Mistral Large 3: 77.3%Vals AIAs of 09/01/2026

More comparisons

Compare GPT-5.4 and Mistral Large 3 with the models people compare them with most often.

Compare another matchup