Claude Opus 4.6
Head-to-head comparison
Compare published benchmark results from matching versions and cohorts, API pricing, and technical specifications. Any documented test setup differences remain visible.
Specifications
Release date, availability, context window, architecture, and published parameter counts at a glance. Undisclosed details remain marked as unavailable.
| Attribute | Claude Opus 4.6 | Kimi K3 |
|---|---|---|
| Provider | Anthropic | Moonshot AI |
| Released | Feb 2026 | Jul 16, 2026 |
| Availability | Active | Active |
| Model type | Proprietary | Open Weights |
| Parameters | Not published | 2.8T, 104B active |
| Architecture | Not published | Mixture of Experts |
| Context window | 1,000,000 tokens | 1,048,576 tokens |
| Knowledge cutoff | May 2025 | Not published |
| Technical sources | Model, Context | Model |
Pricing
The table compares official standard API rates per 1M tokens, including published cache pricing. Batch, fast, priority, regional surcharges, tool calls, and cloud platform pricing are excluded.
| Price type | Claude Opus 4.6 | Kimi K3 |
|---|---|---|
| API input | $5 | $3 |
| API output | $25 | $15 |
| Cache read | $0.5 | $0.3 |
| Cache write (5 min.) | $6.25 | Not listed |
| Cache write (1 hr.) | $10 | Not listed |
| Price verified | 09/22/2026 Source | 09/22/2026 Source |
Key to the marks:better valuebetter, but not conclusivetie
Direct developer pricing and provider endpoint tariffs routed through OpenRouter are listed separately. Prices are in USD per 1M tokens. Context-dependent direct tiers plus regional, Flex, Priority, and other OpenRouter tariffs remain individually identifiable.
| Model | Provider | Purchase route and tariff | Input per 1M tokens | Output per 1M tokens | Source |
|---|---|---|---|---|---|
| Claude Opus 4.6 | Anthropic | Direct from developerStandard API | Lowest listed price: $5 | Lowest listed price: $25 | Source09/22/2026 |
| Amazon Bedrock | Via OpenRouteramazon-bedrock | Lowest listed price: $5 | Lowest listed price: $25 | Source10/26/2026 | |
| Anthropic | Via OpenRouteranthropic | Lowest listed price: $5 | Lowest listed price: $25 | Source10/26/2026 | |
| Azure | Via OpenRouterazure/global | Lowest listed price: $5 | Lowest listed price: $25 | Source10/26/2026 | |
| Claude Platform on AWS | Via OpenRouterclaude-on-aws | Lowest listed price: $5 | Lowest listed price: $25 | Source10/26/2026 | |
| Via OpenRoutergoogle-vertex/europe | $5.5 | $27.5 | Source10/26/2026 | ||
| Via OpenRoutergoogle-vertex/global | Lowest listed price: $5 | Lowest listed price: $25 | Source10/26/2026 | ||
| Kimi K3 | Moonshot AI | Direct from developerStandard API | $3 | $15 | Source09/22/2026 |
| AkashML | Via OpenRouterakashml/fp4 | $1.2 | $14 | Source10/26/2026 | |
| Alibaba | Via OpenRouteralibaba | $3.45 | $17.25 | Source10/26/2026 | |
| Amazon Bedrock | Via OpenRouteramazon-bedrock/us-east-2 | $3 | $15 | Source10/26/2026 | |
| BaseTen | Via OpenRouterbaseten/fp8 | $3 | $15 | Source10/26/2026 | |
| Chutes | Via OpenRouterchutes/mxfp4 | $1.85 | $9.5 | Source10/26/2026 | |
| Decart | Via OpenRouterdecart/mxfp4 | $1.65 | $8.25 | Source10/26/2026 | |
| DeepInfra | Via OpenRouterdeepinfra/mxfp4 | $2.85 | $14.25 | Source10/26/2026 | |
| DigitalOcean | Via OpenRouterdigitalocean | $2.55 | $12.95 | Source10/26/2026 | |
| Fireworks | Via OpenRouterfireworks | $3 | $15 | Source10/26/2026 | |
| Fireworks | Via OpenRouterfireworks/fast | $4.5 | $22.5 | Source10/26/2026 | |
| Fireworks | Via OpenRouterfireworks/us | $4.5 | $22.5 | Source10/26/2026 | |
| InferenceNet | Via OpenRouterinference-net/fast | $0.5 | $11.88 | Source10/26/2026 | |
| InferenceNet | Via OpenRouterinference-net/fp4 | $0.239 | $10.8 | Source10/26/2026 | |
| InferenceNet | Via OpenRouterinference-net/us | $0.239 | $10.8 | Source10/26/2026 | |
| InferenceNet | Via OpenRouterinference-net/us/fast | $2.24 | $14.519 | Source10/26/2026 | |
| Makora | Via OpenRoutermakora/fp4 | $0.65 | $15 | Source10/26/2026 | |
| Modal | Via OpenRoutermodal/mxfp4 | $3 | $15 | Source10/26/2026 | |
| Moonshot AI | Via OpenRoutermoonshotai/mxfp4 | $3 | $15 | Source10/26/2026 | |
| Morph | Via OpenRoutermorph/fp8 | $1.17 | $18.769 | Source10/26/2026 | |
| Parasail | Via OpenRouterparasail/fp4 | $3 | $15 | Source10/26/2026 | |
| ParetoAlpha | Via OpenRouterpareto-alpha/us | $3 | $15 | Source10/26/2026 | |
| Phala | Via OpenRouterphala | $2.55 | $12.75 | Source10/26/2026 | |
| Relace | Via OpenRouterrelace/fp4 | Lowest listed price: $0.2147 | $7.6972 | Source10/26/2026 | |
| Sail Research | Via OpenRoutersail-research/fp4 | $1.2 | Lowest listed price: $5.5 | Source10/26/2026 | |
| Sail Research | Via OpenRoutersail-research/fp4/us | $1.2 | Lowest listed price: $5.5 | Source10/26/2026 | |
| Wafer | Via OpenRouterwafer | $0.226 | $20 | Source10/26/2026 | |
| Wafer | Via OpenRouterwafer/us | $0.36 | $11.9 | Source10/26/2026 |
Benchmark index
The index combines independent benchmarks on a scale from 0 to 100. A lead only counts when a model comes first in at least 95% of 200 recalculations with randomly redrawn test families. Otherwise both count as level.
Kimi K3 leads in 1 of 5 shared areas. 4 areas are tied.
| Area | Claude Opus 4.6 | Kimi K3 |
|---|---|---|
| Codingtied | 43.8 | 52.2 |
| Agents | 48.0 | 61.7 |
| Financetied | 72.9 | 70.3 |
| Legaltied | 71.5 | 73.4 |
| Healthtied | 63.0 | 68.9 |
Performance
Only published results with the same benchmark version, task, metric, and comparison cohort are paired. Different reasoning levels, agents, harnesses, or output limits appear directly in the table.
Each axis averages directly matched benchmark families. A value of 100 means the stronger value within this pair, not a universal quality score.
Not enough directly matched categories for a reliable radar
Only 0 of at least 5 categories have comparable, direct model measurements. The benchmark tables below show the available evidence without filling missing axes.
Key to the marks:better valuebetter, but not conclusivetie
| Benchmark and task | Claude Opus 4.6 | Kimi K3 | Source |
|---|---|---|---|
LMArena Code Arena WebDevOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Code Arena WebDev Kimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena Code Arena WebDevClaude Opus 4.6: Arena rating from 20,698 published pairwise votes.Kimi K3: Arena rating from 18,644 published pairwise votes. | 1,537.258 95% confidence interval: ±5.345The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | Higher measured value1,655.295 95% confidence interval: ±6.069The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
MedCodeOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 4.6: Compute: max, Temperature: 1, Output limit: 30,000 tokens Kimi K3: Reasoning: max, Temperature: 1, Top P: 0.95, Output limit: 262,144 tokens | 48.244 % | Higher measured value49.357 % | Vals AISource detailsData as of: 10/13/2026 |
MedScribeOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 4.6: Compute: max, Temperature: 1, Output limit: 30,000 tokens Kimi K3: Reasoning: max, Temperature: 1, Top P: 0.95, Output limit: 262,144 tokens | 86.738 % | Higher measured value88.048 % | Vals AISource detailsData as of: 10/13/2026 |
Vibe Code Bench v1.1OverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1.1Metric: accuracyScoring: Higher is betterClaude Opus 4.6: Compute: max, Harness: OpenHands, Temperature: 1, Output limit: 128,000 tokens Kimi K3: Reasoning: max, Harness: OpenHands, Temperature: 1, Top P: 0.95, Output limit: 262,144 tokens | 57.573 % | Higher measured value84.968 % | Vals AISource detailsData as of: 10/12/2026 |
LMArena Code Arena WebDevOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Code Arena WebDev Kimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena Code Arena WebDevClaude Opus 4.6: Arena rating from 19,443 published pairwise votes.Kimi K3: Arena rating from 18,644 published pairwise votes. | 1,546.362 95% confidence interval: ±5.46The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | Higher measured value1,655.295 95% confidence interval: ±6.069The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Code Arena WebDevImage to webdevTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Code Arena WebDev Kimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena Code Arena WebDevClaude Opus 4.6: Arena rating from 8,068 published pairwise votes.Kimi K3: Arena rating from 3,504 published pairwise votes. | 1,538.785 95% confidence interval: ±9.009The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | Higher measured value1,579.165 95% confidence interval: ±10.818The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/09/2026 |
LMArena Code Arena WebDevImage to webdevTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Code Arena WebDev Kimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena Code Arena WebDevClaude Opus 4.6: Arena rating from 7,930 published pairwise votes.Kimi K3: Arena rating from 3,504 published pairwise votes. | 1,542.687 95% confidence interval: ±8.913The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | Higher measured value1,579.165 95% confidence interval: ±10.818The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/09/2026 |
LMArena Code Arena WebDevWebdevTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Code Arena WebDev Kimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena Code Arena WebDevClaude Opus 4.6: Arena rating from 20,698 published pairwise votes.Kimi K3: Arena rating from 18,644 published pairwise votes. | 1,537.258 95% confidence interval: ±5.345The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | Higher measured value1,655.295 95% confidence interval: ±6.069The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Code Arena WebDevWebdevTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Code Arena WebDev Kimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena Code Arena WebDevClaude Opus 4.6: Arena rating from 19,443 published pairwise votes.Kimi K3: Arena rating from 18,644 published pairwise votes. | 1,546.362 95% confidence interval: ±5.46The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | Higher measured value1,655.295 95% confidence interval: ±6.069The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Code Arena WebDevWebdev-htmlTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Code Arena WebDev Kimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena Code Arena WebDevClaude Opus 4.6: Arena rating from 2,623 published pairwise votes.Kimi K3: Arena rating from 2,538 published pairwise votes. | 1,546.218 95% confidence interval: ±12.521The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | Higher measured value1,645.8 95% confidence interval: ±13.981The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Code Arena WebDevWebdev-htmlTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Code Arena WebDev Kimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena Code Arena WebDevClaude Opus 4.6: Arena rating from 2,474 published pairwise votes.Kimi K3: Arena rating from 2,538 published pairwise votes. | 1,558.715 95% confidence interval: ±13.217The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | Higher measured value1,645.8 95% confidence interval: ±13.981The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Code Arena WebDevWebdev-reactTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Code Arena WebDev Kimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena Code Arena WebDevClaude Opus 4.6: Arena rating from 16,319 published pairwise votes.Kimi K3: Arena rating from 12,408 published pairwise votes. | 1,528.416 95% confidence interval: ±5.908The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | Higher measured value1,670.362 95% confidence interval: ±7.159The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Code Arena WebDevWebdev-reactTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Code Arena WebDev Kimi K3: Snapshot: kimi-k3-max, Reasoning: max, Harness: Arena Code Arena WebDevClaude Opus 4.6: Arena rating from 15,177 published pairwise votes.Kimi K3: Arena rating from 12,408 published pairwise votes. | 1,538.872 95% confidence interval: ±6.058The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | Higher measured value1,670.362 95% confidence interval: ±7.159The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
Key to the marks:better valuebetter, but not conclusivetie | |||
Our model tests
One SVG prompt and fixed output settings. Captures are shown only with 0 reported reasoning tokens or documented lack of reasoning controls. Identical test conditions do not make the models' internal compute identical.
Shared test round: 43b8c5c46830
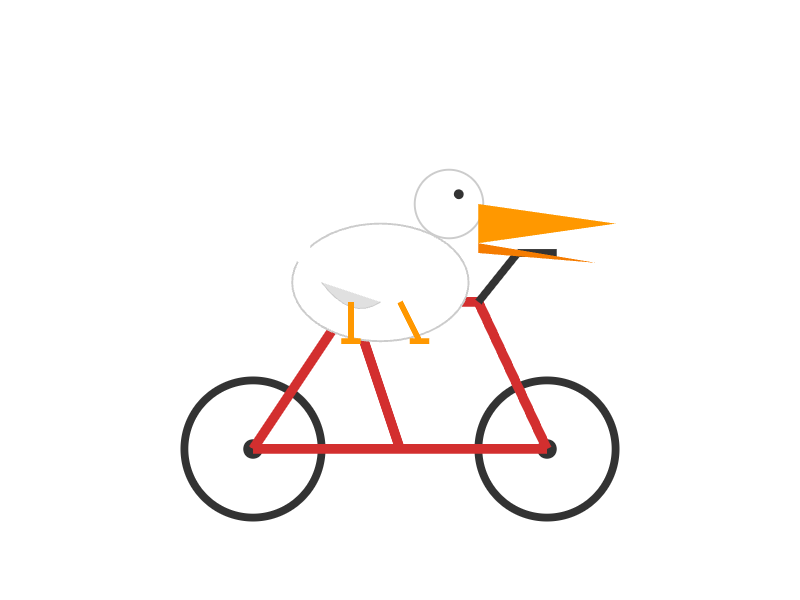
A community classic for free-form SVG drawing.
Claude Opus 4.6
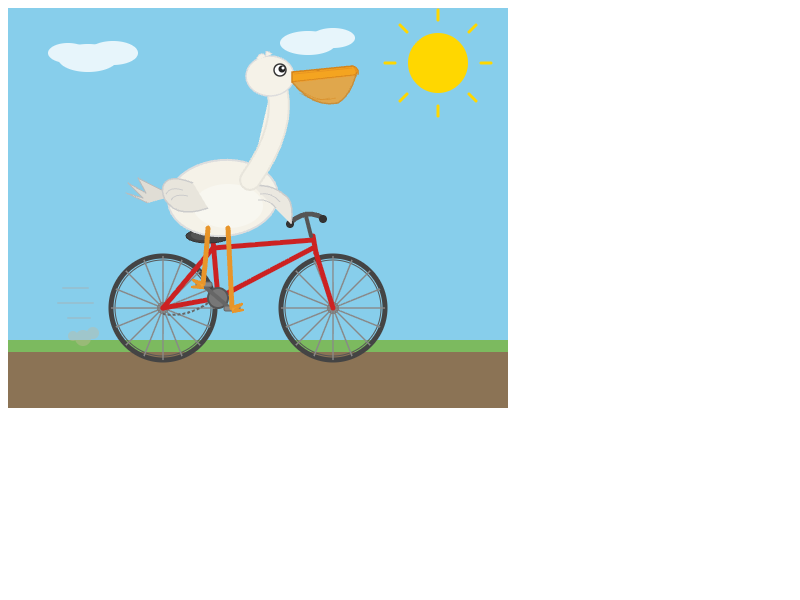
Reasoning (requested): high
Visually reviewed. This individual test does not establish overall model quality.
Kimi K3
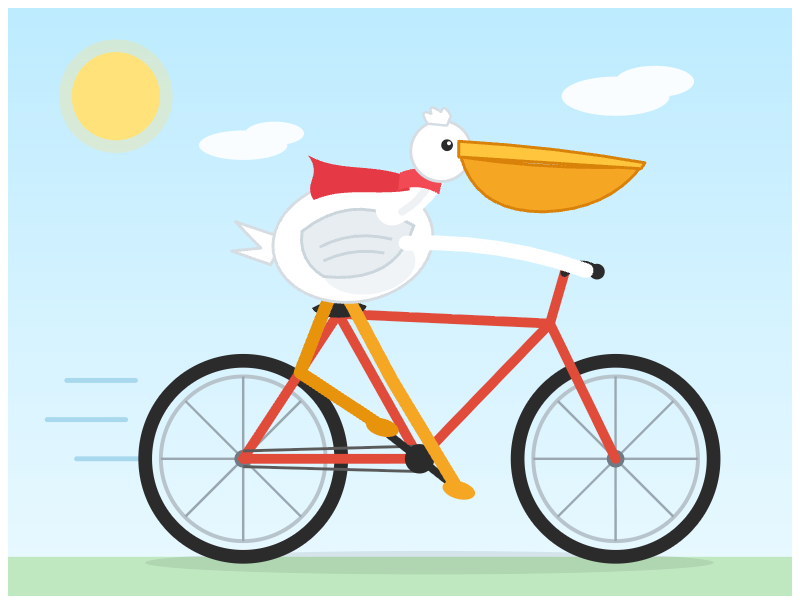
Reasoning (requested): high
Visually reviewed. This individual test does not establish overall model quality.
Generate an SVG of a pelican riding a bicycle
Token limit including reasoning: 8,192 tokens
Task origin (Simon Willison)How to read this comparison
Your workload, budget, and required context length matter most. A coding benchmark says little about visual understanding or agent performance.
The standard price table uses direct developer rates. The provider comparison labels OpenRouter endpoints, regions, and special tariffs separately.
Every result links to its measurement source and retrieval date. Labels distinguish vendor reports, official benchmark leaderboards, and independent evaluations. Disputed or archived results are excluded.
More matchups
Compare Claude Opus 4.6 and Kimi K3 with other leading models using the same data and benchmark logic.