Fireworks ResearchLanguage modelResearch preview

Ember-1

Ember-1 has no overall index value yet because there are too few independent benchmark results. From the vendor-reported results we estimate about 102.5 points (95% range 81.4 to 123.5). This is not an independent measurement.

Intelligenceprovisional, one source only

100.6Overall indexhigher is better

Only test series from Vals AI, not ranked.

Speednot measured

n/ano measurement yet

Priceno API price

n/aper 1M tokenslower is better

Contextn/a

n/atokens in context

Popularityno data yet

n/ano search or usage data

Summary

Ember-1 targets shorter reasoning from Kimi K3. Fireworks post-trained the checkpoint using task feedback and reports 35-50% shorter reasoning without loss of accuracy across seven benchmarks and two customer A/B tests. Fireworks serves Ember-1 through its own API as a time-limited research preview.

Ember-1 in our own test

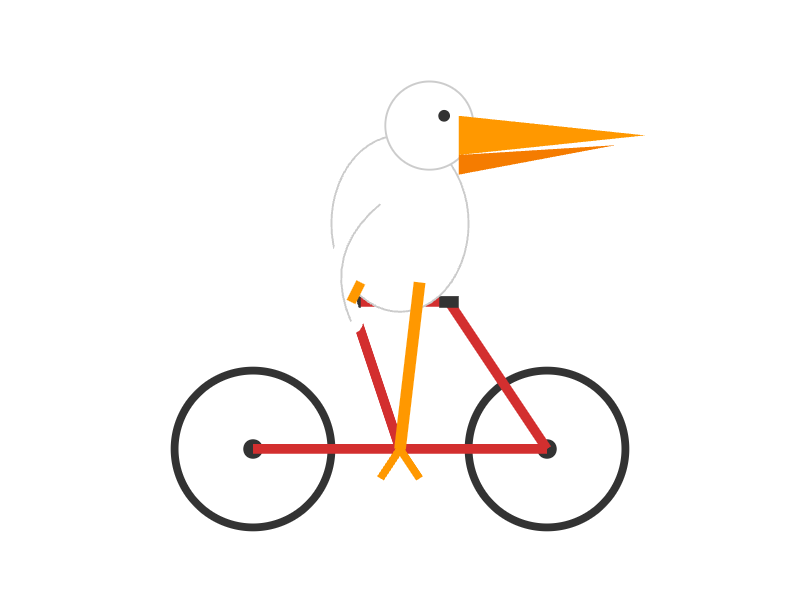
SVG short test

One SVG task with the same fixed settings for every model, without hidden thinking.

Ember-1

Ember-1: SVG short test

Prompt

Return only one standalone SVG of a pelican riding a bicycle. Use viewBox="0 0 800 600", simple shapes, two clearly visible wheels and a recognizable pelican with a long beak. At most 30 SVG elements and 1800 characters. No Markdown, explanations, comments, scripts, animation, CSS or external resources.

Oct 14, 2026 · $0.0079

Test details
Test run
Oct 14, 2026
Provider
fireworks
API model
fireworks/ember-1
Output
511 tokens
Reasoning
API reports 0 reasoning tokens
Cost of the attempt
$0.0079
Test round
43b8c5c46830
Earlier tests

The response reached the token limit. No complete recording is available.

Pelican on a bicycle

Prompt

Generate an SVG of a pelican riding a bicycle

Oct 6, 2026 · 108 s · $0.12

Not yet visually reviewed. A successful recording does not confirm correct physics or full compliance with the prompt.

Test details
Run date
Oct 6, 2026
API provider
openrouter
Requested API model
fireworks/ember-1
Reasoning setting
high
Token limit including reasoning
8,192 tokens
Output tokens
8,192 tokens
Cost of the attempt
$0.1232
Response time
107.5 s
API model reported in response
fireworks/ember-1
Pinned endpoint
Fireworks | fireworks/ember-1-20260923
Temperature
Provider default
Test protocol
community-visual-tests-v1
Technical checks
Failed
Task origin: Simon Willison

All benchmark results

Every published result with its source, test setup and comparison models.

Show all 311 published benchmark results

Page 1 of 26

Measurements without matching peer values

These measurements have no matching peer values under the same test conditions. Their original values and sources remain available here.

BioMysteryBench: Hard (Show measurement, test conditions, and source)
Source value
29.412
Metric
accuracy
Unit
%
Benchmark version
1
Category
general
Task
human_difficult
Task label
Hard
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-07
Methodology
Source model ID: fireworks/ember-1. Source model name: Ember-1. Provider reported by source: Fireworks AI. Evaluator: Vals AI. Dataset type: public. Leaderboard date: 2026-11-05. Harness: Terminus 2. Maximum output tokens: 131072. Latency in seconds: 794.874. Standard error: 6.792. Cost per task in USD: 1.359207. Source ID: vals-ai. Evidence capture ID: vals-biomysterybench-2026-11-07-c2992129e13e. Source payload hash: c2992129e13e1455796b51fe354f18fa049ad9dcfe02fd66196230a60aeea9df. Parser version: vals-astro-v4. Imported at: 2026-11-07. Source cohort: vals-biomysterybench:1:human_difficult
Source Vals AI
BioMysteryBench: Human-solvable (Show measurement, test conditions, and source)
Source value
75.799
Metric
accuracy
Unit
%
Benchmark version
1
Category
general
Task
human_solvable
Task label
Human-solvable
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-07
Methodology
Source model ID: fireworks/ember-1. Source model name: Ember-1. Provider reported by source: Fireworks AI. Evaluator: Vals AI. Dataset type: public. Leaderboard date: 2026-11-05. Harness: Terminus 2. Maximum output tokens: 131072. Latency in seconds: 512.907. Standard error: 2.283. Cost per task in USD: 0.801772. Source ID: vals-ai. Evidence capture ID: vals-biomysterybench-2026-11-07-c2992129e13e. Source payload hash: c2992129e13e1455796b51fe354f18fa049ad9dcfe02fd66196230a60aeea9df. Parser version: vals-astro-v4. Imported at: 2026-11-07. Source cohort: vals-biomysterybench:1:human_solvable
Source Vals AI
BioMysteryBench: Overall (Show measurement, test conditions, and source)
Source value
67.037
Metric
accuracy
Unit
%
Benchmark version
1
Category
general
Task
overall
Task label
Overall
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-07
Methodology
Source model ID: fireworks/ember-1. Source model name: Ember-1. Provider reported by source: Fireworks AI. Evaluator: Vals AI. Dataset type: public. Leaderboard date: 2026-11-05. Harness: Terminus 2. Maximum output tokens: 131072. Latency in seconds: 566.167. Standard error: 3.032. Cost per task in USD: 0.907066. Source ID: vals-ai. Evidence capture ID: vals-biomysterybench-2026-11-07-c2992129e13e. Source payload hash: c2992129e13e1455796b51fe354f18fa049ad9dcfe02fd66196230a60aeea9df. Parser version: vals-astro-v4. Imported at: 2026-11-07. Source cohort: vals-biomysterybench:1:overall
Source Vals AI
Code Migration: CLI (Show measurement, test conditions, and source)
Source value
23.344
Metric
accuracy
Unit
%
Benchmark version
1
Category
coding
Task
cli
Task label
CLI
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-07
Methodology
Source model ID: fireworks/ember-1. Source model name: Ember-1. Provider reported by source: Fireworks AI. Evaluator: Vals AI. Dataset type: private. Leaderboard date: 2026-10-29. Maximum output tokens: 131072. Latency in seconds: 18009.163. Standard error: 2.901. Cost per task in USD: 65.083706. Source ID: vals-ai. Evidence capture ID: vals-code-migration-2026-11-07-23c368426e3e. Source payload hash: 23c368426e3e145dbba17219be86d157ba6ebf3b5c25c8f7ba2d5723986fb9b1. Parser version: vals-astro-v4. Imported at: 2026-11-07. Source cohort: vals-code-migration:1:cli
Source Vals AI
Code Migration: COBOL (Show measurement, test conditions, and source)
Source value
60
Metric
accuracy
Unit
%
Benchmark version
1
Category
coding
Task
cobol
Task label
COBOL
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-07
Methodology
Source model ID: fireworks/ember-1. Source model name: Ember-1. Provider reported by source: Fireworks AI. Evaluator: Vals AI. Dataset type: private. Leaderboard date: 2026-10-29. Maximum output tokens: 131072. Latency in seconds: 5638.286. Standard error: 16.33. Cost per task in USD: 9.192215. Source ID: vals-ai. Evidence capture ID: vals-code-migration-2026-11-07-23c368426e3e. Source payload hash: 23c368426e3e145dbba17219be86d157ba6ebf3b5c25c8f7ba2d5723986fb9b1. Parser version: vals-astro-v4. Imported at: 2026-11-07. Source cohort: vals-code-migration:1:cobol
Source Vals AI
Code Migration: Overall (Show measurement, test conditions, and source)
Source value
32.508
Metric
accuracy
Unit
%
Benchmark version
1
Category
coding
Task
overall
Task label
Overall
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-07
Methodology
Source model ID: fireworks/ember-1. Source model name: Ember-1. Provider reported by source: Fireworks AI. Evaluator: Vals AI. Dataset type: private. Leaderboard date: 2026-10-29. Maximum output tokens: 131072. Latency in seconds: 14916.444. Standard error: 4.626. Cost per task in USD: 51.110833. Source ID: vals-ai. Evidence capture ID: vals-code-migration-2026-11-07-23c368426e3e. Source payload hash: 23c368426e3e145dbba17219be86d157ba6ebf3b5c25c8f7ba2d5723986fb9b1. Parser version: vals-astro-v4. Imported at: 2026-11-07. Source cohort: vals-code-migration:1:overall
Source Vals AI
CyberBench v1.1: Overall (Show measurement, test conditions, and source)
Source value
69.524
Metric
accuracy
Unit
%
Benchmark version
1.1
Category
cybersecurity
Task
overall
Task label
Overall
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-07
Methodology
Source model ID: fireworks/ember-1. Source model name: Ember-1. Provider reported by source: Fireworks AI. Evaluator: Vals AI. Dataset type: private. Leaderboard date: 2026-11-05. Maximum output tokens: 131072. Latency in seconds: 1322.414. Standard error: 5.558. Cost per task in USD: 2.426078. Source ID: vals-ai. Evidence capture ID: vals-cyber-2026-11-07-cc5fe09bf1f8. Source payload hash: cc5fe09bf1f8c926613f8893f823a902fb33f219303590d6a2794e43708d67a5. Parser version: vals-astro-v4. Imported at: 2026-11-07. Source cohort: vals-cyberbench:1.1:overall
Source Vals AI
CyberBench v1.1: Patch (Show measurement, test conditions, and source)
Source value
85.714
Metric
accuracy
Unit
%
Benchmark version
1.1
Category
cybersecurity
Task
patch
Task label
Patch
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-07
Methodology
Source model ID: fireworks/ember-1. Source model name: Ember-1. Provider reported by source: Fireworks AI. Evaluator: Vals AI. Dataset type: private. Leaderboard date: 2026-11-05. Maximum output tokens: 131072. Latency in seconds: 749.952. Standard error: 4.676. Cost per task in USD: 0.997885. Source ID: vals-ai. Evidence capture ID: vals-cyber-2026-11-07-cc5fe09bf1f8. Source payload hash: cc5fe09bf1f8c926613f8893f823a902fb33f219303590d6a2794e43708d67a5. Parser version: vals-astro-v4. Imported at: 2026-11-07. Source cohort: vals-cyberbench:1.1:patch
Source Vals AI
CyberBench v1.1: PoC (Show measurement, test conditions, and source)
Source value
53.333
Metric
accuracy
Unit
%
Benchmark version
1.1
Category
cybersecurity
Task
poc
Task label
PoC
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-07
Methodology
Source model ID: fireworks/ember-1. Source model name: Ember-1. Provider reported by source: Fireworks AI. Evaluator: Vals AI. Dataset type: private. Leaderboard date: 2026-11-05. Maximum output tokens: 131072. Latency in seconds: 1894.876. Standard error: 6.441. Cost per task in USD: 3.854271. Source ID: vals-ai. Evidence capture ID: vals-cyber-2026-11-07-cc5fe09bf1f8. Source payload hash: cc5fe09bf1f8c926613f8893f823a902fb33f219303590d6a2794e43708d67a5. Parser version: vals-astro-v4. Imported at: 2026-11-07. Source cohort: vals-cyberbench:1.1:poc
Source Vals AI
EMB: Comps (Show measurement, test conditions, and source)
Source value
60.496
Metric
accuracy
Unit
%
Benchmark version
1
Category
finance
Task
comps
Task label
Comps
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-07
Methodology
Source model ID: fireworks/ember-1. Source model name: Ember-1. Provider reported by source: Fireworks AI. Evaluator: Vals AI. Dataset type: private. Leaderboard date: 2026-10-20. Maximum output tokens: 131072. Latency in seconds: 1860.074. Standard error: 8.4. Cost per task in USD: 3.11394. Source ID: vals-ai. Evidence capture ID: vals-emb-2026-11-07-58c3d75f6221. Source payload hash: 58c3d75f62214d43f193221a41ce1ca96c1531cd447eb361f50467eb94485fed. Parser version: vals-astro-v4. Imported at: 2026-11-07. Source cohort: vals-emb:1:comps
Source Vals AI
EMB: Dataroom (Show measurement, test conditions, and source)
Source value
81.195
Metric
accuracy
Unit
%
Benchmark version
1
Category
finance
Task
dataroom
Task label
Dataroom
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-07
Methodology
Source model ID: fireworks/ember-1. Source model name: Ember-1. Provider reported by source: Fireworks AI. Evaluator: Vals AI. Dataset type: private. Leaderboard date: 2026-10-20. Maximum output tokens: 131072. Latency in seconds: 1365.657. Standard error: 5.386. Cost per task in USD: 1.491495. Source ID: vals-ai. Evidence capture ID: vals-emb-2026-11-07-58c3d75f6221. Source payload hash: 58c3d75f62214d43f193221a41ce1ca96c1531cd447eb361f50467eb94485fed. Parser version: vals-astro-v4. Imported at: 2026-11-07. Source cohort: vals-emb:1:dataroom
Source Vals AI
EMB: DCF (Show measurement, test conditions, and source)
Source value
50.289
Metric
accuracy
Unit
%
Benchmark version
1
Category
finance
Task
dcf
Task label
DCF
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Vals AI
Status
active
Retrieved at
2026-11-07
Methodology
Source model ID: fireworks/ember-1. Source model name: Ember-1. Provider reported by source: Fireworks AI. Evaluator: Vals AI. Dataset type: private. Leaderboard date: 2026-10-20. Maximum output tokens: 131072. Latency in seconds: 1789.304. Standard error: 10.058. Cost per task in USD: 2.118596. Source ID: vals-ai. Evidence capture ID: vals-emb-2026-11-07-58c3d75f6221. Source payload hash: 58c3d75f62214d43f193221a41ce1ca96c1531cd447eb361f50467eb94485fed. Parser version: vals-astro-v4. Imported at: 2026-11-07. Source cohort: vals-emb:1:dcf
Source Vals AI

Page 1 of 26

All specifications

Architecture

Model class
Specialized language model
Source: Model class

Watermarking and provenance

AI watermarking refers to invisible signals embedded in the output. Visible marks and provenance metadata are listed separately. Unknown means there is insufficient evidence for that particular field.

AI watermarking
Unknown
no source
Watermarking technique
Not known
no source

Licence and access

Access
Fireworks API, time-limited research preview
Source: Access
Shutdown
None announced
no source

API

Model ID
Ember-1
Source: Model ID

Further details

Starting point
Post-trained from Kimi K3
Source: Starting point

Prices

No subscription access recorded in Germany.

All plans in the AI subscription comparison

Frequently asked questions about Ember-1

How good is Ember-1 in benchmarks?

Independent results are not yet enough for the overall index. An estimate from 3 vendor-reported results (DeepSWE v1.1 75.2%, SWE-bench Verified 92.2%, Terminal-Bench 2.1 82%) gives about 102.5 points, with a 95% range of 81.4 to 123.5. The estimate is calibrated on models with both vendor-reported and independent results. Vendor numbers run clearly above independent measurements on some tests; the calibration offsets that on average.

Vendor estimate, not an overall index value

Can I run Ember-1 locally?

No. Fireworks Research does not publish the weights.

Stated by Fireworks Research

Open weights
no
License
n/a
Parameters
n/a
active per token
n/a

Sources and data date

Show all 23 sources

Benchmark sources at a glance

Which independent evaluators tested this model. This is coverage, not a quality ranking.

EvaluatorTest seriesComposite indicesRecorded active measurements
Vals AI171144

Without vendor claims and historical or disputed results; those stay labelled in the single values.

TypeEvidence and data date
Research statusResearch date October 4, 2026. 5 source URLs checked. This documents the inspected sources, not an exhaustive inventory of every publication.
Not published

Vals Science Index component results and scored denominator

Note

The current leaderboard publishes the composite and equal-weight formula but not Ember-1 component values, scored N, or CI.

Additional sourceFireworks Ember-1 announcement (retrieved October 3, 2026; October 4, 2026) · Fireworks Ember-1 announcement · Editorial description reviewed October 4, 2026
Additional sourceVals AI (retrieved November 7, 2026)123456789101112131415
Additional sourceVals AI (retrieved October 16, 2026)12
Additional sourceVals AI (retrieved October 16, 2026; October 31, 2026; November 7, 2026)
Additional sourceVals AI (retrieved October 17, 2026; November 7, 2026)
Additional sourceDuelLab GameBench 2 model results (retrieved October 28, 2026; November 2, 2026; November 5, 2026; November 9, 2026; November 11, 2026; November 12, 2026; November 15, 2026)
Additional sourceParallel Search Capability Leaderboard (retrieved October 28, 2026; November 5, 2026)
Additional sourceParallel Search Capability Leaderboard (retrieved November 5, 2026)