GPT-6 Astra
Unavailable in this round
Head-to-head comparison
Compare published benchmark results from matching versions and cohorts, API pricing, and technical specifications. Any documented test setup differences remain visible.
Specifications
Release date, availability, context window, architecture, and published parameter counts at a glance. Undisclosed details remain marked as unavailable.
| Attribute | GPT-6 Astra | Mistral Large 3 |
|---|---|---|
| Provider | OpenAI | Mistral AI |
| Released | Sep 3, 2026 | Dec 2, 2025 |
| Availability | Limited access | Active |
| Model type | Proprietary | Open Weights |
| Parameters | Not published | 675B, 41B active |
| Architecture | Not published | Mixture of Experts |
| Context window | 1,050,000 tokens | 262,144 tokens |
| Knowledge cutoff | April 30, 2026 | Not published |
| Technical sources | Model, Context | Model, Context |
Pricing
The table compares official standard API rates per 1M tokens, including published cache pricing. Batch, fast, priority, regional surcharges, tool calls, and cloud platform pricing are excluded.
| Price type | GPT-6 Astra | Mistral Large 3 |
|---|---|---|
| API input | $10 ≤272K / $20 >272K | $0.5 |
| API output | $50 ≤272K / $75 >272K | $1.5 |
| Cache read | $1 ≤272K / $2 >272K | Not listed |
| Cache write (5 min.) | $12.5 ≤272K / $25 >272K | Not listed |
| Cache write (1 hr.) | Not listed | Not listed |
| Price verified | 09/22/2026 Source | 09/22/2026 Source |
Key to the marks:better valuebetter, but not conclusivetie
Direct developer pricing and provider endpoint tariffs routed through OpenRouter are listed separately. Prices are in USD per 1M tokens. Context-dependent direct tiers plus regional, Flex, Priority, and other OpenRouter tariffs remain individually identifiable.
| Model | Provider | Purchase route and tariff | Input per 1M tokens | Output per 1M tokens | Source |
|---|---|---|---|---|---|
| GPT-6 Astra | OpenAI | Direct from developerUp to 272,000 context tokens | $10 | $50 | Source09/22/2026 |
| OpenAI | Direct from developerAbove 272,000 context tokens | $20 | $75 | Source09/22/2026 | |
| Amazon Bedrock | Via OpenRouteramazon-bedrock/us-west-2 | $11 | $55 | Source10/19/2026 | |
| Azure | Via OpenRouterazure | $10 | $50 | Source10/19/2026 | |
| Azure | Via OpenRouterazure/us | $11 | $55 | Source10/19/2026 | |
| OpenAI | Via OpenRouteropenai | $10 | $50 | Source10/19/2026 | |
| OpenAI | Via OpenRouteropenai/fast | $20 | $100 | Source10/19/2026 | |
| OpenAI | Via OpenRouteropenai/flex | Lowest listed price: $5 | Lowest listed price: $25 | Source10/19/2026 | |
| OpenAI | Via OpenRouteropenai/ultrafast | $60 | $300 | Source10/19/2026 | |
| Mistral Large 3 | Mistral AI | Direct from developerStandard API | Lowest listed price: $0.5 | Lowest listed price: $1.5 | Source09/22/2026 |
| Mistral | Via OpenRoutermistral/eu | $0.55 | $1.65 | Source10/19/2026 | |
| Mistral | Via OpenRoutermistral/zdr | Lowest listed price: $0.5 | Lowest listed price: $1.5 | Source10/19/2026 |
Performance
Only published results with the same benchmark version, task, metric, and comparison cohort are paired. Different reasoning levels, agents, harnesses, or output limits appear directly in the table.
Each axis averages directly matched benchmark families. A value of 100 means the stronger value within this pair, not a universal quality score.
Not enough directly matched categories for a reliable radar
Only 0 of at least 5 categories have comparable, direct model measurements. The benchmark tables below show the available evidence without filling missing axes.
Key to the marks:better valuebetter, but not conclusivetie
| Benchmark and task | GPT-6 Astra | Mistral Large 3 | Source |
|---|---|---|---|
LMArena Code Arena WebDevOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Code Arena WebDev Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Code Arena WebDevGPT-6 Astra: Arena rating from 5,746 published pairwise votes.Mistral Large 3: Arena rating from 839 published pairwise votes. | Higher measured value1,780.244 95% confidence interval: ±10.541The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,230.205 95% confidence interval: ±25.485The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 11,674 published pairwise votes.Mistral Large 3: Arena rating from 83,498 published pairwise votes. | Higher measured value1,476.716 95% confidence interval: ±6.385The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,414.136 95% confidence interval: ±2.865The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Vision, Style ControlOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Vision, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Vision, style controlGPT-6 Astra: Arena rating from 3,590 published pairwise votes.Mistral Large 3: Arena rating from 8,643 published pairwise votes. | Higher measured value1,285.988 95% confidence interval: ±10.782The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,199.757 95% confidence interval: ±7.981The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/09/2026 |
SAGEOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-6 Astra: Reasoning: max, Output limit: 30,000 tokens Mistral Large 3: Temperature: 1, Output limit: 30,000 tokens | Higher measured value46.367 % | 24.595 % | Vals AISource detailsData as of: 10/08/2026 |
LMArena Code Arena WebDevImage to webdevTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Code Arena WebDev Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Code Arena WebDevGPT-6 Astra: Arena rating from 2,739 published pairwise votes.Mistral Large 3: Arena rating from 1,413 published pairwise votes. | Higher measured value1,731.395 95% confidence interval: ±13.296The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,361.78 95% confidence interval: ±17.387The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/09/2026 |
LMArena Text, Style ControlBusiness, management and financeTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 2,061 published pairwise votes.Mistral Large 3: Arena rating from 15,540 published pairwise votes. | Higher measured value1,472.34 95% confidence interval: ±13.336The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,409.853 95% confidence interval: ±5.362The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Vision, Style ControlChineseTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Vision, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Vision, style controlGPT-6 Astra: Arena rating from 230 published pairwise votes.Mistral Large 3: Arena rating from 540 published pairwise votes. | Higher measured value1,357.126 95% confidence interval: ±39.572The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,211.728 95% confidence interval: ±27.072The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/09/2026 |
SAGEAutomataTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-6 Astra: Reasoning: max, Output limit: 30,000 tokens Mistral Large 3: Temperature: 1, Output limit: 30,000 tokens | Higher measured value37.302 % | 11.905 % | Vals AISource detailsData as of: 10/08/2026 |
LMArena Code Arena WebDevWebdevTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Code Arena WebDev Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Code Arena WebDevGPT-6 Astra: Arena rating from 5,746 published pairwise votes.Mistral Large 3: Arena rating from 839 published pairwise votes. | Higher measured value1,780.244 95% confidence interval: ±10.541The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,230.205 95% confidence interval: ±25.485The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlChineseTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 877 published pairwise votes.Mistral Large 3: Arena rating from 6,341 published pairwise votes. | Higher measured value1,514.537 95% confidence interval: ±19.541The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,432.609 95% confidence interval: ±7.919The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Vision, Style ControlCreative writing visionTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Vision, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Vision, style controlGPT-6 Astra: Arena rating from 367 published pairwise votes.Mistral Large 3: Arena rating from 807 published pairwise votes. | Higher measured value1,289.081 95% confidence interval: ±32.749The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,196.146 95% confidence interval: ±22.467The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/09/2026 |
SAGECalculusTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-6 Astra: Reasoning: max, Output limit: 30,000 tokens Mistral Large 3: Temperature: 1, Output limit: 30,000 tokens | Higher measured value79.938 % | 0 % | Vals AISource detailsData as of: 10/08/2026 |
LMArena Code Arena WebDevWebdev-htmlTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Code Arena WebDev Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Code Arena WebDevGPT-6 Astra: Arena rating from 1,129 published pairwise votes.Mistral Large 3: Arena rating from 839 published pairwise votes. | Higher measured value1,780.13 95% confidence interval: ±22.887The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,238.427 95% confidence interval: ±26.132The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlCodingTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 2,659 published pairwise votes.Mistral Large 3: Arena rating from 21,009 published pairwise votes. | Higher measured value1,543.161 95% confidence interval: ±11.756The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,470.833 95% confidence interval: ±4.783The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Vision, Style ControlDiagramTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Vision, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Vision, style controlGPT-6 Astra: Arena rating from 861 published pairwise votes.Mistral Large 3: Arena rating from 2,169 published pairwise votes. | Higher measured value1,310.509 95% confidence interval: ±20.739The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,235.106 95% confidence interval: ±13.517The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/09/2026 |
SAGELinear AlgebraTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-6 Astra: Reasoning: max, Output limit: 30,000 tokens Mistral Large 3: Temperature: 1, Output limit: 30,000 tokens | Higher measured value62.117 % | 44.419 % | Vals AISource detailsData as of: 10/08/2026 |
LMArena Text, Style ControlCreative writingTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 2,620 published pairwise votes.Mistral Large 3: Arena rating from 14,972 published pairwise votes. | Higher measured value1,449.578 95% confidence interval: ±12.436The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,373.958 95% confidence interval: ±5.611The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Vision, Style ControlEnglishTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Vision, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Vision, style controlGPT-6 Astra: Arena rating from 1,205 published pairwise votes.Mistral Large 3: Arena rating from 2,983 published pairwise votes. | Higher measured value1,288.398 95% confidence interval: ±17.904The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,210.278 95% confidence interval: ±12.173The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/09/2026 |
SAGEPartial Differential EquationsTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-6 Astra: Reasoning: max, Output limit: 30,000 tokens Mistral Large 3: Temperature: 1, Output limit: 30,000 tokens | Higher measured value39.683 % | 17.46 % | Vals AISource detailsData as of: 10/08/2026 |
LMArena Text, Style ControlEnglishTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 4,703 published pairwise votes.Mistral Large 3: Arena rating from 34,656 published pairwise votes. | Higher measured value1,485.113 95% confidence interval: ±9.08The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,426.99 95% confidence interval: ±3.961The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Vision, Style ControlHomeworkTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Vision, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Vision, style controlGPT-6 Astra: Arena rating from 480 published pairwise votes.Mistral Large 3: Arena rating from 891 published pairwise votes. | Higher measured value1,346.15 95% confidence interval: ±26.584The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,211.931 95% confidence interval: ±20.61The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/09/2026 |
LMArena Text, Style ControlEntertainment, sports and mediaTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 2,996 published pairwise votes.Mistral Large 3: Arena rating from 18,448 published pairwise votes. | Higher measured value1,458.633 95% confidence interval: ±11.598The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,372.089 95% confidence interval: ±5.132The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Vision, Style ControlOcrTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Vision, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Vision, style controlGPT-6 Astra: Arena rating from 2,449 published pairwise votes.Mistral Large 3: Arena rating from 5,778 published pairwise votes. | Higher measured value1,301.633 95% confidence interval: ±12.448The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,215.499 95% confidence interval: ±8.709The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/09/2026 |
LMArena Text, Style ControlExcluding tiesTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 8,636 published pairwise votes.Mistral Large 3: Arena rating from 61,071 published pairwise votes. | Higher measured value1,488.868 95% confidence interval: ±8.374The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,401.523 95% confidence interval: ±3.976The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlExpert promptsTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 1,132 published pairwise votes.Mistral Large 3: Arena rating from 7,976 published pairwise votes. | Higher measured value1,509.902 95% confidence interval: ±17.672The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,427.286 95% confidence interval: ±7.215The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlFrenchTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 333 published pairwise votes.Mistral Large 3: Arena rating from 2,379 published pairwise votes. | Higher measured value1,489.442 95% confidence interval: ±32.984The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,432.543 95% confidence interval: ±13.786The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlGermanTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 176 published pairwise votes.Mistral Large 3: Arena rating from 1,359 published pairwise votes. | Higher measured value1,480.596 95% confidence interval: ±44.81The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,407.953 95% confidence interval: ±17.201The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlHard promptsTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 7,117 published pairwise votes.Mistral Large 3: Arena rating from 50,980 published pairwise votes. | Higher measured value1,502.017 95% confidence interval: ±7.647The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,432.155 95% confidence interval: ±3.56The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlHard prompts, EnglishTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 2,847 published pairwise votes.Mistral Large 3: Arena rating from 21,186 published pairwise votes. | Higher measured value1,505.128 95% confidence interval: ±11.467The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,439.589 95% confidence interval: ±4.785The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlInstruction followingTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 3,666 published pairwise votes.Mistral Large 3: Arena rating from 26,939 published pairwise votes. | Higher measured value1,471.988 95% confidence interval: ±10.084The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,401.72 95% confidence interval: ±4.374The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlJapaneseTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 220 published pairwise votes.Mistral Large 3: Arena rating from 929 published pairwise votes. | Higher measured value1,429.026 95% confidence interval: ±42.875The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,379.052 95% confidence interval: ±21.069The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlKoreanTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 210 published pairwise votes.Mistral Large 3: Arena rating from 1,428 published pairwise votes. | Higher measured value1,450.643 95% confidence interval: ±41.535The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,358.651 95% confidence interval: ±17.119The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlLegal and governmentTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 1,000 published pairwise votes.Mistral Large 3: Arena rating from 6,347 published pairwise votes. | Higher measured value1,486.122 95% confidence interval: ±18.889The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,420.684 95% confidence interval: ±7.935The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlLife, physical and social scienceTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 1,987 published pairwise votes.Mistral Large 3: Arena rating from 13,640 published pairwise votes. | Higher measured value1,489.3 95% confidence interval: ±13.614The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,428.444 95% confidence interval: ±5.571The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlLonger queriesTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 4,917 published pairwise votes.Mistral Large 3: Arena rating from 31,737 published pairwise votes. | Higher measured value1,488.357 95% confidence interval: ±9.148The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,417.413 95% confidence interval: ±4.313The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlMathTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 587 published pairwise votes.Mistral Large 3: Arena rating from 4,742 published pairwise votes. | Higher measured value1,481.638 95% confidence interval: ±23.784The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,400.815 95% confidence interval: ±8.893The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlMathematical professionsTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 664 published pairwise votes.Mistral Large 3: Arena rating from 4,407 published pairwise votes. | Higher measured value1,495.728 95% confidence interval: ±22.879The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,413.768 95% confidence interval: ±9.421The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlMedicine and healthcareTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 841 published pairwise votes.Mistral Large 3: Arena rating from 5,848 published pairwise votes. | Higher measured value1,469.187 95% confidence interval: ±20.767The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,431.33 95% confidence interval: ±8.313The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlMulti-turnTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 1,593 published pairwise votes.Mistral Large 3: Arena rating from 14,021 published pairwise votes. | Higher measured value1,485.974 95% confidence interval: ±15.121The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,420.254 95% confidence interval: ±5.589The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlNon-EnglishTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 6,968 published pairwise votes.Mistral Large 3: Arena rating from 48,836 published pairwise votes. | Higher measured value1,463.829 95% confidence interval: ±7.687The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,398.12 95% confidence interval: ±3.514The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlPolishTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 159 published pairwise votes.Mistral Large 3: Arena rating from 1,852 published pairwise votes. | Higher measured value1,454.351 95% confidence interval: ±45.691The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,415.637 95% confidence interval: ±13.929The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlRussianTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 1,542 published pairwise votes.Mistral Large 3: Arena rating from 10,065 published pairwise votes. | Higher measured value1,469.089 95% confidence interval: ±15.197The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,408.261 95% confidence interval: ±6.27The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlSoftware and IT servicesTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 4,224 published pairwise votes.Mistral Large 3: Arena rating from 31,163 published pairwise votes. | Higher measured value1,522.269 95% confidence interval: ±9.455The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,456.413 95% confidence interval: ±4.147The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlSpanishTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 345 published pairwise votes.Mistral Large 3: Arena rating from 2,503 published pairwise votes. | Higher measured value1,443.13 95% confidence interval: ±31.667The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,406.692 95% confidence interval: ±12.904The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlWriting, literature and languageTest detailsTest setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-6 Astra: Snapshot: gpt-6-astra-max, Reasoning: max, Harness: Arena Text, style control Mistral Large 3: Snapshot: mistral-large-3, Harness: Arena Text, style controlGPT-6 Astra: Arena rating from 3,276 published pairwise votes.Mistral Large 3: Arena rating from 20,857 published pairwise votes. | Higher measured value1,464.251 95% confidence interval: ±11.022The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,389.216 95% confidence interval: ±4.844The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
Key to the marks:better valuebetter, but not conclusivetie | |||
Our model tests
One SVG prompt and fixed output settings. Captures are shown only with 0 reported reasoning tokens or documented lack of reasoning controls. Identical test conditions do not make the models' internal compute identical.
Shared test round: 4ae5d8eeb9a9
Unavailable in this round
API request failed. The model was not evaluated.
A community classic for free-form SVG drawing.
GPT-6 Astra
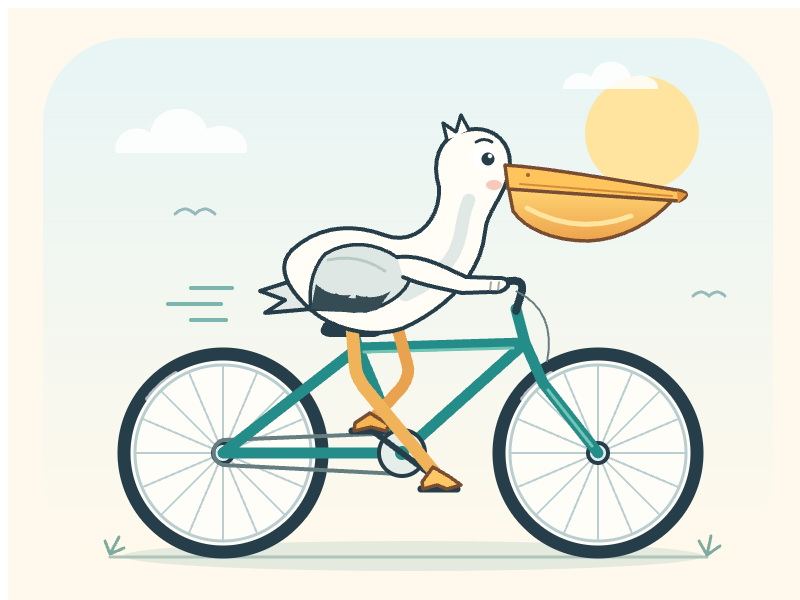
Reasoning (requested): high
Visually reviewed. This individual test does not establish overall model quality.
Mistral Large 3
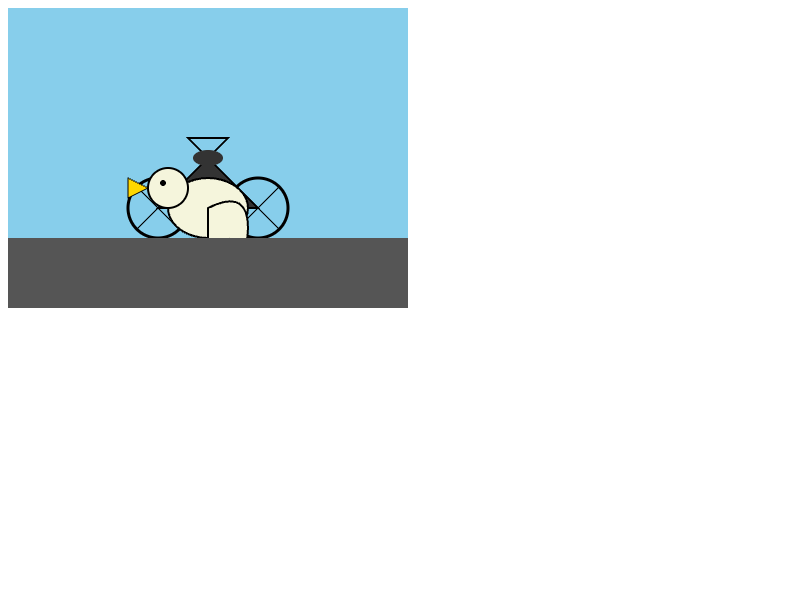
Reasoning (model default): no reasoning mode Source
Visually reviewed. This individual test does not establish overall model quality.
Generate an SVG of a pelican riding a bicycle
Token limit including reasoning: 8,192 tokens
Task origin (Simon Willison)How to read this comparison
Your workload, budget, and required context length matter most. A coding benchmark says little about visual understanding or agent performance.
The standard price table uses direct developer rates. The provider comparison labels OpenRouter endpoints, regions, and special tariffs separately.
Every result links to its measurement source and retrieval date. Labels distinguish vendor reports, official benchmark leaderboards, and independent evaluations. Disputed or archived results are excluded.
More matchups
Compare GPT-6 Astra and Mistral Large 3 with other leading models using the same data and benchmark logic.