
Head-to-head comparison

GPT-5.6 Sol vs. Muse Wonder

Compare published benchmark results from matching versions and cohorts, API pricing, and technical specifications. Any documented test setup differences remain visible.

shared result series
163
distinct benchmarks
18
latest retrieval
2026-10-15

Change model selection

Specifications

General specifications

Release date, availability, context window, architecture, and published parameter counts at a glance. Undisclosed details remain marked as unavailable.

Specifications for GPT-5.6 Sol and Muse Wonder
AttributeGPT-5.6 SolMuse Wonder
ProviderOpenAIMeta
ReleasedJul 9, 2026Oct 12, 2026
AvailabilityActivePreview
Model typeProprietaryProprietary
ParametersNot publishedNot published
ArchitectureNot publishedNot published
Context window1,050,000 tokens1,048,576 tokens
Knowledge cutoffFebruary 16, 2026Not published
Technical sourcesModel, Context, Knowledge cutoffModel, Context

Pricing

API pricing compared

The table compares official standard API rates per 1M tokens, including published cache pricing. Batch, fast, priority, regional surcharges, tool calls, and cloud platform pricing are excluded.

API pricing for GPT-5.6 Sol and Muse Wonder
Price typeGPT-5.6 SolMuse Wonder
API input$4 ≤272K / $8 >272K$4
API output$20 ≤272K / $30 >272K$20
Cache read$0.4 ≤272K / $0.8 >272K$0.2
Cache write (5 min.)$5 ≤272K / $10 >272KNot listed
Cache write (1 hr.)Not listedNot listed
Price verified09/22/2026 Source10/15/2026 Source
GPT-5.6 SolMuse Wonder
API inputUSD per 1M tokens, base tier
GPT-5.6 SolTie$4
Muse WonderTie$4
API outputUSD per 1M tokens, base tier
GPT-5.6 SolTie$20
Muse WonderTie$20
Cache readUSD per 1M tokens, base tier
GPT-5.6 Sol$0.4
Muse WonderLower price$0.2

Key to the marks:better valuebetter, but not conclusivetie

Pricing by provider

Direct developer pricing and provider endpoint tariffs routed through OpenRouter are listed separately. Prices are in USD per 1M tokens. Context-dependent direct tiers plus regional, Flex, Priority, and other OpenRouter tariffs remain individually identifiable.

No provider tariff for Muse Wonder is available in the stored OpenRouter snapshot. The official direct price is still shown.

Provider pricing for GPT-5.6 Sol and Muse Wonder
ModelProviderPurchase route and tariffInput per 1M tokensOutput per 1M tokensSource
GPT-5.6 SolOpenAIDirect from developerUp to 272,000 context tokens$4$20Source09/22/2026
OpenAIDirect from developerAbove 272,000 context tokens$8$30Source09/22/2026
Amazon BedrockVia OpenRouteramazon-bedrock/us-east-1$4.4$22Source10/16/2026
AzureVia OpenRouterazure$4$20Source10/16/2026
AzureVia OpenRouterazure/eu$4.4$22Source10/16/2026
AzureVia OpenRouterazure/us$4.4$22Source10/16/2026
OpenAIVia OpenRouteropenai$4$20Source10/16/2026
OpenAIVia OpenRouteropenai/fast$8$40Source10/16/2026
OpenAIVia OpenRouteropenai/flexLowest listed price: $2Lowest listed price: $10Source10/16/2026
Muse WonderMetaDirect from developerStandard APILowest listed price: $4Lowest listed price: $20Source10/15/2026

Performance

Shared benchmarks

Only published results with the same benchmark version, task, metric, and comparison cohort are paired. Different reasoning levels, agents, harnesses, or output limits appear directly in the table.

Capability profile from matched benchmarks

Each axis averages directly matched benchmark families. A value of 100 means the stronger value within this pair, not a universal quality score.

Not enough directly matched categories for a reliable radar

Only 0 of at least 5 categories have comparable, direct model measurements. The benchmark tables below show the available evidence without filling missing axes.

GPT-5.6 SolMuse Wonder
BioMysteryBenchOverall. Higher is better. Test setup not documented as identical
GPT-5.6 SolHigher measured value71.111 %
Muse Wonder67.037 %
Code MigrationOverall. Higher is better. Test setup not documented as identical
GPT-5.6 Sol52.916 %
Muse WonderHigher measured value62.552 %
CyberBench v1.1Overall. Higher is better. Test setup not documented as identical
GPT-5.6 Sol76.31 %
Muse WonderHigher measured value80.357 %
EMBOverall. Higher is better. Test setup not documented as identical
GPT-5.6 SolHigher measured value72.339 %
Muse Wonder67.084 %
Finance Agent (v2)Overall. Higher is better. Test setup not documented as identical
GPT-5.6 Sol53.756 %
Muse WonderHigher measured value56.637 %
Harvey's Legal Agent BenchmarkOverall · Task fully resolved. Higher is better. Test setup not documented as identical
GPT-5.6 Sol2.5 %
Muse WonderHigher measured value17.083 %
IOIOverall. Higher is better. Test setup not documented as identical
GPT-5.6 SolHigher measured value91.167 %
Muse Wonder66.944 %
Legal Research BenchOverall · All-pass. Higher is better. Test setup not documented as identical
GPT-5.6 Sol48.077 %
Muse WonderHigher measured value50.481 %
LMArena Text, Style ControlOverall. Higher is better. Test setup not documented as identical
GPT-5.6 Sol1,484.86
Muse WonderHigher measured value1,512.671
MysteryMechanismOverall. Higher is better. Test setup not documented as identical
GPT-5.6 SolHigher measured value33.333 %
Muse Wonder27.477 %
ProofBenchOverall. Higher is better. Test setup not documented as identical
GPT-5.6 Sol83 %
Muse WonderHigher measured value84 %
Public Benefits Bench v1.1Overall. Higher is better. Test setup not documented as identical
GPT-5.6 Sol66.509 %
Muse WonderHigher measured value70.23 %

Key to the marks:better valuebetter, but not conclusivetie

Benchmark scores for GPT-5.6 Sol and Muse Wonder
Benchmark and taskGPT-5.6 SolMuse WonderSource
BioMysteryBenchOverall
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Harness: Terminus 2, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Harness: Terminus 2, Temperature: 1, Output limit: 131,072 tokens
Higher measured value71.111 %
67.037 %
Vals AI
Source details
Data as of: 10/12/2026
Code MigrationOverall
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
52.916 %
Higher measured value62.552 %
Vals AI
Source details
Data as of: 10/12/2026
CyberBench v1.1Overall
Test details
Test setup not documented as identicalNo direct winnerVersion: 1.1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
76.31 %
Higher measured value80.357 %
Vals AI
Source details
Data as of: 10/12/2026
EMBOverall
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
Higher measured value72.339 %
67.084 %
Vals AI
Source details
Data as of: 10/12/2026
Finance Agent (v2)Overall
Test details
Test setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
53.756 %
Higher measured value56.637 %
Vals AI
Source details
Data as of: 10/12/2026
Harvey's Legal Agent BenchmarkOverall · Task fully resolved
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: task resolution rateScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
2.5 %
Higher measured value17.083 %
Vals AI
Source details
Data as of: 10/12/2026
IOIOverall
Test details
Test setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
Higher measured value91.167 %
66.944 %
Vals AI
Source details
Data as of: 10/14/2026
Legal Research BenchOverall · All-pass
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: all-pass rateScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
48.077 %
Higher measured value50.481 %
Vals AI
Source details
Data as of: 10/12/2026
LMArena Text, Style ControlOverall
Test details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Sol: Snapshot: gpt-5.6-sol-xhigh, Reasoning: xhigh, Harness: Arena Text, style control
Muse Wonder: Snapshot: muse-wonder-max, Reasoning: max, Harness: Arena Text, style control
GPT-5.6 Sol: Arena rating from 39,832 published pairwise votes.Muse Wonder: Arena rating from 1,944 published pairwise votes.
1,484.86
95% confidence interval: ±4.354The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result.
Higher measured value1,512.671
95% confidence interval: ±13.236The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result.
LMArena
Source details
Data as of: 10/13/2026
MysteryMechanismOverall
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
Higher measured value33.333 %
27.477 %
Vals AI
Source details
Data as of: 10/12/2026
ProofBenchOverall
Test details
Test setup not documented as identicalNo direct winnerVersion: 1.1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
83 %
Higher measured value84 %
Vals AI
Source details
Data as of: 10/12/2026
Public Benefits Bench v1.1Overall
Test details
Test setup not documented as identicalNo direct winnerVersion: 1.1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
66.509 %
Higher measured value70.23 %
Vals AI
Source details
Data as of: 10/12/2026
Tax Agent BenchOverall
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
31.088 %
Higher measured value36.269 %
Vals AI
Source details
Data as of: 10/12/2026
Terminal-Bench 4.0Overall
Test details
Test setup not documented as identicalNo direct winnerVersion: 4.0Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
37.879 %
Higher measured value49.495 %
Vals AI
Source details
Data as of: 10/13/2026
Terminal-Bench ScienceOverall
Test details
Test setup not documented as identicalNo direct winnerVersion: 0.1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Harness: Mini-SWE-agent, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Harness: Mini-SWE-agent, Temperature: 1, Output limit: 131,072 tokens
20 %
Higher measured value22.857 %
Vals AI
Source details
Data as of: 10/14/2026
Vals IndexOverall
Test details
Test setup not documented as identicalNo direct winnerVersion: 2.1Metric: weighted index scoreScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
58.005 %
Higher measured value61.062 %
Vals AI
Source details
Data as of: 10/13/2026
Vibe Code Bench 1-100Overall
Test details
Test setup not documented as identicalNo direct winnerVersion: 1.0Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Harness: OpenHands, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Harness: OpenHands, Temperature: 1, Output limit: 131,072 tokens
20.011 %
Higher measured value26.55 %
Vals AI
Source details
Data as of: 10/14/2026
Vibe Code Bench v1.1Overall
Test details
Test setup not documented as identicalNo direct winnerVersion: 1.1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Harness: OpenHands, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Harness: OpenHands, Temperature: 1, Output limit: 131,072 tokens
80.495 %
Higher measured value83.089 %
Vals AI
Source details
Data as of: 10/12/2026
BioMysteryBenchHard
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Harness: Terminus 2, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Harness: Terminus 2, Temperature: 1, Output limit: 131,072 tokens
No direct winner29.412 %
Vals AI
Source details
Data as of: 10/12/2026
Code MigrationCLI
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
47.221 %
Higher measured value60.07 %
Vals AI
Source details
Data as of: 10/12/2026
CyberBench v1.1Patch
Test details
Test setup not documented as identicalNo direct winnerVersion: 1.1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
Higher measured value89.286 %
85.714 %
Vals AI
Source details
Data as of: 10/12/2026
EMBComps
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
71.309 %
Higher measured value79.488 %
Vals AI
Source details
Data as of: 10/12/2026
Finance Agent (v2)Adjustments
Test details
Test setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
49.233 %
Higher measured value52.67 %
Vals AI
Source details
Data as of: 10/12/2026
Harvey's Legal Agent BenchmarkAntitrust Competition · Criteria passed
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: criteria pass rateScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
78.623 %
Higher measured value93.841 %
Vals AI
Source details
Data as of: 10/12/2026
IOIIOI 2024
Test details
Test setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
Higher measured value100 %
66.833 %
Vals AI
Source details
Data as of: 10/14/2026
Legal Research BenchAdministrative / Regulatory · All-pass
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: all-pass rateScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
60.606 %
Higher measured value63.636 %
Vals AI
Source details
Data as of: 10/12/2026
LMArena Text, Style ControlBusiness, management and finance
Test details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Sol: Snapshot: gpt-5.6-sol-xhigh, Reasoning: xhigh, Harness: Arena Text, style control
Muse Wonder: Snapshot: muse-wonder-max, Reasoning: max, Harness: Arena Text, style control
GPT-5.6 Sol: Arena rating from 7,397 published pairwise votes.Muse Wonder: Arena rating from 338 published pairwise votes.
1,486.398
95% confidence interval: ±7.685The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result.
Higher measured value1,500.247
95% confidence interval: ±30.856The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result.
LMArena
Source details
Data as of: 10/13/2026
Tax Agent BenchControversy & Precedence Analysis
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
No direct winner20 %
Vals AI
Source details
Data as of: 10/12/2026
Terminal-Bench 4.0Hardware
Test details
Test setup not documented as identicalNo direct winnerVersion: 4.0Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
0 %
Higher measured value46.667 %
Vals AI
Source details
Data as of: 10/13/2026
Terminal-Bench ScienceEarth Sciences
Test details
Test setup not documented as identicalNo direct winnerVersion: 0.1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Harness: Mini-SWE-agent, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Harness: Mini-SWE-agent, Temperature: 1, Output limit: 131,072 tokens
25 %
Higher measured value50 %
Vals AI
Source details
Data as of: 10/14/2026
Vals IndexCode Migration
Test details
Test setup not documented as identicalNo direct winnerVersion: 2.1Metric: benchmark scoreScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
52.397 %
Higher measured value62.009 %
Vals AI
Source details
Data as of: 10/13/2026
BioMysteryBenchHuman-solvable
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Harness: Terminus 2, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Harness: Terminus 2, Temperature: 1, Output limit: 131,072 tokens
Higher measured value80.822 %
75.799 %
Vals AI
Source details
Data as of: 10/12/2026
Code MigrationCOBOL
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
No direct winner70 %
Vals AI
Source details
Data as of: 10/12/2026
CyberBench v1.1PoC
Test details
Test setup not documented as identicalNo direct winnerVersion: 1.1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
63.333 %
Higher measured value75 %
Vals AI
Source details
Data as of: 10/12/2026
EMBDataroom
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
Higher measured value85.243 %
79.232 %
Vals AI
Source details
Data as of: 10/12/2026
Finance Agent (v2)All-Pass
Test details
Test setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
41.362 %
Higher measured value45.936 %
Vals AI
Source details
Data as of: 10/12/2026
Harvey's Legal Agent BenchmarkAntitrust Competition · Task fully resolved
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: task resolution rateScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
0 %
Higher measured value20 %
Vals AI
Source details
Data as of: 10/12/2026
IOIIOI 2025
Test details
Test setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
Higher measured value88.333 %
75.5 %
Vals AI
Source details
Data as of: 10/14/2026
Legal Research BenchAdministrative / Regulatory · Weighted partial credit
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: weighted partial-credit scoreScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
Higher measured value90.69 %
90.571 %
Vals AI
Source details
Data as of: 10/12/2026
LMArena Text, Style ControlCoding
Test details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Sol: Snapshot: gpt-5.6-sol-xhigh, Reasoning: xhigh, Harness: Arena Text, style control
Muse Wonder: Snapshot: muse-wonder-max, Reasoning: max, Harness: Arena Text, style control
GPT-5.6 Sol: Arena rating from 10,696 published pairwise votes.Muse Wonder: Arena rating from 487 published pairwise votes.
1,534.274
95% confidence interval: ±6.761The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result.
Higher measured value1,557.956
95% confidence interval: ±26.189The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result.
LMArena
Source details
Data as of: 10/13/2026
Tax Agent BenchControversy & Precedence Analysis
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
68.503 %
Higher measured value71.362 %
Vals AI
Source details
Data as of: 10/12/2026
Terminal-Bench 4.0Media
Test details
Test setup not documented as identicalNo direct winnerVersion: 4.0Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
25 %
Higher measured value33.333 %
Vals AI
Source details
Data as of: 10/13/2026
Terminal-Bench ScienceEngineering Sciences
Test details
Test setup not documented as identicalNo direct winnerVersion: 0.1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Harness: Mini-SWE-agent, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Harness: Mini-SWE-agent, Temperature: 1, Output limit: 131,072 tokens
Higher measured value11.111 %
0 %
Vals AI
Source details
Data as of: 10/14/2026
Vals IndexEMB
Test details
Test setup not documented as identicalNo direct winnerVersion: 2.1Metric: benchmark scoreScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
Higher measured value72.339 %
67.084 %
Vals AI
Source details
Data as of: 10/13/2026
Code MigrationCode Quality
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: mean reviewer code-quality ratingScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
3.847 / 5
Higher measured value4.061 / 5
Vals AI
Source details
Data as of: 10/12/2026
EMBDCF
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
Higher measured value62.764 %
51.035 %
Vals AI
Source details
Data as of: 10/12/2026
Finance Agent (v2)Comparables
Test details
Test setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
45.284 %
Higher measured value47.933 %
Vals AI
Source details
Data as of: 10/12/2026
Harvey's Legal Agent BenchmarkArbitration International Dispute Resolution · Criteria passed
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: criteria pass rateScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
82.079 %
Higher measured value92.473 %
Vals AI
Source details
Data as of: 10/12/2026
IOIIOI 2026
Test details
Test setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
Higher measured value85.167 %
58.5 %
Vals AI
Source details
Data as of: 10/14/2026
Legal Research BenchBusiness & Commercial · All-pass
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: all-pass rateScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
Higher measured value53.488 %
48.837 %
Vals AI
Source details
Data as of: 10/12/2026
LMArena Text, Style ControlCreative writing
Test details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Sol: Snapshot: gpt-5.6-sol-xhigh, Reasoning: xhigh, Harness: Arena Text, style control
Muse Wonder: Snapshot: muse-wonder-max, Reasoning: max, Harness: Arena Text, style control
GPT-5.6 Sol: Arena rating from 8,272 published pairwise votes.Muse Wonder: Arena rating from 427 published pairwise votes.
1,468.655
95% confidence interval: ±7.689The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result.
Higher measured value1,485.682
95% confidence interval: ±29.474The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result.
LMArena
Source details
Data as of: 10/13/2026
Tax Agent BenchCurrent & Temporal Analysis
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
No direct winner50 %
Vals AI
Source details
Data as of: 10/12/2026
Terminal-Bench 4.0ML
Test details
Test setup not documented as identicalNo direct winnerVersion: 4.0Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
42.424 %
Higher measured value45.455 %
Vals AI
Source details
Data as of: 10/13/2026
Terminal-Bench ScienceLife Sciences
Test details
Test setup not documented as identicalNo direct winnerVersion: 0.1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Harness: Mini-SWE-agent, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Harness: Mini-SWE-agent, Temperature: 1, Output limit: 131,072 tokens
No direct winner21.053 %
Vals AI
Source details
Data as of: 10/14/2026
Vals IndexFinance Agent v2
Test details
Test setup not documented as identicalNo direct winnerVersion: 2.1Metric: benchmark scoreScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
53.756 %
Higher measured value56.637 %
Vals AI
Source details
Data as of: 10/13/2026
EMBLBO
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
Higher measured value67.242 %
60.69 %
Vals AI
Source details
Data as of: 10/12/2026
Finance Agent (v2)Disclosure Analysis
Test details
Test setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
63.329 %
Higher measured value67.252 %
Vals AI
Source details
Data as of: 10/12/2026
Harvey's Legal Agent BenchmarkArbitration International Dispute Resolution · Task fully resolved
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: task resolution rateScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
No direct winner0 %
No direct winner0 %
Vals AI
Source details
Data as of: 10/12/2026
Legal Research BenchBusiness & Commercial · Weighted partial credit
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: weighted partial-credit scoreScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
Higher measured value89.003 %
86.88 %
Vals AI
Source details
Data as of: 10/12/2026
LMArena Text, Style ControlEnglish
Test details
Test setup not documented as identicalNo direct winnerVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterGPT-5.6 Sol: Snapshot: gpt-5.6-sol-xhigh, Reasoning: xhigh, Harness: Arena Text, style control
Muse Wonder: Snapshot: muse-wonder-max, Reasoning: max, Harness: Arena Text, style control
GPT-5.6 Sol: Arena rating from 16,085 published pairwise votes.Muse Wonder: Arena rating from 802 published pairwise votes.
1,488.874
95% confidence interval: ±5.758The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result.
Higher measured value1,523.395
95% confidence interval: ±20.831The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result.
LMArena
Source details
Data as of: 10/13/2026
Tax Agent BenchCurrent & Temporal Analysis
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
74.38 %
Higher measured value77.655 %
Vals AI
Source details
Data as of: 10/12/2026
Terminal-Bench 4.0Operations
Test details
Test setup not documented as identicalNo direct winnerVersion: 4.0Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
25.926 %
Higher measured value40.741 %
Vals AI
Source details
Data as of: 10/13/2026
Terminal-Bench ScienceMathematical Sciences
Test details
Test setup not documented as identicalNo direct winnerVersion: 0.1Metric: accuracyScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Harness: Mini-SWE-agent, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Harness: Mini-SWE-agent, Temperature: 1, Output limit: 131,072 tokens
11.765 %
Higher measured value23.529 %
Vals AI
Source details
Data as of: 10/14/2026
Vals IndexHLAB
Test details
Test setup not documented as identicalNo direct winnerVersion: 2.1Metric: benchmark scoreScoring: Higher is betterGPT-5.6 Sol: Reasoning: max, Output limit: 128,000 tokens
Muse Wonder: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
2.5 %
Higher measured value17.083 %
Vals AI
Source details
Data as of: 10/13/2026

Key to the marks:better valuebetter, but not conclusivetie

Our model tests

Our tests

There is no shared test round for this selection. Results from different rounds are not mixed.

Earlier tests

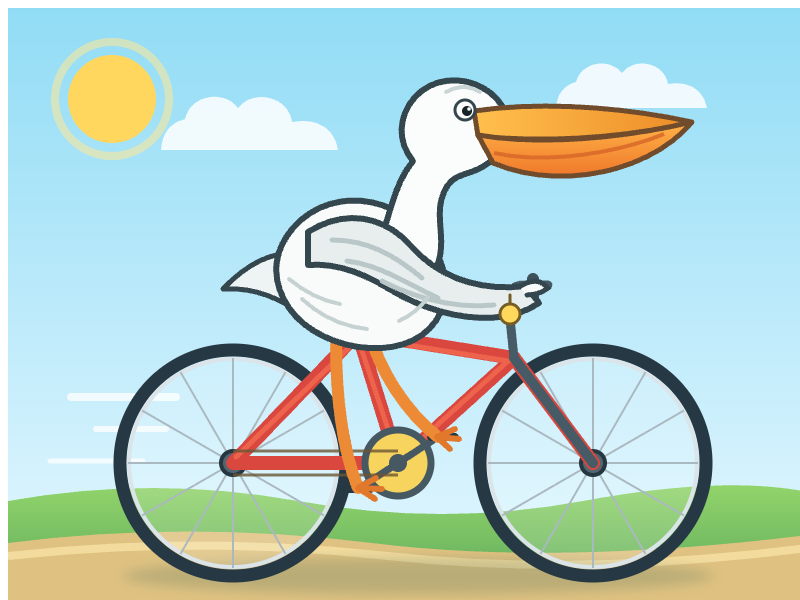
Pelican on a bicycle

A community classic for free-form SVG drawing.

GPT-5.6 Sol

GPT-5.6 Sol: Pelican on a bicycle
A community classic for free-form SVG drawing.

Reasoning (requested): high

Current attempt
Run date
Oct 1, 2026
API provider
openrouter
Requested API model
openai/gpt-5.6-sol
API model reported in response
openai/gpt-5.6-sol
Reasoning setting
high
Pinned endpoint
OpenAI | openai/gpt-5.6-sol-20260709
Temperature
Provider default
Token limit including reasoning
8,192 tokens
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating
Response time
58.7 s

Visually reviewed. This individual test does not establish overall model quality.

Earlier attempts (1)
  • Sep 7, 2026API request failedReasoning setting: high

Muse Wonder

Not tested yet

Prompt and test conditions

Generate an SVG of a pelican riding a bicycle

Token limit including reasoning: 8,192 tokens

Task origin (Simon Willison)

How to read this comparison

Winning one benchmark is not an overall verdict

Your workload, budget, and required context length matter most. A coding benchmark says little about visual understanding or agent performance.

The standard price table uses direct developer rates. The provider comparison labels OpenRouter endpoints, regions, and special tariffs separately.

Every result links to its measurement source and retrieval date. Labels distinguish vendor reports, official benchmark leaderboards, and independent evaluations. Disputed or archived results are excluded.

More matchups

Compare GPT-5.6 Sol and Muse Wonder with other leading models using the same data and benchmark logic.
View the complete LLM comparison