Claude Opus 4.6
Head-to-head comparison
Compare published benchmark results from matching versions and cohorts, API pricing, and technical specifications. Any documented test setup differences remain visible.
Specifications
Release date, availability, context window, architecture, and published parameter counts at a glance. Undisclosed details remain marked as unavailable.
| Attribute | Claude Opus 4.6 | DeepSeek-V4-Flash |
|---|---|---|
| Provider | Anthropic | DeepSeek |
| Released | Feb 2026 | Apr 24, 2026 |
| Availability | Active | Limited access |
| Model type | Proprietary | Open Weights |
| Parameters | Not published | 284B, 13B active |
| Architecture | Not published | Mixture of Experts |
| Context window | 1,000,000 tokens | 1,000,000 tokens |
| Knowledge cutoff | May 2025 | Not published |
| Technical sources | Model, Context | Model |
Pricing
The table compares official standard API rates per 1M tokens, including published cache pricing. Batch, fast, priority, regional surcharges, tool calls, and cloud platform pricing are excluded.
| Price type | Claude Opus 4.6 | DeepSeek-V4-Flash |
|---|---|---|
| API input | $5 | $0.14 |
| API output | $25 | $0.28 |
| Cache read | $0.5 | Not listed |
| Cache write (5 min.) | $6.25 | Not listed |
| Cache write (1 hr.) | $10 | Not listed |
| Price verified | 09/22/2026 Source | 10/17/2026 Source |
Key to the marks:better valuebetter, but not conclusivetie
Direct developer pricing and provider endpoint tariffs routed through OpenRouter are listed separately. Prices are in USD per 1M tokens. Context-dependent direct tiers plus regional, Flex, Priority, and other OpenRouter tariffs remain individually identifiable.
| Model | Provider | Purchase route and tariff | Input per 1M tokens | Output per 1M tokens | Source |
|---|---|---|---|---|---|
| Claude Opus 4.6 | Anthropic | Direct from developerStandard API | Lowest listed price: $5 | Lowest listed price: $25 | Source09/22/2026 |
| Amazon Bedrock | Via OpenRouteramazon-bedrock | Lowest listed price: $5 | Lowest listed price: $25 | Source10/17/2026 | |
| Anthropic | Via OpenRouteranthropic | Lowest listed price: $5 | Lowest listed price: $25 | Source10/17/2026 | |
| Azure | Via OpenRouterazure/global | Lowest listed price: $5 | Lowest listed price: $25 | Source10/17/2026 | |
| Claude Platform on AWS | Via OpenRouterclaude-on-aws | Lowest listed price: $5 | Lowest listed price: $25 | Source10/17/2026 | |
| Via OpenRoutergoogle-vertex/europe | $5.5 | $27.5 | Source10/17/2026 | ||
| Via OpenRoutergoogle-vertex/global | Lowest listed price: $5 | Lowest listed price: $25 | Source10/17/2026 | ||
| DeepSeek-V4-Flash | Alibaba | Via OpenRouteralibaba | $0.352 | $1.056 | Source10/17/2026 |
| Alibaba | Via OpenRouteralibaba/us-east-1 | $0.374 | $1.122 | Source10/17/2026 | |
| AtlasCloud | Via OpenRouteratlas-cloud/fp4 | $0.44 | $1.32 | Source10/17/2026 | |
| Baidu | Via OpenRouterbaidu/fp8 | $0.0598 | $0.1795 | Source10/17/2026 | |
| BaseTen | Via OpenRouterbaseten/fp32 | $0.13 | $0.26 | Source10/17/2026 | |
| BaseTen | Via OpenRouterbaseten/fp8 | $0.13 | $0.26 | Source10/17/2026 | |
| Cloudflare | Via OpenRoutercloudflare | $0.44 | $1.32 | Source10/17/2026 | |
| Cohere | Via OpenRoutercohere | $0.14 | $0.28 | Source10/17/2026 | |
| CoreWeave | Via OpenRoutercoreweave/fp8 | $0.13 | $0.28 | Source10/17/2026 | |
| DeepInfra | Via OpenRouterdeepinfra/fp8 | $0.06 | $0.18 | Source10/17/2026 | |
| DigitalOcean | Via OpenRouterdigitalocean | $0.119 | $0.238 | Source10/17/2026 | |
| GMICloud | Via OpenRoutergmicloud/fp8 | $0.286 | $0.858 | Source10/17/2026 | |
| Inceptron | Via OpenRouterinceptron/fp4 | $0.13 | $0.4782 | Source10/17/2026 | |
| Mancer 2 | Via OpenRoutermancer/fp8 | $0.2 | $0.6 | Source10/17/2026 | |
| Novita | Via OpenRouternovita/fp8 | $0.4092 | $1.2276 | Source10/17/2026 | |
| OpenInference | Via OpenRouteropen-inference/fp4 | $0.0052 | Lowest listed price: $0.1436 | Source10/17/2026 | |
| Parasail | Via OpenRouterparasail/fp8 | $0.14 | $0.28 | Source10/17/2026 | |
| Phala | Via OpenRouterphala | $0.44 | $1.32 | Source10/17/2026 | |
| Reka | Via OpenRouterreka | $0.021 | $0.528 | Source10/17/2026 | |
| Relace | Via OpenRouterrelace/fp4 | Lowest listed price: $0.0049 | $1.28 | Source10/17/2026 | |
| Sail Research | Via OpenRoutersail-research/fp4 | $0.1 | $0.3 | Source10/17/2026 | |
| Sail Research | Via OpenRoutersail-research/us | $0.1 | $0.3 | Source10/17/2026 | |
| SiliconFlow | Via OpenRoutersiliconflow/fp8 | $0.22 | $0.66 | Source10/17/2026 | |
| StreamLake | Via OpenRouterstreamlake/fp8 | $0.088 | $0.264 | Source10/17/2026 | |
| Together | Via OpenRoutertogether | $0.14 | $0.28 | Source10/17/2026 | |
| Venice | Via OpenRoutervenice | $0.13 | $0.26 | Source10/17/2026 | |
| Wafer | Via OpenRouterwafer/fast | $0.13 | $0.23 | Source10/17/2026 |
Performance
Only published results with the same benchmark version, task, metric, and comparison cohort are paired. Different reasoning levels, agents, harnesses, or output limits appear directly in the table.
Each axis averages directly matched benchmark families. A value of 100 means the stronger value within this pair, not a universal quality score.
62 matched rows from 2 benchmark families were considered. The radar shows 8 of 8 comparable categories.
Key to the marks:better valuebetter, but not conclusivetie
| Benchmark and task | Claude Opus 4.6 | DeepSeek-V4-Flash | Source |
|---|---|---|---|
LMArena Code Arena WebDevOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Code Arena WebDev DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Code Arena WebDevClaude Opus 4.6: Arena rating from 20,698 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 10,152 published pairwise votes. | Higher measured value1,537.258 95% confidence interval: ±5.345The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,430.632 95% confidence interval: ±6.942The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlOverallTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 85,445 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 52,016 published pairwise votes. | Winner1,497.663 95% confidence interval: ±3.27The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,435.976 95% confidence interval: ±4.036The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Code Arena WebDevOverallTest detailsNo documented difference in the test setupVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Code Arena WebDev DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Code Arena WebDevClaude Opus 4.6: Arena rating from 19,443 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 10,152 published pairwise votes. | Winner1,546.362 95% confidence interval: ±5.46The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,430.632 95% confidence interval: ±6.942The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlOverallTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 80,827 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 51,814 published pairwise votes. | Winner1,503.106 95% confidence interval: ±3.353The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,438.654 95% confidence interval: ±4.106The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Code Arena WebDevWebdevTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Code Arena WebDev DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Code Arena WebDevClaude Opus 4.6: Arena rating from 20,698 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 10,152 published pairwise votes. | Higher measured value1,537.258 95% confidence interval: ±5.345The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,430.632 95% confidence interval: ±6.942The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlBusiness, management and financeTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 16,859 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 10,448 published pairwise votes. | Winner1,499.695 95% confidence interval: ±5.707The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,438.829 95% confidence interval: ±6.961The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Code Arena WebDevWebdevTest detailsNo documented difference in the test setupVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Code Arena WebDev DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Code Arena WebDevClaude Opus 4.6: Arena rating from 19,443 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 10,152 published pairwise votes. | Winner1,546.362 95% confidence interval: ±5.46The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,430.632 95% confidence interval: ±6.942The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlBusiness, management and financeTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 15,865 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 10,643 published pairwise votes. | Winner1,500.43 95% confidence interval: ±5.84The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,434.084 95% confidence interval: ±6.963The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Code Arena WebDevWebdev-htmlTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Code Arena WebDev DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Code Arena WebDevClaude Opus 4.6: Arena rating from 2,623 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 1,165 published pairwise votes. | Higher measured value1,546.218 95% confidence interval: ±12.521The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,416.219 95% confidence interval: ±18.033The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlChineseTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 5,821 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 3,005 published pairwise votes. | Winner1,545.153 95% confidence interval: ±8.666The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,470.018 95% confidence interval: ±11.382The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Code Arena WebDevWebdev-htmlTest detailsNo documented difference in the test setupVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Code Arena WebDev DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Code Arena WebDevClaude Opus 4.6: Arena rating from 2,474 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 1,165 published pairwise votes. | Winner1,558.715 95% confidence interval: ±13.217The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,416.219 95% confidence interval: ±18.033The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlChineseTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 5,591 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 2,975 published pairwise votes. | Winner1,550.027 95% confidence interval: ±8.89The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,480.516 95% confidence interval: ±11.412The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Code Arena WebDevWebdev-reactTest detailsTest setup not documented as identicalNo direct winnerVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Code Arena WebDev DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Code Arena WebDevClaude Opus 4.6: Arena rating from 16,319 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 8,109 published pairwise votes. | Higher measured value1,528.416 95% confidence interval: ±5.908The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,421.593 95% confidence interval: ±7.665The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlCodingTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 23,695 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 15,290 published pairwise votes. | Winner1,547.708 95% confidence interval: ±5.22The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,484.301 95% confidence interval: ±6.214The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Code Arena WebDevWebdev-reactTest detailsNo documented difference in the test setupVersion: webdevMetric: WebDev Arena Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Code Arena WebDev DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Code Arena WebDevClaude Opus 4.6: Arena rating from 15,177 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 8,109 published pairwise votes. | Winner1,538.872 95% confidence interval: ±6.058The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,421.593 95% confidence interval: ±7.665The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlCodingTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 20,969 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 15,245 published pairwise votes. | Winner1,548.395 95% confidence interval: ±5.448The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,479.463 95% confidence interval: ±6.25The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlCreative writingTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 14,986 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 8,595 published pairwise votes. | Winner1,478.397 95% confidence interval: ±6.086The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,408.246 95% confidence interval: ±7.512The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlCreative writingTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 14,826 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 8,668 published pairwise votes. | Winner1,499.767 95% confidence interval: ±6.246The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,410.845 95% confidence interval: ±7.548The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlEnglishTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 38,162 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 23,136 published pairwise votes. | Winner1,506.394 95% confidence interval: ±4.352The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,445.189 95% confidence interval: ±5.273The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlEnglishTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 35,612 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 23,022 published pairwise votes. | Winner1,513.707 95% confidence interval: ±4.48The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,449.707 95% confidence interval: ±5.31The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlEntertainment, sports and mediaTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 19,048 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 11,221 published pairwise votes. | Winner1,478.55 95% confidence interval: ±5.586The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,404.55 95% confidence interval: ±6.918The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlEntertainment, sports and mediaTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 18,282 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 11,460 published pairwise votes. | Winner1,491.123 95% confidence interval: ±5.751The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,407.781 95% confidence interval: ±6.873The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlExcluding tiesTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 64,924 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 39,351 published pairwise votes. | Winner1,516.544 95% confidence interval: ±4.425The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,431.858 95% confidence interval: ±5.294The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlExcluding tiesTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 61,691 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 39,449 published pairwise votes. | Winner1,522.764 95% confidence interval: ±4.502The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,436.129 95% confidence interval: ±5.336The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlExpert promptsTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 8,806 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 5,416 published pairwise votes. | Winner1,533.95 95% confidence interval: ±7.394The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,457.085 95% confidence interval: ±8.727The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlExpert promptsTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 7,356 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 5,338 published pairwise votes. | Winner1,545.814 95% confidence interval: ±7.928The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,466.764 95% confidence interval: ±8.816The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlFrenchTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 2,808 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 2,004 published pairwise votes. | Winner1,496.997 95% confidence interval: ±13.146The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,449.161 95% confidence interval: ±14.911The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlFrenchTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 2,619 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 1,957 published pairwise votes. | Winner1,511.426 95% confidence interval: ±13.557The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,458.886 95% confidence interval: ±15.182The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlGermanTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 1,328 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 841 published pairwise votes. | Winner1,490.887 95% confidence interval: ±17.278The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,425.17 95% confidence interval: ±21.221The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlGermanTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 1,284 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 904 published pairwise votes. | Winner1,507.167 95% confidence interval: ±17.309The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,433.291 95% confidence interval: ±20.525The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlHard promptsTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 55,452 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 34,789 published pairwise votes. | Winner1,527.527 95% confidence interval: ±3.977The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,459.087 95% confidence interval: ±4.755The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlHard promptsTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 51,483 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 34,719 published pairwise votes. | Winner1,531.566 95% confidence interval: ±4.093The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,458.022 95% confidence interval: ±4.823The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlHard prompts, EnglishTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 25,280 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 16,226 published pairwise votes. | Winner1,529.961 95% confidence interval: ±5.118The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,463.782 95% confidence interval: ±6.043The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlHard prompts, EnglishTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 23,143 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 16,101 published pairwise votes. | Winner1,535.921 95% confidence interval: ±5.299The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,464.326 95% confidence interval: ±6.118The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlInstruction followingTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 28,622 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 17,984 published pairwise votes. | Winner1,499.444 95% confidence interval: ±4.848The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,428.161 95% confidence interval: ±5.795The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlInstruction followingTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 26,036 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 18,097 published pairwise votes. | Winner1,512.245 95% confidence interval: ±5.064The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,433.654 95% confidence interval: ±5.864The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlJapaneseTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 941 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 653 published pairwise votes. | Winner1,483.858 95% confidence interval: ±21.248The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,398.855 95% confidence interval: ±24.754The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlJapaneseTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 922 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 640 published pairwise votes. | Winner1,498.901 95% confidence interval: ±21.325The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,426.069 95% confidence interval: ±24.977The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlKoreanTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 1,536 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 900 published pairwise votes. | Winner1,465.035 95% confidence interval: ±16.873The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,391.938 95% confidence interval: ±20.897The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlKoreanTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 1,361 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 949 published pairwise votes. | Winner1,445.732 95% confidence interval: ±17.684The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,376.332 95% confidence interval: ±20.813The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlLegal and governmentTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 6,844 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 4,152 published pairwise votes. | Winner1,506.526 95% confidence interval: ±8.092The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,448.281 95% confidence interval: ±9.836The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlLegal and governmentTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 6,593 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 4,099 published pairwise votes. | Winner1,510.822 95% confidence interval: ±8.22The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,457.757 95% confidence interval: ±9.897The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlLife, physical and social scienceTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 14,216 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 8,416 published pairwise votes. | Winner1,518.741 95% confidence interval: ±6.004The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,456.243 95% confidence interval: ±7.368The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlLife, physical and social scienceTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 13,449 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 8,489 published pairwise votes. | Winner1,528.541 95% confidence interval: ±6.139The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,459.964 95% confidence interval: ±7.4The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlLonger queriesTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 37,162 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 23,382 published pairwise votes. | Winner1,516.98 95% confidence interval: ±4.682The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,447.798 95% confidence interval: ±5.56The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlLonger queriesTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 34,277 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 23,493 published pairwise votes. | Winner1,522.054 95% confidence interval: ±4.811The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,448.579 95% confidence interval: ±5.563The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlMathTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 4,642 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 2,699 published pairwise votes. | Winner1,505.04 95% confidence interval: ±9.289The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,424.989 95% confidence interval: ±11.731The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlMathTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 4,148 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 2,625 published pairwise votes. | Winner1,517.433 95% confidence interval: ±9.697The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,441.363 95% confidence interval: ±11.858The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlMathematical professionsTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 4,797 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 2,980 published pairwise votes. | Winner1,512.7 95% confidence interval: ±9.399The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,434.613 95% confidence interval: ±11.415The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlMathematical professionsTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 4,208 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 2,825 published pairwise votes. | Winner1,525.513 95% confidence interval: ±9.98The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,444.604 95% confidence interval: ±11.746The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlMedicine and healthcareTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 6,382 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 3,692 published pairwise votes. | Winner1,512.795 95% confidence interval: ±8.433The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,459.398 95% confidence interval: ±10.484The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlMedicine and healthcareTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 6,092 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 3,760 published pairwise votes. | Winner1,518.12 95% confidence interval: ±8.547The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,461.041 95% confidence interval: ±10.433The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlMulti-turnTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 14,990 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 9,349 published pairwise votes. | Winner1,512.066 95% confidence interval: ±5.994The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,453.168 95% confidence interval: ±7.275The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlMulti-turnTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 13,729 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 9,223 published pairwise votes. | Winner1,517.415 95% confidence interval: ±6.216The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,446.213 95% confidence interval: ±7.326The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlNon-EnglishTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 47,281 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 28,879 published pairwise votes. | Winner1,485.029 95% confidence interval: ±3.996The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,422.96 95% confidence interval: ±4.937The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlNon-EnglishTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 45,212 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 28,790 published pairwise votes. | Winner1,489.27 95% confidence interval: ±4.076The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,423.369 95% confidence interval: ±5.014The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlPolishTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 1,595 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 1,027 published pairwise votes. | Winner1,494.127 95% confidence interval: ±15.586The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,436.594 95% confidence interval: ±18.719The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlPolishTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 1,527 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 1,040 published pairwise votes. | Winner1,501.723 95% confidence interval: ±15.429The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,433.769 95% confidence interval: ±18.399The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlRussianTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 9,657 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 5,766 published pairwise votes. | Winner1,504.697 95% confidence interval: ±6.819The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,432.997 95% confidence interval: ±8.479The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlRussianTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 9,274 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 5,793 published pairwise votes. | Winner1,506.054 95% confidence interval: ±6.965The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,436.964 95% confidence interval: ±8.567The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlSoftware and IT servicesTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 33,350 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 21,384 published pairwise votes. | Winner1,535.811 95% confidence interval: ±4.602The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,471.26 95% confidence interval: ±5.499The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlSoftware and IT servicesTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 30,709 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 21,349 published pairwise votes. | Winner1,538.109 95% confidence interval: ±4.73The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,472.791 95% confidence interval: ±5.525The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlSpanishTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 2,834 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 1,580 published pairwise votes. | Winner1,499.257 95% confidence interval: ±12.441The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,431.488 95% confidence interval: ±16.062The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
LMArena Text, Style ControlSpanishTest detailsNo documented difference in the test setupVersion: style-control-v1Metric: style-controlled Bradley-Terry ratingScoring: Higher is betterClaude Opus 4.6: Snapshot: claude-opus-4-6-high, Reasoning: high, Harness: Arena Text, style control DeepSeek-V4-Flash: Snapshot: deepseek-v4-flash-high-preview, Reasoning: high, Harness: Arena Text, style controlClaude Opus 4.6: Arena rating from 2,745 published pairwise votes.DeepSeek-V4-Flash: Arena rating from 1,476 published pairwise votes. | Winner1,493.263 95% confidence interval: ±12.592The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | 1,429.907 95% confidence interval: ±16.461The Arena score measures human preference rather than a fixed capability test. The confidence interval, Arena category, and model configuration are part of the result. | LMArenaSource detailsData as of: 10/13/2026 |
Key to the marks:better valuebetter, but not conclusivetie | |||
Our model tests
One SVG prompt and fixed output settings. Captures are shown only with 0 reported reasoning tokens or documented lack of reasoning controls. Identical test conditions do not make the models' internal compute identical.
Shared test round: 4ae5d8eeb9a9
API request failed. The model was not evaluated.
A community classic for free-form SVG drawing.
Claude Opus 4.6
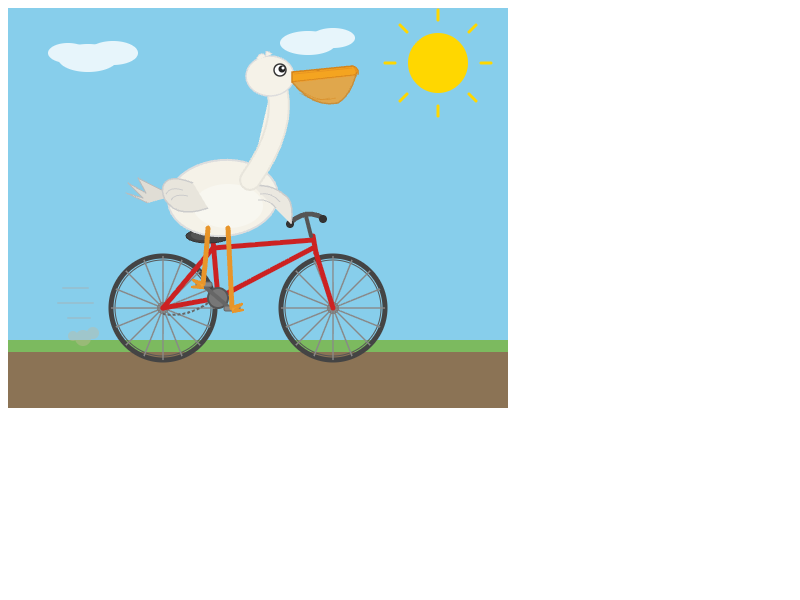
Reasoning (requested): high
Visually reviewed. This individual test does not establish overall model quality.
DeepSeek-V4-Flash
The response reached the token limit. No complete recording is available.
Reasoning (requested): high
Not yet visually reviewed. A successful recording does not confirm correct physics or full compliance with the prompt.
Generate an SVG of a pelican riding a bicycle
Token limit including reasoning: 8,192 tokens
Task origin (Simon Willison)How to read this comparison
Your workload, budget, and required context length matter most. A coding benchmark says little about visual understanding or agent performance.
The standard price table uses direct developer rates. The provider comparison labels OpenRouter endpoints, regions, and special tariffs separately.
Every result links to its measurement source and retrieval date. Labels distinguish vendor reports, official benchmark leaderboards, and independent evaluations. Disputed or archived results are excluded.
More matchups
Compare Claude Opus 4.6 and DeepSeek-V4-Flash with other leading models using the same data and benchmark logic.